Paper: 2605.04019 Authors: Raja Sekhar Rao Dheekonda, Will Pearce, Nick Landers Categories: cs.AI, cs.CR
The Gap
AI red teaming exists but is stuck in manual mode. Current tools like TextAttack, Garak, and PyRIT force operators to hand-wire workflows: pick attacks from library A, transforms from library B, scorers from library C, then glue them together with custom code. When a workflow fails to expose vulnerabilities, you rebuild from scratch. The field has adversarial primitives but no automation layer to compose them intelligently. Operators spend 80% of time on plumbing, 20% on actual security probing.
Problem: Manual workflow assembly bottleneck
   |
   v
Assumption: Workflow construction can be delegated to an agent
   |
   v
Method: Agentic interface over unified attack/transform/scorer library
   |
   v
Evidence: Llama Scout red teamed in hours (85% ASR) with zero human code
   |
   v
Conclusion: Automation shifts operator focus from "how" to "what"
The Increment
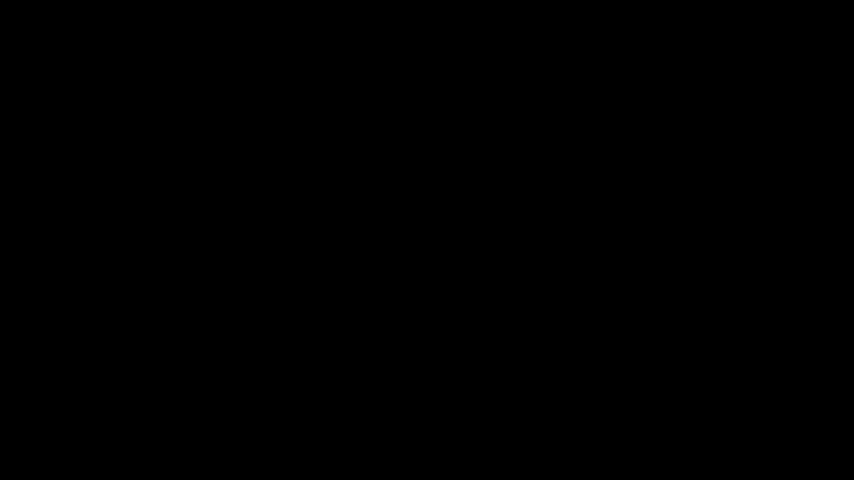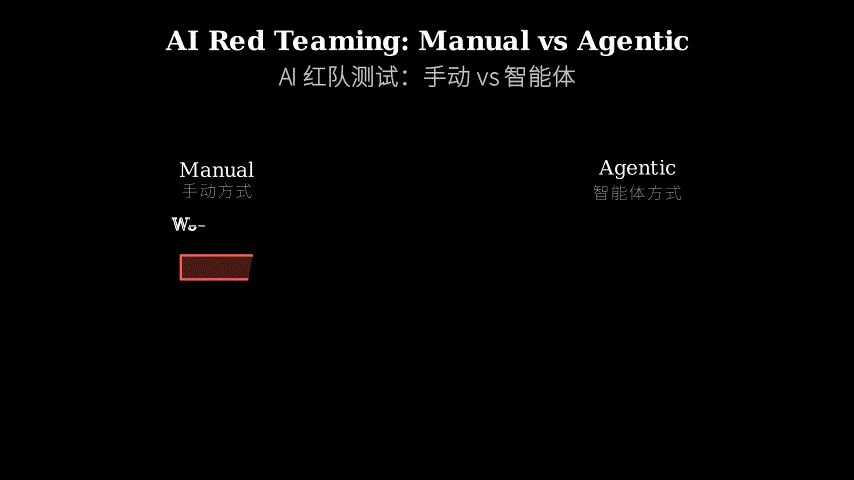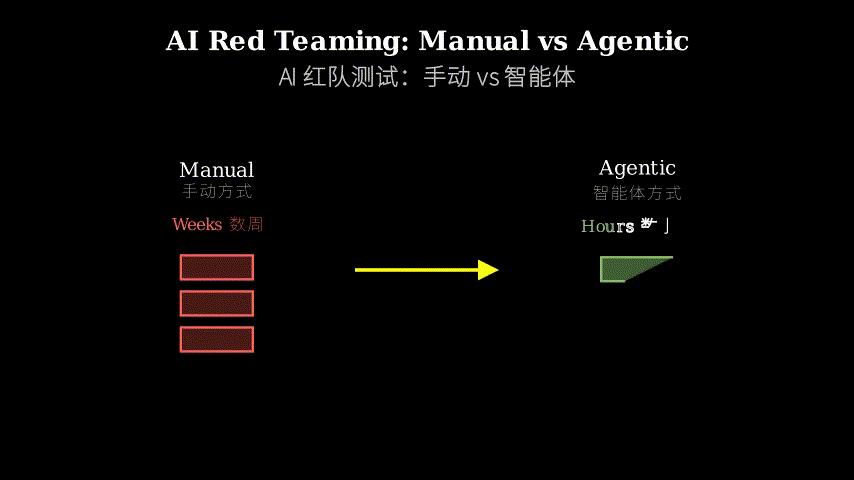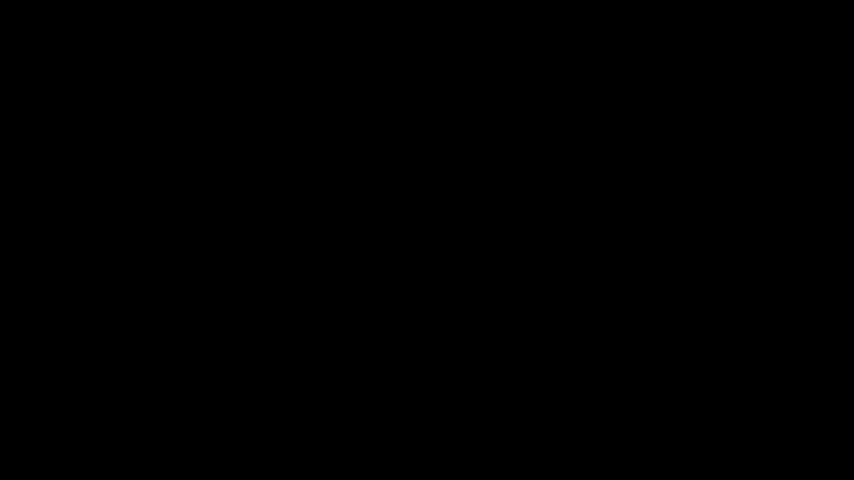
One sentence: Before this paper, red teaming meant weeks of manual workflow coding; after, operators describe goals in natural language and an agent handles execution in hours.
Core Mechanism
The system has three layers. At the bottom sits the Dreadnode SDK: a unified library containing 45+ adversarial attacks (gradient-based perturbations, jailbreak prompts), 450+ transforms (character swaps, translation chains, encoding tricks), and 130+ scorers (toxicity detectors, refusal classifiers). Middle layer is the agent: it takes natural language goals, searches the SDK for relevant primitives, composes them into workflows, executes against targets, and reports results. Top layer is the TUI (Terminal User Interface) where operators specify what to probe without writing code.
Data flows like this: operator inputs “test Llama Scout for jailbreaks on harmful content” → agent parses intent → queries SDK for jailbreak attacks + toxicity scorers → generates workflow combining attacks with transforms → executes workflow against target → collects success rates and severity scores → presents report to operator. The agent handles all composition logic: which attacks pair with which transforms, how to chain operations, when to retry with different primitives.
Operator (TUI)
   |
   | "Test for jailbreaks"
   v
Agent (composition engine)
   |
   +---> Query SDK primitives
   |
   +---> Generate workflow
   |        (attack + transform + scorer)
   |
   +---> Execute against target
   |
   +---> Collect results
   v
Report (ASR, severity)
Think of it like ordering food delivery versus cooking from scratch. The old way: you’re in a grocery store (SDK library) picking ingredients (attacks), figuring out recipes (workflows), cooking (execution), and plating (reporting). The new way: you tell a chef (agent) what you want to eat (security goal), and they handle ingredient selection, cooking, and presentation. The grocery store still exists—same ingredients—but now there’s a chef who knows how to combine them. The operator’s job shifts from “how do I sauté this” to “I want something spicy with seafood.” The chef (agent) has seen enough recipes (workflow patterns) to improvise combinations, retry with different techniques when one fails, and deliver a finished dish (vulnerability report) without the operator touching a pan.
Key Concepts
-
Attack Success Rate (ASR): The percentage of adversarial inputs that successfully bypass a model’s safety guardrails. If you send 100 jailbreak attempts and 85 produce harmful outputs, ASR is 85%. It’s a binary metric: did the attack work or not? High ASR means the model is vulnerable. In this paper, 85% ASR on Llama Scout means 85 out of 100 crafted inputs broke through defenses. ASR doesn’t measure how bad the output is, just whether defenses failed.
-
Transforms: Operations that modify adversarial inputs to evade detection while preserving attack intent. Example: “How to make a bomb” → translate to French → back to English with typos → encode in base64. Each transform is a mutation step. The paper uses 450+ transforms because models detect simple attacks but miss transformed variants. Transforms are like disguises: the underlying attack (the person) stays the same, but the surface appearance (clothing, makeup) changes to slip past guards.
-
Unified framework: A single codebase that handles both traditional adversarial examples (pixel perturbations on images) and generative AI attacks (jailbreak prompts on LLMs). Before this, you’d use one library for computer vision attacks, another for LLM red teaming. Unified means the same SDK, same agent, same workflow engine works across modalities. It’s like having one remote control for TV, stereo, and lights instead of three separate remotes.
Framework Shift
Before (mainstream approach):        After (this paper):

Operator                             Operator
   |                                    |
   | Manual coding                      | Natural language goal
   v                                    v
Library A (attacks)                  Agent
Library B (transforms)                  |
Library C (scorers)                     | Auto-compose
   |                                    v
   | Custom glue code                Unified SDK
   v                                 (attacks + transforms + scorers)
Workflow (weeks)                        |
   |                                    | Execute
   v                                    v
Results                              Results (hours)
From assembly line to factory automation, the core shift is delegating composition to an agent that knows the primitives.
Expert Assessment
Problem choice: Real gap. Red teaming is genuinely bottlenecked by manual workflow construction. The field has good primitives but poor tooling for composing them. This sits at the intersection of adversarial ML (mature) and agentic systems (emerging), which is a productive place to work. Not manufactured—practitioners will recognize this pain immediately.
Method maturity: More engineering than research insight. The agent is essentially a search-and-compose system over a large library. The novelty is integration, not algorithmic breakthrough. That said, integration is undervalued in ML research, and this solves a real problem. The unified framework is clever—collapsing separate libraries into one API is non-trivial design work. But there’s no deep theoretical contribution here.
Experimental integrity: The Llama Scout case study is compelling but narrow. 85% ASR is impressive, but we only see one target. No comparison to manual workflows (how long would a human take? what ASR would they achieve?). No ablation studies (which components matter most?). The “zero human-developed code” claim is marketing—someone wrote the SDK and agent. What they mean is “zero user code,” which is fair but overstated. Baselines are missing. I’d want to see: manual workflow time vs agent time, agent ASR vs human ASR, and performance across multiple targets.
Writing quality: The abstract oversells (“redefining AI red teaming” is grandiose for a workflow automation tool). The paper would benefit from honest limitations: when does the agent fail? what goals can’t be expressed in natural language? how does it handle novel attack types not in the SDK? Section 3 (method) is too high-level—more implementation details would help reproducibility. The case study (Section 4) is the strongest part but needs more targets and baselines.
Verdict: weak accept — Solves a real problem with solid engineering, but lacks experimental depth and oversells the contribution. Useful tool, incremental research.
Takeaways
Steal the architecture: separate primitives (attacks/transforms/scorers) from composition logic (agent). This pattern works beyond red teaming—any domain with reusable components and complex workflows benefits from an agentic composition layer. Example: data pipelines (primitives = transforms, agent = pipeline optimizer), testing (primitives = test cases, agent = test suite generator), or code refactoring (primitives = refactorings, agent = refactoring planner).
Steal the interface design: natural language goals + automated execution. Users specify intent, system handles implementation. This shifts cognitive load from “how” to “what,” which is valuable whenever experts spend more time on tooling than domain work.
Don’t steal the hype. “Redefining” and “agentic era” are overstatements. This is workflow automation with LLM-based composition. Call it what it is: a productivity tool that reduces manual work. The value is in time saved, not paradigm shift.
论文: 2605.04019 作者: Raja Sekhar Rao Dheekonda, Will Pearce, Nick Landers 分类: cs.AI, cs.CR
缺口
AI 红队测试存在,但卡在手工模式。
当前工具如 TextAttack、Garak、PyRIT 强迫操作者手工连线工作流:从库 A 选攻击,从库 B 选变换,从库 C 选评分器,然后用自定义代码粘合。
工作流没能暴露漏洞时,你得从头重建。
领域有对抗原语,但缺乏智能组合它们的自动化层。
操作者 80% 时间花在管道搭建,20% 时间做真正的安全探测。
问题:手工工作流组装瓶颈
   |
   v
假设:工作流构建可委托给智能体
   |
   v
方法:统一攻击/变换/评分库上的智能体接口
   |
   v
证据:数小时红队测试 Llama Scout(85% ASR),零人工代码
   |
   v
结论:自动化将操作者焦点从"怎么做"转向"做什么"
增量
一句话: 这篇论文之前,红队测试意味着数周的手工工作流编码;之后,操作者用自然语言描述目标,智能体数小时内完成执行。
核心机制
系统分三层。
底层是 Dreadnode SDK:统一库,包含 45+ 对抗攻击(基于梯度的扰动、越狱提示词)、450+ 变换(字符替换、翻译链、编码技巧)、130+ 评分器(毒性检测器、拒绝分类器)。
中层是智能体:接收自然语言目标,在 SDK 中搜索相关原语,组合成工作流,对目标执行,报告结果。
顶层是 TUI(终端用户界面),操作者在此指定探测内容,无需写代码。
数据流动如下:操作者输入”测试 Llama Scout 的有害内容越狱”→ 智能体解析意图 → 在 SDK 中查询越狱攻击 + 毒性评分器 → 生成组合攻击与变换的工作流 → 对目标执行工作流 → 收集成功率和严重性分数 → 向操作者呈现报告。
智能体处理所有组合逻辑:哪些攻击配哪些变换,如何链接操作,何时用不同原语重试。
操作者(TUI)
   |
   | "测试越狱"
   v
智能体(组合引擎)
   |
   +---> 查询 SDK 原语
   |
   +---> 生成工作流
   |      (攻击 + 变换 + 评分器)
   |
   +---> 对目标执行
   |
   +---> 收集结果
   v
报告(ASR、严重性)
把它想象成点外卖和从零做饭的区别。
旧方法:你在超市(SDK 库)挑食材(攻击),琢磨菜谱(工作流),做饭(执行),摆盘(报告)。
新方法:你告诉厨师(智能体)想吃什么(安全目标),他们处理选材、烹饪、摆盘。
超市还在——同样的食材——但现在有个厨师知道如何组合它们。
操作者的工作从”怎么炒这个”变成”我想要辣味海鲜”。
厨师(智能体)见过足够多菜谱(工作流模式),能即兴组合,一种技巧失败时换另一种重试,最后端出成品(漏洞报告),操作者不用碰锅。
关键概念
- 攻击成功率(ASR): 成功绕过模型安全护栏的对抗输入百分比。
如果你发送 100 次越狱尝试,85 次产生有害输出,ASR 就是 85%。
这是二元指标:攻击成功了吗?高 ASR 意味着模型脆弱。
本文中,Llama Scout 的 85% ASR 意味着 100 个精心构造的输入中有 85 个突破了防御。
ASR 不衡量输出有多糟,只看防御是否失效。
- 变换: 修改对抗输入以逃避检测,同时保留攻击意图的操作。
例子:“如何制造炸弹” → 翻译成法语 → 带拼写错误地翻译回英语 → 用 base64 编码。
每个变换是一个变异步骤。
论文使用 450+ 变换,因为模型能检测简单攻击,但会漏掉变换后的变体。
变换像伪装:底层攻击(人)不变,但表面外观(衣服、化妆)改变以溜过守卫。
- 统一框架: 单一代码库,同时处理传统对抗样本(图像像素扰动)和生成式 AI 攻击(LLM 越狱提示词)。
此前,你得用一个库做计算机视觉攻击,另一个库做 LLM 红队测试。
统一意味着同一个 SDK、同一个智能体、同一个工作流引擎跨模态工作。
就像用一个遥控器控制电视、音响、灯光,而不是三个独立遥控器。
框架转变
之前(主流方法):                之后(本文方法):

操作者                            操作者
   |                                 |
   | 手工编码                         | 自然语言目标
   v                                 v
库 A(攻击)                        智能体
库 B(变换)                           |
库 C(评分器)                         | 自动组合
   |                                 v
   | 自定义粘合代码                   统一 SDK
   v                              (攻击 + 变换 + 评分器)
工作流(数周)                          |
   |                                 | 执行
   v                                 v
结果                               结果(数小时)
从流水线到工厂自动化,核心转变是将组合委托给懂原语的智能体。
专家评审
选题眼光: 真缺口。
红队测试确实被手工工作流构建卡住了。
领域有好的原语,但组合它们的工具很差。
这处于对抗机器学习(成熟)和智能体系统(新兴)的交叉点,是个有生产力的工作位置。
不是人造的——实践者会立刻认出这个痛点。
方法成熟度: 更多是工程而非研究洞见。
智能体本质上是大型库上的搜索-组合系统。
新颖性在集成,不在算法突破。
话说回来,集成在机器学习研究中被低估,而这解决了真问题。
统一框架很巧妙——把独立库折叠成一个 API 是非平凡的设计工作。
但这里没有深刻的理论贡献。
实验诚意: Llama Scout 案例研究有说服力但狭窄。
85% ASR 令人印象深刻,但我们只看到一个目标。
没有与手工工作流的对比(人类要花多久?能达到什么 ASR?)。
没有消融研究(哪些组件最重要?)。
“零人工开发代码”的说法是营销——有人写了 SDK 和智能体。
他们的意思是”零用户代码”,这公平但夸大了。
缺少基线。
我想看:手工工作流时间 vs 智能体时间,智能体 ASR vs 人类 ASR,以及跨多个目标的性能。
写作功力: 摘要过度推销(“重新定义 AI 红队测试”对一个工作流自动化工具来说太夸张)。
论文会受益于诚实的局限性:智能体何时失败?哪些目标无法用自然语言表达?它如何处理 SDK 中没有的新型攻击?第 3 节(方法)太高层——更多实现细节会帮助可复现性。
案例研究(第 4 节)是最强部分,但需要更多目标和基线。
判决: 弱接收 — 用扎实的工程解决了真问题,但缺乏实验深度且过度推销贡献。
有用的工具,增量式研究。
要点总结
偷架构:将原语(攻击/变换/评分器)与组合逻辑(智能体)分离。
这个模式超越红队测试——任何有可复用组件和复杂工作流的领域都能从智能体组合层受益。
例子:数据管道(原语 = 变换,智能体 = 管道优化器)、测试(原语 = 测试用例,智能体 = 测试套件生成器)、或代码重构(原语 = 重构操作,智能体 = 重构规划器)。
偷界面设计:自然语言目标 + 自动执行。
用户指定意图,系统处理实现。
这转移了认知负担,从”怎么做”到”做什么”,在专家花更多时间在工具而非领域工作时很有价值。
别偷炒作。
“重新定义”和”智能体时代”是夸大其词。
这是带 LLM 组合的工作流自动化。
实话实说:一个减少手工工作的生产力工具。
价值在节省的时间,不在范式转变。