Paper: 2605.06639 Authors: Apurva Gandhi, Satyaki Chakraborty, Xiangjun Wang, Aviral Kumar, Graham Neubig Categories: cs.LG, cs.AI, cs.CL, cs.MA
The Gap
Current LLM agents hit a wall when tasks exceed their context window or require complex multi-step reasoning. Existing approaches either (1) use fixed-depth hierarchical planning that doesn’t adapt to problem complexity, or (2) rely on chain-of-thought prompting that still processes everything in a single forward pass. Neither approach teaches the model when to break down problems or how to coordinate sub-solutions.
The core limitation: we train models to solve problems end-to-end, but deploy them in settings where recursive decomposition would be more efficient. There’s no training signal for learning good decomposition strategies.
Problem: Tasks beyond single-agent capacity
    |
    v
Assumption: Recursive decomposition is learnable, not just executable
    |
    v
Method: RL over recursive execution traces
    |
    +---> Reward: Task success + efficiency
    |
    v
Evidence: Outperforms single-agent on long-context tasks
    |
    v
Conclusion: Training for recursion > prompting for recursion
The Increment
One sentence: Before RAO, agents could execute recursive algorithms if prompted correctly; after RAO, agents learn when and how to recurse through reinforcement learning on execution traces.
Core Mechanism
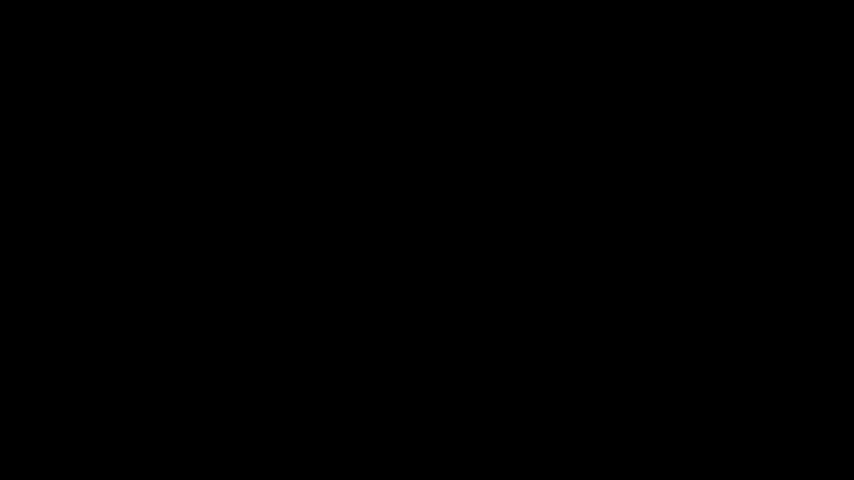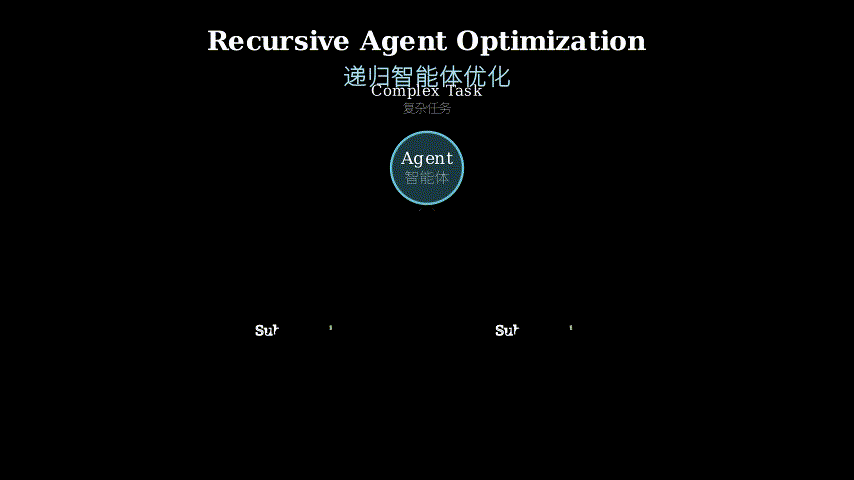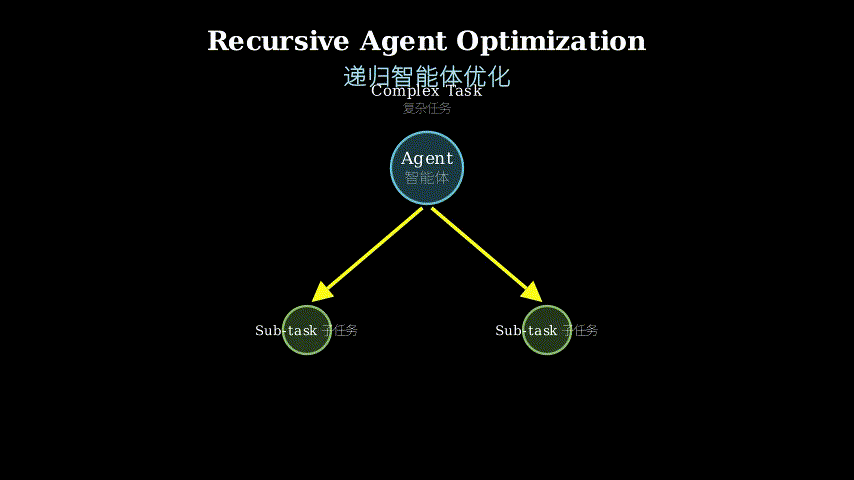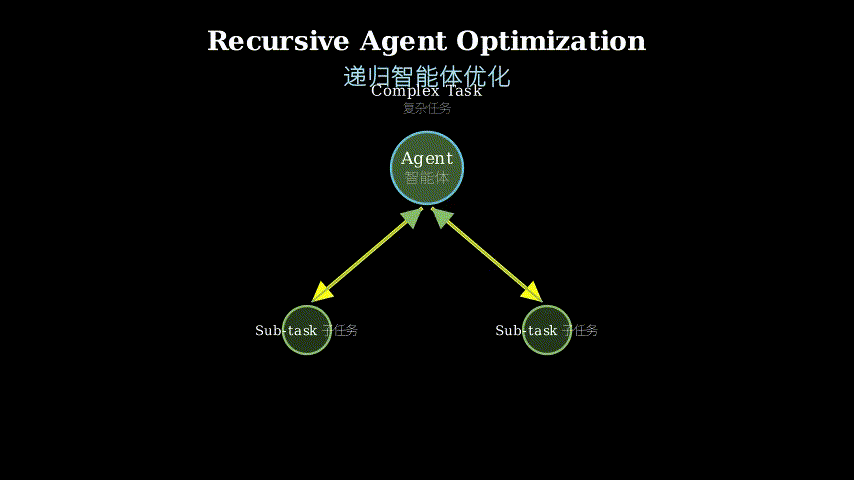
RAO trains agents in an environment where they can spawn child instances of themselves. Each agent receives a task, decides whether to solve it directly or delegate sub-tasks to children, and receives rewards based on final task success and computational efficiency. The training loop collects full execution trees—parent decisions, child spawns, communication patterns—and uses policy gradient methods to optimize the agent’s delegation strategy.
The key architectural choice: agents communicate through a structured message-passing interface. A parent can send context to children and receive results back. The RL objective balances task completion (did the recursive tree solve the problem?) against resource usage (how many agents were spawned? how much total computation?).
Training Episode:

    Agent receives task T
         |
         v
    [Decide: solve or delegate?]
         |
    +----+----+
    |         |
  Solve    Delegate
    |         |
    |    Spawn children
    |    Send sub-tasks
    |    Receive results
    |    Aggregate
    |         |
    +----+----+
         |
         v
    Return solution
         |
         v
    Reward = f(correct, #agents, time)
         |
         v
    Update policy via RL
Think of RAO like training a manager who can clone themselves. Initially, the manager doesn’t know when to delegate—they either try to do everything themselves (context overflow) or delegate trivially small tasks (coordination overhead). Through trial and error with feedback on both quality and efficiency, they learn the sweet spot: delegate when sub-problems are independent and substantial, solve directly when the task fits their capacity. The clones aren’t different people—they’re the same manager with the same skills, just working on different sub-problems. The training teaches the manager’s decision-making, not the clones’ individual abilities.
Key Concepts
-
Recursive agent: An agent that can instantiate new copies of itself to handle sub-tasks. Unlike hierarchical systems with specialized sub-agents, all instances run the same model with the same weights. The recursion is in the execution pattern, not the architecture. Concretely: if you ask a recursive agent to summarize a 100-page document, it might spawn 10 child agents, each summarizing 10 pages, then aggregate their outputs. Each child is running the same model you started with.
-
Inference-time scaling: The idea that you can improve performance by using more computation at test time, not just bigger models or more training. RAO’s recursion is a form of inference-time scaling—harder problems automatically trigger deeper recursion trees, using more agent-steps. This is different from chain-of-thought, which scales linearly with reasoning steps. Recursion scales with problem structure.
-
Delegation policy: The learned strategy for when to spawn children versus solving directly. This is what RL optimizes. A good delegation policy recognizes problem structure (is this parallelizable?), estimates sub-problem difficulty (will children succeed?), and balances coordination cost against direct-solve cost. Without training, agents either never delegate (context overflow) or always delegate (infinite recursion). RAO learns the middle path.
Framework Shift
Before (single-agent):              After (RAO):

    Task                                Task
     |                                   |
     v                                   v
  [Agent]                            [Agent]
     |                                   |
  (process                          (decide)
   entire                                |
   task in                      +--------+--------+
   one pass)                    |        |        |
     |                          v        v        v
     v                      [Child1] [Child2] [Child3]
  Solution                      |        |        |
                           (sub-task) (sub-task) (sub-task)
                                |        |        |
                                +--------+--------+
                                         |
                                         v
                                  [Aggregate]
                                         |
                                         v
                                    Solution
From monolithic processing to learned decomposition, the core shift is training the decision to recurse, not just the ability to recurse.
Expert Assessment
Problem choice: Real gap. Inference-time scaling is a hot topic (see o1, tree search methods), but most work focuses on search over reasoning paths, not learned recursive decomposition. The connection to context window limitations is practical—this matters for real deployments.
Method maturity: Conceptually clean but implementation details matter. The paper doesn’t deeply address: How do you prevent infinite recursion during training? How sensitive is the reward function to the efficiency term? What happens when children fail—does the parent retry or give up? The RL formulation is standard policy gradient, which is fine but not novel. The novelty is in the environment design (recursive spawning) and the training objective (balancing correctness and efficiency).
Experimental integrity: The tasks (long-context QA, code generation, math problems) are well-chosen to showcase recursion benefits. Baselines include single-agent and prompted recursion, which is fair. The generalization experiments (training on easy tasks, testing on hard) are the strongest evidence—this suggests the agent learns decomposition principles, not just task-specific tricks. However, the paper would benefit from ablations on reward function design and failure mode analysis.
Writing quality: The abstract and intro are strong. The method section could be clearer about the message-passing protocol and termination conditions. The related work undersells connections to hierarchical RL and program synthesis. The experiments section is thorough but could use more error analysis—when does recursion fail?
Verdict: weak accept — Solid contribution to inference-time scaling with practical benefits, but the method is more “RL applied to a new environment” than a fundamental algorithmic innovation. The generalization results elevate it above a pure engineering paper.
Takeaways
For practitioners:
- If you’re building agents for tasks with natural decomposition structure (document processing, code generation, multi-step reasoning), consider training with recursive execution rather than just prompting for it. The performance gains come from learning when to delegate, not just how.
- The reward function design is critical: pure task success leads to over-delegation (spawn children for everything), while pure efficiency leads to under-delegation (never spawn). You need both terms.
- Recursive agents can generalize to harder problems than they were trained on, which is rare in RL. This suggests the learned skill is decomposition strategy, not problem-specific heuristics.
For researchers:
- The recursive agent framework is a clean testbed for studying inference-time scaling. You could explore: learned termination conditions, dynamic depth limits, heterogeneous child agents, or recursive self-improvement.
- The connection to program synthesis is underexplored. Recursive agents are essentially learning to write and execute recursive programs. Could you combine this with neural program induction?
论文: 2605.06639 作者: Apurva Gandhi, Satyaki Chakraborty, Xiangjun Wang, Aviral Kumar, Graham Neubig 分类: cs.LG, cs.AI, cs.CL, cs.MA
缺口
当前的大语言模型智能体在任务超出上下文窗口或需要复杂多步推理时会遇到瓶颈。
现有方法要么(1)使用固定深度的层级规划,无法适应问题复杂度,要么(2)依赖思维链提示,但仍在单次前向传播中处理所有内容。
两种方法都没有教会模型何时分解问题或如何协调子解决方案。
核心局限:我们训练模型端到端解决问题,但在部署时递归分解会更高效。
缺少学习良好分解策略的训练信号。
问题:超出单智能体能力的任务
    |
    v
假设:递归分解是可学习的,不只是可执行的
    |
    v
方法:对递归执行轨迹进行强化学习
    |
    +---> 奖励:任务成功 + 效率
    |
    v
证据:在长上下文任务上优于单智能体
    |
    v
结论:训练递归 > 提示递归
增量
一句话:RAO 之前,智能体在正确提示下能执行递归算法;RAO 之后,智能体通过对执行轨迹的强化学习来学会何时以及如何递归。
核心机制
RAO 在一个智能体可以生成自身子实例的环境中训练。
每个智能体接收任务,决定是直接解决还是将子任务委派给子智能体,并根据最终任务成功率和计算效率获得奖励。
训练循环收集完整的执行树——父节点决策、子节点生成、通信模式——并使用策略梯度方法优化智能体的委派策略。
关键架构选择:智能体通过结构化消息传递接口通信。
父节点可以向子节点发送上下文并接收返回结果。
强化学习目标在任务完成(递归树是否解决了问题?
)和资源使用(生成了多少智能体?
总计算量是多少?
)之间取得平衡。
训练回合:

    智能体接收任务 T
         |
         v
    [决策:直接解决还是委派?]
         |
    +----+----+
    |         |
  解决    委派
    |         |
    |    生成子智能体
    |    发送子任务
    |    接收结果
    |    聚合
    |         |
    +----+----+
         |
         v
    返回解决方案
         |
         v
    奖励 = f(正确性, 智能体数量, 时间)
         |
         v
    通过强化学习更新策略
把 RAO 想象成训练一个能克隆自己的管理者。
最初,管理者不知道何时委派——要么试图自己做所有事(上下文溢出),要么委派琐碎的小任务(协调开销)。
通过对质量和效率的反馈进行试错,他们学会了最佳点:当子问题独立且实质性时委派,当任务符合自身能力时直接解决。
克隆体不是不同的人——他们是同一个管理者,有相同的技能,只是在处理不同的子问题。
训练教会的是管理者的决策能力,而非克隆体的个体能力。
关键概念
- 递归智能体:能够实例化自身新副本来处理子任务的智能体。
与具有专门子智能体的层级系统不同,所有实例运行相同的模型和权重。
递归在于执行模式,而非架构。
具体来说:如果你让递归智能体总结一份 100 页的文档,它可能生成 10 个子智能体,每个总结 10 页,然后聚合它们的输出。
每个子智能体运行的都是你最初使用的同一个模型。
- 推理时扩展:通过在测试时使用更多计算来提升性能,而不仅仅是更大的模型或更多训练。
RAO 的递归是推理时扩展的一种形式——更难的问题自动触发更深的递归树,使用更多智能体步骤。
这与思维链不同,后者随推理步骤线性扩展。
递归随问题结构扩展。
- 委派策略:关于何时生成子智能体而非直接解决的学习策略。
这是强化学习优化的内容。
好的委派策略能识别问题结构(这可以并行化吗?
),估计子问题难度(子智能体会成功吗?
),并在协调成本和直接解决成本之间取得平衡。
没有训练,智能体要么从不委派(上下文溢出),要么总是委派(无限递归)。
RAO 学习中间路径。
框架转变
之前(单智能体):              之后(RAO):

    任务                            任务
     |                               |
     v                               v
  [智能体]                        [智能体]
     |                               |
  (在一次                        (决策)
   传递中                            |
   处理整个                  +-------+-------+
   任务)                     |       |       |
     |                       v       v       v
     v                   [子1]   [子2]   [子3]
  解决方案                   |       |       |
                        (子任务)(子任务)(子任务)
                             |       |       |
                             +-------+-------+
                                     |
                                     v
                                [聚合]
                                     |
                                     v
                                解决方案
从整体处理到学习分解,核心转变是训练递归的决策,而不仅仅是递归的能力。
专家评审
选题眼光:真实缺口。
推理时扩展是热门话题(参见 o1、树搜索方法),但大多数工作关注推理路径上的搜索,而非学习递归分解。
与上下文窗口限制的联系很实用——这对实际部署很重要。
方法成熟度:概念上清晰,但实现细节很重要。
论文没有深入探讨:如何在训练期间防止无限递归?
奖励函数对效率项有多敏感?
当子智能体失败时会发生什么——父智能体重试还是放弃?
强化学习公式是标准的策略梯度,这没问题但不新颖。
新颖之处在于环境设计(递归生成)和训练目标(平衡正确性和效率)。
实验诚意:任务(长上下文问答、代码生成、数学问题)选择得当,能展示递归的优势。
基线包括单智能体和提示递归,这是公平的。
泛化实验(在简单任务上训练,在困难任务上测试)是最有力的证据——这表明智能体学习了分解原则,而非仅仅是任务特定的技巧。
然而,论文需要更多关于奖励函数设计的消融实验和失败模式分析。
写作功力:摘要和引言很强。
方法部分在消息传递协议和终止条件方面可以更清晰。
相关工作低估了与层级强化学习和程序综合的联系。
实验部分很全面,但需要更多错误分析——递归何时失败?
判决:弱接收 — 对推理时扩展的扎实贡献,具有实际效益,但该方法更像是”将强化学习应用于新环境”,而非根本性的算法创新。
泛化结果使其超越了纯工程论文。
要点总结
对实践者:
- 如果你在构建具有自然分解结构的任务智能体(文档处理、代码生成、多步推理),考虑用递归执行训练而不仅仅是提示。
性能提升来自学习何时委派,而不仅仅是如何委派。
- 奖励函数设计至关重要:纯任务成功导致过度委派(为所有事情生成子智能体),而纯效率导致委派不足(从不生成)。
你需要两个项。
- 递归智能体可以泛化到比训练时更难的问题,这在强化学习中很罕见。
这表明学到的技能是分解策略,而非问题特定的启发式。
对研究者:
- 递归智能体框架是研究推理时扩展的清晰测试平台。
你可以探索:学习终止条件、动态深度限制、异构子智能体或递归自我改进。
- 与程序综合的联系尚未充分探索。
递归智能体本质上是在学习编写和执行递归程序。
能否将其与神经程序归纳结合?