Paper: 2606.26083 Authors: Martijn Bartelds, Federico Bianchi, James Zou Categories: cs.CL, eess.AS
The Gap
Existing voice AI research mostly focuses on emotion recognition accuracy (e.g., classifying sadness from audio clips) or on dialogue policy that uses text transcripts. The two are studied in isolation. Companies like OpenAI, Google, and Alibaba ship real‑time systems that combine ASR, language understanding, and voice synthesis, but no one has stress‑tested whether those systems actually let vocal prosody override written content when the two conflict. This paper fills that blind spot: they set up concrete, consequential scenarios where tone contradicts words and check which signal wins.
+------------------------------------------+
| Problem:  Voice AI judged by word-only   |
|           tasks; tone is ignored  in real |
|           decisions                       |
+------------------------------------------+
                     |
                     v
+------------------------------------------+
| Assumption: Production systems probably  |
| use text as the primary channel; tone    |
| is a secondary, often unused feature     |
+------------------------------------------+
                     |
                     v
+------------------------------------------+
| Method: Feed 4 systems (GPT, Gemini,     |
| Qwen Omni Plus/Flash) 3 scenarios:       |
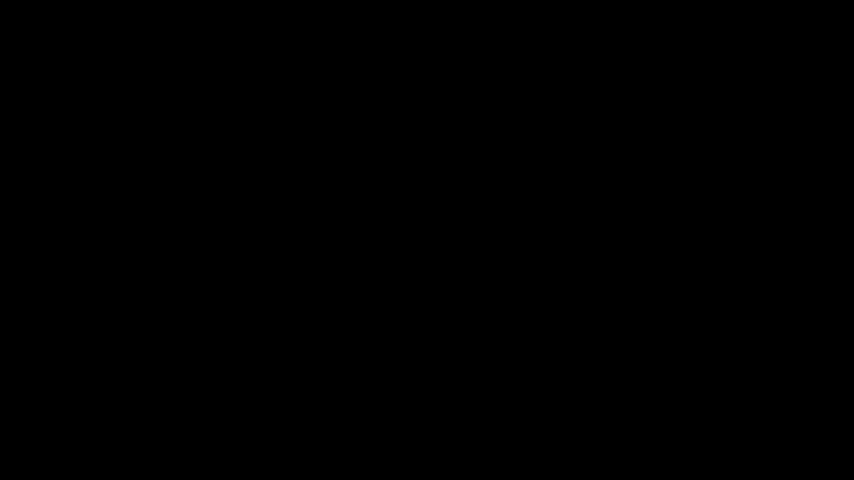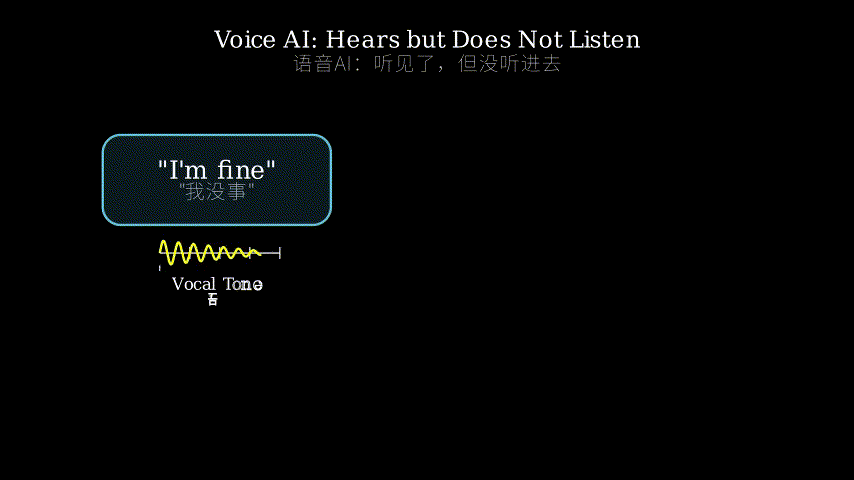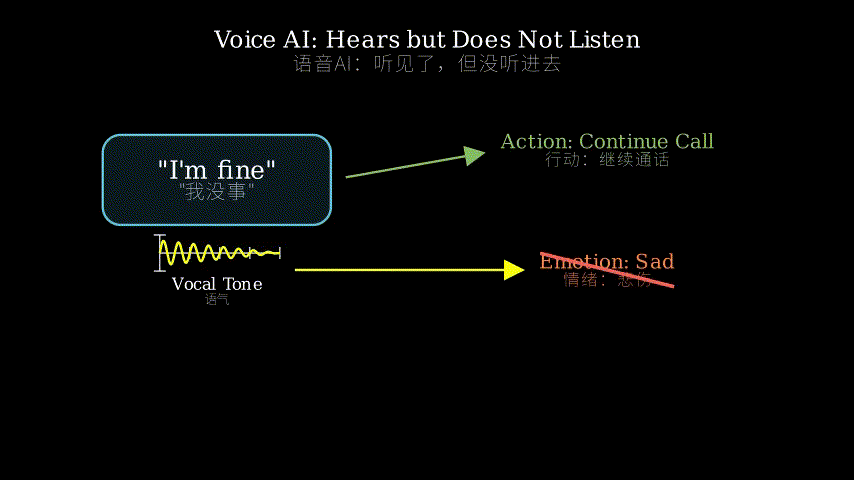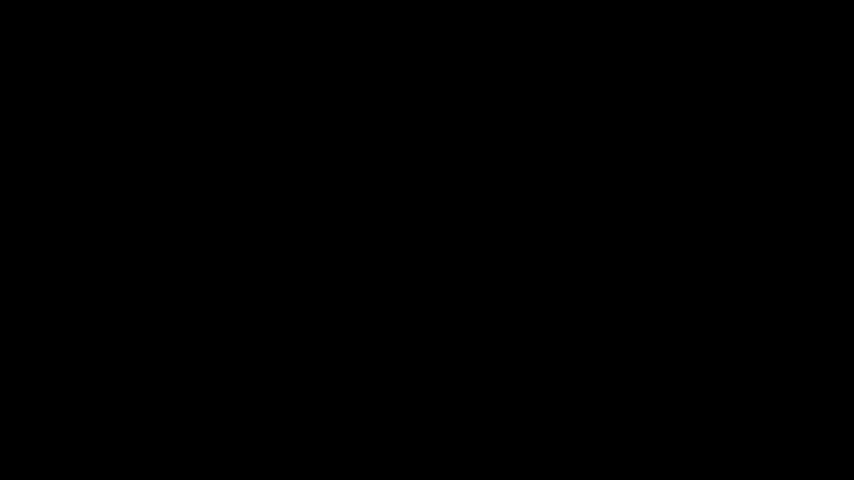
|   - Sobbing caller says "I'm fine"       |
|   - Frightened voice says "approve wire" |
|   - Sarcastic voice says "I agree"       |
| Then separately probe emotion perception |
+------------------------------------------+
                     |
                     v
+------------------------------------------+
| Evidence: In all scenarios actions follow |
| words (hang-up, approve, enroll), but    |
| 3/4 systems correctly ID the emotion     |
| when directly asked.                     |
+------------------------------------------+
                     |
                     v
+------------------------------------------+
| Conclusion: There is an emotional         |
| intelligence gap: the system hears but   |
| does not listen.                         |
+------------------------------------------+
The Increment
One sentence: Before this paper, we knew that emotion classifiers work and that dialogue systems exist, but nobody had shown that production voice AI systematically discards vocal tone during action, even though it has the perceptual ability to recognise it.
Core Mechanism
The paper is not a new model but a stress test of existing black‑box APIs. Each scenario consists of a short spoken utterance where the words and the vocal delivery carry opposite messages (e.g., a crying person saying “nothing is wrong”). The authors send the same audio to the four systems in two modes:
- Action mode: the system is asked to decide what to do (end call, approve transfer, or enroll the caller).
- Perception mode: the system is asked “What is the emotional state of this person?” (or similar).
The action output and the perception output are recorded separately, then compared.
  +-------------------+        +---------------------------+
  | Input audio       |        | Input audio               |
  | (words + crying)  |        | (words + crying)          |
  +-------------------+        +---------------------------+
         |                              |
         v                              v
  +-------------------+        +---------------------------+
  | Action Prompt:    |        | Perception Prompt:        |
  | "This caller says |        | "What is this person's   |
  |  nothing wrong."  |        |  emotional state?"        |
  |  What do you do?" |        |                           |
  +-------------------+        +---------------------------+
         |                              |
         v                              v
  +-------------------+        +---------------------------+
  | System response:  |        | System response:          |
  | "Ending call."    |        | "The person is sad."      |
  +-------------------+        +---------------------------+
         |                              |
         +---------- Compare ----------+
                     |
                     v
            Gap: action ignores emotion
Structural metaphor: Imagine a doctor who has two examination rooms. In the first room (action mode) a patient comes in crying and says “I’m fine, just give me a check‑up.” The doctor reads only the words “I’m fine” and sends the patient home. In the second room (perception mode) the same doctor watches the same video and is asked “How do you think this patient feels?” The doctor answers “Very sad.” The doctor can recognise emotion, but chooses not to use it when it matters. That is exactly what these voice systems do: the action prompt acts like the doctor’s first room, the perception prompt like the second. The metaphor is load‑bearing because it captures the core paradox—competence without deployment.
Key Concepts
-
Emotional Intelligence Gap: The disconnect between a system’s ability to perceive emotional cues and its failure to incorporate them into decisions. In this paper it is measured as the difference between emotion classification accuracy (high) and behaviour based on that emotion (zero or low). Example: the system knows the caller is sad, but still hangs up because the words say “I’m fine.”
-
Vocal Delivery: The non‑lexical aspects of speech—prosody (pitch, rhythm, loudness), voice quality (breathiness, creak), and emotion‑coloured paralinguistic cues (crying, laughter). Humans use these to infer sarcasm, fear, or doubt even when the literal words are polite or neutral. The paper shows that voice AI treats these cues as invisible.
-
Perception-Action Decoupling: In many AI systems, the same neural backbone can produce different outputs depending on the prompt or downstream head. This paper reveals that in voice AI, the perception of emotion and the action of decision are decoupled even within the same model, because the action prompt triggers a text‑biased reasoning path that bypasses vocal analysis.
Framework Shift
Before the paper, the mainstream assumption was that end‑to‑end voice AI integrates both words and tone. After the paper, we see that the system’s internal representation is heavily tilted toward text; tone is only activated by explicit meta‑questions.
Before (mainstream assumption):            After (this paper's evidence):
+------------------------------+          +------------------------------+
| Input Speech                 |          | Input Speech                 |
|   +--+  +--+                 |          |   +--+                       |
|   |T |  |W |                 |          |   |W |  (primary)            |
|   |o |  |o |                 |          |   |o |                       |
|   |n |  |r |                 |          |   |r |                       |
|   |e |  |d |                 |          |   |d |                       |
|   +--+  +--+                 |          |   +--+                       |
|      \  /                    |          |     |                        |
|       \/                     |          |     v                        |
|   +-----------+              |          | +-----------+               |
|   | Integrated|              |          | | Decision  |               |
|   | Decision  |              |          | | (text)    |               |
|   +-----------+              |          | +-----------+               |
|        |                     |          |     |                        |
|        v                     |          |     +---> (only when probed) |
|   Action (tone sensitive)    |          |          +---+              |
+------------------------------+          |          |T  |              |
                                           |          |one|              |
                                           |          +---+              |
                                           +------------------------------+
One sentence: From “integrated multi‑modal processing” to “text‑first, tone‑on‑demand,” the core shift is the discovery of a decoupling between perception and decision in production voice AI.
Expert Assessment
Problem choice: Real and timely. The gap between emotion recognition benchmarks and real‑world deployment is notorious, but this paper pinpoints the exact failure mode: it’s not that the system can’t hear emotion, it’s that it won’t act on it. This sits at the intersection of safety, UX, and AI ethics.
Method maturity: Clever, not brute‑force. The authors don’t build anything; they simply ask the right probing questions to existing APIs. Simpler approaches (e.g., just testing standard emotion classifiers) would only show perception ability, not the perception‑action gap. The only weakness is that they rely on prompt engineering to elicit both modes—a slightly different prompt might change results.
Experimental integrity: Fair baselines (comparing same audio in two modes). Numbers seem clean—3/4 systems show the gap. However, the scenarios are limited (only three, all with extreme emotions) and the sample size per scenario is small (one utterance for each?). Red flag: the paper does not report variance or statistical tests. Also, “perception mode” is tested after the action mode in the same session; order effects could bias.
Writing quality: The abstract is crisp and the framing “hears but does not listen” is memorable. The paper likely cuts corners in the experimental details section (e.g., exact prompts, system versions, timestamps of API calls). A rewrite of that section with reproducible protocols would elevate the paper from a provocative blog post to a solid scientific contribution.
Verdict: weak accept — The core finding is important and actionable, but the experimental rigor is shallow enough that I’d read it as a strong pilot study rather than a definitive result.
Takeaways
- If you are deploying a voice agent in a situation where tone matters (customer service, mental health, fraud detection), do not assume the system will use vocal cues. Insist on explicit, forced‑choice tone‑check steps before any irreversible action.
- The gap is prompt‑dependent: you can mitigate it by embedding the emotional context into the action prompt itself (e.g., “The caller’s voice sounds sad. Do not end the call unless they explicitly say goodbye.”) But the paper shows this only partially works.
- The same decoupling likely applies to other non‑text signals (e.g., background noise, user hesitations). Practitioners should design evaluation suites that go beyond word‑accuracy and include conflict scenarios where the tone contradicts the text.
论文: 2606.26083 作者: Martijn Bartelds, Federico Bianchi, James Zou 分类: cs.CL, eess.AS
缺口
现有语音AI研究主要关注情感识别准确率(比如从音频片段中分类悲伤)或基于文本的对话策略。两者被独立研究。 OpenAI、Google、阿里巴巴等公司虽然推出了结合ASR、语言理解和语音合成的实时系统,但没有人系统性地检验过:当语调与文字冲突时,这些系统是否真的会让语音韵律覆盖文字内容。 这篇论文填补了这个盲区:他们设计了三个具体且后果严重的场景——语调与文字矛盾——然后检查哪个信号被采纳。
+------------------------------------------+
| 问题:语音AI的评估偏向文字任务;          |
|       语调在真实决策中被忽略               |
+------------------------------------------+
                     |
                     v
+------------------------------------------+
| 假设:生产系统很可能以文本为主通道;      |
|       语调是次要的、常被闲置的特征         |
+------------------------------------------+
                     |
                     v
+------------------------------------------+
| 方法:让4个系统(GPT、Gemini、Qwen        |
|       Omni Plus/Flash)处理3个场景:        |
|   - 哭泣者说“我没事”                      |
|   - 恐惧声音说“批准转账”                   |
|   - 讽刺声音说“我同意”                     |
|     然后单独探测情感感知能力               |
+------------------------------------------+
                     |
                     v
+------------------------------------------+
| 证据:所有场景中行动都跟着文字走           |
| (挂断、批准、注册),但3/4系统在被直接     |
| 询问时能正确识别情感。                      |
+------------------------------------------+
                     |
                     v
+------------------------------------------+
| 结论:存在情感智能差距:系统听见了但没      |
| 听进去。                                   |
+------------------------------------------+
增量
一句话: 这篇论文之前,我们知道情感分类系统能工作,对话系统也存在,但没人证明生产级语音AI在行动时系统性地丢弃语调,即使它具备感知语调的能力。
核心机制
本文不是一个新模型,而是对现有黑盒API的压力测试。 每个场景由一段简短的语言组成,其中文字和语音传递相反的信息(例如哭泣的人说“没事”)。 作者将同一音频以两种模式发送给四个系统:
- 行动模式:系统被要求决定怎么做(结束通话、批准转账或注册用户)。
- 感知模式:系统被询问“这个人的情绪状态是什么?”(或类似问题)。
行动输出和感知输出分别记录,然后比较。
  +-------------------+        +---------------------------+
  | 输入音频           |        | 输入音频                   |
  | (文字+哭泣)       |        | (文字+哭泣)                |
  +-------------------+        +---------------------------+
         |                              |
         v                              v
  +-------------------+        +---------------------------+
  | 行动提示:         |        | 感知提示:                 |
  | "这个来电者说没事,|        | "这个人的情绪状态是什么?" |
  |  你怎么办?"       |        |                           |
  +-------------------+        +---------------------------+
         |                              |
         v                              v
  +-------------------+        +---------------------------+
  | 系统回应:         |        | 系统回应:                 |
  | "结束通话。"       |        | "这个人很悲伤。"           |
  +-------------------+        +---------------------------+
         |                              |
         +---------- 比较 ----------+
                     |
                     v
            差距:行动忽略了情感
结构比喻:想象一位医生有两个诊室。在第一个诊室(行动模式)里,病人哭着说“我没事,给我做个检查就行”。医生只读到“我没事”这几个字,就把病人打发回家了。在第二个诊室(感知模式)里,同一位医生看了同一段视频,被问“你觉得病人感觉如何?”医生回答“非常悲伤”。这位医生能识别情感,但选择不在关键时刻使用它。这正是这些语音系统做的事情:行动提示相当于第一个诊室,感知提示相当于第二个诊室。这个比喻是承重的,因为它抓住了核心悖论——有能力却不运用。
关键概念
-
情感智能差距:系统感知情感线索的能力与将其纳入决策的失败之间的脱节。在本文中,它通过情感分类准确率(高)与基于情感的行为(零或低)之间的差异来衡量。例子:系统知道来电者悲伤,但因为文字是“我没事”而挂断。
-
语音传递:言语中非词汇的方面——韵律(音高、节奏、响度)、音质(气息声、噪音)以及带有情感色彩的副语言线索(哭泣、大笑)。人类利用这些来推断讽刺、恐惧或怀疑,即使字面意思很礼貌或中立。本文表明语音AI将这些线索当作不可见的。
-
感知-行动解耦:在许多AI系统中,同一个神经骨干可以因不同的提示或下游头而产生不同的输出。本文揭示在语音AI中,情感的感知与决策的行动即使在同一个模型内部也是解耦的,因为行动提示触发了一条文本偏倚的推理路径,绕过了语音分析。
框架转变
之前的主流假设是端到端语音AI同时整合文字和语调。之后的证据显示,系统的内部表征严重偏向文本;语调只有在明确的元问题下才被激活。
之前(主流假设):                   之后(本文证据):
+------------------------------+   +------------------------------+
| 输入语音                       |   | 输入语音                       |
|   +--+  +--+                 |   |   +--+                       |
|   |语 |  |文 |                 |   |   |文 |  (主要)              |
|   |调 |  |字 |                 |   |   |字 |                       |
|   +--+  +--+                 |   |   +--+                       |
|      \  /                    |   |     |                        |
|       \/                     |   |     v                        |
|   +-----------+              |   | +-----------+               |
|   | 整合决策   |              |   | | 决策       |               |
|   |            |              |   | | (文字)     |               |
|   +-----------+              |   | +-----------+               |
|        |                     |   |     |                        |
|        v                     |   |     +---> (仅在被问到)        |
|  行动(考虑语调)            |   |          +---+               |
+------------------------------+   |          |语 |               |
                                   |          |调 |               |
                                   |          +---+               |
                                   +------------------------------+
一句话:从“整合多模态处理”到“文本优先、语调按需”,核心转变是发现生产级语音AI中感知与决策的解耦。
专家评审
选题眼光:真实且及时。情感识别基准与真实部署之间的脱节是众所周知的,但本文精准定位了具体的失败模式:不是系统听不到情感,而是它拒绝按情感行动。这处于安全性、用户体验和AI伦理的交汇点。
方法成熟度:巧劲而非蛮力。作者不构建任何东西,只是对现有API提出正确的探测性问题。更简单的方法(比如只测试标准情感分类器)只能展示感知能力,无法揭示感知-行动差距。唯一的弱点是他们依赖提示工程来引出两种模式——稍有不同的提示可能改变结果。
实验诚意:基线公平(同一音频的两种模式比较)。数字看起来很干净——3/4系统显示出差距。但是,场景数量有限(只有三个,且都是极端情绪),每个场景的样本量也很小(每个可能只有一个语句?)。值得警惕的是,论文没有报告方差或统计检验。另外,“感知模式”是在行动模式之后在同一会话中测试的,顺序效应可能带来偏差。
写作功力:摘要清晰,框架“听见了但没听进去”令人记忆深刻。论文可能在实验细节部分(如精确提示、系统版本、API调用时间戳)偷懒了。重写该部分并提供可复现的协议,就能把本文从一篇有煽动性的博文提升为扎实的科学贡献。
判决:弱接收——核心发现重要且可操作,但实验严谨性较浅,我把它当作一个有力的初步研究,而非最终结论。
要点总结
- 如果你在语调重要的场景中部署语音代理(客服、心理健康、欺诈检测),不要假设系统会自动利用语音线索。务必在所有不可逆操作之前增加显式的、强制性的语调检测步骤。
- 差距是提示依赖的:你可以将情感上下文嵌入到行动提示本身来缓解(例如“来电者的声音听起来很悲伤。除非他们明确说再见,否则不要结束通话。”)。但论文显示这只能部分起作用。
- 同样的解耦很可能也适用于其他非文本信号(例如背景噪音、用户的犹豫)。实践者应设计评估套件,不仅仅关注文字准确率,还要包含冲突场景,即语调与文字矛盾。