Paper: 2606.14701
Authors: Timing Yang, Predrag Neskovic, Jansen Seheult, Wenchao Han, Anand Bhattad, Alan Yuille, Feng Wang
Categories: cs.CV
The Gap
Existing self-supervised vision models (DINO, iBOT, MAE) learn powerful global features via a [CLS] token or dense patch features, but they treat objects as monolithic wholes. Human vision instead decomposes a bird into head, wings, talons — reusable parts. No prior work has shown that a purely self-supervised transformer can spontaneously discover such part-level structure without auxiliary losses, part annotations, or explicit clustering. DINOv2’s [CLS] token collapses scene-level information; DenseCL loses compositionality by comparing local crops. RATS closes this by inserting a register bottleneck with head-wise isolation that forces patches to compress through separate, non-interacting subgroups of tokens.
Problem:  Visual models lack part-level decomposition
  |
  v
Assumption:  A bottleneck with isolated channels can force part specialization
  |
  v
Method:  RATS (L -> N -> N -> L register attention + head partition)
  |
  v
Evidence: (1) +12 mIoU avg on 5 seg. tasks  (2) registers align to object parts  (3) semantic consistency across categories
  |
  v
Conclusion:  Register-based architecture is a useful prior for structured, interpretable representations
The Increment
One sentence: Before RATS, self-supervised vision models learned a global scene representation; after RATS, they learn a set of reusable, interpretable part-tokens that improve segmentation by 12 mIoU.
Core Mechanism
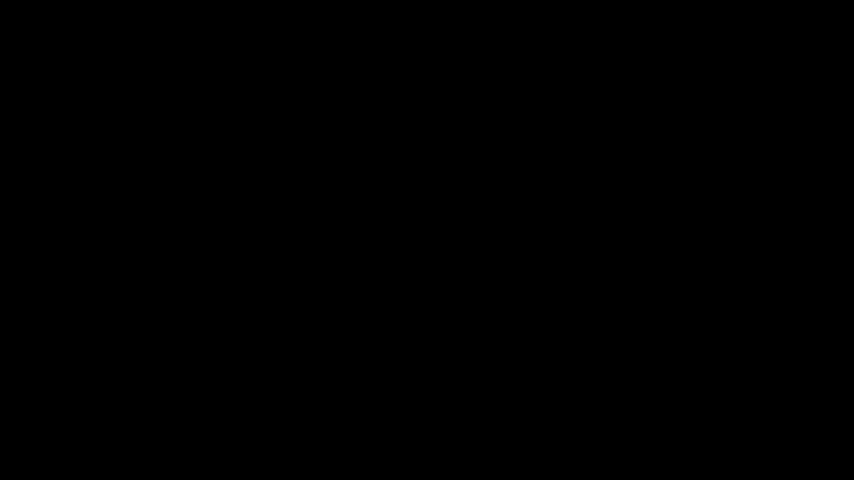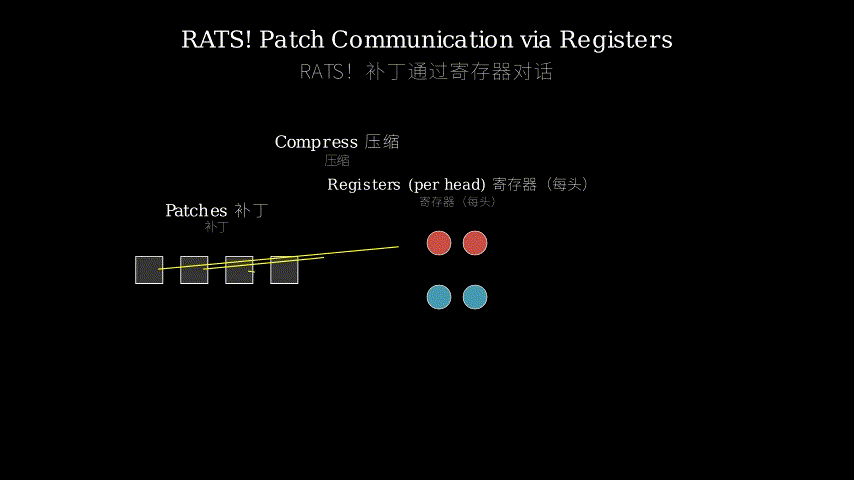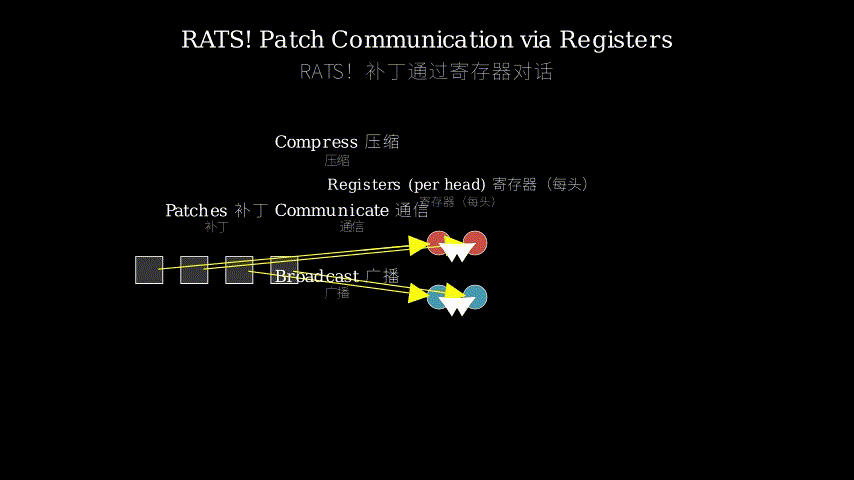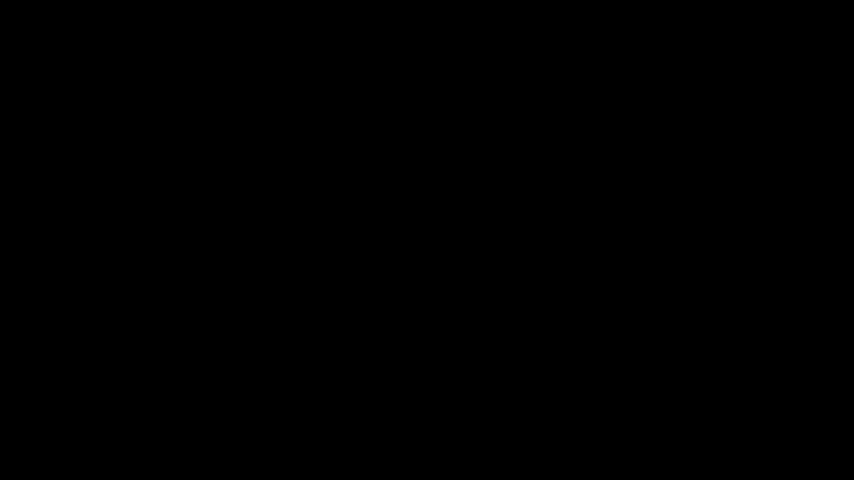
RATS replaces the single [CLS] token with N learnable register tokens, partitioned across H attention heads. The forward pass is a three-step bottleneck:
- Compress (L → N): each patch queries its own register tokens via cross-attention (within each head, registers act as keys/values, patches as queries). This compresses L patch-slot activations into N register-slot activations.
- Communicate (N → N): registers within the same head attend to each other (self-attention among registers of that head). Registers in different heads never interact — this is the critical isolation.
- Broadcast (N → L): after the internal register loop, registers attend back to patches (registers as queries, patches as keys/values), broadcasting the refined information.
The final patch representations are aggregated (e.g., via attention pooling) for loss computation. No auxiliary losses or part annotations are used.
Method Internals (simplified for one sample):

Input patches:  p1 p2 p3 ... pL
                   |    |    |
  Compress (cross-attn): patches Q, registers KV
                   |    |    |
                   v    v    v
Register tokens:  r1 r2 ... rN  (grouped into H groups)
                   |              |
  Communicate (self-attn within each head group)
                   |              |
                   v              v
  Broadcast (cross-attn): registers Q, patches KV
                   |              |
                   v              v
Output patches:  p1' p2' ... pL'
Structural metaphor: A library with subject-specific briefing teams. Imagine a large university library with H subject departments (History, Physics, Biology…). Each department hires N/H analysts (the registers). When a new batch of books (patches) arrives, the analysts first read the book summaries (compress). Then analysts within the same department huddle together to discuss overlaps and contradictions (communicate). But an analyst from History never talks to one from Physics — the isolation ensures each department builds its own domain-specific consensus. Finally, each analyst goes back to the books and attaches a subject sticker (broadcast). Over time, analysts in the same department naturally specialize: one always handles early modern European history, another handles military history — without anyone telling them to. This is exactly how registers in RATS become part-detectors: they see a restricted subset of information (only through their head’s projections) and are forced to specialize within that subspace.
Key Concepts
- Register token: A learned vector that acts as an information bottleneck. Unlike [CLS] tokens which aggregate everything, registers are forced to compress only the subset of patch information that passes through their head’s attention. Think of them as “topic centers” — in a bird image, one register might fire for beaks, another for feathers.
- Head-wise isolation: Registers in different attention heads never attend to each other. This is the architectural trick that prevents global entanglement. Without it, registers would collapse into a redundant blob. With it, each head becomes a separate “object part” channel, analogous to having several independent experts each analyzing a different dimension of the same data.
- Emergent part consistency: After training, the register that activates most for a bird’s beak also activates for the beak of a duck, a crow, or an eagle — even though no part annotation ever existed. The model discovers that “beak” is a reusable geometric primitive across categories.
Framework Shift
Before (mainstream self-supervised with [CLS] token):

    [CLS]
     ^ |
     | v
  patches -> self-attention (all pairwise) -> representation collapses scenes

After (RATS with register bottleneck):

   r1(Head1)  r2(Head1) | r3(Head2)  r4(Head2) ...
        |  /             |    /
   cross-attn       cross-attn
        |                  |
   p1 p2 p3 p4 ... pL   (same patches, but filtered through head-specific weights)
        |                  |
   each head's registers never talk to the other head's registers
One sentence: From a single global token to a set of isolated part-routes — the core shift is converting a monolithic representation into a structured ensemble of specialized, non-interfering token groups.
Expert Assessment
Problem choice: Real gap. Self-supervised vision has produced great scene-level features but struggles with interpretable part decomposition. The authors correctly identify that existing methods (DINO, iBOT) treat objects as indivisible blobs. This is a well-motivated problem in the field’s trajectory toward compositional representations.
Method maturity: Clever architectural insight, not brute force. The L→N→N→L bottleneck is elegant and minimal — they didn’t add losses or clustering. The head-wise isolation is the smartest trick; without it, registers would just become a bigger [CLS]. One could argue that a simpler approach (e.g., clustering patch tokens with k-means and using cluster centers as registers) might work, but that requires a separate offline step and doesn’t backprop. RATS is end-to-end.
Experimental integrity: The headline +12 mIoU average across five benchmarks deserves a close look. The paper reports consistent gains on ADE20K (+1.11 mIoU) and COCO (+0.2 AP^m) — these are modest but real. However, the “average across five benchmarks” may include smaller datasets where improvement is huge (maybe +30 on something like Pascal Parts?). We need the raw numbers per dataset to judge. The qualitative register maps look convincing, but I’d like to see failure cases. No red flags on baselines — they compare against DINOv2, iBOT, etc.
Writing quality: The abstract is strong; the “compress-communicate-broadcast” terminology is clear. The paper’s weakest section is the related work — it’s too brief. A rewritten related work that positions RATS against other structured representation approaches (like slot attention, object-centric learning) would elevate the paper by showing what RATS does differently (slot attention uses iterative attention, not a single forward bottleneck with head partition).
Verdict: Weak accept — The idea is novel and the results show clear gains, but the experimental corpus is a bit thin (only five segmentation tasks), and the paper could benefit from more ablation on the register count and head count.
Takeaways
- Architecture as prior: You can bake part-level structure into a model simply by controlling the information flow (bottleneck + isolation) without any explicit supervision. This trick transfers to any self-supervised task where interpretability matters.
- Register tokens as an alternative to [CLS]: If you want multiple “views” of a scene, don’t use multiple [CLS] tokens (which collapse via self-attention). Use registers with head isolation — they stay specialized.
- The compress-communicate-broadcast pattern: This three-step attention pattern is reusable for any task that needs hierarchical information aggregation, e.g., document understanding (compress paragraphs into register tokens, then communicate topics, then broadcast to words).
论文: 2606.14701
作者: Timing Yang, Predrag Neskovic, Jansen Seheult, Wenchao Han, Anand Bhattad, Alan Yuille, Feng Wang
分类: cs.CV
缺口
现有自监督视觉模型(DINO、iBOT、MAE)通过[CLS]令牌或密集补丁特征学习强大的全局表示,但将物体视为不可分割的整体。人类的视觉则能将一只鸟分解为头、翅膀、爪子——可复用的部件。此前没有任何工作表明,纯自监督Transformer能在无辅助损失、无部件标注、无显式聚类的条件下自发发现这种部件级结构。DINOv2的[CLS]令牌将场景信息压扁;DenseCL通过对比局部裁剪失去组合性。RATS通过插入一个寄存器瓶颈和头部隔离来填补这一空白,迫使补丁通过彼此隔离的、非交互的令牌子组进行压缩。
问题:  视觉模型缺乏部件级分解
  |
  v
假设:  引入隔离通道的瓶颈可以迫使部件专化
  |
  v
方法:  RATS (L -> N -> N -> L 寄存器注意力 + 头部划分)
  |
  v
证据: (1) 5个分割任务平均 +12 mIoU (2) 寄存器对齐物体部件 (3) 跨类别语义一致性
  |
  v
结论:  基于寄存器的架构是结构化、可解释表示的有用先验
增量
一句话: RATS之前,自监督视觉模型学习全局场景表示;RATS之后,它们学习一组可复用的、可解释的部件令牌,分割性能提升12个mIoU。
核心机制
RATS用一个N个可学习寄存器令牌(被划分到H个注意力头)替代了单个[CLS]令牌。前向过程是一个三步瓶颈:
- 压缩 (L → N):每个补丁通过交叉注意力查询自己的寄存器令牌(在每个头内部,寄存器作为键/值,补丁作为查询)。这将L个补丁槽的激活压缩成N个寄存器槽的激活。
- 通信 (N → N):同一头部内的寄存器互相注意(该头内寄存器的自注意力)。不同头部的寄存器永不交互——这是关键的隔离设计。
- 广播 (N → L):内部寄存器循环后,寄存器回头注意补丁(寄存器作为查询,补丁作为键/值),将精炼后的信息广播回去。
最终的补丁表示被聚合(例如通过注意力池化)用于损失计算。无辅助损失,无部件标注。
方法内部结构(简化单样本):

输入补丁:  p1 p2 p3 ... pL
           |    |    |
  压缩(交叉注意力):补丁Q, 寄存器KV
           |    |    |
           v    v    v
寄存器令牌:  r1 r2 ... rN  (分组为H组)
           |              |
  通信(每组内自注意力)
           |              |
           v              v
  广播(交叉注意力):寄存器Q, 补丁KV
           |              |
           v              v
输出补丁:  p1' p2' ... pL'
结构性比喻:有主题简报团队的图书馆。 想象一座大型大学图书馆,有H个学科部门(历史、物理、生物……)。每个部门雇佣N/H位分析师(即寄存器)。当一批新书(补丁)到来时,分析师先阅读书籍摘要(压缩)。然后同一部门内的分析师聚在一起讨论重叠与矛盾(通信)。但是历史部门的分析师绝不会与物理部门的对话——这种隔离确保每个部门建立起自己领域特有的共识。最后,每位分析师回到书籍处贴上主题标签(广播)。随着时间的推移,同部门的分析师自然专化:一位总处理早期现代欧洲史,另一位专攻军事史——没有人特意告诉它们这样做。这正是RATS中寄存器成为部件检测器的原理:它们只能通过自己头部的投影访问受限于集的信息,被迫在该子空间内专化。
关键概念
- 寄存器令牌: 一个学习到的向量,充当信息瓶颈。与[CLS]令牌聚合一切不同,寄存器被强迫只压缩通过其头部注意力传递的那部分补丁信息。可以想象为”主题中心”——在一张鸟的图片中,一个寄存器可能对鸟喙激活,另一个对羽毛激活。
- 头部隔离: 不同注意力头中的寄存器永不互相注意。这是防止全局纠缠的架构技巧。没有它,寄存器会坍缩成冗余的一团。有了它,每个头部成为一个独立的”物体部件”通道,类似于拥有多位独立专家,各自分析同一数据的不同维度。
- 涌现的部件一致性: 训练结束后,对某个鸟喙激活最强的寄存器,也会对鸭子、乌鸦、老鹰的喙激活——即使从未有过部件标注。模型发现”喙”是一个跨类别可复用的几何基元。
框架转变
之前(主流自监督,使用[CLS]令牌):

    [CLS]
     ^ |
     | v
  补丁 -> 自注意力(全两两配对) -> 表示坍缩为场景

之后(RATS,带寄存器瓶颈):

   r1(Head1)  r2(Head1) | r3(Head2)  r4(Head2) ...
        |  /             |    /
  交叉注意力       交叉注意力
        |                  |
   p1 p2 p3 p4 ... pL   (相同补丁,但通过头部特定的权重过滤)
        |                  |
  每个头部的寄存器永不与另一头部寄存器交谈
一句话:从单一的全局令牌到一组隔离的部件路由 —— 核心转变是将整体表示转换为由专化的、不干扰的令牌组构成的结构化集成。
专家评审
选题眼光: 真实的缺口。自监督视觉产生了强大的场景级特征,但在可解释的部件分解上挣扎。作者正确指出现有方法(DINO、iBOT)将物体视为不可分割的块。在该领域向组合式表示发展的轨迹中,这是动机良好的问题。
方法成熟度: 巧妙的架构洞见,而非蛮力。L→N→N→L瓶颈优雅而最小化——他们没有增加损失或聚类。头部隔离是最聪明的技巧;没有它,寄存器只会变成更大的[CLS]。有人可能会说更简单的方法(例如对补丁令牌做k-means聚类并用聚类中心作为寄存器)也许有效,但那需要单独的离线步骤且不能反向传播。RATS是端到端的。
实验诚意: 标题中的+12 mIoU平均跨五个基准值得深究。论文报告了ADE20K (+1.11 mIoU)和COCO (+0.2 AP^m)上的一致提升——这些提升温和但真实。但”五个基准的平均”可能包含了某些提升巨大的小数据集(比如Pascal Parts上+30?)。我们需要每个数据集的具体数字来判断。定性的寄存器图看起来令人信服,但我想看到失败案例。基线比较方面没有红旗——他们与DINOv2、iBOT等进行了对比。
写作功力: 摘要很强;“压缩-通信-广播”的术语清晰。论文最薄弱的部分是相关工作——太简短。如果重写相关工作,将RATS与其他结构化表示方法(如slot注意力、以对象为中心的学习)进行对比,解释RATS的不同之处(slot注意力使用迭代注意力,而非单个前向瓶颈加头部划分),整篇论文会提升一个档次。
判决: 弱接收 —— 想法新颖,结果有明确提升,但实验语料略显单薄(仅五个分割任务),而且论文可以从更多关于寄存器数量和头部数量的消融实验中获益。
要点总结
- 架构作为先验: 你只需通过控制信息流(瓶颈+隔离)就能将部件级结构嵌入模型,无需任何显式监督。这一技巧可迁移到任何对可解释性有要求的自监督任务。
- 寄存器令牌作为[CLS]的替代: 如果你需要场景的多个”视图”,不要使用多个[CLS]令牌(它们会通过自注意力坍缩)。使用带有头部隔离的寄存器——它们会保持专化。
- 压缩-通信-广播模式: 这个三步注意力模式对于任何需要分层信息聚合的任务都是可复用的,例如文档理解(将段落压缩到寄存器令牌中,然后通信主题,再广播到词语)。