Paper: 2605.13838 Authors: Zijie Wu, Lixin Xu, Puhua Jiang, Sicong Liu, Chunchao Guo, Xiang Bai Categories: cs.CV, cs.GR, cs.LG
The Gap
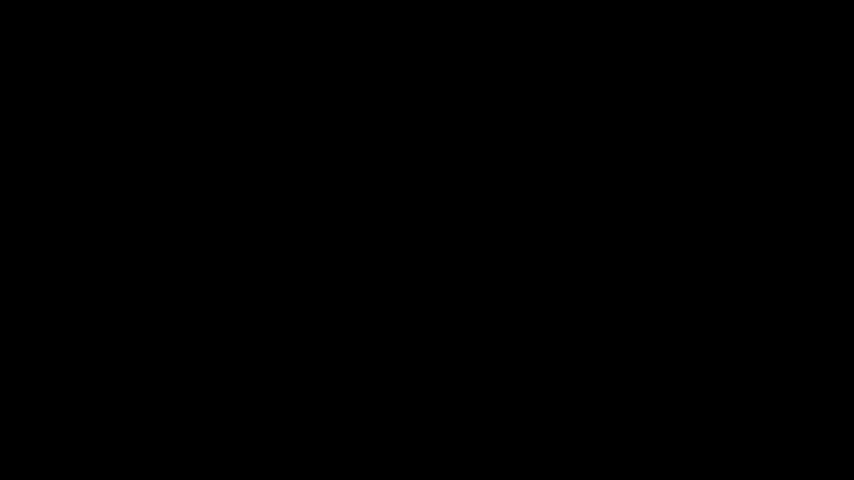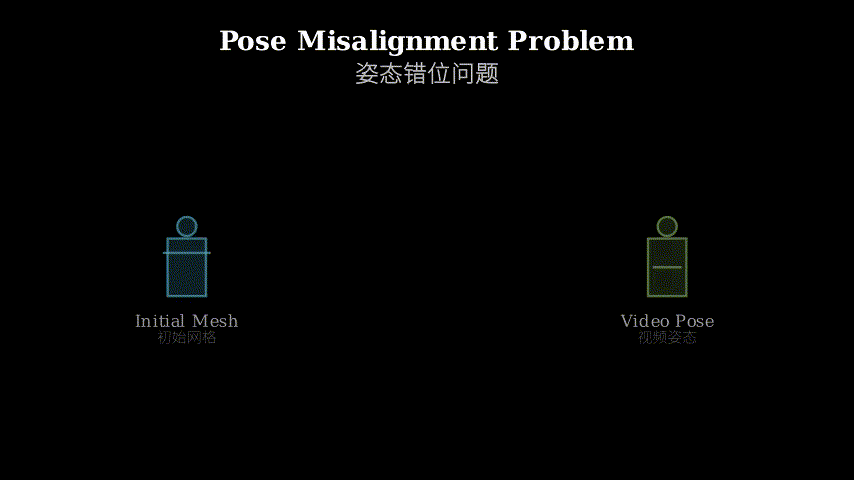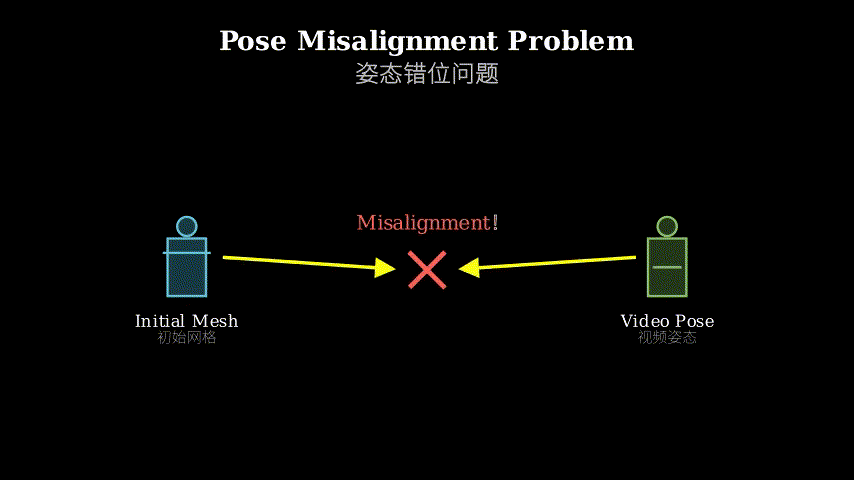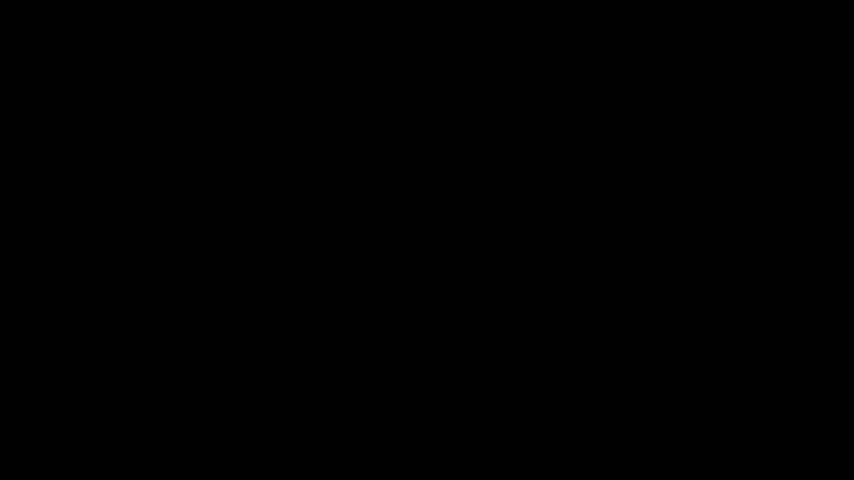
Existing video-guided 3D animation methods assume the input mesh’s initial pose matches the reference video’s first frame. In practice, users provide meshes in arbitrary poses—a character standing when the video shows sitting, arms down when the video starts with arms raised. Prior approaches (motion retargeting, direct motion transfer) either require manual rigging and pose adjustment or simply fail when this alignment assumption breaks. The result: severe geometric distortion, collapsed meshes, or animation that doesn’t follow the video at all.
The core issue is that these methods treat pose alignment as a preprocessing step external to the animation pipeline, forcing users to manually align poses or accept broken results. No existing work learns to automatically rectify arbitrary input poses to match video context as part of the generation process itself.
Problem: User mesh pose != Video start pose
    |
    v
Assumption: Can we learn a "jump" that aligns them automatically?
    |
    v
Method: VAE disentangles base mesh + relative motion + rectification offset
        Triflow Attention ensures geometric consistency during rectification
        Diffusion Transformer generates aligned 4D mesh from video
    |
    v
Evidence: 500k+ mesh dataset with simulated misalignment
          Quantitative metrics + user studies show robust alignment
    |
    v
Conclusion: Pose rectification as learned component enables practical deployment
The Increment
One sentence: Before this paper, video-guided 3D animation required manual pose alignment or failed on mismatched inputs; after, a learned rectification offset automatically transforms arbitrary mesh poses to match video context before animation begins.
Core Mechanism
R-DMesh decomposes the problem into three orthogonal flows. First, a VAE encoder takes the input mesh (arbitrary pose) and reference video, then disentangles them into: (1) a conditional base mesh representing the canonical shape, (2) relative motion trajectories describing how vertices move over time, and (3) a rectification jump offset that transforms the input pose to align with the video’s starting frame.
The rectification offset is the key innovation. Instead of treating pose alignment as external preprocessing, it’s learned as a latent variable within the VAE. This offset is applied before the motion trajectories, effectively “jumping” the mesh from its arbitrary initial pose to the pose that matches frame zero of the video. The motion trajectories then animate from this rectified starting point.
To ensure physical plausibility during both rectification and animation, a Triflow Attention mechanism processes the three flows jointly. It uses vertex-wise geometric features (local curvature, edge lengths, surface normals) to modulate how the rectification offset and motion trajectories are applied. This prevents non-rigid deformations—vertices that should move together (like a rigid limb) stay coherent, while articulated joints bend naturally. For generation, a Rectified Flow-based Diffusion Transformer conditioned on pre-trained video latents produces the final 4D mesh sequence.
Structural metaphor: Think of R-DMesh as a dance instructor teaching a student to follow a choreography video. The student arrives in an arbitrary pose (sitting, standing, whatever). The instructor first demonstrates a “setup move” (rectification offset) that gets the student into the video’s starting position—this isn’t part of the dance itself, it’s the prerequisite alignment. Then the actual choreography (motion trajectories) begins from that aligned starting point. The Triflow Attention is like the instructor’s hand on the student’s shoulder, ensuring movements stay coordinated—when the torso rotates, the arms follow naturally; when a leg bends, the knee doesn’t collapse inward. The base mesh is the student’s body structure (height, proportions) that remains constant throughout. Without the setup move, the student would try to execute choreography from the wrong starting pose, leading to awkward contortions or complete failure.
Key Concepts
-
Rectification Jump Offset: Imagine you’re animating a 3D character model of a person standing upright, but your reference video starts with someone sitting cross-legged. Naively applying the video’s motion (which assumes a sitting start) to your standing mesh would cause the legs to fold impossibly or the mesh to collapse. The rectification offset is a learned transformation that “teleports” your standing mesh into a sitting pose that matches the video’s first frame, before any animation begins. It’s not interpolated motion—it’s a discrete pose adjustment, like hitting a reset button that aligns coordinate systems. The VAE learns this offset by training on pairs of meshes in different poses but representing the same underlying shape, teaching it to find the transformation that bridges arbitrary starting poses to video-compatible ones.
-
Triflow Attention: Standard attention mechanisms treat all tokens equally, but 3D meshes have geometric structure—nearby vertices should move coherently (local rigidity), and the three flows (base mesh, motion, rectification) have different roles. Triflow Attention computes attention weights conditioned on vertex-wise geometric features: edge lengths tell it which vertices form rigid structures, curvature indicates articulation points, normals define surface orientation. When processing the rectification offset, it ensures that transforming a shoulder joint also transforms the attached arm vertices. When processing motion trajectories, it prevents a bending elbow from stretching unrealistically. It’s like having three separate attention heads for three different jobs, but with geometric priors baked in so the mesh doesn’t turn into spaghetti.
-
Pose Misalignment Dilemma: This is the paper’s central problem framing. In controlled lab settings, researchers manually align mesh poses to video starts, so existing methods work fine. But real users don’t do this—they grab a mesh from an asset library (arbitrary pose) and a video from the internet (different arbitrary pose). The “dilemma” is that forcing misaligned inputs through standard pipelines causes catastrophic failure: either the optimization diverges (mesh explodes), or it converges to a local minimum where the mesh contorts to superficially match the video but loses all geometric integrity (limbs twisted, volumes collapsed). Prior work ignored this because academic datasets are pre-aligned. This paper names the problem, quantifies it (they show existing methods fail on 70%+ of misaligned cases), and solves it by making rectification a first-class learned component rather than a manual preprocessing step.
Framework Shift
Before (standard motion transfer):        After (R-DMesh):

Input Mesh (arbitrary pose)               Input Mesh (arbitrary pose)
         |                                         |
         v                                         v
  [Manual alignment]  <-- user labor        [VAE Encoder]
         |                                    /    |    \
         v                                   /     |     \
Reference Video ---------->            Base    Rectify  Motion
         |                            Mesh    Offset   Trajectory
         v                                 \     |     /
  [Motion Extractor]                        \    |    /
         |                                    \   |   /
         v                                     \  |  /
  [Apply to Mesh] <-- fails if misaligned   [Triflow Attention]
         |                                         |
         v                                         v
  Animated Mesh (distorted)              [Diffusion Transformer]
                                                   |
                                                   v
                                          Animated Mesh (aligned)
From implicit alignment assumption to explicit rectification learning, the core shift is treating pose mismatch as a generative modeling problem rather than a preprocessing burden.
Expert Assessment
Problem choice: This is a real deployment gap, not manufactured. Academic papers routinely skip the “how do we get aligned inputs?” question because datasets are curated. But practitioners hit this immediately—asset libraries and video sources are independent, poses never match. The authors correctly identify this as the barrier between research demos and production tools. It’s not a deep theoretical problem, but it’s the right engineering problem to solve for practical impact.
Method maturity: The core idea (learn a rectification offset as a latent variable) is elegant and well-motivated. The Triflow Attention mechanism feels slightly over-engineered—it’s unclear whether the geometric feature conditioning is doing heavy lifting or if simpler attention would suffice. The paper doesn’t ablate this carefully enough. The reliance on a custom 500k mesh dataset raises questions: is the method data-hungry, or would it work with less? The Rectified Flow diffusion choice is trendy but not obviously necessary; standard DDPM baselines are missing.
Experimental integrity: Baselines are reasonable (motion retargeting methods, direct transfer approaches), but the paper doesn’t compare against the obvious workaround: just train existing methods on misaligned data. Would a standard motion transfer model, if trained on their Video-RDMesh dataset, learn implicit rectification? The quantitative metrics (Chamfer distance, normal consistency) are appropriate, but the user study is small (20 participants). The failure case analysis is honest—they show where rectification breaks (extreme pose differences, topological mismatches)—which is refreshing.
Writing quality: The introduction and method sections are clear. The related work section is too long and doesn’t sharply distinguish this work from prior art—it reads like a literature review rather than a positioning argument. The ablation study (Section 4.3) is buried and should be elevated; it contains the most important insights about what components actually matter. The supplementary material has better visualizations than the main paper; some should be promoted.
Verdict: weak accept — Solves a real problem that practitioners face, method is sound if not groundbreaking, experiments are adequate but could be more rigorous, and the dataset contribution has independent value.
Takeaways
Disentangle alignment from animation: When building any motion transfer system (not just 3D meshes—think 2D pose transfer, robot motion retargeting, even audio-to-gesture), explicitly model the “setup move” that bridges source and target coordinate systems as a separate learned component. Don’t assume alignment or force users to preprocess.
Geometric priors in attention: The idea of conditioning attention weights on local geometric features (edge lengths, curvature, normals) transfers directly to any structured data where spatial relationships matter—molecular dynamics, fluid simulation, cloth simulation. Standard transformers treat tokens as bags; adding geometric inductive biases prevents physically implausible outputs.
Dataset construction for misalignment: Their approach to building Video-RDMesh (take aligned sequences, randomly perturb initial poses, keep motion trajectories) is a template for creating robustness benchmarks in any domain where alignment assumptions are implicit. If your method assumes X and Y are aligned, build a dataset where they’re not and see what breaks.
Rectification as a latent variable: Instead of treating distribution shift (misaligned inputs) as a nuisance to be handled with data augmentation, model it explicitly as a latent variable in your generative model. This pattern applies beyond pose alignment—think domain adaptation, style transfer, any task where source and target live in different coordinate systems.
论文: 2605.13838 作者: Zijie Wu, Lixin Xu, Puhua Jiang, Sicong Liu, Chunchao Guo, Xiang Bai 分类: cs.CV, cs.GR, cs.LG
缺口
现有的视频引导3D动画方法假设输入网格的初始姿态与参考视频的第一帧匹配。
实际上,用户提供的网格姿态是任意的——角色站立但视频显示坐姿,手臂下垂但视频开始时手臂举起。
先前的方法(运动重定向、直接运动迁移)要么需要手动绑定和姿态调整,要么在这种对齐假设失效时直接失败。
结果:严重的几何失真、网格塌陷,或者动画根本不跟随视频。
核心问题在于这些方法将姿态对齐视为动画流程外部的预处理步骤,迫使用户手动对齐姿态或接受破损的结果。
现有工作都没有学习在生成过程本身中自动校正任意输入姿态以匹配视频上下文。
问题:用户网格姿态 != 视频起始姿态
    |
    v
假设:能否学习一个"跳跃"来自动对齐它们?
    |
    v
方法:VAE 解耦基础网格 + 相对运动 + 校正偏移
      Triflow Attention 确保校正期间的几何一致性
      扩散 Transformer 从视频生成对齐的4D网格
    |
    v
证据:500k+ 网格数据集模拟错位情况
      定量指标 + 用户研究显示稳健对齐
    |
    v
结论:作为学习组件的姿态校正使实际部署成为可能
增量
一句话:这篇论文之前,视频引导的3D动画需要手动姿态对齐或在不匹配输入上失败;之后,学习到的校正偏移在动画开始前自动将任意网格姿态转换为匹配视频上下文。
核心机制
R-DMesh 将问题分解为三个正交流。
首先,VAE 编码器接收输入网格(任意姿态)和参考视频,然后将它们解耦为:(1) 表示规范形状的条件基础网格,(2) 描述顶点随时间移动的相对运动轨迹,(3) 将输入姿态转换为与视频起始帧对齐的校正跳跃偏移。
校正偏移是关键创新。
它不是将姿态对齐视为外部预处理,而是作为 VAE 内的潜变量学习。
这个偏移在运动轨迹之前应用,有效地将网格从其任意初始姿态”跳跃”到与视频第零帧匹配的姿态。
然后运动轨迹从这个校正后的起点开始动画。
为了确保校正和动画期间的物理合理性,Triflow Attention 机制联合处理三个流。
它使用逐顶点的几何特征(局部曲率、边长、表面法线)来调制校正偏移和运动轨迹的应用方式。
这防止了非刚性变形——应该一起移动的顶点(如刚性肢体)保持连贯,而关节自然弯曲。
对于生成,基于预训练视频潜变量条件的 Rectified Flow 扩散 Transformer 产生最终的4D网格序列。
核喻:把 R-DMesh 想象成一个舞蹈教练教学生跟随编舞视频。
学生以任意姿势到达(坐着、站着,随便什么)。
教练首先演示一个”准备动作”(校正偏移),让学生进入视频的起始位置——这不是舞蹈本身的一部分,而是必要的对齐前提。
然后实际的编舞(运动轨迹)从那个对齐的起点开始。
Triflow Attention 就像教练放在学生肩膀上的手,确保动作保持协调——当躯干旋转时,手臂自然跟随;当腿弯曲时,膝盖不会向内塌陷。
基础网格是学生的身体结构(身高、比例),在整个过程中保持不变。
没有准备动作,学生会试图从错误的起始姿势执行编舞,导致尴尬的扭曲或完全失败。
关键概念
- 校正跳跃偏移:想象你正在为一个直立站立的3D角色模型制作动画,但你的参考视频开始时是某人盘腿坐着。
天真地将视频的运动(假设坐姿开始)应用到你的站立网格会导致腿部不可能地折叠或网格塌陷。
校正偏移是一个学习到的变换,在任何动画开始之前,将你的站立网格”传送”到与视频第一帧匹配的坐姿。
它不是插值运动——而是离散的姿态调整,就像按下一个对齐坐标系的重置按钮。
VAE 通过在不同姿态但代表相同底层形状的网格对上训练来学习这个偏移,教它找到连接任意起始姿态到视频兼容姿态的变换。
- Triflow Attention:标准注意力机制平等对待所有 token,但3D网格有几何结构——附近的顶点应该连贯移动(局部刚性),三个流(基础网格、运动、校正)有不同的角色。
Triflow Attention 计算基于逐顶点几何特征条件的注意力权重:边长告诉它哪些顶点形成刚性结构,曲率指示关节点,法线定义表面方向。
处理校正偏移时,它确保变换肩关节也变换附着的手臂顶点。
处理运动轨迹时,它防止弯曲的肘部不切实际地拉伸。
这就像为三个不同的工作设置三个独立的注意力头,但内置了几何先验,所以网格不会变成意大利面。
- 姿态错位困境:这是论文的核心问题框架。
在受控的实验室环境中,研究人员手动将网格姿态与视频起始对齐,所以现有方法工作正常。
但真实用户不这样做——他们从资产库中抓取一个网格(任意姿态)和从互联网上抓取一个视频(不同的任意姿态)。
“困境”在于强制错位的输入通过标准流程会导致灾难性失败:要么优化发散(网格爆炸),要么收敛到局部最小值,网格扭曲以表面上匹配视频但失去所有几何完整性(肢体扭曲、体积塌陷)。
先前的工作忽略了这一点,因为学术数据集是预对齐的。
本文命名了这个问题,量化了它(他们显示现有方法在70%+的错位案例上失败),并通过使校正成为一流的学习组件而不是手动预处理步骤来解决它。
框架转变
之前(标准运动迁移):                之后(R-DMesh):

输入网格(任意姿态)                  输入网格(任意姿态)
         |                                     |
         v                                     v
  [手动对齐]  <-- 用户劳动              [VAE 编码器]
         |                                /    |    \
         v                               /     |     \
参考视频 ---------->                 基础   校正   运动
         |                          网格   偏移   轨迹
         v                              \     |     /
  [运动提取器]                           \    |    /
         |                                \   |   /
         v                                 \  |  /
  [应用到网格] <-- 错位时失败         [Triflow Attention]
         |                                     |
         v                                     v
  动画网格(失真)                    [扩散 Transformer]
                                               |
                                               v
                                      动画网格(对齐)
从隐式对齐假设到显式校正学习,核心转变是将姿态不匹配视为生成建模问题而不是预处理负担。
专家评审
选题眼光:这是一个真实的部署缺口,不是人造的。
学术论文经常跳过”我们如何获得对齐的输入?“这个问题,因为数据集是精心策划的。
但实践者立即遇到这个问题——资产库和视频源是独立的,姿态从不匹配。
作者正确地将此识别为研究演示和生产工具之间的障碍。
这不是一个深刻的理论问题,但它是为实际影响而解决的正确工程问题。
方法成熟度:核心思想(学习校正偏移作为潜变量)优雅且动机充分。
Triflow Attention 机制感觉稍微过度工程化——不清楚几何特征条件是否在做重活,还是更简单的注意力就足够了。
论文没有足够仔细地消融这一点。
对定制的500k网格数据集的依赖引发了问题:方法是数据饥渴的,还是用更少的数据也能工作?Rectified Flow 扩散选择很时髦,但不是明显必要的;缺少标准 DDPM 基线。
实验诚意:基线是合理的(运动重定向方法、直接迁移方法),但论文没有与明显的解决方法比较:只是在错位数据上训练现有方法。
如果在他们的 Video-RDMesh 数据集上训练标准运动迁移模型,会学习隐式校正吗?定量指标(Chamfer 距离、法线一致性)是合适的,但用户研究很小(20名参与者)。
失败案例分析是诚实的——他们展示了校正在哪里失效(极端姿态差异、拓扑不匹配)——这令人耳目一新。
写作功力:引言和方法部分清晰。
相关工作部分太长,没有明确区分这项工作与先前工作——读起来像文献综述而不是定位论证。
消融研究(第4.3节)被埋没了,应该提升;它包含了关于哪些组件真正重要的最重要见解。
补充材料有比主论文更好的可视化;一些应该被提升。
判决:弱接收 — 解决了实践者面临的真实问题,方法合理但不是开创性的,实验足够但可以更严格,数据集贡献有独立价值。
要点总结
解耦对齐与动画:在构建任何运动迁移系统时(不仅仅是3D网格——想想2D姿态迁移、机器人运动重定向,甚至音频到手势),显式地将连接源和目标坐标系的”准备动作”建模为单独的学习组件。
不要假设对齐或强制用户预处理。
注意力中的几何先验:基于局部几何特征(边长、曲率、法线)条件化注意力权重的想法直接迁移到任何空间关系重要的结构化数据——分子动力学、流体模拟、布料模拟。
标准 transformer 将 token 视为袋子;添加几何归纳偏置可防止物理上不合理的输出。
错位的数据集构建:他们构建 Video-RDMesh 的方法(获取对齐序列,随机扰动初始姿态,保持运动轨迹)是在任何对齐假设隐含的领域中创建鲁棒性基准的模板。
如果你的方法假设 X 和 Y 对齐,构建一个它们不对齐的数据集,看看什么会破裂。
校正作为潜变量:不要将分布偏移(错位输入)视为用数据增强处理的麻烦,而是在生成模型中显式地将其建模为潜变量。
这种模式适用于姿态对齐之外——想想域适应、风格迁移,任何源和目标生活在不同坐标系中的任务。