Paper: 2605.16238 Authors: Sarah Martinson, Michael P. Brenner, Martyna Plomecka, Brian P. Williams, Nicholas G. Reich, Zahra Shamsi Categories: cs.AI
The Gap
Disease forecasting teams manually craft models for each pathogen and location. This expert-driven process works but doesn’t scale: when RSV surges in a new county or a novel pathogen emerges, you need epidemiologists to design models from scratch. The CDC hub aggregates human-curated models, but the curation bottleneck limits geographic granularity and response speed. Prior automated forecasting (statistical baselines, neural nets) either lacks interpretability or fails to incorporate domain theory, making them unsuitable for public health deployment where transparency matters.
Problem: Manual model curation bottleneck
   |
   v
Assumption: Epidemiological theory can be
            translated to code algorithmically
   |
   v
Method: LLM-guided tree search generates
        + evaluates + optimizes models
   |
   v
Evidence: Prospective 2025-26 evaluation
          matches CDC expert ensembles
   |
   v
Conclusion: Autonomous forecasting at scale
            without sacrificing accuracy
The Increment
One sentence: Before this paper, disease forecasting required expert teams to manually code models for each pathogen-location pair; after, an autonomous system generates comparable forecasts by searching the space of executable epidemiological models.
Core Mechanism
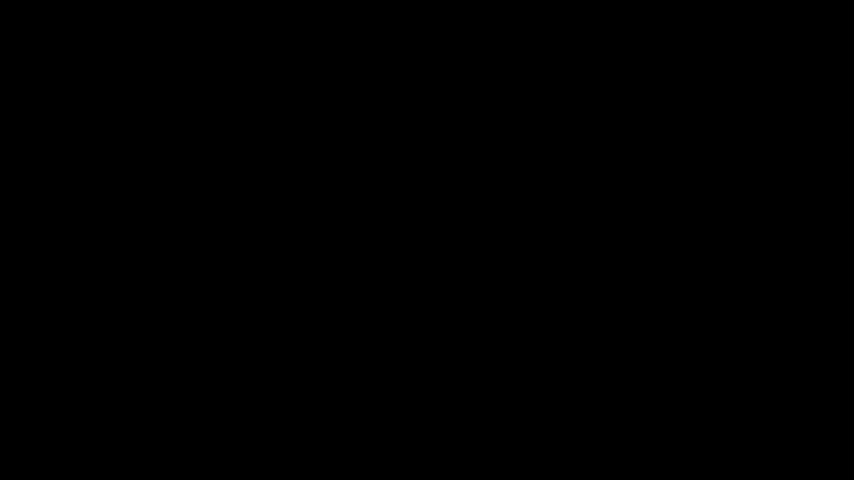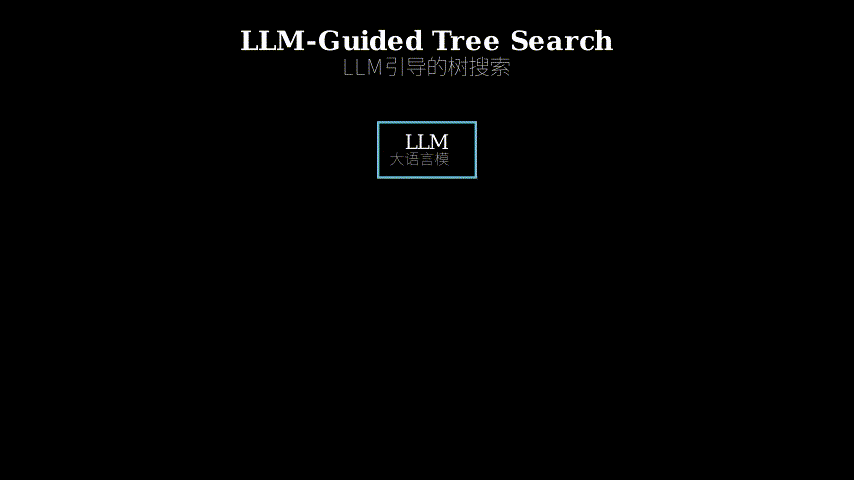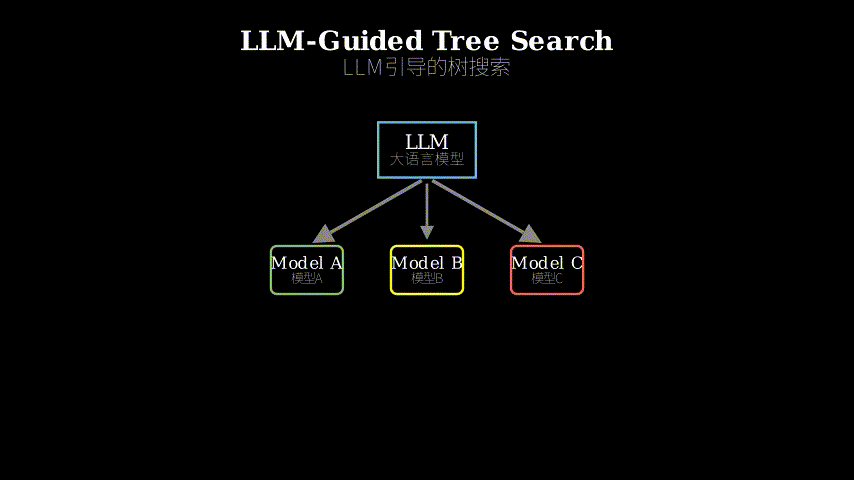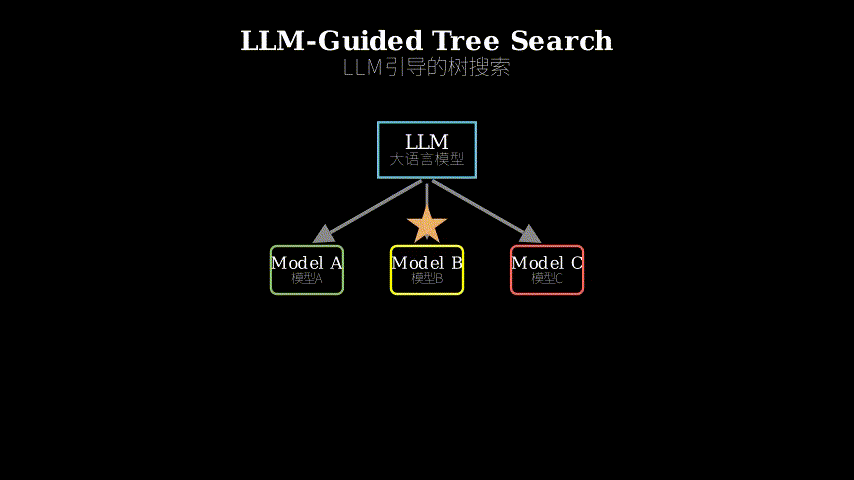
The system operates as a code-generating search process. An LLM proposes candidate forecasting models as executable Python code, guided by epidemiological theory from its training. Each candidate is evaluated on historical data using a log-scale distance metric. The search tree expands by mutating high-performing branches—refining data preprocessing, adjusting model structure, or trying different statistical approaches. An automated judge verifies that generated code actually implements the intended epidemiological mechanism (e.g., checking that an SEIR model truly has susceptible-exposed-infected-recovered compartments). The search runs until performance plateaus, then the top-k diverse models form an ensemble.
   [Epidemiological Theory]
            |
            v
    +---------------+
    |  LLM Proposer |  --> Generates Python code
    +---------------+      (ARIMA, SEIR, ensemble, etc.)
            |
            v
    +---------------+
    | Eval on Data  |  --> Log-scale distance metric
    +---------------+
            |
            v
    +---------------+
    | Judge Check   |  --> Structural fidelity test
    +---------------+
            |
            v
    Tree expansion: mutate high-performers
            |
            v
    Final ensemble of top-k models
Think of this as evolutionary recipe development in a test kitchen. The LLM is a chef who knows culinary theory (epidemiology) and proposes recipes (models). Each recipe gets cooked (executed on data) and tasted (evaluated). A food critic (judge) checks whether the dish actually follows the intended technique—if you claimed to make a soufflé, did it rise? The kitchen keeps the best recipes, tweaks them (tree search mutations), and tries variations. Eventually, you serve a tasting menu (ensemble) of the top dishes. The key insight: you don’t need the head chef to manually write every recipe if you have a system that can generate, test, and refine them automatically while respecting culinary principles.
Key Concepts
-
Log-scale distance metric: Standard forecasting metrics (mean absolute error, squared error) measure distance in absolute case counts. If a model predicts 1000 cases when truth is 1100, that’s an error of 100. But if it predicts 10 when truth is 110, that’s also 100—yet the second is a 10x mistake while the first is 10%. Log-scale metrics measure *relative error by comparing log(prediction) to log(truth). This prevents “reward hacking” where models game the metric by always predicting high numbers (large outbreaks dominate absolute error, so predicting big is safe). In epidemiology, getting the order of magnitude right matters more than exact counts, especially during exponential growth phases.
-
Judge-in-the-loop: The LLM can generate syntactically correct code that doesn’t actually implement the claimed epidemiological model. For example, it might output an SEIR model that skips the “exposed” compartment or uses the wrong differential equations. The judge is an automated verifier (itself an LLM with a specialized prompt) that reads the generated code and checks structural properties: Does this SEIR model have four compartments? Does transmission depend on susceptible-infected contact? Does it integrate the ODEs correctly? This catches “specification drift” where the search optimizes for metric performance by accidentally abandoning the theoretical framework.
Framework Shift
Before (mainstream approach):        After (this paper):

Expert Team                          LLM + Tree Search
    |                                     |
    v                                     v
Manual model design                  Auto-generate candidates
    |                                     |
    v                                     v
Code implementation                  Auto-evaluate on data
    |                                     |
    v                                     v
Validation + tuning                  Judge structural fidelity
    |                                     |
    v                                     v
Deploy for one pathogen              Ensemble top performers
                                          |
[Repeat for each new                      v
 pathogen/location]                  Deploy for all pathogens

Bottleneck: Human labor              Bottleneck: Compute budget
From artisanal model crafting to automated model discovery, the core shift is replacing human iteration with algorithmic search over the space of executable theories.
Expert Assessment
Problem choice: Real and well-motivated. The CDC hub exists precisely because manual forecasting doesn’t scale, and the 2025-26 prospective evaluation proves the problem isn’t hypothetical. The timing is good—LLMs are now capable enough to generate non-trivial scientific code, and disease forecasting has standardized evaluation infrastructure (FluSight, COVID-19 Forecast Hub).
Method maturity: The tree search + judge architecture is sound, but the heavy lifting happens inside the LLM’s ability to propose sensible models. The paper doesn’t deeply ablate what makes a good proposal distribution—how much comes from epidemiological pretraining vs. in-context examples vs. search dynamics? The log-scale metric fix is clever and well-justified. The judge-in-the-loop feels necessary but underexplored: how often does it catch real violations vs. false positives? What happens when the judge and the proposer are the same model family?
Experimental integrity: The prospective evaluation is the paper’s strongest asset—no hindsight bias, real-time comparison to CDC ensembles. The RSV “cold start” scenario is a good stress test. However, the baselines are somewhat limited: they compare to CDC hub ensembles (which aggregate human models) but not to other automated approaches like pure neural forecasters or simpler LLM-based methods without tree search. The ablations (log-scale metric, judge) are informative but narrow. I’d want to see: what if you just prompted GPT-4 to write one good model without search? How much does ensemble diversity matter?
Writing quality: The abstract and introduction are crisp. The methods section buries important details (judge prompt design, tree search hyperparameters) in ways that hurt reproducibility. The results focus heavily on aggregate performance but don’t show failure modes—when does the system generate nonsense? The discussion oversells “unprecedented scales” when the evaluation covers three pathogens in one country. A rewrite of the methods section with clearer algorithmic pseudocode and judge examples would elevate the paper significantly.
Verdict: weak accept — Solid prospective results and a real problem, but the method feels like “LLM + standard search + domain-specific fixes” rather than a fundamental innovation. The contribution is more engineering integration than algorithmic novelty, which is valuable but not groundbreaking.
Takeaways
Steal the log-scale evaluation trick: If your domain has exponential dynamics (finance, network growth, viral spread), standard error metrics let models game the system by predicting conservatively high. Switching to log-space forces models to get the growth rate right, not just the peak magnitude.
Judge-in-the-loop for scientific code generation: When generating code that must satisfy domain constraints (physical laws, statistical properties, algorithmic correctness), add a verification step that checks structural properties beyond “does it run?” This prevents the generator from finding shortcuts that optimize metrics while violating theory.
Ensemble diversity from search trees: Instead of training multiple models with different random seeds, use tree search to explore methodologically different approaches (ARIMA vs. mechanistic vs. ensemble) and aggregate them. The search naturally finds diverse high-performers if you penalize redundancy.
Cold start strategy: The RSV scenario shows that even with sparse historical data, the system can bootstrap by generating simple models (moving averages, naive baselines) and iteratively complexifying. This “start simple, search for complexity” approach transfers to any domain where you need to forecast a new phenomenon with limited data.
论文: 2605.16238 作者: Sarah Martinson, Michael P. Brenner, Martyna Plomecka, Brian P. Williams, Nicholas G. Reich, Zahra Shamsi 分类: cs.AI
缺口
疾病预测团队需要为每种病原体和地点手工设计模型。
这种专家驱动的流程有效但无法扩展:当RSV在新县爆发或新病原体出现时,你需要流行病学家从零开始设计模型。
CDC中心汇总人工策划的模型,但策划瓶颈限制了地理粒度和响应速度。
此前的自动预测(统计基线、神经网络)要么缺乏可解释性,要么无法融入领域理论,使其不适合需要透明度的公共卫生部署。
问题:手工模型策划瓶颈
   |
   v
假设:流行病学理论可以
      算法化地转译为代码
   |
   v
方法:LLM引导的树搜索
      生成+评估+优化模型
   |
   v
证据:2025-26前瞻性评估
      匹配CDC专家集成
   |
   v
结论:大规模自主预测
      不牺牲准确性
增量
一句话: 这篇论文之前,疾病预测需要专家团队为每个病原体-地点对手工编码模型;之后,自主系统通过搜索可执行流行病学模型的空间生成可比预测。
核心机制
系统作为代码生成搜索过程运行。
LLM提出候选预测模型作为可执行Python代码,由其训练中的流行病学理论引导。
每个候选在历史数据上使用对数尺度距离度量进行评估。
搜索树通过变异高性能分支来扩展——改进数据预处理、调整模型结构或尝试不同统计方法。
自动评判器验证生成的代码是否真正实现了预期的流行病学机制(例如,检查SEIR模型是否真的有易感-暴露-感染-康复四个仓室)。
搜索运行直到性能平稳,然后前k个多样化模型形成集成。
   [流行病学理论]
            |
            v
    +---------------+
    |  LLM提议器    |  --> 生成Python代码
    +---------------+      (ARIMA, SEIR, 集成等)
            |
            v
    +---------------+
    | 数据上评估    |  --> 对数尺度距离度量
    +---------------+
            |
            v
    +---------------+
    | 评判器检查    |  --> 结构保真度测试
    +---------------+
            |
            v
    树扩展:变异高性能者
            |
            v
    前k个模型的最终集成
把这想象成试验厨房中的进化食谱开发。
LLM是懂烹饪理论(流行病学)的厨师,提出食谱(模型)。
每个食谱被烹饪(在数据上执行)并品尝(评估)。
美食评论家(评判器)检查菜品是否真正遵循了预期技术——如果你声称做舒芙蕾,它膨起来了吗?厨房保留最佳食谱,调整它们(树搜索变异),并尝试变体。
最终,你端上品鉴菜单(集成)的顶级菜品。
关键洞察:如果你有一个能自动生成、测试和改进食谱的系统,同时尊重烹饪原则,你就不需要主厨手写每个食谱。
关键概念
- 对数尺度距离度量: 标准预测度量(平均绝对误差、平方误差)测量绝对病例数的距离。
如果模型预测1000例而真实值是1100,误差是100。
但如果预测10而真实值是110,也是100——然而第二个是10倍错误而第一个是10%。
对数尺度度量通过比较log(预测)和log(真实)来测量相对误差。
这防止了”奖励黑客”,即模型通过总是预测高数字来玩弄度量(大爆发主导绝对误差,所以预测大是安全的)。
在流行病学中,获得数量级正确比精确计数更重要,特别是在指数增长阶段。
- 评判器在环: LLM可以生成语法正确但实际上没有实现声称的流行病学模型的代码。
例如,它可能输出一个跳过”暴露”仓室或使用错误微分方程的SEIR模型。
评判器是一个自动验证器(本身是带有专门提示的LLM),读取生成的代码并检查结构属性:这个SEIR模型有四个仓室吗?传播依赖于易感-感染接触吗?它正确积分ODE了吗?这捕获了”规范漂移”,即搜索通过意外放弃理论框架来优化度量性能。
框架转变
之前(主流方法):                之后(本文方法):

专家团队                          LLM + 树搜索
    |                                     |
    v                                     v
手工模型设计                      自动生成候选
    |                                     |
    v                                     v
代码实现                          数据上自动评估
    |                                     |
    v                                     v
验证+调优                         评判结构保真度
    |                                     |
    v                                     v
为一种病原体部署                  集成顶级表现者
                                          |
[为每个新病原体/                          v
 地点重复]                        为所有病原体部署

瓶颈:人力劳动                    瓶颈:计算预算
从手工模型制作到自动模型发现,核心转变是用算法搜索可执行理论空间替代人类迭代。
专家评审
选题眼光: 真实且动机充分。
CDC中心的存在恰恰因为手工预测无法扩展,2025-26前瞻性评估证明问题不是假设的。
时机很好——LLM现在足够强大可以生成非平凡的科学代码,疾病预测有标准化的评估基础设施(FluSight、COVID-19预测中心)。
方法成熟度: 树搜索+评判器架构是合理的,但繁重的工作发生在LLM提出合理模型的能力内部。
论文没有深入消融什么构成好的提议分布——有多少来自流行病学预训练vs上下文示例vs搜索动态?对数尺度度量修复是巧妙且有充分理由的。
评判器在环感觉必要但探索不足:它多久捕获一次真正的违规vs假阳性?当评判器和提议器是同一模型家族时会发生什么?
实验诚意: 前瞻性评估是论文最强资产——没有后见之明偏差,与CDC集成实时比较。
RSV”冷启动”场景是一个好的压力测试。
然而,基线有些局限:它们与CDC中心集成(汇总人类模型)比较,但不与其他自动方法如纯神经预测器或没有树搜索的更简单基于LLM的方法比较。
消融(对数尺度度量、评判器)信息丰富但狭窄。
我想看到:如果你只是提示GPT-4写一个好模型而不搜索会怎样?集成多样性有多重要?
写作功力: 摘要和引言简洁。
方法部分以损害可重复性的方式埋藏重要细节(评判器提示设计、树搜索超参数)。
结果重点关注聚合性能但不显示失败模式——系统何时生成无意义内容?讨论过度推销”前所未有的规模”,而评估覆盖一个国家的三种病原体。
用更清晰的算法伪代码和评判器示例重写方法部分将显著提升论文。
判决: 弱接收 — 扎实的前瞻性结果和真实问题,但方法感觉像”LLM+标准搜索+领域特定修复”而非根本创新。
贡献更多是工程集成而非算法新颖性,这有价值但不是突破性的。
要点总结
偷走对数尺度评估技巧: 如果你的领域有指数动态(金融、网络增长、病毒传播),标准误差度量让模型通过保守预测高来玩弄系统。
切换到对数空间迫使模型获得增长率正确,而不仅仅是峰值幅度。
科学代码生成的评判器在环: 当生成必须满足领域约束(物理定律、统计属性、算法正确性)的代码时,添加一个验证步骤,检查超越”它运行吗?“的结构属性。
这防止生成器找到优化度量但违反理论的捷径。
从搜索树获得集成多样性: 不是用不同随机种子训练多个模型,而是使用树搜索探索方法论上不同的方法(ARIMA vs机械vs集成)并聚合它们。
如果你惩罚冗余,搜索自然找到多样化的高性能者。
冷启动策略: RSV场景显示即使历史数据稀疏,系统也可以通过生成简单模型(移动平均、朴素基线)并迭代复杂化来引导。
这种”从简单开始,搜索复杂性”方法转移到任何需要用有限数据预测新现象的领域。