Paper: 2605.18732 Authors: Matthew L. Smith, Jonathan P. Shock, Samuel T. Segun, Iyiola E. Olatunji, Tegawendé F. Bissyandé Categories: cs.CL, cs.AI, cs.LG
The Gap
We know scaling laws predict aggregate LLM performance — more parameters, better benchmarks. But when you ask GPT-4 about a specific fact, why does it nail some and hallucinate others? Existing scaling laws treat the model as a black box averaging over all tasks. They don’t explain why the same model recalls “Einstein’s 1905 papers” flawlessly but fabricates citations for obscure 1987 conference proceedings.
Prior work (Carlini et al., Kandpal et al.) showed training data frequency matters for memorization. Separately, we know bigger models store more facts. But no one had quantified how these two variables — model size and topic frequency in training data — jointly determine factual recall quality. The gap: no predictive model linking architectural scale and data composition to fact-level performance.
Problem: Why do LLMs recall some facts but hallucinate others?
   |
   v
Hypothesis: Recall = f(model_size, data_frequency)
   |
   v
Method: Test 38 models on 8,900 scholarly references
        Measure: parameter count + topic frequency in training corpus
   |
   v
Evidence: Sigmoid fit in log-linear space
          R^2 = 0.60 across families, 0.74-0.94 within families
   |
   v
Conclusion: Signal-to-noise ratio gates recall
            Signal ~ frequency, Noise floor ~ 1/capacity
The Increment
One sentence: Before this paper, we knew bigger models and more training examples help separately; after, we have a quantitative law predicting factual recall from the interaction of model capacity and concept frequency in training data.
Core Mechanism
The authors treat factual recall as a signal detection problem. Each fact in the training corpus generates a “signal” proportional to how often it appears. The model’s internal representation space has a “noise floor” that decreases as parameter count grows — more capacity means cleaner separation between stored concepts.
They tested 38 models (7M to 405B parameters) from families like Llama, Qwen, Gemma, and Phi on 8,900 scholarly references spanning physics, math, CS, and biology. For each reference, they measured two things: (1) how many parameters the model has, and (2) how frequently the reference’s topic appears in a proxy training corpus (arXiv papers). They used an automated citation verification system to score recall quality on a 0-1 scale.
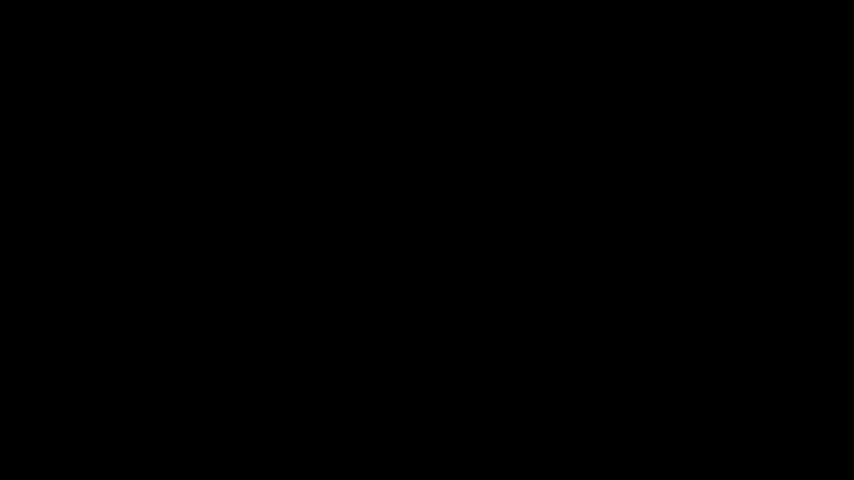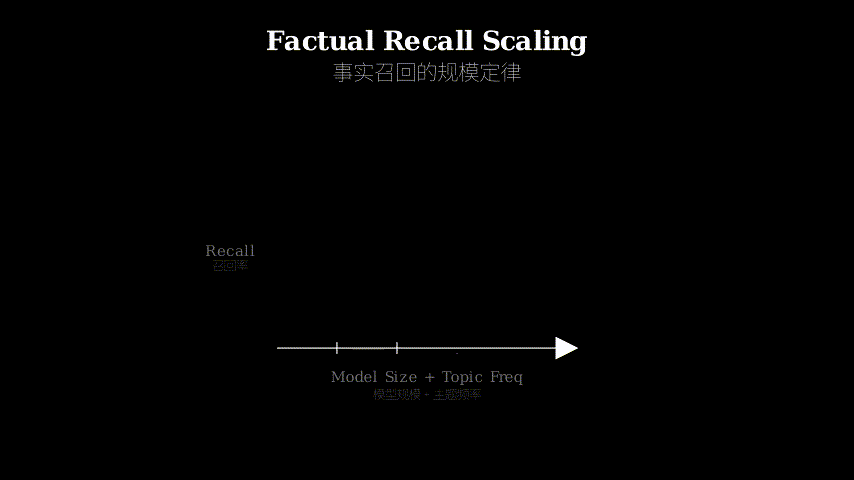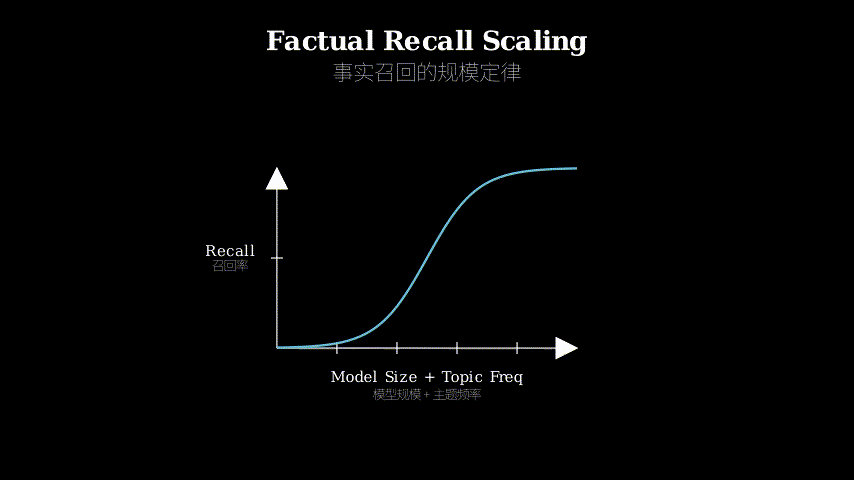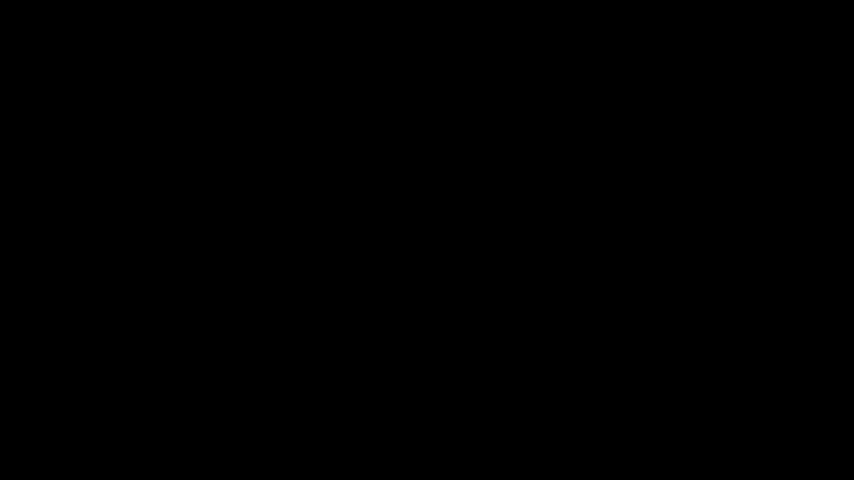
The key finding: recall quality follows a sigmoid curve when plotted against log(params) + β·log(frequency). The sigmoid shape means there’s a threshold — below it, the model mostly hallucinates; above it, recall becomes reliable. The log-linear combination captures the multiplicative interaction: doubling parameters has the same effect as increasing topic frequency by a factor of 2^(1/β).
Training Data               Model Internals              Output
--------------             -------------------          --------
Topic appears              Concept vector               Recall
N times                    embedded in                  quality
    |                      parameter space              score
    v                            |                         ^
Frequency                  Signal strength               |
signal                     = log(N)                      |
    |                            |                        |
    +----------> Combined -----> SNR -------> Sigmoid -->+
    |            with model      threshold    activation
    |            capacity                     function
    v                            ^
log(params)                Noise floor
increases                  = -log(params)
capacity
Think of the model as a radio receiver trying to pick up stations. Each fact is a radio station broadcasting at a power proportional to how often it appeared in training (frequency = signal strength). The model’s parameter count determines the quality of its antenna and noise-canceling circuitry (capacity = noise suppression). A weak station (rare fact) needs a really good receiver (large model) to come through clearly. A strong station (common fact) can be heard even on a cheap radio (small model). But there’s a threshold: below a certain signal-to-noise ratio, you get static (hallucinations); above it, you get clear audio (accurate recall). The sigmoid curve is the transition from static to clarity as you turn up either the broadcast power or the receiver quality.
Key Concepts
-
Superposition in neural networks: Imagine a library where books are stored not on individual shelves but as holograms — each hologram contains fragments of many books overlapping in the same physical space. When you shine light through the hologram at the right angle (query the network), one book’s image emerges clearly while others fade into noise. Neural networks store concepts this way: a single parameter participates in representing many different facts simultaneously. The “right angle” is the activation pattern that isolates one concept from the superposition. This works because most concepts are only needed rarely, so their representations can overlap without constant interference. But if two concepts are too similar or the storage is too crowded (small model, many facts), they interfere destructively — you get a blurry image (hallucination) instead of a clear one (correct recall).
-
Signal-to-noise ratio (SNR) as a gating mechanism: In communication theory, SNR determines whether a message gets through. Below a threshold, the receiver can’t distinguish signal from noise — it might as well be guessing. Above the threshold, error rates drop exponentially. The authors propose LLM recall works the same way: each fact has a signal strength (training frequency) and the model has a noise floor (inversely proportional to capacity). When
signal/noise > threshold, the model reliably recalls the fact. Whensignal/noise < threshold, it confabulates. The sigmoid shape in their data is the hallmark of this threshold behavior — it’s not a gradual improvement but a phase transition from unreliable to reliable recall.
Framework Shift
Before (aggregate scaling laws):        After (this paper):

Performance                              Recall Quality
    ^                                        ^
    |     /                                  |         ___---
    |    /                                   |      _--
    |   /                                    |    _-
    |  /                                     |  _-
    | /                                      | /
    |/                                       |/___________
    +----------> Model Size                  +----------> log(params) + β·log(freq)

Single curve for all tasks               Fact-specific curves
No role for data composition             Data frequency is load-bearing
One sentence: From treating models as uniform black boxes that improve monotonically with scale, to recognizing factual recall as a threshold phenomenon gated by the interaction of architectural capacity and training data composition.
Expert Assessment
Problem choice: This is a real gap. Scaling laws have been phenomenally useful for predicting aggregate performance, but practitioners care about reliability on specific facts — especially in domains like medicine or law where hallucinations are costly. The choice to focus on scholarly references is smart: they’re verifiable, span difficulty levels, and have measurable frequency in training corpora. The problem sits at the intersection of interpretability (why do models fail?) and practical deployment (when can we trust them?).
Method maturity: The approach is elegant but not novel — it’s applying signal detection theory to LLM behavior. The real contribution is empirical: they actually measured topic frequency in a proxy corpus and tested across 38 models. The sigmoid fit is clean, but the 60% variance explained across families suggests other factors matter (architecture differences, tokenization, training dynamics). The within-family R² of 74-94% is more convincing. One concern: they use arXiv as a proxy for training data, but models are trained on web scrapes with different distributions. The correlation might hold because arXiv frequency correlates with general web frequency, not because it’s the actual training data.
Experimental integrity: Baselines are fair — they compare models from different families at different scales. The automated citation verification is a strength (no human annotation bias), but also a limitation (it can’t catch subtle errors like correct author, wrong year). The 8,900 references are well-distributed across fields, but all are scholarly citations — does this generalize to other fact types (historical events, product specs)? The paper doesn’t test that. The sigmoid fit is convincing, but they don’t show residuals or test alternative functional forms rigorously. A Bayesian model comparison would strengthen the claim that sigmoid-in-log-space is the right functional form.
Writing quality: The abstract and introduction are crisp. The methods section is dense but complete. The results section leans too heavily on figures — the text should walk through the key numbers more explicitly. The discussion connects to superposition theory, which is intellectually satisfying, but the mechanistic link is speculative (they don’t probe model internals to confirm superposition). The paper would benefit from a limitations section acknowledging the proxy corpus issue and the narrow fact domain. The related work section undersells prior work on memorization (Carlini, Kandpal) — this paper is more incremental than the framing suggests.
Verdict: weak accept — Solid empirical contribution with a clean quantitative result, but the mechanistic story is underdeveloped and the generalization beyond scholarly citations is untested.
Takeaways
For practitioners: If you’re deploying an LLM in a domain where factual accuracy matters, this paper gives you a heuristic for risk assessment. Facts that are rare in training data need much larger models to recall reliably. You can estimate risk by checking how often your domain appears in web corpora (use Common Crawl statistics as a proxy). If you’re stuck with a smaller model, focus on facts that are well-represented in training data or use retrieval augmentation for rare facts.
For researchers: The sigmoid-in-log-space functional form is a testable prediction. If you’re working on interpretability, check whether this pattern holds for other fact types (not just citations). If you’re training models, this suggests a data curation strategy: for facts you care about, ensure they appear above the frequency threshold for your model size. The SNR framing also suggests a path to better prompting: if you can increase “signal” by providing context that primes the relevant concept, you might push marginal facts over the recall threshold.
For theorists: The connection to superposition is tantalizing but needs mechanistic validation. Can you probe model internals to show that rare facts have noisier representations? Does the noise floor actually scale as 1/params, or is that an approximation? The sigmoid shape suggests a phase transition — is there a statistical mechanics analogy that predicts the transition point from first principles?
论文: 2605.18732 作者: Matthew L. Smith, Jonathan P. Shock, Samuel T. Segun, Iyiola E. Olatunji, Tegawendé F. Bissyandé 分类: cs.CL, cs.AI, cs.LG
缺口
我们知道缩放定律能预测大语言模型的总体性能——参数越多,基准测试越好。
但当你问 GPT-4 一个具体事实时,为什么它有些答得完美,有些却胡编乱造?
现有缩放定律把模型当作黑箱,对所有任务取平均。
它们无法解释为什么同一个模型能完美回忆”爱因斯坦1905年的论文”,却会捏造1987年某个冷门会议的引用。
先前工作(Carlini等人,Kandpal等人)表明训练数据频率影响记忆。
另一方面,我们知道更大的模型能存储更多事实。
但没人量化过这两个变量——模型规模和主题在训练数据中的频率——如何共同决定事实召回质量。
缺口在于:没有预测模型将架构规模和数据组成与事实级性能联系起来。
问题:为什么大语言模型能回忆某些事实却幻觉其他事实?
   |
   v
假设:召回 = f(模型规模, 数据频率)
   |
   v
方法:在8900个学术引用上测试38个模型
      测量:参数数量 + 主题在训练语料中的频率
   |
   v
证据:对数线性空间中的S型拟合
      R^2 = 0.60(跨模型家族),0.74-0.94(家族内)
   |
   v
结论:信噪比控制召回
      信号 ~ 频率,噪声底 ~ 1/容量
增量
一句话:这篇论文之前,我们知道更大的模型和更多训练样本分别有帮助;
之后,我们有了一个定量定律,能从模型容量和概念在训练数据中的频率的交互作用预测事实召回。
核心机制
作者将事实召回视为信号检测问题。
训练语料中的每个事实产生一个”信号”,强度与其出现频率成正比。
模型的内部表示空间有一个”噪声底”,随着参数数量增长而降低——更大的容量意味着存储概念之间的分离更清晰。
他们在来自 Llama、Qwen、Gemma 和 Phi 等家族的38个模型(7M到405B参数)上测试了8900个学术引用,涵盖物理、数学、计算机科学和生物学。
对每个引用,他们测量两件事:(1) 模型有多少参数,(2) 引用的主题在代理训练语料(arXiv论文)中出现的频率。
他们使用自动引用验证系统对召回质量打分,范围0-1。
关键发现:当对 log(参数) + β·log(频率) 作图时,召回质量遵循S型曲线。
S型形状意味着存在阈值——低于阈值,模型主要产生幻觉;
高于阈值,召回变得可靠。
对数线性组合捕捉了乘法交互:参数翻倍的效果等同于将主题频率增加 2^(1/β) 倍。
训练数据               模型内部              输出
--------              --------            ------
主题出现              概念向量             召回
N次                   嵌入在               质量
  |                   参数空间             评分
  v                       |                  ^
频率                  信号强度               |
信号                  = log(N)               |
  |                       |                  |
  +--------> 与模型 -----> 信噪比 ----> S型 -->+
  |          容量组合      阈值        激活
  |                       ^           函数
  v                       |
log(参数)            噪声底
增加容量             = -log(参数)
把模型想象成一台收音机,试图接收电台。
每个事实是一个广播电台,发射功率与它在训练中出现的频率成正比(频率=信号强度)。
模型的参数数量决定了天线和降噪电路的质量(容量=噪声抑制)。
弱电台(罕见事实)需要非常好的接收器(大模型)才能清晰接收。
强电台(常见事实)即使在廉价收音机(小模型)上也能听到。
但存在阈值:低于某个信噪比,你得到的是杂音(幻觉);
高于阈值,你得到清晰的音频(准确召回)。
S型曲线是从杂音到清晰的过渡,当你提高广播功率或接收器质量时发生。
关键概念
- 神经网络中的叠加:想象一个图书馆,书不是存放在单独的书架上,而是作为全息图——每个全息图包含许多书的片段,在同一物理空间中重叠。
当你以正确的角度照射全息图(查询网络)时,一本书的图像清晰浮现,而其他书淡入噪声。
神经网络以这种方式存储概念:单个参数同时参与表示许多不同的事实。
“正确的角度”是从叠加中分离出一个概念的激活模式。
这之所以有效,是因为大多数概念只是偶尔需要,所以它们的表示可以重叠而不会持续干扰。
但如果两个概念太相似或存储太拥挤(小模型,许多事实),它们会破坏性干扰——你得到模糊的图像(幻觉)而不是清晰的图像(正确召回)。
- 信噪比(SNR)作为门控机制:在通信理论中,信噪比决定消息是否能传达。
低于阈值,接收器无法区分信号和噪声——它可能只是在猜测。
高于阈值,错误率呈指数下降。
作者提出大语言模型召回以同样方式工作:每个事实有一个信号强度(训练频率),模型有一个噪声底(与容量成反比)。
当 信号/噪声 > 阈值 时,模型可靠地召回事实。
当 信号/噪声 < 阈值 时,它产生幻觉。
他们数据中的S型形状是这种阈值行为的标志——这不是渐进改善,而是从不可靠到可靠召回的相变。
框架转变
之前(总体缩放定律):              之后(本文):

性能                                召回质量
  ^                                    ^
  |     /                              |         ___---
  |    /                               |      _--
  |   /                                |    _-
  |  /                                 |  _-
  | /                                  | /
  |/                                   |/___________
  +----------> 模型规模                 +----------> log(参数) + β·log(频率)

所有任务的单一曲线                    事实特定的曲线
数据组成不起作用                      数据频率是承重的
一句话:从将模型视为随规模单调改善的均匀黑箱,到认识到事实召回是由架构容量和训练数据组成的交互作用控制的阈值现象。
专家评审
选题眼光:这是真缺口。
缩放定律在预测总体性能方面非常有用,但实践者关心特定事实的可靠性——尤其在医学或法律等幻觉代价高昂的领域。
选择关注学术引用很聪明:它们可验证,跨越难度级别,在训练语料中有可测量的频率。
问题位于可解释性(为什么模型失败?
)和实际部署(何时可以信任它们?
)的交叉点。
方法成熟度:方法优雅但不新颖——它是将信号检测理论应用于大语言模型行为。
真正的贡献是经验性的:他们实际测量了代理语料中的主题频率,并在38个模型上测试。
S型拟合很干净,但跨家族解释的60%方差表明其他因素也很重要(架构差异、分词、训练动态)。
家族内74-94%的R²更有说服力。
一个担忧:他们使用arXiv作为训练数据的代理,但模型是在具有不同分布的网络爬取数据上训练的。
相关性可能成立是因为arXiv频率与一般网络频率相关,而不是因为它是实际的训练数据。
实验诚意:基线公平——他们比较了不同家族、不同规模的模型。
自动引用验证是优势(无人工标注偏差),但也是局限(无法捕捉微妙错误,如作者正确但年份错误)。
8900个引用在各领域分布良好,但都是学术引用——这能推广到其他事实类型(历史事件、产品规格)吗?
论文没有测试这一点。
S型拟合令人信服,但他们没有展示残差或严格测试替代函数形式。
贝叶斯模型比较会加强”对数空间中的S型”是正确函数形式的主张。
写作功力:摘要和引言简洁。
方法部分密集但完整。
结果部分过度依赖图表——文本应该更明确地走过关键数字。
讨论部分与叠加理论联系,这在智识上令人满意,但机制联系是推测性的(他们没有探测模型内部以确认叠加)。
论文会受益于一个局限性部分,承认代理语料问题和狭窄的事实领域。
相关工作部分低估了关于记忆的先前工作(Carlini,Kandpal)——这篇论文比框架暗示的更增量。
判决:弱接收 — 扎实的经验贡献,有干净的定量结果,但机制故事欠发达,超越学术引用的泛化未经测试。
要点总结
对实践者:如果你在事实准确性重要的领域部署大语言模型,这篇论文给你一个风险评估启发式。
在训练数据中罕见的事实需要大得多的模型才能可靠召回。
你可以通过检查你的领域在网络语料中出现的频率来估计风险(使用Common Crawl统计作为代理)。
如果你被困在较小的模型上,专注于在训练数据中有良好表示的事实,或对罕见事实使用检索增强。
对研究者:对数空间中的S型函数形式是可测试的预测。
如果你在做可解释性工作,检查这种模式是否适用于其他事实类型(不仅仅是引用)。
如果你在训练模型,这暗示了一种数据策划策略:对于你关心的事实,确保它们出现在你的模型规模的频率阈值之上。
信噪比框架也暗示了更好的提示路径:如果你能通过提供启动相关概念的上下文来增加”信号”,你可能会将边缘事实推过召回阈值。
对理论家:与叠加的联系诱人但需要机制验证。
你能探测模型内部以显示罕见事实有更嘈杂的表示吗?
噪声底真的按 1/参数 缩放,还是这只是近似?
S型形状暗示相变——是否有统计力学类比能从第一原理预测转变点?