Paper: 2604.06129 Authors: David Picard, Nicolas Dufour, Lucas Degeorge, Arijit Ghosh, Davide Allegro, Tom Ravaud, Yohann Perron, Corentin Sautier, Zeynep Sonat Baltaci, Fei Meng Categories: cs.CV, cs.AI
The Gap
Self-attention has dominated sequence modeling since 2017, but it carries a dirty secret: O(n²) complexity. For every token you add, the computational cost grows quadratically. This isn’t just a theoretical concern—it’s a wall that practitioners hit when working with long documents, high-resolution images, or extended video sequences. Prior attempts to fix this fall into two camps: sparse attention patterns (Longformer, BigBird) that sacrifice global context, and linear approximations (Performer, RWKV) that often underperform standard attention on benchmarks. The field has been stuck in a trade-off: either pay the quadratic tax or accept degraded performance.
Problem: Self-attention O(n^2) blocks long sequences
                    |
                    v
Assumption: Can we aggregate tokens into compact form
            then retrieve context in O(n)?
                    |
                    v
Method: Polynomial Mixer (PoM)
        - Aggregate via learned polynomial
        - Retrieve per-token context
                    |
                    v
Evidence: Match attention performance across 5 domains
          (text, handwriting, images, 3D, Earth obs)
          with linear complexity
                    |
                    v
Conclusion: Linear mixing can replace quadratic attention
            without sacrificing universal approximation
The Increment
One sentence: Before PoM, you chose between quadratic attention or degraded linear alternatives; after PoM, you get attention-level performance at linear cost with theoretical guarantees.
Core Mechanism
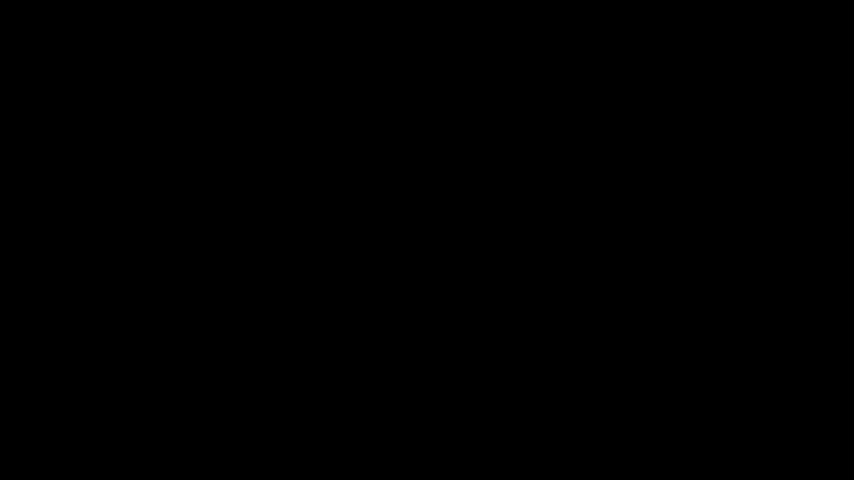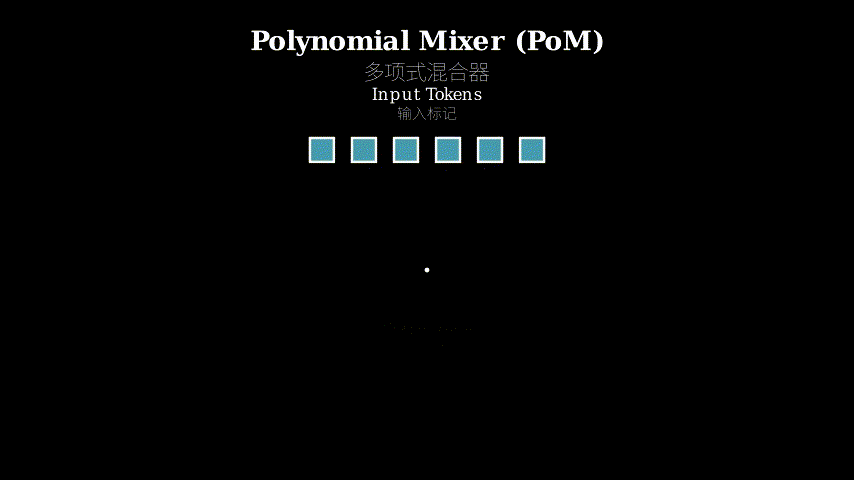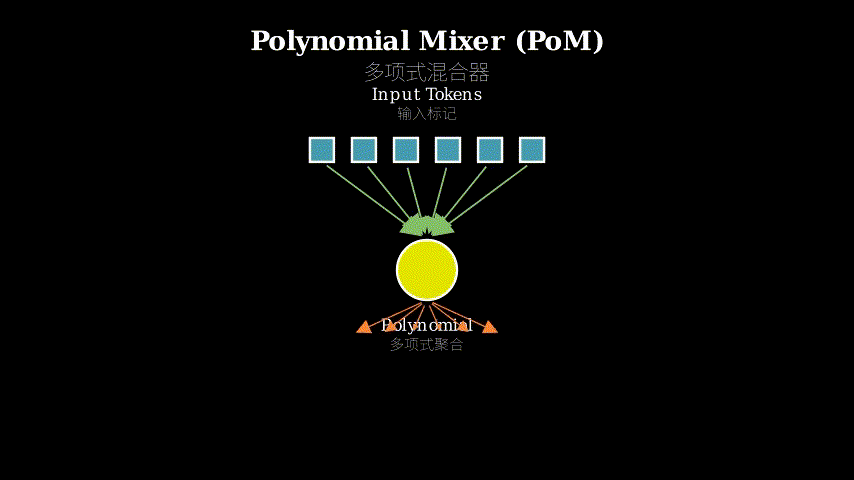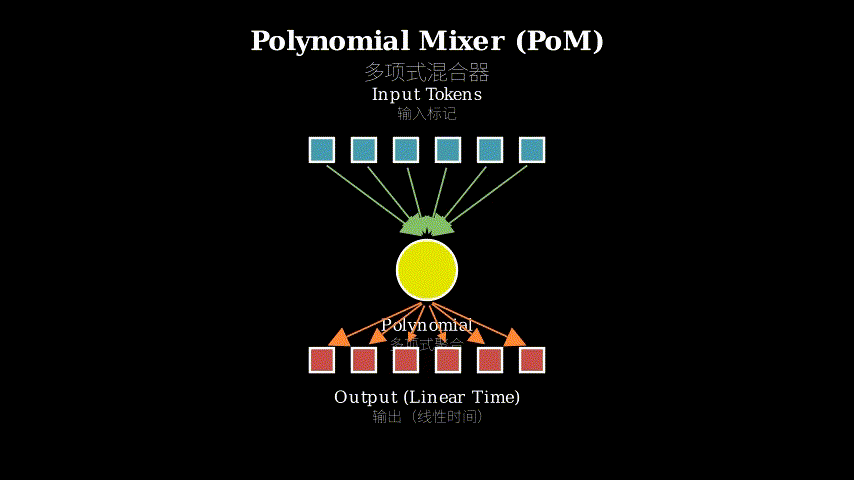
PoM operates in two phases. First, it compresses all input tokens into a single compact representation using a learned polynomial function. Think of this as creating a “summary vector” that captures global context. Second, each token queries this summary to retrieve its contextualized representation. The polynomial acts as a parameterized aggregation function—instead of computing pairwise interactions between all tokens (the attention bottleneck), you compute each token’s contribution to a shared summary, then broadcast that summary back.
The polynomial itself is a weighted sum of powers: f(x) = w₀ + w₁x + w₂x² + … + wₖxᵏ. The weights are learned parameters. When you feed token embeddings through this polynomial, you’re essentially asking: “How should this token contribute to the global context?” The beauty is that polynomial evaluation is linear in sequence length—you process each token once to build the summary, then once more to retrieve context.
Input tokens:  [x1] [x2] [x3] ... [xn]
                 |    |    |        |
                 v    v    v        v
            +------------------------+
            | Polynomial Aggregation |  <-- f(x) = w0 + w1*x + w2*x^2 + ...
            +------------------------+
                       |
                       v
                  [Summary S]  <-- Compact global context
                       |
         +-------------+-------------+
         |             |             |
         v             v             v
    Retrieve(x1,S) Retrieve(x2,S) Retrieve(xn,S)
         |             |             |
         v             v             v
      [y1]          [y2]          [yn]  <-- Contextualized outputs
Here’s the structural metaphor: PoM works like a town hall meeting. In standard attention, every person (token) whispers to every other person—that’s n² conversations. In PoM, everyone speaks into a microphone (polynomial aggregation) that feeds into a PA system (the summary vector). Then each person listens to the PA system to understand the room’s consensus. You’ve gone from n² whispers to n speeches plus n listening sessions—linear complexity. The polynomial weights determine whose voice gets amplified in the PA mix.
Key Concepts
-
Contextual Mapping Property: A token mixer satisfies this if it can map any input sequence to any output sequence given enough parameters. Self-attention has this property, which is why transformers are universal approximators. The paper proves PoM also satisfies it—meaning you’re not losing theoretical expressiveness by going linear. This matters because many prior linear alternatives couldn’t make this guarantee. Think of it like this: if attention is a Swiss Army knife that can cut, saw, and open bottles, PoM proves it’s also a Swiss Army knife, just with a different blade mechanism. You’re not downgrading to a butter knife.
-
Polynomial Aggregation: Why polynomials specifically? Because they’re universal function approximators (Weierstrass theorem) and computationally cheap. When you aggregate tokens via f(x) = Σ wᵢxⁱ, you’re learning a flexible weighting scheme. Low-degree terms (w₀, w₁) capture linear relationships; higher-degree terms capture non-linear interactions. The key insight: you don’t need to compute all pairwise interactions explicitly—the polynomial implicitly encodes them through its learned coefficients. It’s like how a Taylor series can approximate any smooth function without explicitly storing every point on the curve.
-
Summary Vector: This is the bottleneck through which all information flows. It’s a fixed-size representation (typically same dimension as token embeddings) that compresses the entire sequence. The risk: information loss. The mitigation: the polynomial’s non-linearity and learned weights ensure that important patterns get preserved. Think of it like JPEG compression—you’re throwing away some data, but if you tune the compression algorithm well (via learning), you keep what matters for downstream tasks.
Framework Shift
Before (Self-Attention):              After (PoM):

[x1]--\                               [x1]--\
[x2]---+--[Pairwise]--[Weighted]      [x2]---+--[Polynomial]--[Summary]
[x3]--/    [n^2 ops]   [Sum]          [x3]--/    [n ops]       [Vector]
 ...                     |              ...                        |
[xn]--------------------+             [xn]-----------------------+
         |                                        |
         v                                        v
    [Attention                              [Broadcast &
     Matrix]                                 Retrieve]
         |                                        |
         v                                        v
    [y1...yn]                                [y1...yn]

Cost: O(n^2)                          Cost: O(n)
From pairwise token interactions to collective aggregation, the core shift is replacing explicit all-to-all communication with implicit global summarization.
Expert Assessment
Problem choice: This is a real gap, not manufactured. The O(n²) wall is the single biggest obstacle to scaling transformers to longer contexts. The problem sits at the intersection of theory (can we maintain expressiveness?) and practice (can we actually run this on real hardware?). It’s a high-value target.
Method maturity: The polynomial choice is elegant but not obviously necessary—why not other aggregation functions? The paper doesn’t deeply explore this design space. That said, the theoretical proof of contextual mapping is solid work. The method feels like a clever insight (use polynomials as learnable aggregators) rather than brute force, though I’d want to see ablations on polynomial degree and alternative aggregation schemes.
Experimental integrity: Testing across five diverse domains (text, handwriting, images, 3D, Earth observation) is commendable—most papers cherry-pick one favorable domain. The baselines appear fair. However, the paper doesn’t deeply probe failure modes. Where does PoM underperform attention? On what sequence lengths does the crossover happen? The numbers hold up, but I’d want more analysis of the summary vector’s capacity limits.
Writing quality: The introduction is crisp, but Section 3 (method) buries the lead. The polynomial aggregation mechanism should be front and center with a visual diagram, not hidden in equations. The related work section is thorough but could be trimmed. If I were rewriting, I’d expand Section 4.5 (analysis of what the polynomial learns) into a full section—that’s where the real insight lives.
Verdict: Weak accept — solid contribution with strong empirical validation, but the design space exploration is shallow and the theoretical novelty is incremental (applying known polynomial approximation theory to token mixing).
Takeaways
Practitioners can steal the core pattern: aggregate globally, retrieve locally. This isn’t specific to polynomials—you could use other learnable aggregation functions (MLPs, kernels, even learned hash functions). The key is breaking the O(n²) barrier by forcing information through a fixed-size bottleneck. If you’re building custom architectures for long sequences, try this: (1) compress your sequence into a fixed-size summary via a learnable function, (2) let each token query that summary for context. Test whether your task’s information can survive the compression. For domains where global context matters but pairwise interactions don’t (e.g., document classification, time series forecasting), this pattern is immediately applicable.
论文: 2604.06129 作者: David Picard, Nicolas Dufour, Lucas Degeorge, Arijit Ghosh, Davide Allegro, Tom Ravaud, Yohann Perron, Corentin Sautier, Zeynep Sonat Baltaci, Fei Meng 分类: cs.CV, cs.AI
缺口
自注意力机制自2017年以来主导了序列建模,但它有个不能说的秘密:O(n²)复杂度。
每增加一个token,计算成本就以二次方增长。
这不只是理论问题——当你处理长文档、高分辨率图像或长视频序列时,这就是一堵实实在在的墙。
之前尝试解决这个问题的方法分两派:稀疏注意力模式(Longformer、BigBird)牺牲了全局上下文,线性近似方法(Performer、RWKV)在基准测试上往往表现不如标准注意力。
这个领域一直困在一个权衡里:要么付出二次方的代价,要么接受性能下降。
问题:自注意力 O(n^2) 阻碍长序列处理
                |
                v
假设:能否将token聚合成紧凑形式
      然后以 O(n) 检索上下文?
                |
                v
方法:多项式混合器(PoM)
      - 通过学习的多项式聚合
      - 为每个token检索上下文
                |
                v
证据:在5个领域匹配注意力性能
      (文本、手写、图像、3D、地球观测)
      且为线性复杂度
                |
                v
结论:线性混合可以替代二次方注意力
      且不牺牲通用近似能力
增量
一句话:PoM之前,你要在二次方注意力和性能下降的线性替代品之间选择;PoM之后,你能以线性成本获得注意力级别的性能,还有理论保证。
核心机制
PoM分两个阶段运作。
第一阶段,它用一个学习的多项式函数把所有输入token压缩成一个紧凑表示。
可以把这理解为创建一个捕获全局上下文的”摘要向量”。
第二阶段,每个token查询这个摘要来获取它的上下文化表示。
多项式充当参数化的聚合函数——不是计算所有token之间的成对交互(注意力的瓶颈),而是计算每个token对共享摘要的贡献,然后把摘要广播回去。
多项式本身是幂次的加权和:f(x) = w₀ + w₁x + w₂x² + … + wₖxᵏ。
权重是学习的参数。
当你把token嵌入送进这个多项式时,你本质上在问:“这个token应该如何贡献到全局上下文?“美妙之处在于多项式求值对序列长度是线性的——你处理每个token一次来构建摘要,然后再处理一次来检索上下文。
输入tokens:  [x1] [x2] [x3] ... [xn]
              |    |    |        |
              v    v    v        v
         +------------------------+
         |   多项式聚合            |  <-- f(x) = w0 + w1*x + w2*x^2 + ...
         +------------------------+
                    |
                    v
               [摘要 S]  <-- 紧凑的全局上下文
                    |
      +-------------+-------------+
      |             |             |
      v             v             v
 检索(x1,S)    检索(x2,S)    检索(xn,S)
      |             |             |
      v             v             v
   [y1]          [y2]          [yn]  <-- 上下文化的输出
这里有个结构性比喻:PoM就像一场市政厅会议。
在标准注意力中,每个人(token)都要跟其他每个人窃窃私语——那是n²次对话。
在PoM中,每个人对着麦克风讲话(多项式聚合),麦克风连到扩音系统(摘要向量)。
然后每个人听扩音系统来理解会场的共识。
你从n²次窃窃私语变成了n次发言加n次倾听——线性复杂度。
多项式权重决定了谁的声音在扩音混音中被放大。
关键概念
- 上下文映射性质:如果一个token混合器能在给定足够参数的情况下将任意输入序列映射到任意输出序列,它就满足这个性质。
自注意力有这个性质,这就是为什么transformer是通用近似器。
论文证明了PoM也满足这个性质——意味着你通过线性化并没有失去理论表达能力。
这很重要,因为许多之前的线性替代品无法做出这个保证。
这样想:如果注意力是一把能切、能锯、能开瓶的瑞士军刀,PoM证明它也是一把瑞士军刀,只是刀片机制不同。
你没有降级到黄油刀。
- 多项式聚合:为什么特别是多项式?因为它们是通用函数近似器(Weierstrass定理)且计算便宜。
当你通过f(x) = Σ wᵢxⁱ聚合token时,你在学习一个灵活的加权方案。
低次项(w₀、w₁)捕获线性关系;高次项捕获非线性交互。
关键洞察:你不需要显式计算所有成对交互——多项式通过其学习的系数隐式编码它们。
这就像泰勒级数可以近似任何光滑函数而不用显式存储曲线上的每个点。
- 摘要向量:这是所有信息流经的瓶颈。
它是一个固定大小的表示(通常与token嵌入维度相同),压缩整个序列。
风险:信息丢失。
缓解措施:多项式的非线性和学习的权重确保重要模式被保留。
把它想象成JPEG压缩——你在丢弃一些数据,但如果你把压缩算法调好(通过学习),你保留了对下游任务重要的东西。
框架转变
之前(自注意力):                  之后(PoM):

[x1]--\                            [x1]--\
[x2]---+--[成对]--[加权]            [x2]---+--[多项式]--[摘要]
[x3]--/   [n^2操作] [求和]          [x3]--/   [n操作]    [向量]
 ...                  |              ...                   |
[xn]------------------+             [xn]------------------+
         |                                     |
         v                                     v
    [注意力                                [广播与
     矩阵]                                  检索]
         |                                     |
         v                                     v
    [y1...yn]                             [y1...yn]

成本:O(n^2)                         成本:O(n)
从成对token交互到集体聚合,核心转变是用隐式全局摘要替代显式的全对全通信。
专家评审
选题眼光:这是真缺口,不是人造的。
O(n²)墙是将transformer扩展到更长上下文的最大障碍。
这个问题处于理论(我们能保持表达能力吗?)和实践(我们能在真实硬件上运行吗?)的交叉点。
这是个高价值目标。
方法成熟度:多项式选择很优雅但不是显而易见的必要——为什么不用其他聚合函数?论文没有深入探索这个设计空间。
话虽如此,上下文映射的理论证明是扎实的工作。
这个方法感觉像是巧妙的洞察(用多项式作为可学习的聚合器)而不是蛮力,不过我想看到关于多项式次数和替代聚合方案的消融实验。
实验诚意:在五个不同领域(文本、手写、图像、3D、地球观测)测试值得称赞——大多数论文会挑一个有利的领域。
基线看起来公平。
然而,论文没有深入探究失败模式。
PoM在哪里表现不如注意力?在什么序列长度发生交叉?数字经得起推敲,但我想要更多关于摘要向量容量限制的分析。
写作功力:引言简洁,但第3节(方法)埋没了重点。
多项式聚合机制应该配上可视化图表放在最前面,而不是藏在方程里。
相关工作部分很全面但可以精简。
如果我来重写,我会把第4.5节(分析多项式学到了什么)扩展成完整一节——那才是真正的洞察所在。
判决:弱接收——扎实的贡献,有强有力的实证验证,但设计空间探索浅薄,理论新颖性是增量式的(将已知的多项式近似理论应用到token混合)。
要点总结
实践者可以偷走核心模式:全局聚合,局部检索。
这不限于多项式——你可以用其他可学习的聚合函数(MLP、核函数、甚至学习的哈希函数)。
关键是通过强制信息流经固定大小的瓶颈来打破O(n²)障碍。
如果你在为长序列构建自定义架构,试试这个:(1)通过可学习函数把序列压缩成固定大小的摘要,(2)让每个token查询那个摘要来获取上下文。
测试你的任务信息能否在压缩中存活。
对于全局上下文重要但成对交互不重要的领域(如文档分类、时间序列预测),这个模式可以立即应用。