Paper: 2605.20147 Authors: Haojun Chen, Haoyang He, Chengming Xu, Qingdong He, Junwei Zhu, Yabiao Wang, Zhucun Xue, Xianfang Zeng, Zhennan Chen, Xiaobin Hu Categories: cs.CV
The Gap
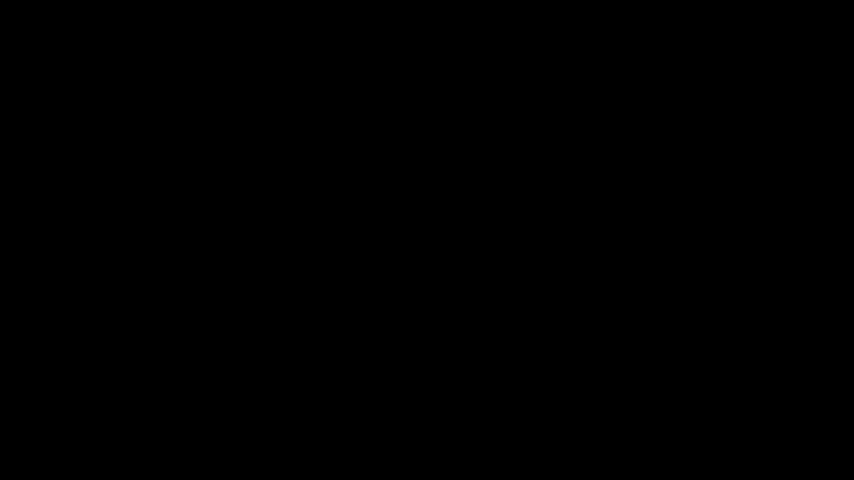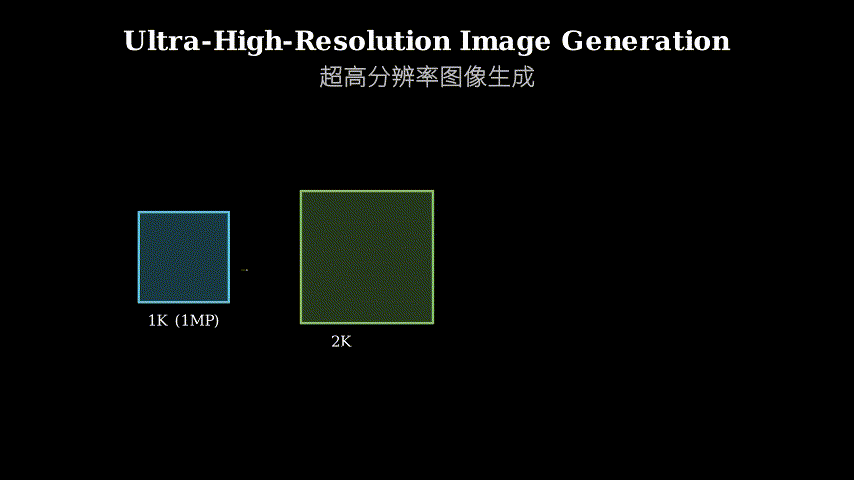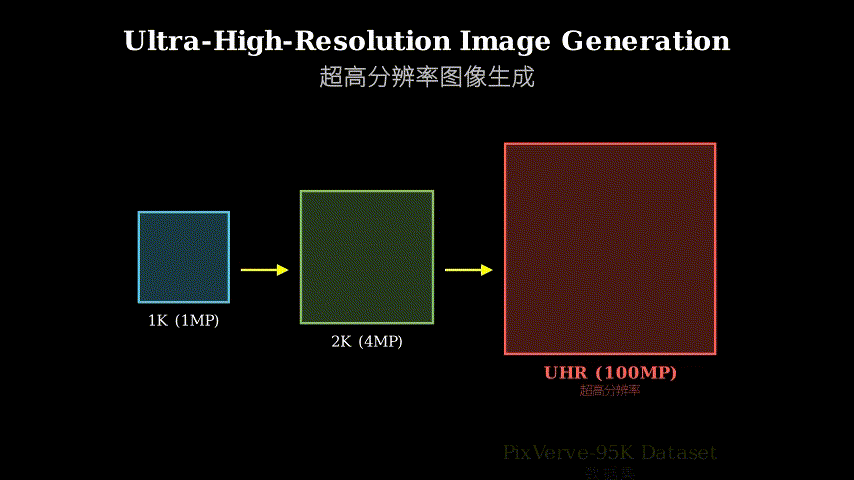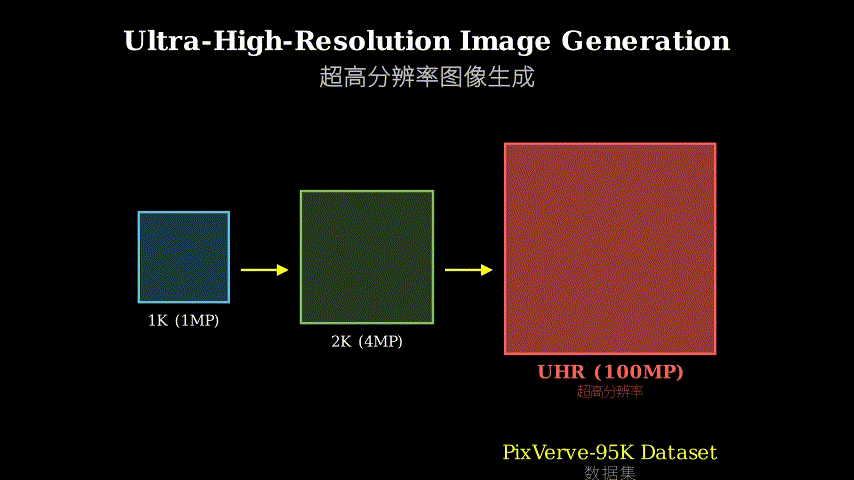
Text-to-image models like DALL-E, Stable Diffusion, and Midjourney have plateaued around 1K-2K resolution. When you need billboard-quality images (10K+ pixels) or print-ready graphics, current approaches either upscale low-res outputs (introducing artifacts) or use cascaded super-resolution pipelines (slow, error-prone). The core problem: training data. Existing datasets (LAION, COYO) contain mostly web images under 2K resolution. High-resolution images are rare, expensive to curate, and computationally prohibitive to train on at scale.
This paper attacks the data bottleneck head-on: build a 95K-image dataset where every sample exceeds 100 megapixels, then train foundation models natively at that resolution.
Problem: T2I models stuck at 2K
   |
   v
Root cause: No large-scale UHR training data
   |
   +---> Existing datasets: web images < 2K
   |
   v
Solution: PixVerve-95K dataset (95K images, 100MP+ each)
   |
   v
Method: Extend foundation models with 3 training schemes
   |
   v
Evidence: PixVerve-Bench evaluation (quality + alignment)
   |
   v
Result: Native 100MP generation without cascades
The Increment
One sentence: Before this paper, generating ultra-high-resolution images required multi-stage upscaling pipelines; after, foundation models can synthesize 100MP images end-to-end in a single pass.
Core Mechanism
The method has three layers: data curation, model adaptation, and evaluation.
Data curation starts with raw high-res images from diverse sources (stock photos, professional photography, digital art). Each image passes through a quality filter (sharpness, aesthetic score, artifact detection), then gets annotated along seven dimensions: dense captions (what’s in the image), style tags (photorealistic, impressionist), composition metadata (rule of thirds, symmetry), color palette, object counts, scene complexity, and technical attributes (lighting, depth of field). This multi-dimensional annotation gives models richer supervision than standard caption-only datasets.
Model adaptation takes existing T2I architectures (Stable Diffusion, FLUX) and extends them to 100MP through three training schemes. Progressive resolution training starts at 2K, gradually increases to 10K over multiple stages, letting the model adapt without catastrophic forgetting. Multi-scale training samples patches at different resolutions within each image, teaching the model to handle both global composition and fine details. Attention mechanism modifications replace full self-attention (quadratic cost) with windowed or sparse attention patterns that scale to ultra-high resolutions.
Input text --> Encoder --> Latent code (low-res)
                              |
                              v
                    Diffusion UNet (modified attention)
                              |
                    +----+----+----+
                    |    |    |    |
                  2K   4K   8K  10K  (progressive stages)
                    |    |    |    |
                    +----+----+----+
                              |
                              v
                    VAE Decoder --> 100MP image
Think of this like training a painter to work on murals instead of canvases. You don’t just hand them a 50-foot wall and say “paint.” First, you give them progressively larger surfaces (progressive resolution = small wall, medium wall, large wall). Second, you teach them to think at multiple scales simultaneously: step back to see the whole composition, step close to refine brushstrokes (multi-scale training = zooming in/out). Third, you change their tools: a tiny brush won’t cover a mural efficiently, so you give them rollers for broad strokes and detail brushes for accents (attention modifications = efficient tools for large canvas). The seven-dimensional annotations are like giving the painter reference photos from multiple angles, color swatches, and composition sketches—richer guidance than a single reference image.
Key Concepts
-
Native vs. Cascaded Generation: Native generation means the model directly outputs the target resolution in one forward pass. Cascaded generation produces a low-res image, then runs separate super-resolution models to upscale it. The difference matters because cascades accumulate errors at each stage (a blurry face at 512px becomes a blurry face at 4K, just sharper), while native generation can plan global structure and local details jointly. Imagine writing an essay: cascaded is like writing a one-paragraph summary, then expanding each sentence into a paragraph later (you lose coherence). Native is like writing the full essay from the start, knowing where each section fits.
-
Ultra-High-Resolution (UHR): The paper defines UHR as 100 megapixels or more (roughly 10,000 x 10,000 pixels). For context, a 4K TV is 8 megapixels, a high-end DSLR photo is 20-50 megapixels, and a billboard-sized print needs 100+ megapixels to avoid visible pixelation. The computational challenge: memory and compute scale quadratically with resolution. A 10K image has 100x more pixels than a 1K image, so naive training would need 100x more GPU memory.
-
Multi-Dimensional Annotation: Instead of just “a dog in a park,” annotations include: dense caption (“golden retriever running through autumn leaves”), style (“photorealistic, shallow depth of field”), composition (“rule of thirds, subject off-center”), color palette (“warm tones, orange and brown dominant”), object count (“1 dog, 15+ trees”), scene complexity (“medium—single subject, textured background”), technical attributes (“natural lighting, f/2.8 aperture simulation”). This gives the model multiple supervision signals. If the caption says “golden retriever” but the style tag says “oil painting,” the model learns to disentangle content from rendering style.
Framework Shift
Before (cascaded approach):          After (PixVerve):

Text --> [Base Model]                Text --> [Foundation Model]
            |                                      |
          512px                            (progressive training)
            |                                      |
            v                                      v
      [SR Model 1]                         Native 100MP output
            |                                      ^
          2048px                                   |
            |                              (single forward pass)
            v
      [SR Model 2]
            |
          8192px
            |
            v
      [SR Model 3]
            |
         100MP

(3-4 models, error accumulation)    (1 model, end-to-end)
From multi-stage pipelines to single-pass synthesis, the core shift is eliminating the resolution ladder by training directly at the target scale.
Expert Assessment
Problem choice: Real gap. The demand for UHR content is genuine (advertising, medical imaging, satellite imagery, digital art), and current solutions are hacky. However, the paper doesn’t deeply justify *why native generation is necessary—cascaded approaches with better super-resolution models might close the gap at lower cost. The problem is well-motivated but not uniquely solvable by this approach.
Method maturity: Mostly engineering, not algorithmic novelty. Progressive training and multi-scale sampling are standard tricks from the super-resolution literature. The attention modifications (windowed/sparse) are borrowed from vision transformers. The real contribution is the dataset and the empirical demonstration that existing architectures *can scale to 100MP with enough data and compute. This is valuable but not intellectually surprising.
Experimental integrity: The benchmark (PixVerve-Bench) is a strength—using multimodal LLMs for semantic alignment evaluation is more robust than CLIP scores alone. However, the paper lacks ablations on training scheme components (what if you skip progressive training? how much does multi-scale sampling matter?). Baselines are limited: they compare against cascaded pipelines but not against other native UHR approaches (do any exist?). The 95K dataset size is small by modern standards (LAION has billions of images)—it’s unclear if quality compensates for quantity.
Writing quality: The abstract oversells (“pioneering step”—really?). The method section is dense with implementation details but light on design rationale. Why seven annotation dimensions specifically? How were the quality thresholds chosen? The evaluation section is thorough, but the paper would benefit from a failure analysis: what kinds of prompts still produce artifacts at 100MP? The related work section name-drops datasets but doesn’t critically compare their curation pipelines.
Verdict: Weak accept — Solid engineering contribution with a useful dataset, but limited algorithmic novelty and incomplete experimental analysis. The work advances the state of practice more than the state of understanding.
Takeaways
For practitioners: The seven-dimensional annotation schema is worth stealing. If you’re building any vision dataset, adding style/composition/technical metadata alongside captions gives models richer supervision at minimal extra cost. Use off-the-shelf classifiers for style, CLIP for composition analysis, and rule-based heuristics for technical attributes.
For researchers: Progressive resolution training is underused outside super-resolution. If you’re scaling any generative model to higher dimensions (longer videos, larger 3D scenes), consider curriculum learning over the target dimension rather than jumping straight to the final scale.
For infrastructure teams: The paper’s attention modifications (windowed/sparse patterns) are necessary but not sufficient for 100MP generation. Memory-efficient training at this scale requires gradient checkpointing, mixed precision, and probably model parallelism. Budget 8x A100 GPUs minimum for replication.
Honest take: The dataset is the paper’s lasting contribution. The training schemes are competent but not groundbreaking. If you need UHR generation today, this gives you a starting point. If you’re researching generative models, the ideas here won’t change your roadmap.
论文: 2605.20147 作者: Haojun Chen, Haoyang He, Chengming Xu, Qingdong He, Junwei Zhu, Yabiao Wang, Zhucun Xue, Xianfang Zeng, Zhennan Chen, Xiaobin Hu 分类: cs.CV
缺口
DALL-E、Stable Diffusion、Midjourney 这些文生图模型已经在 1K-2K 分辨率上停滞了。
当你需要广告牌级别的图像(10K+ 像素)或印刷级图形时,现有方法要么放大低分辨率输出(引入伪影),要么使用级联超分辨率管线(慢且容易出错)。
核心问题是训练数据。
现有数据集(LAION、COYO)主要包含 2K 以下的网络图像。
高分辨率图像稀少、策展成本高,且大规模训练在计算上难以承受。
本文直击数据瓶颈:构建一个 95K 图像的数据集,每个样本都超过 1 亿像素,然后在该分辨率上原生训练基础模型。
问题:文生图模型卡在 2K
   |
   v
根本原因:缺乏大规模超高分辨率训练数据
   |
   +---> 现有数据集:网络图像 < 2K
   |
   v
解决方案:PixVerve-95K 数据集(95K 图像,每张 100MP+)
   |
   v
方法:用 3 种训练方案扩展基础模型
   |
   v
证据:PixVerve-Bench 评估(质量 + 对齐)
   |
   v
结果:无需级联的原生 100MP 生成
增量
一句话: 这篇论文之前,生成超高分辨率图像需要多阶段放大管线;之后,基础模型可以一次性端到端合成 100MP 图像。
核心机制
方法分三层:数据策展、模型适配、评估。
数据策展从多样化来源(库存照片、专业摄影、数字艺术)的原始高分辨率图像开始。
每张图像通过质量过滤器(清晰度、美学评分、伪影检测),然后沿七个维度标注:密集描述(图像内容)、风格标签(写实、印象派)、构图元数据(三分法、对称性)、色板、物体计数、场景复杂度、技术属性(光照、景深)。
这种多维标注比标准的纯描述数据集提供更丰富的监督。
模型适配采用现有文生图架构(Stable Diffusion、FLUX),通过三种训练方案将其扩展到 100MP。
渐进分辨率训练从 2K 开始,在多个阶段逐步增加到 10K,让模型适应而不会灾难性遗忘。
多尺度训练在每张图像内采样不同分辨率的块,教会模型同时处理全局构图和精细细节。
注意力机制修改将全自注意力(二次成本)替换为窗口化或稀疏注意力模式,以扩展到超高分辨率。
输入文本 --> 编码器 --> 潜码(低分辨率)
                              |
                              v
                    扩散 UNet(修改后的注意力)
                              |
                    +----+----+----+
                    |    |    |    |
                  2K   4K   8K  10K  (渐进阶段)
                    |    |    |    |
                    +----+----+----+
                              |
                              v
                    VAE 解码器 --> 100MP 图像
把这想象成训练画家在壁画上作画而不是画布上。
你不会直接给他们一面 15 米的墙说”画吧”。
首先,你给他们逐渐增大的表面(渐进分辨率 = 小墙、中墙、大墙)。
其次,你教他们同时在多个尺度上思考:后退看整体构图,靠近细化笔触(多尺度训练 = 放大/缩小)。
第三,你改变他们的工具:小刷子无法高效覆盖壁画,所以你给他们滚筒刷大面积、细刷画细节(注意力修改 = 大画布的高效工具)。
七维标注就像给画家提供多角度参考照片、色卡和构图草图——比单张参考图更丰富的指导。
关键概念
- 原生 vs. 级联生成: 原生生成意味着模型在一次前向传播中直接输出目标分辨率。
级联生成先产生低分辨率图像,然后运行单独的超分辨率模型来放大。
区别很重要,因为级联在每个阶段累积误差(512px 的模糊脸变成 4K 的模糊脸,只是更清晰),而原生生成可以联合规划全局结构和局部细节。
想象写论文:级联就像先写一段摘要,然后把每句话扩展成一段(你会失去连贯性)。
原生就像从一开始写完整论文,知道每个部分如何衔接。
- 超高分辨率(UHR): 论文将 UHR 定义为 1 亿像素或更多(大约 10,000 x 10,000 像素)。
作为参考,4K 电视是 800 万像素,高端单反照片是 2000-5000 万像素,广告牌尺寸的印刷品需要 100+ 百万像素才能避免可见像素化。
计算挑战:内存和计算随分辨率二次方增长。
10K 图像的像素数是 1K 图像的 100 倍,所以朴素训练需要 100 倍的 GPU 内存。
- 多维标注: 不只是”公园里的狗”,标注包括:密集描述(“金毛猎犬在秋叶中奔跑”)、风格(“写实,浅景深”)、构图(“三分法,主体偏离中心”)、色板(“暖色调,橙色和棕色主导”)、物体计数(“1 只狗,15+ 棵树”)、场景复杂度(“中等——单一主体,纹理背景”)、技术属性(“自然光,f/2.8 光圈模拟”)。
这给模型提供多个监督信号。
如果描述说”金毛猎犬”但风格标签说”油画”,模型学会解耦内容和渲染风格。
框架转变
之前(级联方法):                之后(PixVerve):

文本 --> [基础模型]                文本 --> [基础模型]
            |                                      |
          512px                            (渐进训练)
            |                                      |
            v                                      v
      [超分模型 1]                         原生 100MP 输出
            |                                      ^
          2048px                                   |
            |                              (单次前向传播)
            v
      [超分模型 2]
            |
          8192px
            |
            v
      [超分模型 3]
            |
         100MP

(3-4 个模型,误差累积)            (1 个模型,端到端)
从多阶段管线到单次合成,核心转变是通过直接在目标尺度上训练来消除分辨率阶梯。
专家评审
选题眼光: 真实缺口。
对 UHR 内容的需求是真实的(广告、医学成像、卫星图像、数字艺术),现有解决方案都是权宜之计。
然而,论文没有深入论证为什么原生生成是必要的——更好的超分辨率模型的级联方法可能以更低成本缩小差距。
问题动机充分,但不是这种方法独有可解的。
方法成熟度: 主要是工程,不是算法创新。
渐进训练和多尺度采样是超分辨率文献中的标准技巧。
注意力修改(窗口化/稀疏)借鉴自视觉 Transformer。
真正的贡献是数据集和实证证明现有架构可以用足够的数据和计算扩展到 100MP。
这很有价值但在智识上不令人惊讶。
实验诚意: 基准测试(PixVerve-Bench)是优势——使用多模态 LLM 进行语义对齐评估比单纯 CLIP 分数更稳健。
然而,论文缺乏训练方案组件的消融实验(如果跳过渐进训练会怎样?多尺度采样有多重要?)。
基线有限:他们与级联管线比较,但没有与其他原生 UHR 方法比较(有其他方法存在吗?)。
95K 数据集规模按现代标准很小(LAION 有数十亿图像)——不清楚质量是否补偿了数量。
写作功力: 摘要过度推销(“开创性步骤”——真的吗?)。
方法部分充满实现细节但缺乏设计理由。
为什么恰好是七个标注维度?质量阈值如何选择?评估部分很彻底,但论文会受益于失败分析:什么样的提示在 100MP 下仍然产生伪影?相关工作部分罗列数据集但没有批判性比较它们的策展管线。
判决: 弱接收 — 扎实的工程贡献和有用的数据集,但算法创新有限且实验分析不完整。
这项工作推进了实践状态多于理解状态。
要点总结
对实践者: 七维标注模式值得借鉴。
如果你在构建任何视觉数据集,在描述之外添加风格/构图/技术元数据以最小额外成本给模型提供更丰富的监督。
使用现成的分类器做风格,CLIP 做构图分析,基于规则的启发式做技术属性。
对研究者: 渐进分辨率训练在超分辨率之外使用不足。
如果你在将任何生成模型扩展到更高维度(更长视频、更大 3D 场景),考虑在目标维度上进行课程学习,而不是直接跳到最终尺度。
对基础设施团队: 论文的注意力修改(窗口化/稀疏模式)是必要但不充分的 100MP 生成条件。
这种规模的内存高效训练需要梯度检查点、混合精度,可能还需要模型并行。
预算至少 8 块 A100 GPU 用于复现。
坦率说: 数据集是论文的持久贡献。
训练方案称职但不开创性。
如果你今天需要 UHR 生成,这给你一个起点。
如果你在研究生成模型,这里的想法不会改变你的路线图。