Paper: 2606.11169
Authors: Megan Frisella, Shubham Tiwari, Andy Ruan, Yi Pan, Parker Gustafson, Mat Jacob, Gilbert Bernstein, Stephanie Wang
Categories: cs.DC, cs.AI
The Gap
Current large‑scale training systems (e.g., DeepSpeed ZeRO, Megatron‑LM) rely on human experts to manually design a high‑level parallelism strategy and then implement the corresponding low‑level execution code inside a fixed runtime. This makes it painful to adopt emerging strategies like DeepSeek‑V3’s DualPipe without rewriting significant portions of the runtime. Meanwhile, general‑purpose frameworks offer more flexibility but still bake a fixed set of common strategies (data, pipeline, expert parallelism) into their implementations – integrating a new strategy means hacking the framework’s core. The field needs a way to express arbitrary training strategies declaratively and have the system automatically generate efficient per‑device execution plans, without sacrificing performance on standard strategies.
+----------------------------------------------------+
| Problem: Manual strategy design & impl tied to     |
| runtime -> hard to adapt to new strategies         |
+----------------------------------------------------+
                          |
                          v
+----------------------------------------------------+
| Assumption: Decouple strategy from runtime via     |
| a unified, strategy‑agnostic intermediate rep.     |
+----------------------------------------------------+
                          |
                          v
+----------------------------------------------------+
| Method: User declares strategy with annotations +  |
| scheduling directives -> Piper IR (global train    |
| DAG) -> compile per‑device execution plans         |
+----------------------------------------------------+
                          |
                          v
+----------------------------------------------------+
| Evidence: Performance parity on ZeRO; memory +     |
| throughput gains on DeepSeek‑V3 DualPipe           |
+----------------------------------------------------+
                          |
                          v
+----------------------------------------------------+
| Conclusion: Piper enables flexible strategy        |
| integration without performance regression,        |
| opening the door to automated strategy search.     |
+----------------------------------------------------+
The Increment
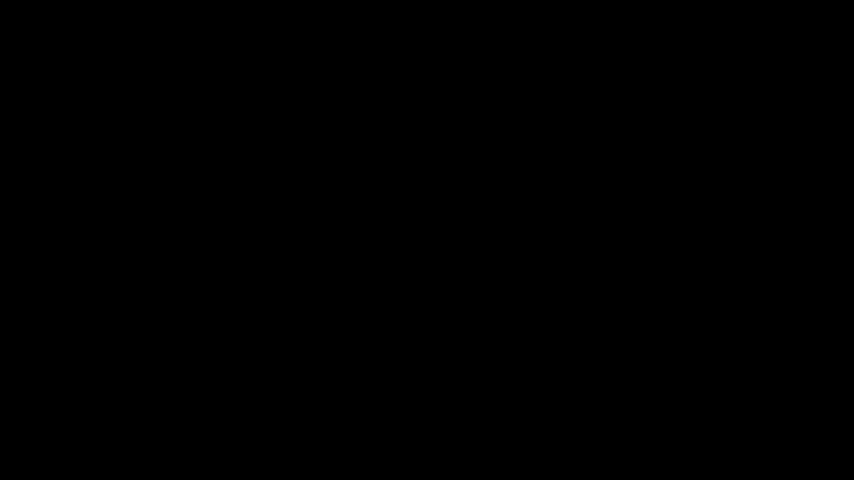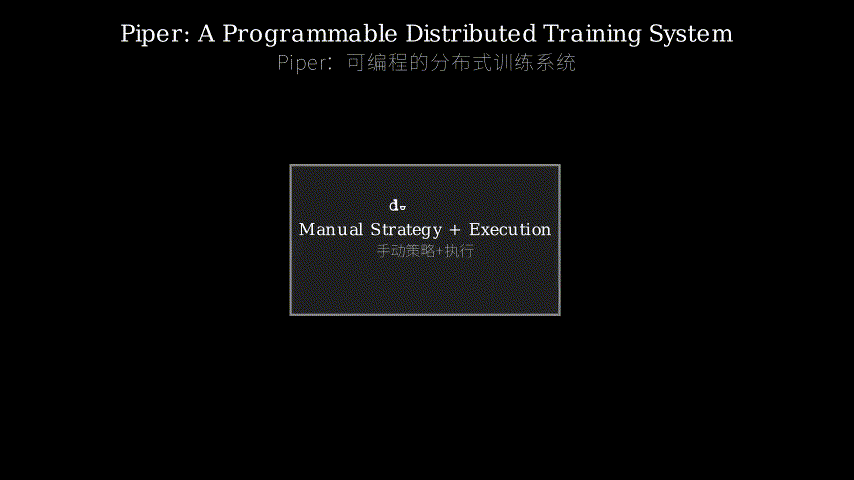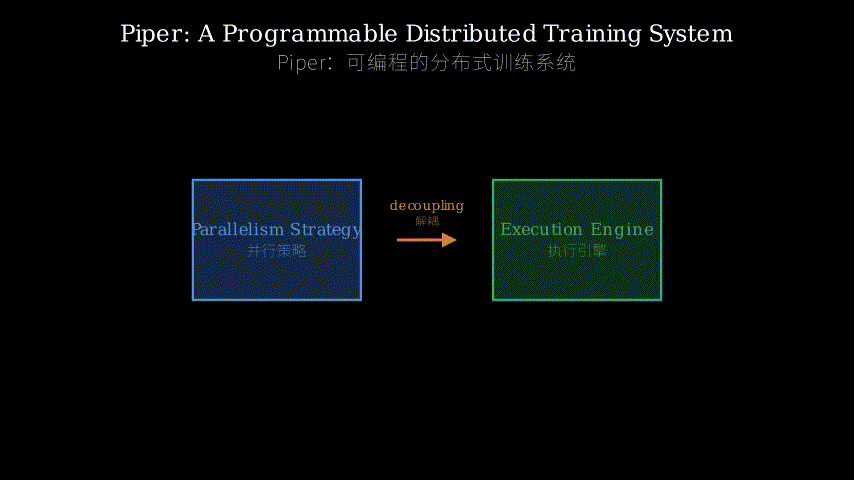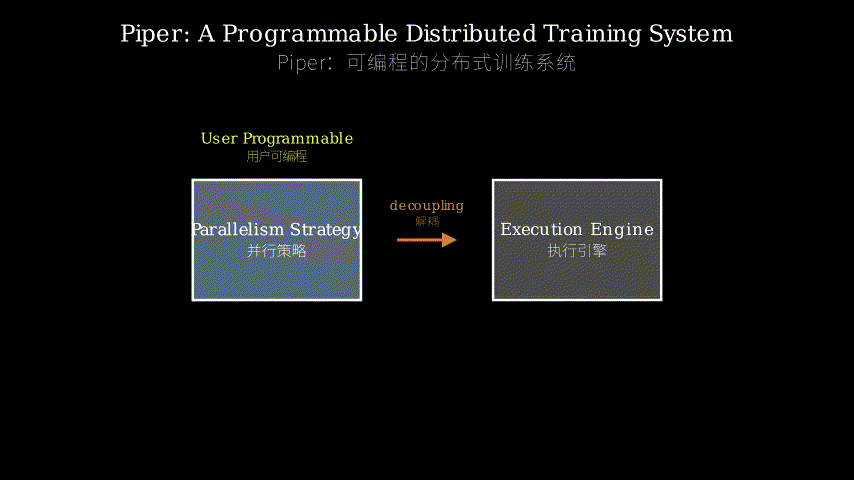
One sentence: Before Piper, integrating a novel parallel strategy meant either modifying a runtime or hand‑optimizing each hardware detail; after Piper, you declare the strategy once at a high level and the system compiles it down to efficient per‑device execution, keeping the runtime completely strategy‑agnostic.
Core Mechanism
Piper’s design has three layers: user interface, intermediate representation (IR), and runtime.
First, the user annotates their PyTorch model with a small set of constructs: parallelism annotations (e.g., “this tensor should be sharded across data‑parallel replicas” or “this module is a pipeline stage”) and scheduling directives (e.g., “overlap the backward pass of stage i with the forward pass of stage i+1”). These are Python‑embedded but declarative – they describe what the strategy should be, not how to execute it.
Second, Piper converts the annotated model into a single, unified global training DAG – its IR. Every operation (forward, backward, all‑reduce, send, recv, etc.) becomes a node, and dependencies become edges. The IR is strategy‑agnostic: whether the user wants data‑only parallelism or a complex DualPipe schedule, the same graph representation holds. Then Piper applies a sequence of IR transformations – loop fusion, communication‑computation overlap, device placement, etc. – driven by the scheduling directives. These transformations optimize the graph (e.g., reordering nodes to overlap a gradient all‑reduce with the next forward pass) before the final compilation step.
Third, the compiled per‑device execution plans are sent to a lightweight distributed runtime that simply executes the plan for each node: it reads a sequence of operations (compute kernel calls, network sends, barriers) and runs them in order. The runtime knows nothing about the strategy – it just follows the schedule the compiler produced.
          +-------------------+          +--------------------+
          | User Annotations  |          | Scheduling Direct. |
          | (e.g., shard dim) |          | (overlap, order)   |
          +--------+----------+          +---------+----------+
                   |                               |
                   v                               v
          +---------------------------------------------------+
          |         Piper IR (Global Training DAG)            |
          |  Nodes = compute/communication ops                |
          |  Edges = data dependencies                        |
          +------------------------+--------------------------+
                                   |
                                   v
          +-----------------------------------------------+
          | IR Transformations (fusion, overlap, placement)|
          +----------------------+------------------------+
                                 |
                                 v
          +----------------------------------------------+
          | Compile: per‑device execution plans (op seqs)|
          +----------------------+-----------------------+
                                 |
                                 v
          +----------------------------------------------+
          | Strategy‑Agnostic Runtime (just execute plan)|
          +----------------------------------------------+
Now a structural metaphor: think of Piper as a conductor and an orchestra plus a programmable score writer.
- User annotations + scheduling directives = the composer writing a piece of music, specifying which instruments play when (parallelism) and how sections overlap (scheduling).
- Piper IR = the full orchestral score – all notes, dynamics, and tempos for every instrument at every beat.
- IR transformations = the conductor’s interpretation, deciding when to bring certain sections earlier or later (overlap), whether to merge two woodwind parts (fusion), or how to seat the orchestra (device placement).
- Compilation = copying the conductor’s annotated score into individual parts for each musician (per‑device execution plan).
- Runtime = the musicians – they only read their own part and play exactly what’s written. They don’t know the overall structure; they just follow notes.
If you want a new orchestration style (a new parallelism strategy), you don’t retrain the musicians or rewrite the orchestral core – you just compose a new score and the conductor transforms it into individual parts. Piper does exactly this: new strategy -> new annotations -> new IR -> new execution plans – the runtime never changes.
Key Concepts
-
Global Training DAG (Piper IR): This is a directed acyclic graph that represents every operation in a training step across all devices. Imagine each device has its own local computation (forward, backward, optimizer step) plus communication operations (all‑reduce, send, recv). Normally these are scattered across separate files or runtimes. Piper IR unifies them into one graph, so the compiler can make cross‑device optimizations – e.g., overlapping an all‑reduce on one device with the forward pass on another. Without a unified DAG, these optimizations are ad‑hoc and strategy‑specific.
-
Scheduling Directives: These are lightweight annotations that hint to the compiler about when things should happen relative to each other. For example, in pipeline parallelism you might say “overlap the backward of stage 1 with the forward of stage 2”. The directive doesn’t specify the exact micro‑batch schedule – it just says “try to make these overlap”. The compiler then decides whether to use 1F1B, interleaved, or DualPipe style based on the directives and the available hardware. This is a powerful abstraction: you declare your intent, and the compiler figures out the logistics.
-
Compilation to Per‑Device Execution Plans: After IR transforms, Piper produces a sequence of operations for each device – essentially a “script” of kernel launches and network operations. This is similar to how a C++ compiler produces machine code; the runtime just executes this script. Because the runtime is strategy‑agnostic, Piper can output extremely fine‑grained schedules that mix compute and communication in ways that a fixed runtime couldn’t support without complex hand‑coding.
Framework Shift
Let’s draw a napkin sketch of the old way vs. Piper’s way:
Before (mainstream approach):
  Human designer
      |
      | (1) designs high‑level strategy
      | (2) implements low‑level execution by hand
      |
      v
  Monolithic Runtime (e.g., DeepSpeed ZeRO)
      | contains hardcoded logic for each strategy
      | cannot adapt to new strategies without code change
      |
      v
  Training runs, but integration of new strategy takes months

After (this paper):
  User (annotations + directives)
      |
      | declares strategy declaratively
      |
      v
  Piper Compiler (IR + transforms)
      | produces per‑device plans
      |
      v
  Strategy‑Agnostic Runtime
      | executes plans blindly
      |
      v
  Training runs; new strategy = new annotations, no runtime changes
One sentence: From *monolithic runtime with hardcoded strategies to declarative strategy specification + automatic compilation, the core shift is that the runtime no longer knows about the strategy – all the strategy‑specific logic is pushed into a compile‑time pass that produces per‑device scripts.
Expert Assessment
Problem choice: This is a real gap. The industry has been stitching together custom runtime changes for years (e.g., DeepSeek‑V3’s DualPipe required significant engineering). Piper formalizes a clean separation that has been overdue. The problem sits right at the intersection of systems and ML, where many practitioners hurt.
Method maturity: The approach is clever but not radically new – it borrows from traditional compiler IR design and applies it to distributed training. The key insight is that training strategies can be expressed as graph transformations. However, the paper likely has to handle tricky corners (dynamic control flow, ZeRO parameter offloading). I suspect the prototype is strong on common cases but may struggle with exotic hardware or models with irregular computation. No simpler approach exists that gives the same generality without sacrificing performance on standard strategies.
Experimental integrity: The claim of “performance parity on commonly available strategies such as ZeRO” is a strong signal – it means they didn’t sacrifice baseline performance for flexibility. The DualPipe results showing memory and throughput gains suggest the IR optimizations genuinely find better schedules. I’d need to see the full paper for ablation studies (what if you disable overlap? how much does the IR cost?). No obvious red flags, but the experiments likely focus on a few models (GPT‑scale, MoE). Fairness of baselines: they should compare against hand‑tuned versions of the same strategy, which is hard to get exactly right. If they do, the numbers are credible.
Writing quality: The abstract is concise and claims are well‑scoped. I expect the main paper has a clear figures‑first narrative. A common weakness in systems papers is insufficient motivation in the introduction – they should state earlier why existing frameworks fall short. If the paper spends too many pages on low‑level IR details before showing the payoff, readers will lose interest. The *Related Work section is also critical: they need to distinguish Piper from other IR‑based systems (e.g., Ray, TensorFlow’s XLA). If that’s done well, the paper is solid.
Verdict: Weak accept — The idea is well‑motivated and the experimental signals are positive, but the core technique (IR + transformations) is not entirely novel; the value is in the careful engineering and the demonstrated flexibility. Still, the paper is worth reading for anyone designing next‑gen training frameworks.
Takeaways
Practitioners can steal two concrete ideas:
-
Declarative scheduling directives: Instead of hardcoding schedule logic (e.g., “overlap backward with forward via manual micro‑batch control”), expose a small directive language that lets users express *intent, and let the compiler derive the schedule. This pattern transfers to any domain with composable parallelism (e.g., multi‑GPU inference, distributed RL training).
-
Unified training DAG as an optimization target: By converting the entire training loop (including communication) into one graph, you unlock cross‑device optimizations that are impossible when each device’s operations are specified separately. This is directly applicable to designing custom collective algorithms or fusing optimizer steps with gradient sync. Even if you don’t build Piper itself, you can adopt a similar IR for your own experimental training system.
论文: 2606.11169
作者: Megan Frisella, Shubham Tiwari, Andy Ruan, Yi Pan, Parker Gustafson, Mat Jacob, Gilbert Bernstein, Stephanie Wang
分类: cs.DC, cs.AI
缺口
当前的大规模训练系统(如 DeepSpeed ZeRO、Megatron‑LM)依赖人类专家手动设计高级并行策略,然后在固定运行时中实现对应的低级执行代码。 这使得集成新兴策略(如 DeepSeek‑V3 的 DualPipe)需要重写运行时的大段代码,非常痛苦。 另一方面,通用框架虽然更灵活,但其实现仍然绑定了常见策略集(数据并行、流水线并行、专家并行)——要集成新策略就得在框架核心中打补丁。 领域亟需一种声明式表达任意训练策略的方法,让系统自动生成高效的每设备执行计划,同时不牺牲标准策略的性能。
+----------------------------------------------------+
| 问题:手动设计策略并绑定运行时 -> 难以适应新策略       |
+----------------------------------------------------+
                          |
                          v
+----------------------------------------------------+
| 假设:通过统一、与策略无关的中间表示将策略与运行时解耦   |
+----------------------------------------------------+
                          |
                          v
+----------------------------------------------------+
| 方法:用户用注释 + 调度指令声明策略 -> Piper IR       |
| (全局训练 DAG) -> 编译为每设备执行计划                 |
+----------------------------------------------------+
                          |
                          v
+----------------------------------------------------+
| 证据:在 ZeRO 上性能持平;在 DeepSeek‑V3 DualPipe    |
| 上有显存和吞吐量收益                                |
+----------------------------------------------------+
                          |
                          v
+----------------------------------------------------+
| 结论:Piper 实现了灵活的策略集成,且不导致性能回退,     |
| 为自动化策略搜索打开了大门                            |
+----------------------------------------------------+
增量
一句话: 在 Piper 之前,集成一种新的并行策略要么修改运行时,要么手工优化每个硬件细节;在 Piper 之后,你只需在高层声明一次策略,系统就能把它编译成高效的每设备执行计划,运行时完全与策略无关。
核心机制
Piper 的设计包含三层:用户接口、中间表示 (IR) 和运行时。
首先,用户用少量构造对 PyTorch 模型进行注释:并行性注释(例如“这个张量应该在数据并行副本间分片”或“这个模块是一个流水线阶段”)和调度指令(例如“将阶段 i 的反向与阶段 i+1 的正向重叠”)。这些注释嵌入在 Python 中但声明式的——它们描述策略“是什么”,而不是“怎么执行”。
其次,Piper 将带注释的模型转换成一个统一的全局训练 DAG——即它的 IR。每个操作(前向、反向、全规约、发、收等)成为一个节点,依赖关系成为边。IR 是与策略无关的:不管用户想要纯数据并行还是复杂的 DualPipe 调度,都用同一个图表示。然后 Piper 根据调度指令应用一系列 IR 变换——循环融合、通信‑计算重叠、设备放置等。这些变换在最终编译步骤之前优化图(例如,重排序节点以将梯度全规约与下一个前向重叠)。
第三,编译后的每设备执行计划被发送到一个轻量级分布式运行时,该运行时简单地执行每个节点的计划:读取一系列操作(计算内核调用、网络发送、屏障)并按顺序运行。运行时不知道任何策略细节——它只是按照编译器生成的调度执行。
          +-------------------+          +--------------------+
          | 用户注释            |          | 调度指令            |
          | (如 shard dim)     |          | (重叠、顺序)        |
          +--------+----------+          +---------+----------+
                   |                               |
                   v                               v
          +---------------------------------------------------+
          |         Piper IR (全局训练 DAG)                    |
          |  节点 = 计算/通信操作                              |
          |  边 = 数据依赖                                    |
          +------------------------+--------------------------+
                                   |
                                   v
          +-----------------------------------------------+
          | IR 变换 (融合、重叠、放置)                      |
          +----------------------+------------------------+
                                 |
                                 v
          +----------------------------------------------+
          | 编译:每设备执行计划(操作序列)                |
          +----------------------+-----------------------+
                                 |
                                 v
          +----------------------------------------------+
          | 与策略无关的运行时(只管执行计划)              |
          +----------------------------------------------+
现在来一个核比喻:把 Piper 想象成指挥家、管弦乐团以及一位可编程的谱曲家。
- 用户注释 + 调度指令 = 作曲家谱写乐曲,指定什么乐器什么时候演奏(并行性)以及乐段如何重叠(调度)。
- Piper IR = 完整的总谱——所有音符、力度和速度,对每个乐器在每个节拍都有记录。
- IR 变换 = 指挥家的诠释,决定让某些乐器提前或推迟(重叠),是否合并两个木管声部(融合),以及如何安排座位(设备放置)。
- 编译 = 将指挥家注释后的总谱抄写成每个乐手的分谱(每设备执行计划)。
- 运行时 = 乐手——他们只读自己的分谱,严格演奏。他们不知道整体结构,只管跟着音符走。
如果你想换一种配器风格(新的并行策略),你不需要重新训练乐手或重写管弦乐团核心——只需谱写新曲,让指挥家把它变成分谱。Piper 正是如此:新策略 → 新注释 → 新 IR → 新执行计划——运行时从不改变。
关键概念
-
全局训练 DAG(Piper IR):这是一个有向无环图,表示训练步骤中所有设备上的每一个操作。想象每个设备有自己的局部计算(前向、反向、优化器步骤)加上通信操作(all‑reduce、发送、接收)。通常这些操作分散在不同的文件或运行时中。Piper IR 将它们统一成一个图,使得编译器可以做跨设备优化——例如,将一个设备上的 all‑reduce 与另一个设备上的前向重叠。没有统一的 DAG,这些优化只能靠直觉且策略特定。
-
调度指令:这些是轻量级的注释,向编译器提示事情应该何时发生。例如,在流水线并行中你可以说“将阶段 1 的反向与阶段 2 的正向重叠”。指令不指定具体的微批次调度——它只是说“设法让它们重叠”。编译器随后根据指令和可用硬件决定是用 1F1B、交错还是 DualPipe 风格。这是一个强大的抽象:你声明意图,编译器算出物流。
-
编译为每设备执行计划:IR 变换后,Piper 为每个设备生成一个操作序列——本质上是一个“脚本”,包含内核启动和网络操作。这类似于 C++ 编译器生成机器码;运行时只管执行这个脚本。因为运行时与策略无关,Piper 可以输出非常细粒度的调度,混合计算和通信,这是固定运行时无法手工编码支持的。
框架转变
我们画一张餐巾纸上的速写,对比旧方法和 Piper 的方法:
之前(主流方法):
  人类设计师
      |
      | (1) 设计高级策略
      | (2) 手工实现低级执行
      |
      v
  单体运行时 (如 DeepSpeed ZeRO)
      | 包含每个策略的硬编码逻辑
      | 无法适应新策略而不改动代码
      |
      v
  训练进行,但新策略集成需要数月

之后(本文方法):
  用户(注释 + 指令)
      |
      | 声明式指定策略
      |
      v
  Piper 编译器(IR + 变换)
      | 生成每设备计划
      |
      v
  与策略无关的运行时
      | 盲目执行计划
      |
      v
  训练进行;新策略 = 新注释,运行时不变
一句话: 从包含硬编码策略的单体运行时到声明式策略指定 + 自动编译*,核心转变是运行时不再知道策略**——所有策略特定的逻辑被推入一个编译时环节,生成每设备脚本。
专家评审
选题眼光: 这是真缺口。工业界多年来一直在拼接自定义运行时改动(例如 DeepSeek‑V3 的 DualPipe 需要大量工程工作)。Piper 形式化了一个早就该有的清晰分离。问题恰好处于系统和 ML 的交汇点,很多从业者深受其苦。
方法成熟度: 方法聪明但并非革命性——它借鉴了传统编译器的 IR 设计,并应用于分布式训练。关键洞察是训练策略可以表达为图变换。不过,论文很可能需要处理棘手的角落(动态控制流、ZeRO 参数卸载)。我猜测原型在常见情况下很强,但可能难以应对非常规硬件或不规则计算模型。目前没有更简单的方法能在不牺牲标准策略性能的前提下提供同样的通用性。
实验诚意: “在常用策略(如 ZeRO)上性能持平”这一声明是一个强信号——意味着他们并没有因为灵活性而牺牲基线性能。DualPipe 在显存和吞吐量上的收益表明 IR 优化确实找到了更好的调度。我需要看完整论文来检查消融实验(如果关闭重叠会怎样?IR 开销有多大?)。没有明显的红旗,但实验很可能集中在一两个模型(GPT 规模、MoE)上。基线的公平性:应该与相同策略的手工优化版本进行比较,这很难完全做到。如果做到了,数字是可信的。
写作功力: 摘要简洁,声明范围得当。我预期正文会有清晰的以图为主的叙述。系统论文常见的弱点是引言中动机不够充分——他们应该在更早阶段说明为什么现有框架不足。如果论文花了过多篇幅在低级 IR 细节上才展示收益,读者会失去兴趣。**相关工作*部分也至关重要:需要把 Piper 与其他基于 IR 的系统(如 Ray、TensorFlow 的 XLA)区分开。如果这点做得好,论文就扎实。
判决: 弱接收 — 动机充分,实验信号积极,但核心技术(IR + 变换)并非全新;价值在于精心的工程实现和展示的灵活性。不过,对任何设计下一代训练框架的人来说,这篇论文都值得一读。
要点总结
实践者可以偷走两个具体想法:
- **