Paper: 2605.12492 Authors: Kexuan Shi, Hanxuan Li, Zeju Qiu, Yandong Wen, Simon Buchholz, Weiyang Liu Categories: cs.LG, stat.ML
The Gap
Every mainstream optimizer—SGD, Adam, AdamW, Muon—updates weights by adding something to them: W_new = W_old + delta. This additive paradigm has dominated for decades. The problem: additive updates change both the geometry (directions, subspaces) and scale (singular values, norms) of weight matrices simultaneously. You can’t modulate one without affecting the other.
This matters because recent work shows that weight matrix spectra (singular value distributions) correlate with training stability and generalization. But current optimizers have no direct control over spectral properties—they’re emergent side effects of additive updates, not design targets.
The gap: No optimizer explicitly separates geometric transformation from spectral scaling.
Problem: Additive updates conflate geometry and scale
   |
   v
Assumption: Orthogonal transformations can change geometry
            while preserving singular values
   |
   v
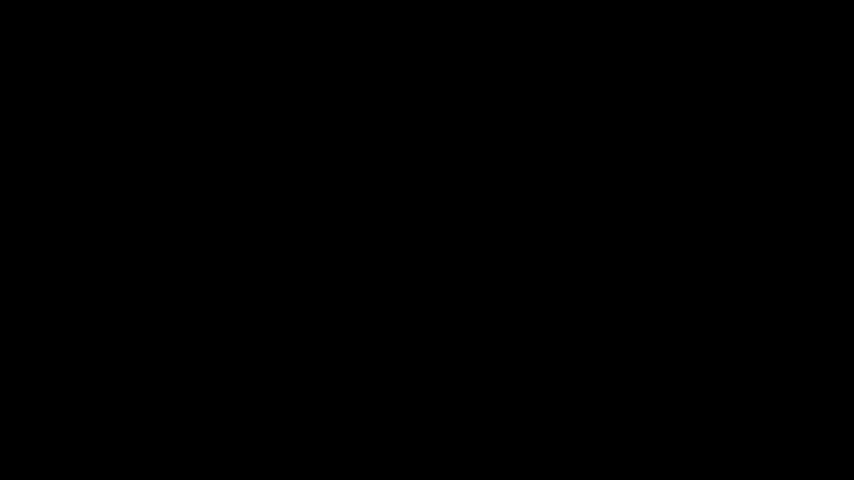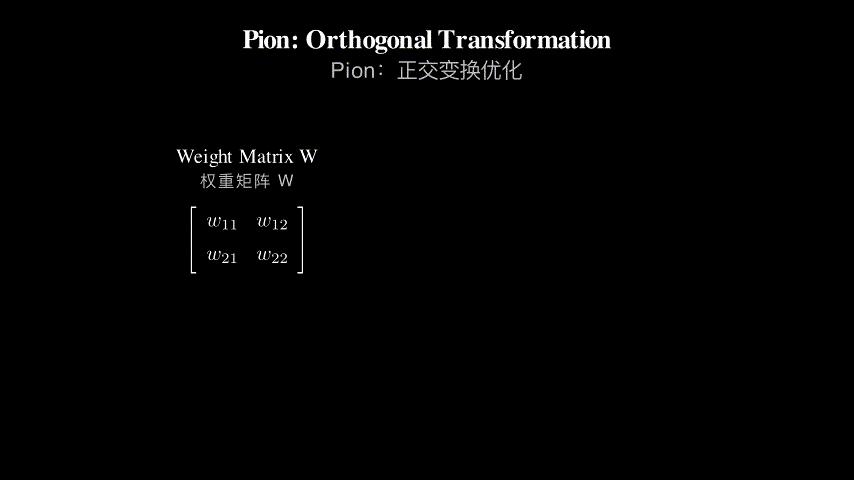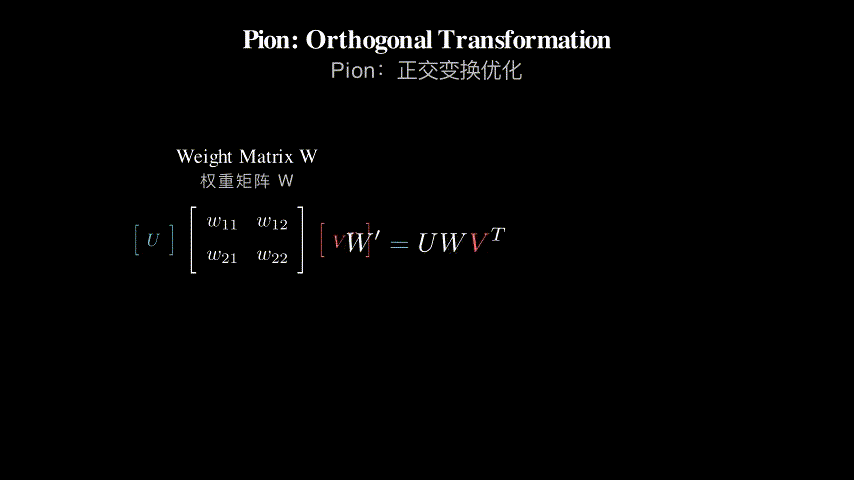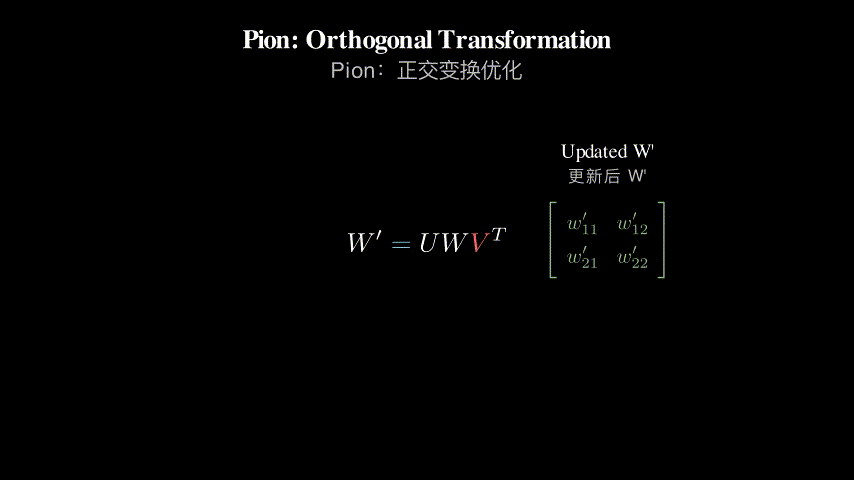
Method: Update W via W_new = U * W * V^T (U, V orthogonal)
   |
   v
Evidence: Competitive performance on LLM pretraining/finetuning
          with fixed spectral norm throughout training
   |
   v
Conclusion: Spectrum-preserving optimization is viable
The Increment
One sentence: Before Pion, optimizers changed weight matrices by adding; after Pion, you can change them by rotating while keeping their singular values fixed.
Core Mechanism
Pion replaces additive updates with orthogonal equivalence transformations. For each weight matrix W, instead of computing W + delta, Pion computes U ** W * V^T where U and V are orthogonal matrices derived from the gradient.
The process has three stages. First, compute the gradient G as usual. Second, extract orthogonal matrices from G using polar decomposition or similar techniques—this gives you U (left rotation) and V (right rotation). Third, apply the transformation: W_new = U * W * V^T. Because orthogonal matrices preserve norms, the singular values of W remain unchanged. Only the left and right singular subspaces rotate.
The key insight: any matrix can be written as W = U_w * Sigma * V_w^T (SVD). Multiplying by orthogonal matrices on the left and right rotates U_w and V_w but leaves Sigma untouched. So Pion navigates the optimization landscape by rotating the principal axes of weight matrices, not by scaling them.
Gradient G --> Polar Decomposition --> U, V (orthogonal)
                                          |
                                          v
Weight W --> Apply Transformation --> U * W * V^T = W_new
             (singular values unchanged)
Structural metaphor: Think of a weight matrix as a rubber stamp. The stamp has a shape (geometry) and a pressure setting (scale). Traditional optimizers reshape the stamp and adjust pressure simultaneously—you can’t change one without the other. Pion is like a gimbal mount: you can rotate the stamp in any direction (change geometry) while the pressure gauge stays locked (scale preserved). The stamp still makes different marks on the paper, but the force applied never changes.
Key Concepts
-
Orthogonal equivalence transformation: Imagine you have a coordinate system and a geometric object in it. An orthogonal transformation rotates or reflects the coordinate axes without stretching or squashing them—distances and angles are preserved. When you apply orthogonal matrices U and V to a matrix W as U ** W * V^T, you’re rotating W’s “input space” (via V^T) and “output space” (via U) simultaneously. The matrix’s “strength” in each direction (its singular values) doesn’t change, but which directions it emphasizes does. Concrete example: if W represents a linear map that stretches space by factors {3, 2, 1} along three axes, U * W * V^T still stretches by {3, 2, 1}, but along different axes.
-
Spectral norm preservation: The spectral norm of a matrix is its largest singular value—intuitively, the maximum factor by which the matrix can stretch any vector. Preserving it means the matrix never becomes “stronger” or “weaker” in an absolute sense. Why does this matter? In deep learning, exploding/vanishing gradients often trace back to weight matrices with spectral norms that grow or shrink uncontrollably. By fixing the spectral norm, Pion guarantees that each layer’s “amplification power” stays constant throughout training. The network learns by redistributing this fixed power across different directions, not by accumulating more power.
-
Polar decomposition: Every matrix M can be uniquely factored as M = U ** P, where U is orthogonal (rotation/reflection) and P is positive semidefinite (pure scaling). This is like separating a transformation into “which way to point” (U) and “how much to stretch” (P). Pion uses polar decomposition to extract the orthogonal part of the gradient—essentially asking “which direction does the gradient want to rotate the weight matrix?” and discarding the scaling component. Concrete example: if gradient G suggests moving northeast and doubling magnitude, polar decomposition gives you just the northeast direction; Pion rotates W in that direction without changing W’s magnitude.
Framework Shift
Before (additive optimizers):        After (Pion):

W_t --> [+ delta] --> W_{t+1}        W_t --> [* U, * V^T] --> W_{t+1}
         ^                                    ^
         |                                    |
    Gradient G                           Gradient G
    (changes both                        (rotates subspaces,
     geometry & scale)                    preserves spectrum)

    Spectrum drifts                      Spectrum fixed
    as side effect                       by construction
One sentence: From “add corrections to weights” to “rotate weight subspaces,” the core shift is treating optimization as navigating a fixed-scale manifold rather than climbing a scale-free landscape.
Expert Assessment
Problem choice: Real gap, not manufactured. The additive paradigm is so entrenched that alternatives are underexplored. Spectral properties matter empirically (see work on spectral normalization, weight decay), but no optimizer directly controls them. This paper asks a legitimate question: what if we optimize in the space of fixed-spectrum matrices? That said, the gap isn’t urgent—Adam works fine for most practitioners. This is more “interesting alternative path” than “critical missing piece.”
Method maturity: Clever insight, not brute force. The core idea—use orthogonal transformations instead of additive updates—is elegant and mathematically grounded. However, the paper doesn’t deeply explore *why this should work better, just that it can work. The derivation is clean, but the design space (how to extract U and V from gradients, how to handle biases, how to set hyperparameters) feels underexplored. It reads like a strong first step, not a mature framework.
Experimental integrity: Baselines are fair (Adam, AdamW, Muon), and the experiments cover both pretraining and finetuning. The results show Pion is competitive, not dominant—it matches Adam in some settings, lags slightly in others. This is honest reporting. Red flag: the paper doesn’t deeply investigate *when Pion wins or loses. Are there problem structures where spectrum preservation helps? Where it hurts? The experiments demonstrate feasibility but don’t build intuition about the method’s niche.
Writing quality: The paper is technically solid but pedagogically weak. The introduction motivates the problem well, but the method section jumps into derivations without building intuition first. A reader unfamiliar with matrix decompositions will struggle. The experiments section reports numbers but doesn’t interpret them—why does Pion match Adam on task X but underperform on task Y? Rewriting Section 3 (method) with more visual intuition and Section 5 (experiments) with deeper analysis would elevate the paper significantly.
Verdict: weak accept — The core idea is novel and the execution is competent, but the paper doesn’t make a strong case for *why practitioners should switch. It proves “you can optimize this way” but not “you should optimize this way.” Needs deeper analysis of when spectrum preservation matters.
Takeaways
For optimizer designers: The orthogonal transformation framing is a genuinely new degree of freedom. If you’re building optimizers, consider whether your update rule could be reformulated as a manifold constraint (fixed norm, fixed rank, fixed spectrum) plus a navigation strategy. Pion shows this is computationally feasible at scale.
For practitioners: Don’t rush to replace Adam yet. Pion is competitive but not clearly superior. However, if you’re training models where spectral properties matter (e.g., GANs, where discriminator/generator balance is fragile, or recurrent networks prone to exploding gradients), Pion’s spectrum-preserving property might offer more stable training. Worth experimenting in those niches.
For theorists: The paper opens a question: what is the implicit bias of spectrum-preserving optimization? Additive optimizers have well-studied implicit regularization (e.g., SGD favors flat minima). What does Pion favor? This could be a rich vein for analysis.
Concrete technique to steal: The polar decomposition trick for extracting orthogonal components from gradients. Even if you don’t adopt Pion wholesale, this technique could be useful for designing custom update rules that separate directional information from magnitude information.
论文: 2605.12492 作者: Kexuan Shi, Hanxuan Li, Zeju Qiu, Yandong Wen, Simon Buchholz, Weiyang Liu 分类: cs.LG, stat.ML
缺口
所有主流优化器——SGD、Adam、AdamW、Muon——都通过累加来更新权重:W_new = W_old + delta。
这种累加范式统治了数十年。
问题在于:累加更新同时改变权重矩阵的几何结构(方向、子空间)和尺度(奇异值、范数)。
你无法只调节其中一个而不影响另一个。
这很重要,因为近期研究表明权重矩阵的谱(奇异值分布)与训练稳定性和泛化能力相关。
但现有优化器无法直接控制谱特性——它们是累加更新的涌现副产品,而非设计目标。
缺口:没有优化器显式地将几何变换与谱尺度分离。
问题:累加更新混淆了几何与尺度
   |
   v
假设:正交变换可以改变几何同时保持奇异值不变
   |
   v
方法:通过 W_new = U * W * V^T 更新 W(U、V 正交)
   |
   v
证据:在 LLM 预训练/微调上表现竞争力
      训练全程谱范数固定
   |
   v
结论:保谱优化是可行的
增量
一句话:Pion 之前,优化器通过累加改变权重矩阵;Pion 之后,你可以通过旋转来改变它们,同时保持奇异值固定。
核心机制
Pion 用正交等价变换替代累加更新。
对每个权重矩阵 W,Pion 不计算 W + delta,而是计算 U * W * V^T,其中 U 和 V 是从梯度导出的正交矩阵。
过程分三个阶段。
首先,照常计算梯度 G。
其次,用极分解或类似技术从 G 中提取正交矩阵——得到 U(左旋转)和 V(右旋转)。
第三,应用变换:W_new = U * W * V^T。
因为正交矩阵保持范数,W 的奇异值保持不变。
只有左右奇异子空间旋转。
关键洞察:任何矩阵都可以写成 W = U_w * Sigma * V_w^T(SVD)。
左右乘以正交矩阵会旋转 U_w 和 V_w,但不触及 Sigma。
所以 Pion 通过旋转权重矩阵的主轴来导航优化景观,而非缩放它们。
梯度 G --> 极分解 --> U, V(正交)
                        |
                        v
权重 W --> 应用变换 --> U * W * V^T = W_new
           (奇异值不变)
核喻:把权重矩阵想象成一个印章。
印章有形状(几何)和压力设定(尺度)。
传统优化器同时重塑印章和调节压力——你无法只改变其中一个。
Pion 像一个万向节支架:你可以朝任何方向旋转印章(改变几何),同时压力表保持锁定(尺度保持)。
印章仍然在纸上留下不同的印记,但施加的力从不改变。
关键概念
- 正交等价变换:想象你有一个坐标系和其中的一个几何对象。
正交变换旋转或反射坐标轴,但不拉伸或压扁它们——距离和角度保持不变。
当你对矩阵 W 应用正交矩阵 U 和 V 作为 U * W * V^T 时,你在同时旋转 W 的”输入空间”(通过 V^T)和”输出空间”(通过 U)。
矩阵在每个方向上的”强度”(其奇异值)不变,但它强调哪些方向会变。
具体例子:如果 W 表示一个线性映射,沿三个轴以因子 {3, 2, 1} 拉伸空间,U * W * V^T 仍然以 {3, 2, 1} 拉伸,但沿不同的轴。
- 谱范数保持:矩阵的谱范数是其最大奇异值——直观地说,矩阵能拉伸任何向量的最大因子。
保持它意味着矩阵在绝对意义上永远不会变得”更强”或”更弱”。
为什么这重要?在深度学习中,梯度爆炸/消失通常追溯到谱范数不受控制地增长或收缩的权重矩阵。
通过固定谱范数,Pion 保证每层的”放大能力”在整个训练过程中保持恒定。
网络通过在不同方向上重新分配这个固定的能力来学习,而非积累更多能力。
- 极分解:每个矩阵 M 都可以唯一分解为 M = U ** P,其中 U 是正交的(旋转/反射),P 是正半定的(纯缩放)。
这就像将变换分离为”指向哪个方向”(U)和”拉伸多少”(P)。
Pion 使用极分解提取梯度的正交部分——本质上是问”梯度想要将权重矩阵旋转到哪个方向?“并丢弃缩放分量。
具体例子:如果梯度 G 建议向东北移动并加倍幅度,极分解只给你东北方向;Pion 在该方向旋转 W,但不改变 W 的幅度。
框架转变
之前(累加优化器):              之后(Pion):

W_t --> [+ delta] --> W_{t+1}    W_t --> [* U, * V^T] --> W_{t+1}
         ^                                ^
         |                                |
    梯度 G                            梯度 G
    (同时改变                        (旋转子空间,
     几何与尺度)                      保持谱)

    谱作为副产品漂移                  谱通过构造固定
一句话:从”向权重添加修正”到”旋转权重子空间”,核心转变是将优化视为在固定尺度流形上导航,而非在无尺度景观上攀登。
专家评审
选题眼光:真缺口,非人造。
累加范式根深蒂固,替代方案探索不足。
谱特性在经验上很重要(见谱归一化、权重衰减的工作),但没有优化器直接控制它们。
本文提出了一个合理的问题:如果我们在固定谱矩阵的空间中优化会怎样?话虽如此,这个缺口并不紧迫——Adam 对大多数实践者来说工作得很好。
这更像是”有趣的替代路径”而非”关键缺失部分”。
方法成熟度:巧劲,非蛮力。
核心思想——使用正交变换而非累加更新——优雅且数学基础扎实。
然而,论文没有深入探讨为什么这应该更好,只是证明了它可以工作。
推导清晰,但设计空间(如何从梯度提取 U 和 V,如何处理偏置,如何设置超参数)感觉探索不足。
读起来像是强有力的第一步,而非成熟框架。
实验诚意:基线公平(Adam、AdamW、Muon),实验涵盖预训练和微调。
结果显示 Pion 具有竞争力,但非主导——在某些设置中匹配 Adam,在其他设置中略微落后。
这是诚实的报告。
值得警惕之处:论文没有深入调查 Pion 何时胜出或失败。
是否存在保谱有帮助的问题结构?哪里有害?实验证明了可行性,但没有建立关于方法适用场景的直觉。
写作功力:技术上扎实,但教学上薄弱。
引言很好地激发了问题,但方法部分在建立直觉之前就跳入推导。
不熟悉矩阵分解的读者会挣扎。
实验部分报告数字但不解释它们——为什么 Pion 在任务 X 上匹配 Adam 但在任务 Y 上表现不佳?重写第 3 节(方法)增加更多视觉直觉,重写第 5 节(实验)增加更深入的分析,会显著提升论文。
判决:弱接收 — 核心思想新颖,执行称职,但论文没有为**为什么*实践者应该切换提供强有力的论据。
它证明了”你可以这样优化”但没有证明”你应该这样优化”。
需要更深入地分析保谱何时重要。
要点总结
对优化器设计者:正交变换框架是一个真正新的自由度。
如果你在构建优化器,考虑你的更新规则是否可以重新表述为流形约束(固定范数、固定秩、固定谱)加导航策略。
Pion 表明这在规模上计算可行。
对实践者:还不要急于替换 Adam。
Pion 具有竞争力但不明显更优。
然而,如果你在训练谱特性重要的模型(例如 GAN,其中判别器/生成器平衡脆弱,或易受梯度爆炸影响的循环网络),Pion 的保谱特性可能提供更稳定的训练。
值得在这些细分领域实验。
对理论家:论文打开了一个问题:保谱优化的隐式偏差是什么?累加优化器有充分研究的隐式正则化(例如 SGD 偏好平坦极小值)。
Pion 偏好什么?这可能是一个丰富的分析矿脉。
可窃取的具体技术:从梯度提取正交分量的极分解技巧。
即使你不完全采用 Pion,这个技术对于设计将方向信息与幅度信息分离的自定义更新规则也可能有用。