Paper: 2603.13228 Authors: Yangsong Zhang, Anujith Muraleedharan, Rikhat Akizhanov, Abdul Ahad Butt, Gül Varol, Pascal Fua, Fabio Pizzati, Ivan Laptev Categories: cs.LG, cs.AI, cs.CV, cs.RO
The Gap
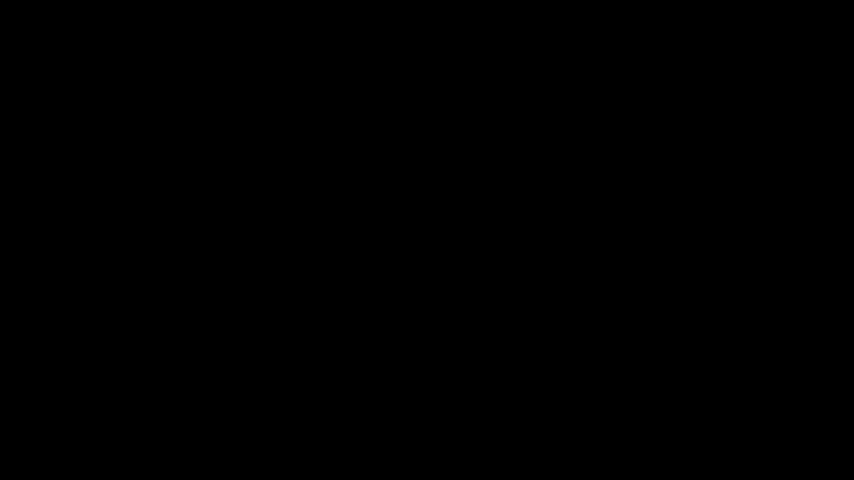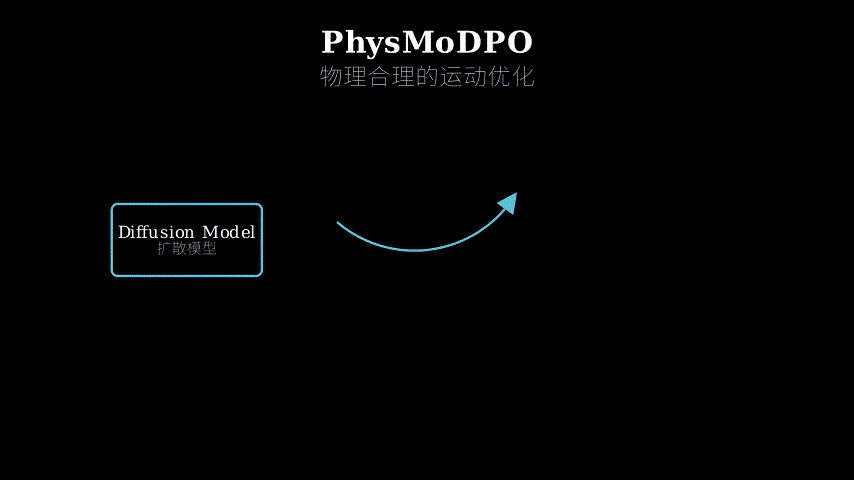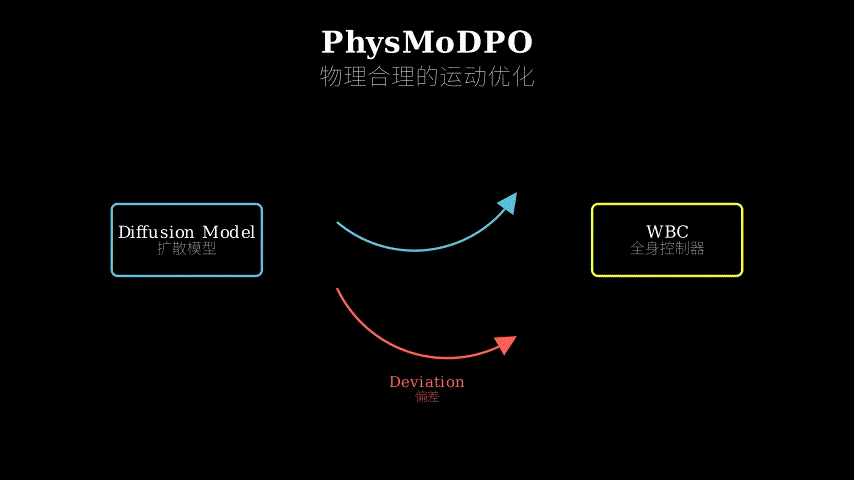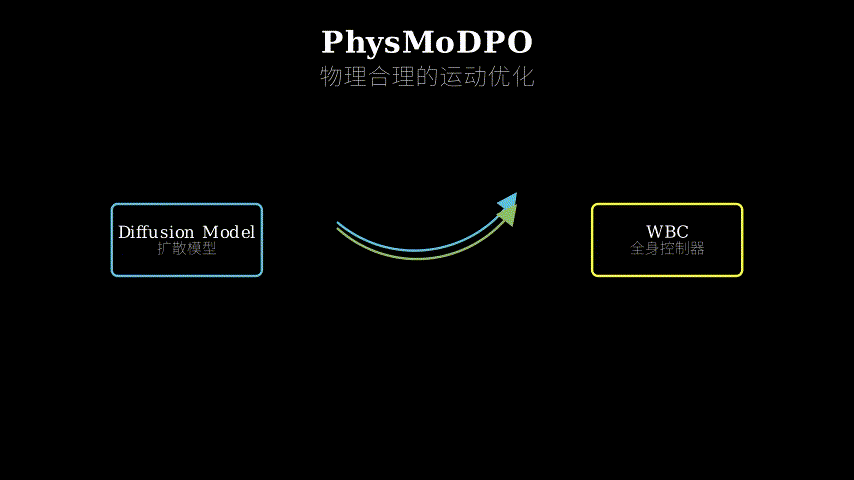
Text-to-motion diffusion models have gotten really good at generating human-like movements from text descriptions. The problem hits when you try to make a robot actually perform these motions. Current approaches use a Whole-Body Controller (WBC) to convert the generated motion into something physically executable—balancing forces, preventing falls, respecting joint limits. But here’s the catch: the WBC has to modify the motion so much to make it physics-compliant that the robot ends up doing something quite different from what the diffusion model generated. The model learns to make pretty animations, not executable movements.
Prior work tried fixing this with hand-crafted penalties during training—things like “penalize foot sliding” or “reward stable poses.” But these heuristics are brittle and don’t capture the full complexity of what makes a motion actually executable by a WBC.
Problem: Generated motion =/= Executable motion
   |
   v
Assumption: WBC modifications reveal what's physically wrong
   |
   v
Method: Train diffusion model using WBC output as ground truth
   |
   v
Evidence: Improved physics metrics + task success on real robot
   |
   v
Conclusion: Direct optimization for WBC compatibility works
The Increment
One sentence: Before this paper, motion models generated movements that controllers had to heavily modify to execute; after, models learn to generate movements that controllers can execute with minimal modification.
Core Mechanism
PhysMoDPO integrates the Whole-Body Controller directly into the training loop. For each generated motion, they run it through the WBC to get the actually-executed trajectory. Then they use Direct Preference Optimization (DPO)—a technique from language model alignment—to train the diffusion model to prefer generating motions that the WBC can execute faithfully.
The training pipeline works like this: generate pairs of motions from the diffusion model, pass both through the WBC, evaluate the WBC outputs using physics-based rewards (contact forces, joint torques, task completion), and use these rewards to create preference labels. The diffusion model then learns to increase the probability of generating motions that lead to high-reward WBC executions.
Text prompt --> Diffusion Model --> Motion A, Motion B
                                         |         |
                                         v         v
                                      WBC       WBC
                                         |         |
                                         v         v
                                    Executed  Executed
                                    Motion A  Motion B
                                         |         |
                                         v         v
                                    Reward    Reward
                                         |         |
                                         +----+----+
                                              |
                                              v
                                    Preference Label
                                              |
                                              v
                                    Update Diffusion Model
Think of it like training a chef who’s never tasted their own cooking. Traditional approaches are like giving the chef a recipe book with rules: “don’t oversalt,” “cook meat to 165°F.” PhysMoDPO is like having the chef cook two dishes, having actual diners eat them (the WBC executing the motions), getting feedback on which dish worked better in practice, and using that to improve. The chef learns not just what sounds good on paper, but what actually works when it hits the plate. The WBC is the diner’s digestive system—it reveals which recipes are actually edible versus which just look good in the cookbook.
Key Concepts
-
Whole-Body Controller (WBC): Imagine you’re a puppeteer controlling a marionette, but the strings can only pull so hard, the joints only bend so far, and if you don’t keep it balanced it’ll fall over. A WBC is the mathematical system that takes a desired motion (like “raise your arm”) and figures out exactly what forces each motor needs to apply to make it happen while respecting all physical constraints. It’s the bridge between “what you want the robot to do” and “what the robot can actually do without breaking or falling.” When the WBC has to modify a motion heavily, that’s a signal the original motion was physically implausible.
-
Direct Preference Optimization (DPO): Instead of defining a reward function and doing reinforcement learning (which is unstable and sample-inefficient), DPO works with pairwise preferences. You show the model two options, label which is better, and directly optimize the model to increase the probability of the preferred option. It’s like teaching a dog tricks: instead of trying to quantify exactly how many points each behavior is worth, you just consistently reward the better behavior when comparing two attempts. This is more stable because you’re not trying to learn absolute values, just relative rankings.
-
Physics-based rewards: These are metrics that measure how well a motion respects physical reality—things like “are the contact forces reasonable?” (you can’t push through the ground with infinite force), “are joint torques within motor limits?” (motors have maximum strength), “is the center of mass stable?” (won’t tip over). Unlike hand-crafted penalties that try to prevent specific bad behaviors, these rewards directly measure the quality of the executed motion in terms that matter for real-world deployment.
Framework Shift
Before (mainstream approach):        After (this paper):

Text --> Diffusion --> Motion        Text --> Diffusion --> Motion
              |                                    |
              v                                    v
         Add penalties                          WBC
         (foot sliding,                           |
          stability, etc)                         v
              |                              Executed Motion
              v                                    |
         Train model                               v
              |                            Evaluate rewards
              v                                    |
         Motion                                    v
              |                            Preference labels
              v                                    |
         WBC (at test time)                       v
              |                            Train model (DPO)
              v                                    |
         Heavily modified                         v
         executed motion                      Motion
                                                   |
                                                   v
                                              WBC (at test time)
                                                   |
                                                   v
                                              Minimally modified
                                              executed motion
From heuristic penalties to closed-loop optimization, the core shift is training with the actual execution system in the loop rather than guessing what will work.
Expert Assessment
Problem choice: This is a real gap. The text-to-motion community has been celebrating increasingly realistic animations while roboticists struggle to deploy them. The observation that WBC modifications reveal physical implausibility is sharp—it’s using the execution system as an oracle rather than trying to hand-code physics knowledge. The problem sits at a critical juncture where generative models meet embodied AI.
Method maturity: The use of DPO here is clever—it’s a natural fit for the preference structure (WBC-compliant vs non-compliant motions). However, I’m skeptical about the scalability. They’re running WBC in simulation for every training sample, which is computationally expensive. A simpler approach might be to distill the WBC’s preferences into a learned discriminator, but they don’t explore this. The method feels like the right idea executed at 70% efficiency.
Experimental integrity: The baselines are fair—they compare against the state-of-the-art motion generation methods plus ablations. The real-world G1 robot deployment is the strongest evidence; too many papers stop at simulation. However, I’d like to see failure cases. They show improvements but don’t discuss when the method breaks down. The metrics are appropriate (physics-based + task-specific), though I wish they’d included user studies on motion quality.
Writing quality: The related work section is too long and doesn’t clearly position the contribution. The method section is clear but could use more implementation details—what’s the WBC update rate? How many preference pairs per batch? The results section front-loads numbers without building intuition first. If they rewrote Section 4 to lead with qualitative insights then support with quantitative evidence, the paper would be much stronger.
Verdict: weak accept — Solid contribution addressing a real problem with reasonable evidence, but the method feels like an obvious next step rather than a conceptual breakthrough, and the writing doesn’t do the work justice.
Takeaways
The big transferable idea: when you have a downstream system that modifies your model’s outputs (like a safety filter, a constraint solver, or a controller), train your model to minimize those modifications rather than trying to hand-code what the downstream system wants. This applies beyond robotics—think content moderation systems, code formatters, or any pipeline where post-processing reveals misalignment.
Technically, the DPO framework for continuous control is worth stealing. Most DPO applications are in discrete spaces (language). Showing it works for motion generation opens the door for other continuous domains like trajectory planning, animation, or molecular dynamics.
The experimental setup of using simulation rewards to create preferences, then validating on real hardware, is a solid template for any sim-to-real work. They don’t just throw the model at the robot and hope—they use simulation to learn preferences, then verify the preferences transfer.
论文: 2603.13228 作者: Yangsong Zhang, Anujith Muraleedharan, Rikhat Akizhanov, Abdul Ahad Butt, Gül Varol, Pascal Fua, Fabio Pizzati, Ivan Laptev 分类: cs.LG, cs.AI, cs.CV, cs.RO
缺口
文本到运动的扩散模型已经能很好地根据文本描述生成类人运动了。
问题出在你想让机器人真正执行这些动作的时候。
当前方法使用全身控制器(WBC)把生成的运动转换成物理上可执行的东西——平衡力、防止摔倒、遵守关节限制。
但问题来了:控制器为了让运动符合物理规律,不得不大幅修改动作,以至于机器人最终做的事情和扩散模型生成的相差甚远。
模型学会了制作漂亮的动画,而不是可执行的动作。
之前的工作试图用手工设计的惩罚来修复这个问题——比如”惩罚脚滑动”或”奖励稳定姿势”。
但这些启发式规则很脆弱,无法捕捉到什么才能让运动真正被控制器执行的全部复杂性。
问题:生成的运动 =/= 可执行的运动
   |
   v
假设:控制器的修改揭示了物理上的问题
   |
   v
方法:用控制器输出作为真值训练扩散模型
   |
   v
证据:物理指标改善 + 真实机器人任务成功
   |
   v
结论:直接优化控制器兼容性有效
增量
一句话: 这篇论文之前,运动模型生成的动作需要控制器大幅修改才能执行;之后,模型学会生成控制器只需最小修改就能执行的动作。
核心机制
PhysMoDPO 把全身控制器直接整合到训练循环中。
对每个生成的运动,他们通过控制器运行它以获得实际执行的轨迹。
然后他们使用直接偏好优化(DPO)——一种来自语言模型对齐的技术——来训练扩散模型,让它倾向于生成控制器能忠实执行的运动。
训练流程是这样的:从扩散模型生成成对的运动,两个都通过控制器,用基于物理的奖励(接触力、关节扭矩、任务完成度)评估控制器输出,用这些奖励创建偏好标签。
然后扩散模型学习增加生成能导致高奖励控制器执行的运动的概率。
文本提示 --> 扩散模型 --> 运动A, 运动B
                              |         |
                              v         v
                           控制器    控制器
                              |         |
                              v         v
                          执行的    执行的
                          运动A     运动B
                              |         |
                              v         v
                           奖励      奖励
                              |         |
                              +----+----+
                                   |
                                   v
                             偏好标签
                                   |
                                   v
                          更新扩散模型
把它想象成训练一个从未品尝过自己菜肴的厨师。
传统方法就像给厨师一本规则手册:“别放太多盐”、“肉要煮到165华氏度”。
PhysMoDPO 就像让厨师做两道菜,让真正的食客吃(控制器执行运动),获得哪道菜在实践中更好的反馈,然后用这个来改进。
厨师学到的不只是纸面上听起来好的东西,而是端上桌时真正有效的东西。
控制器就是食客的消化系统——它揭示了哪些菜谱真正能吃,哪些只是在菜谱书里好看。
关键概念
- 全身控制器(WBC): 想象你是个操纵木偶的人,但绳子只能拉那么紧,关节只能弯那么多,如果不保持平衡它就会倒。
全身控制器是一个数学系统,它接收期望的运动(比如”抬起手臂”),然后精确计算每个电机需要施加什么力才能实现它,同时遵守所有物理约束。
它是”你想让机器人做什么”和”机器人实际能做什么而不会损坏或摔倒”之间的桥梁。
当控制器不得不大幅修改运动时,这就是原始运动在物理上不合理的信号。
- 直接偏好优化(DPO): 不是定义奖励函数然后做强化学习(不稳定且样本效率低),DPO 使用成对偏好。
你给模型展示两个选项,标记哪个更好,然后直接优化模型以增加首选选项的概率。
就像训练狗做把戏:不是试图量化每个行为到底值多少分,你只是在比较两次尝试时始终奖励更好的行为。
这更稳定,因为你不是试图学习绝对值,只是相对排名。
- 基于物理的奖励: 这些是衡量运动如何遵守物理现实的指标——比如”接触力合理吗?“(你不能用无限力推穿地面)、“关节扭矩在电机限制内吗?“(电机有最大强度)、“质心稳定吗?“(不会翻倒)。
与试图防止特定不良行为的手工惩罚不同,这些奖励直接衡量执行运动的质量,用对现实世界部署重要的术语。
框架转变
之前(主流方法):              之后(本文方法):

文本 --> 扩散 --> 运动          文本 --> 扩散 --> 运动
           |                              |
           v                              v
      添加惩罚                         控制器
      (脚滑动、                           |
       稳定性等)                          v
           |                         执行的运动
           v                              |
      训练模型                            v
           |                         评估奖励
           v                              |
        运动                              v
           |                         偏好标签
           v                              |
    控制器(测试时)                        v
           |                      训练模型(DPO)
           v                              |
      大幅修改的                          v
      执行运动                         运动
                                          |
                                          v
                                   控制器(测试时)
                                          |
                                          v
                                     最小修改的
                                     执行运动
从启发式惩罚到闭环优化,核心转变是在训练时把实际执行系统纳入循环,而不是猜测什么会有效。
专家评审
选题眼光: 这是个真缺口。
文本到运动社区一直在庆祝越来越逼真的动画,而机器人学家却在努力部署它们。
观察到控制器修改揭示物理不合理性很敏锐——它把执行系统当作预言机,而不是试图手工编码物理知识。
这个问题处于生成模型与具身AI相遇的关键节点。
方法成熟度: 这里使用 DPO 很聪明——它自然适合偏好结构(控制器兼容 vs 不兼容的运动)。
但我对可扩展性持怀疑态度。
他们为每个训练样本在仿真中运行控制器,计算开销很大。
更简单的方法可能是把控制器的偏好蒸馏到学习的判别器中,但他们没有探索这个。
方法感觉像是正确的想法以70%的效率执行。
实验诚意: 基线公平——他们与最先进的运动生成方法加消融实验对比。
真实世界的 G1 机器人部署是最有力的证据;太多论文止步于仿真。
但我想看失败案例。
他们展示了改进但没有讨论方法何时失效。
指标是合适的(基于物理 + 任务特定),尽管我希望他们包含运动质量的用户研究。
写作功力: 相关工作部分太长,没有清楚地定位贡献。
方法部分清晰但可以有更多实现细节——控制器更新率是多少?每批多少偏好对?结果部分先堆数字而不是先建立直觉。
如果他们重写第4节,先给出定性洞察然后用定量证据支持,论文会强得多。
判决: 弱接收 — 扎实的贡献解决了真实问题并有合理证据,但方法感觉像是显而易见的下一步而非概念突破,写作也没有为工作增光。
要点总结
可迁移的大想法:当你有一个下游系统会修改模型输出时(比如安全过滤器、约束求解器或控制器),训练模型去最小化这些修改,而不是试图手工编码下游系统想要什么。
这超越了机器人学——想想内容审核系统、代码格式化器,或任何后处理揭示不对齐的流水线。
技术上,用于连续控制的 DPO 框架值得借鉴。
大多数 DPO 应用在离散空间(语言)。
展示它对运动生成有效,为其他连续域打开了大门,比如轨迹规划、动画或分子动力学。
使用仿真奖励创建偏好然后在真实硬件上验证的实验设置,是任何仿真到现实工作的可靠模板。
他们不只是把模型扔给机器人然后祈祷——他们用仿真学习偏好,然后验证偏好能迁移。