Paper: 2605.05163 Authors: Yunhan Yang, Chunshi Wang, Junliang Ye, Yang Li, Zanxin Chen, Zehuan Huang, Yao Mu, Zhuo Chen, Chunchao Guo, Xihui Liu Categories: cs.CV
The Gap
Existing 3D generation methods (NeRF, diffusion-based models, GANs) produce visually impressive static geometry but ignore functional properties. You get a beautiful chair mesh, but the simulator doesn’t know which parts move, what materials they’re made of, or how joints articulate. For embodied AI and interactive virtual worlds, this is a dead end — agents need to open drawers, push buttons, grasp handles. Prior work either hand-annotates physics (doesn’t scale) or infers it post-hoc from geometry alone (unreliable and ambiguous).
The core problem: geometry-first generation decouples form from function. A drawer’s visual appearance doesn’t uniquely determine its sliding axis or friction coefficient. The paper argues you need to plan physics constraints *before generating geometry, not retrofit them after.
Problem: Static 3D generation
   |
   v
Assumption: Functional properties must guide geometry synthesis
   |
   v
Method: Two-stage (VLM plans physics blueprint -> diffusion realizes it)
   |
   v
Evidence: PhysDB dataset + KineVoxel Injection mechanism
   |
   v
Conclusion: Simulation-ready assets with plausible kinematics
The Increment
One sentence: Before PhysForge, 3D generation produced inert meshes requiring manual rigging; after, it outputs simulation-ready assets with material properties, joint hierarchies, and kinematic parameters baked in.
Core Mechanism
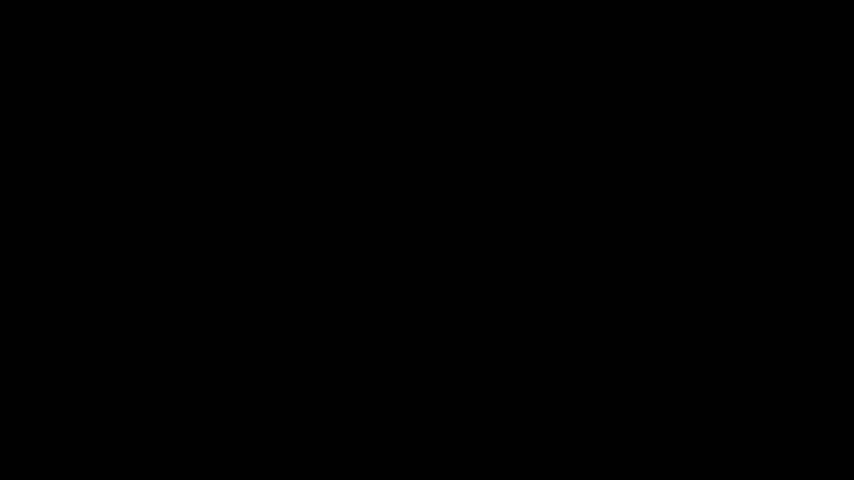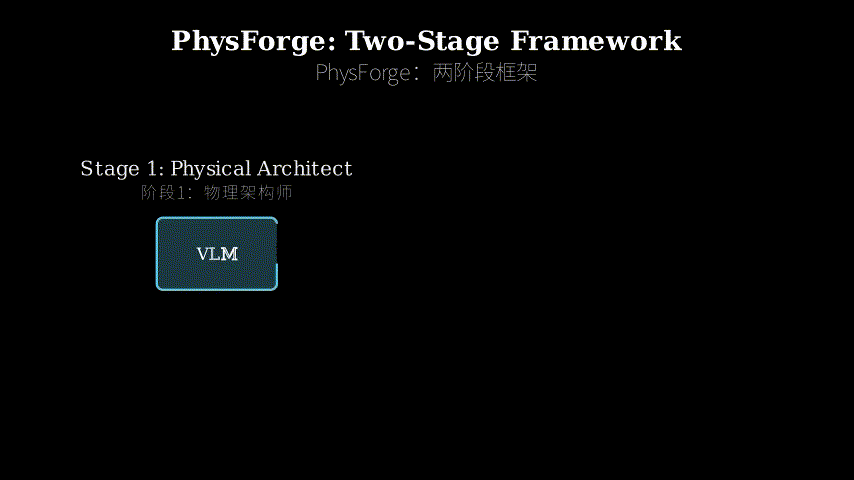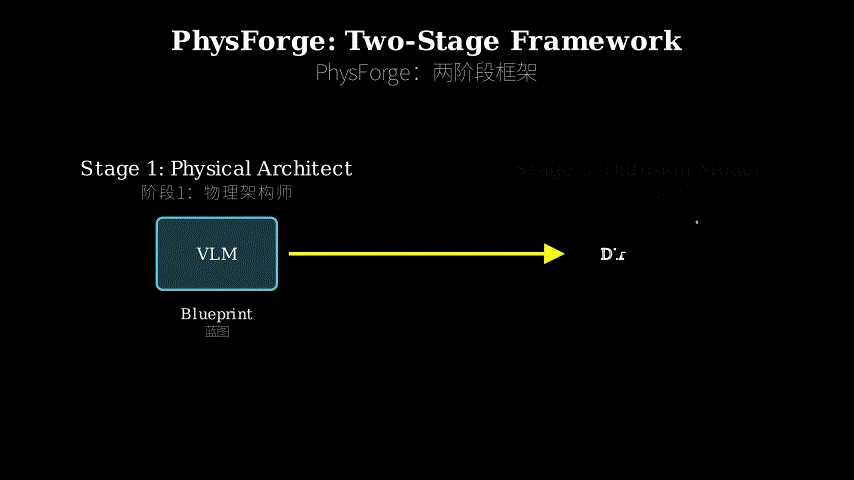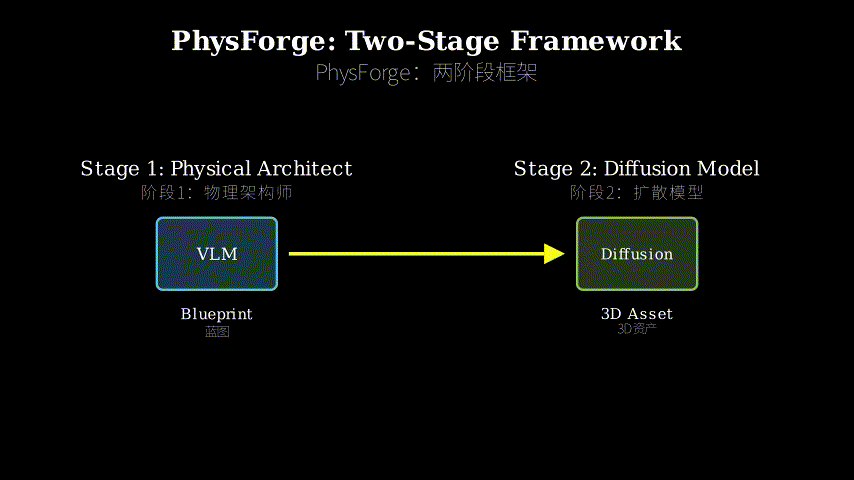
PhysForge splits generation into two stages. Stage 1: A vision-language model (VLM) acts as a “physical architect.” Given a text prompt like “wooden cabinet with two drawers,” it outputs a Hierarchical Physical Blueprint — a structured plan specifying material types (wood, metal), functional parts (drawer bodies, handles), kinematic constraints (prismatic joints with sliding ranges), and part relationships (drawer is child of cabinet frame). This blueprint is a symbolic representation, not geometry yet.
Stage 2: A physics-grounded diffusion model takes this blueprint and synthesizes voxel-based geometry. The key innovation is KineVoxel Injection (KVI) — during diffusion denoising, the model injects kinematic parameters (joint types, axes, limits) directly into the latent space via learned embeddings. This conditions geometry generation on physics constraints, ensuring the final mesh respects the planned kinematics. The output is a complete asset: textured geometry + material labels + articulation graph + joint parameters, ready to drop into a physics simulator.
Text Prompt
    |
    v
[VLM Physical Architect]
    |
    +---> Hierarchical Physical Blueprint
           (materials, parts, joints, constraints)
    |
    v
[Physics-Grounded Diffusion + KVI]
    |
    +---> Inject kinematic embeddings into latent space
    |
    v
Voxel Geometry + Kinematic Parameters
    |
    v
Simulation-Ready Asset
Think of PhysForge like building a puppet. Traditional 3D generation carves the puppet’s body (geometry) and hands it to you — now you figure out where to drill holes for strings and how joints should move. PhysForge instead starts with a puppet master’s blueprint: “left arm needs a hinge at the elbow, 90-degree range; right leg needs a ball joint at the hip.” Only after this plan is locked in does the carver (diffusion model) sculpt the wood, ensuring the elbow naturally bends where the blueprint says it should. The strings (kinematic parameters) and body (geometry) are co-designed, not retrofitted.
Key Concepts
-
Hierarchical Physical Blueprint: A structured specification of an asset’s functional decomposition. It’s not a 3D model — it’s a parts list with physics annotations. For a microwave: “door (rigid body, wood) connects to chassis (rigid body, metal) via revolute joint (axis: vertical, range: 0-120°); button (rigid body, plastic) connects to door via fixed joint.” This separates *what should exist (planning) from how it looks (synthesis). The hierarchy matters because physics simulators need parent-child relationships to propagate forces correctly.
-
KineVoxel Injection (KVI): A mechanism to condition diffusion models on kinematic parameters without breaking the generative process. Standard diffusion models denoise images/voxels based on text embeddings. KVI extends this: for each part in the blueprint, it creates a learned embedding vector encoding joint type, axis direction, and motion limits. During each denoising step, these embeddings are injected into the UNet’s latent features via cross-attention. Result: the model learns to generate geometry that “makes sense” for the specified kinematics — a sliding drawer gets a rectangular cavity, a rotating door gets a cylindrical hinge.
-
Four-Tier Physical Annotations: PhysDB labels assets at four levels: (1) material per part (wood, metal, plastic — affects mass, friction), (2) functional segmentation (which mesh regions are separate parts), (3) kinematic graph (parent-child joint relationships), (4) joint parameters (type, axis, limits). This is expensive to annotate but critical — without it, you can’t train models to predict physics from text. The paper’s contribution is scaling this to 150K assets via a mix of simulation, heuristics, and human verification.
Framework Shift
Before (mainstream approach):        After (this paper):

Text --> [Diffusion] --> Mesh        Text --> [VLM Planner] --> Blueprint
              |                                      |
              v                                      v
         Static Geometry              Blueprint --> [Diffusion+KVI] --> Mesh+Physics
              |                                      |
              v                                      v
    Manual Rigging (human)            Simulation-Ready Asset (automatic)
         (slow, error-prone)                  (scalable, consistent)
From geometry-centric generation to physics-first generation, the core shift is planning functional constraints before synthesis rather than inferring them post-hoc.
Expert Assessment
Problem choice: Real gap. Embodied AI and interactive simulation are bottlenecked by asset availability — manually rigging physics for every object doesn’t scale. The field has been stuck generating pretty but inert meshes. This paper targets the right constraint.
Method maturity: The two-stage design is sensible but not groundbreaking — it’s a natural application of VLMs for structured planning + diffusion for realization. KVI is clever but incremental (cross-attention conditioning is standard; the novelty is applying it to kinematic parameters). The real contribution is PhysDB — 150K annotated assets is serious infrastructure work. Without that dataset, the method wouldn’t train.
Experimental integrity: Baselines are fair (PartNet-Mobility, GAPartNet). Metrics cover geometry quality (Chamfer distance), kinematic accuracy (joint parameter error), and functional plausibility (simulation stability). One concern: the paper doesn’t deeply probe failure modes. What happens when the VLM hallucinates impossible kinematics? How often does KVI produce geometry that *looks right but fails in simulation due to collision issues? The success rate numbers (Table 3) are high but lack error analysis.
Writing quality: The abstract and intro are strong. Section 3 (method) buries the lead — KVI is explained in dense notation before intuition is built. The paper would benefit from leading with the puppet metaphor (or similar) before equations. Section 4 (experiments) is thorough but repetitive; ablations could be condensed. The related work section name-drops too many tangential papers without crisp positioning.
Verdict: weak accept — Solid execution on an important problem with meaningful infrastructure contribution (PhysDB), but the method itself is more engineering than insight. The paper’s value is in demonstrating that physics-grounded generation is tractable at scale, not in algorithmic novelty.
Takeaways
For practitioners building interactive 3D systems: The two-stage decomposition (symbolic planning → conditioned synthesis) is transferable. If you’re generating complex structured outputs (CAD models, robot designs, architectural layouts), consider separating constraint specification from geometry realization. VLMs are surprisingly good at outputting structured plans when prompted correctly.
For dataset builders: The four-tier annotation scheme (material, segmentation, kinematic graph, joint parameters) is a useful template for physics-aware datasets. The paper’s mix of automated heuristics + human verification is pragmatic — you don’t need perfect labels, just consistent enough to train on.
For diffusion model researchers: KVI shows that injecting structured parameters (not just text) into diffusion latents via learned embeddings works. This generalizes: if you need to condition generation on non-textual constraints (equations, graphs, sensor data), cross-attention on learned embeddings is a viable path.
Steal this: The “Hierarchical Physical Blueprint” as an intermediate representation. It’s a clean interface between high-level intent (text) and low-level realization (mesh). If you’re building multi-stage generative pipelines, explicit intermediate symbolic representations reduce error propagation and make debugging tractable.
论文: 2605.05163 作者: Yunhan Yang, Chunshi Wang, Junliang Ye, Yang Li, Zanxin Chen, Zehuan Huang, Yao Mu, Zhuo Chen, Chunchao Guo, Xihui Liu 分类: cs.CV
缺口
现有的3D生成方法(NeRF、基于扩散的模型、GAN)能产出视觉上令人印象深刻的静态几何体,但忽略了功能属性。
你得到一个漂亮的椅子网格,但模拟器不知道哪些部分能动、由什么材料制成、关节如何铰接。
对于具身AI和交互式虚拟世界来说,这是死路——智能体需要打开抽屉、按按钮、抓握把手。
先前工作要么手工标注物理属性(无法规模化),要么从几何体事后推断(不可靠且模糊)。
核心问题:几何优先的生成将形式与功能解耦。
抽屉的视觉外观无法唯一确定其滑动轴或摩擦系数。
论文认为需要在生成几何体之前规划物理约束,而非事后改装。
问题:静态3D生成
   |
   v
假设:功能属性必须引导几何体合成
   |
   v
方法:两阶段(VLM规划物理蓝图 -> 扩散实现蓝图)
   |
   v
证据:PhysDB数据集 + KineVoxel注入机制
   |
   v
结论:具有合理运动学的仿真就绪资产
增量
一句话:PhysForge之前,3D生成产出需要手动绑定的惰性网格;
之后,它输出仿真就绪的资产,材料属性、关节层次和运动学参数都已内置。
核心机制
PhysForge将生成分为两个阶段。
阶段1:视觉-语言模型(VLM)充当”物理架构师”。
给定文本提示如”带两个抽屉的木柜”,它输出分层物理蓝图——一个结构化计划,指定材料类型(木材、金属)、功能部件(抽屉本体、把手)、运动学约束(带滑动范围的棱柱关节)以及部件关系(抽屉是柜体框架的子节点)。
这个蓝图是符号表示,还不是几何体。
阶段2:物理基础扩散模型接收这个蓝图并合成基于体素的几何体。
关键创新是KineVoxel注入(KVI)——在扩散去噪过程中,模型通过学习到的嵌入将运动学参数(关节类型、轴向、限制)直接注入潜在空间。
这使几何体生成以物理约束为条件,确保最终网格遵守规划的运动学。
输出是完整资产:纹理几何体 + 材料标签 + 铰接图 + 关节参数,可直接放入物理模拟器。
文本提示
    |
    v
[VLM物理架构师]
    |
    +---> 分层物理蓝图
           (材料、部件、关节、约束)
    |
    v
[物理基础扩散 + KVI]
    |
    +---> 将运动学嵌入注入潜在空间
    |
    v
体素几何体 + 运动学参数
    |
    v
仿真就绪资产
把PhysForge想象成制作木偶。
传统3D生成雕刻木偶的身体(几何体)然后交给你——现在你要弄清楚在哪里钻孔穿线、关节该如何移动。
PhysForge则从木偶师的蓝图开始:“左臂肘部需要铰链关节,90度范围;
右腿髋部需要球形关节。
“只有在这个计划锁定后,雕刻师(扩散模型)才雕刻木材,确保肘部自然地在蓝图指定的位置弯曲。
线(运动学参数)和身体(几何体)是共同设计的,而非改装的。
关键概念
- 分层物理蓝图:资产功能分解的结构化规范。
它不是3D模型——而是带物理标注的零件清单。
对于微波炉:“门(刚体,木材)通过旋转关节(轴向:垂直,范围:0-120°)连接到机箱(刚体,金属);
按钮(刚体,塑料)通过固定关节连接到门。
“这将应该存在什么(规划)与看起来如何(合成)分离。
层次结构很重要,因为物理模拟器需要父子关系来正确传播力。
- KineVoxel注入(KVI):一种在不破坏生成过程的情况下,使扩散模型以运动学参数为条件的机制。
标准扩散模型基于文本嵌入对图像/体素去噪。
KVI扩展了这一点:对于蓝图中的每个部件,它创建一个学习到的嵌入向量,编码关节类型、轴向和运动限制。
在每个去噪步骤中,这些嵌入通过交叉注意力注入UNet的潜在特征。
结果:模型学会生成对指定运动学”有意义”的几何体——滑动抽屉得到矩形腔体,旋转门得到圆柱形铰链。
- 四层物理标注:PhysDB在四个层次标注资产:(1) 每个部件的材料(木材、金属、塑料——影响质量、摩擦),(2) 功能分割(哪些网格区域是独立部件),(3) 运动学图(父子关节关系),(4) 关节参数(类型、轴向、限制)。
这标注成本高但关键——没有它,无法训练模型从文本预测物理属性。
论文的贡献是通过仿真、启发式和人工验证的混合方式将其扩展到15万个资产。
框架转变
之前(主流方法):                之后(本文方法):

文本 --> [扩散] --> 网格          文本 --> [VLM规划器] --> 蓝图
              |                                      |
              v                                      v
         静态几何体                  蓝图 --> [扩散+KVI] --> 网格+物理
              |                                      |
              v                                      v
    手动绑定(人工)                仿真就绪资产(自动)
         (慢、易错)                      (可扩展、一致)
从以几何为中心的生成到物理优先的生成,核心转变是在合成之前规划功能约束,而非事后推断。
专家评审
选题眼光:真实缺口。
具身AI和交互仿真受资产可用性瓶颈制约——为每个对象手动绑定物理属性无法规模化。
该领域一直困在生成漂亮但惰性的网格上。
本文瞄准了正确的约束。
方法成熟度:两阶段设计合理但不算突破——这是VLM用于结构化规划 + 扩散用于实现的自然应用。
KVI巧妙但增量式(交叉注意力条件化是标准做法;
新颖之处在于将其应用于运动学参数)。
真正的贡献是PhysDB——15万个标注资产是严肃的基础设施工作。
没有那个数据集,方法无法训练。
实验诚意:基线公平(PartNet-Mobility、GAPartNet)。
指标涵盖几何质量(Chamfer距离)、运动学精度(关节参数误差)和功能合理性(仿真稳定性)。
一个担忧:论文没有深入探究失败模式。
当VLM幻觉出不可能的运动学时会发生什么?
KVI多久会产生看起来对但因碰撞问题在仿真中失败的几何体?
成功率数字(表3)很高但缺乏错误分析。
写作功力:摘要和引言很强。
第3节(方法)埋没了重点——KVI在建立直觉之前用密集符号解释。
论文如果在方程之前先用木偶比喻(或类似的)会更好。
第4节(实验)彻底但重复;
消融研究可以压缩。
相关工作部分罗列了太多边缘论文而没有清晰定位。
判决:弱接收 — 在重要问题上扎实执行,有意义的基础设施贡献(PhysDB),但方法本身更多是工程而非洞见。
论文的价值在于证明物理基础生成在规模上是可行的,而非算法新颖性。
要点总结
对于构建交互式3D系统的实践者:两阶段分解(符号规划 → 条件化合成)是可迁移的。
如果你在生成复杂的结构化输出(CAD模型、机器人设计、建筑布局),考虑将约束规范与几何实现分离。
VLM在正确提示时输出结构化计划的能力出人意料地好。
对于数据集构建者:四层标注方案(材料、分割、运动学图、关节参数)是物理感知数据集的有用模板。
论文的自动启发式 + 人工验证混合方式务实——你不需要完美标签,只需足够一致以供训练。
对于扩散模型研究者:KVI表明通过学习嵌入将结构化参数(不仅是文本)注入扩散潜在变量是有效的。
这可以推广:如果需要以非文本约束(方程、图、传感器数据)为条件生成,通过学习嵌入的交叉注意力是可行路径。
偷走这个:“分层物理蓝图”作为中间表示。
它是高层意图(文本)和低层实现(网格)之间的清晰接口。
如果你在构建多阶段生成管道,显式的中间符号表示可减少错误传播并使调试变得可行。