
Paper: 2605.28806 Authors: Viet Nguyen, Thao Nguyen, Vishal M. Patel, Yuheng Li Categories: cs.CV, cs.CL, cs.IR
The Gap
Existing long-term memory systems for AI agents treat images as second-class citizens. When a user shares a photo, systems like MemGPT or Letta convert it to a generic caption (“a person standing in a park”) and discard the visual data. This works fine when the question is “What did I do last weekend?” but fails when the question is “What’s my dog’s name?” or “Which of my friends has visited the most cities?” The personal information—recurring faces, owned objects, visual preferences—gets lost in translation.
Prior work assumed that if something matters, the user will say it explicitly in text. But people don’t narrate their lives like that. They share a photo of their dog without saying “This is my dog Max.” They show you their coffee mug collection without listing each one. The visual evidence is there, but text-only memory systems are blind to it.
Problem: Text-only memory loses personal visual info
   |
   v
Assumption: Images carry user facts text doesn't state
   |
   v
Method: Structured visual memory + identity resolution
   |
   v
Evidence: 23% gain on visual questions, no loss on text
   |
   v
Conclusion: Visual memory is a distinct component
The Increment
One sentence: Before this paper, AI agents forgot your face after you showed them a photo; after, they can recognize you, your dog, and your coffee mug across conversations.
Core Mechanism
VisualMem has three components working in concert. First, a text memory backend (any existing system like MemGPT) stores conversational text as usual. Second, a personal visual memory module maintains a structured database of user-associated entities: faces with identity labels, objects with ownership tags, and visual facts inferred from context. Third, an identity resolution layer uses conversational cues to link visual entities to user facts—when you say “my dog” while showing a photo, it binds that face to “user’s dog.”
Data flows like this: when an image arrives, the system extracts visual features (faces, objects, scenes) and holds them in a staging area. As the conversation unfolds, the identity resolver watches for linguistic anchors (“my,” “this is,” possessive constructions) and binds staged visuals to user entities. Resolved entities move into persistent visual memory with metadata (first seen, last seen, co-occurrence patterns). When a question arrives, the system queries both text memory and visual memory, then fuses results.
Input: Image + Conversation
   |
   v
[Visual Feature Extraction] ---> Staging Area
   |                                  |
   v                                  v
[Text Memory] <--- [Identity Resolver] ---> [Visual Memory]
   |                      ^                       |
   |                      |                       |
   +--- Linguistic cues --+                       |
   |                                              |
   v                                              v
[Query Fusion] <----------------------------------+
   |
   v
Output: Answer with visual + text evidence
Think of VisualMem as a photo album with smart captions. A traditional photo album just stores images in chronological order—you flip through and remember context yourself. A text-only system is like someone describing your photos to you over the phone—they tell you “there was a dog” but can’t show you which dog. VisualMem is like a photo album where each picture has sticky notes: “This is Max (your dog),” “This mug—you bought it in Tokyo,” “This person appears in 8 other photos.” The sticky notes aren’t written by you; they’re inferred from what you say while flipping through the album. When you later ask “Show me all photos with Max,” the album knows which dog is Max because it listened when you said “my dog” the first time.
Key Concepts
-
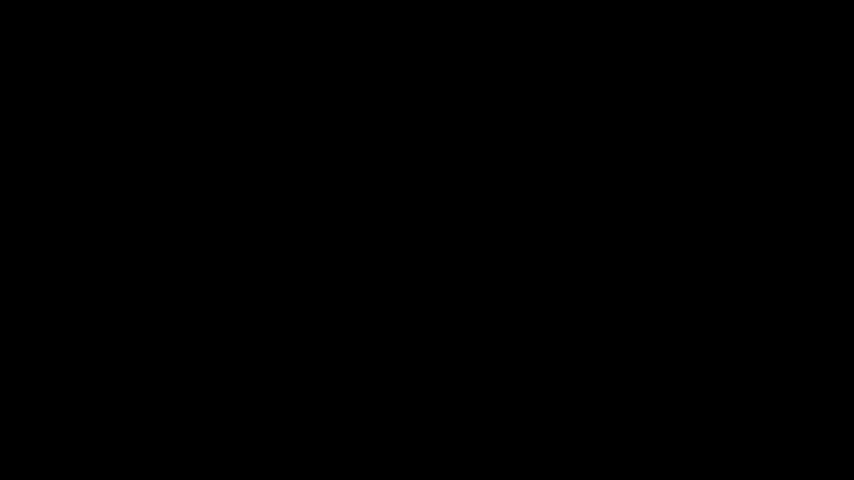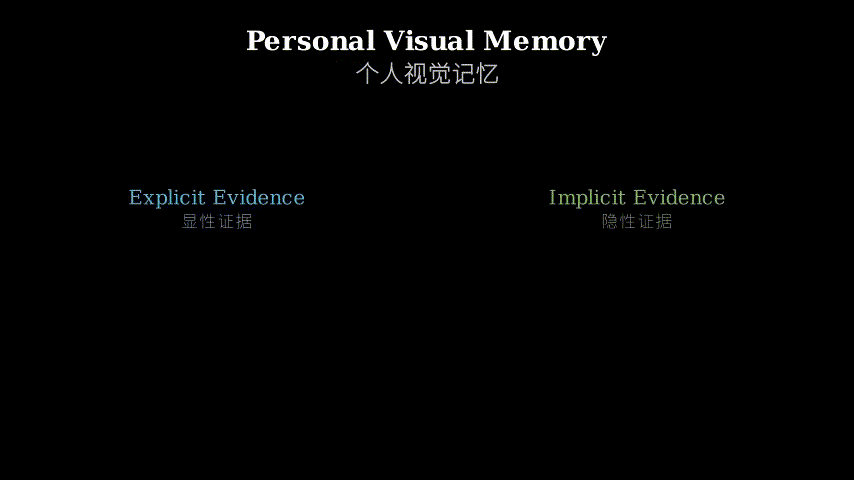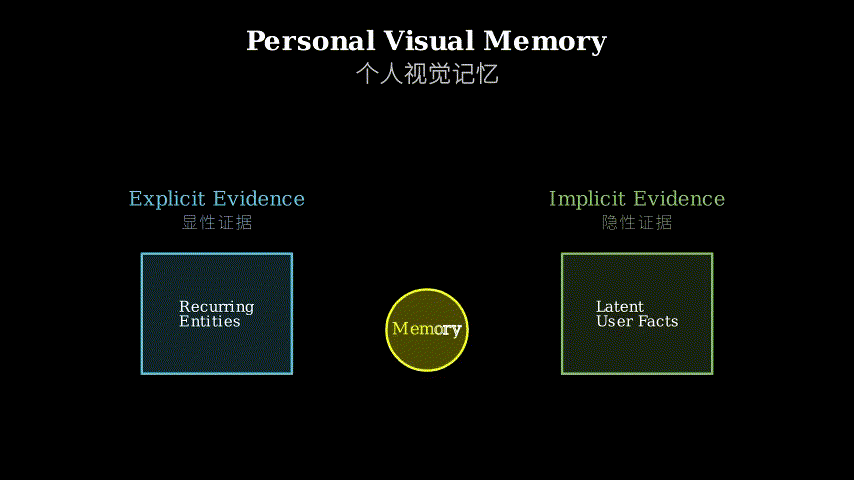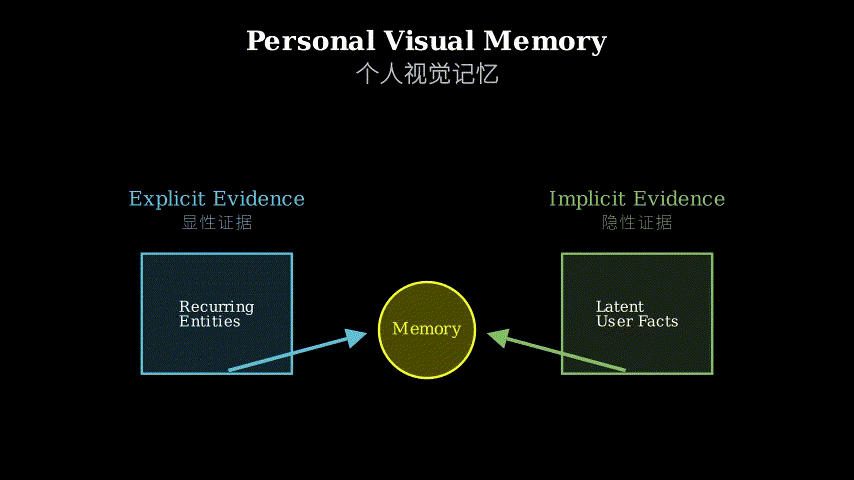
Explicit vs Implicit Visual Evidence: Explicit evidence is information directly visible and nameable in an image—a face, a logo, a specific object. Implicit evidence is user facts inferred from visual patterns plus context. Example: if you share three photos of coffee shops over two weeks, and each shows a different latte art style, the implicit fact is “user cares about coffee presentation.” The image alone doesn’t state this; the pattern plus conversational context does. Existing systems capture neither because they collapse images to captions before pattern detection happens.
-
Identity Resolution: This is the binding problem for personal memory. When you show a photo and say “this is my sister,” the system must link the face in the image to the entity “user’s sister” in its knowledge graph. The challenge: pronouns and possessives are ambiguous without visual grounding. “She loves hiking” could refer to your sister, your friend, or someone mentioned three turns ago. Identity resolution uses conversational context (recency, coreference, possessive markers) plus visual features (face embeddings, object attributes) to make the binding. Once bound, future images of that face automatically retrieve the “user’s sister” entity without re-annotation.
-
Structured Visual Memory: Instead of storing images as opaque blobs or reducing them to text, structured visual memory maintains a queryable database of visual entities with metadata. Each entity has: (1) visual features (embeddings, bounding boxes), (2) identity labels (resolved from conversation), (3) temporal metadata (first/last seen), (4) relational links (co-occurs with X, owned by user). This structure enables queries like “show me all photos with my dog” or “which friend appears most often?” that are impossible with caption-based memory.
Framework Shift
Before (caption-based memory):        After (VisualMem):

User: [shows photo of dog]            User: [shows photo of dog]
  |                                     |
  v                                     v
[Image -> Caption]                    [Image -> Visual Features]
  |                                     |        |
  "a dog in a park"                     |        +---> Face/Object DB
  |                                     |        |
  v                                     v        v
[Text Memory Store]                   [Text]  [Visual Memory]
  |                                     |        |
Later: "What's my dog's name?"         |        |
  |                                     +--------+
  v                                     |
[Search text: no match]                v
  |                                   [Fuse: dog entity + context]
  v                                     |
"I don't have that information"        v
                                      "That's Max, you mentioned
                                       him on May 15th"
One sentence: From collapsing images into lossy text to preserving visual entities with conversational grounding, the core shift is treating images as first-class memory objects.
Expert Assessment
Problem choice: Real gap. The text-centric bias in memory systems is a genuine limitation, not a manufactured problem. As AI agents move toward long-term personalization, the inability to remember visual context is a bottleneck. The paper sits at the intersection of multimodal understanding and personalized AI—a trajectory that’s accelerating.
Method maturity: Solid engineering with one clever insight (identity resolution via conversational grounding) and one brute-force component (the visual feature extractor is off-the-shelf). The identity resolver is the load-bearing idea; the rest is competent plumbing. A simpler approach might be: just store image embeddings and retrieve by similarity. But that misses the binding problem—you’d retrieve visually similar images without knowing which dog is *your dog.
Experimental integrity: The benchmark is custom-built, which raises questions about generalizability, but the authors test on existing text-memory benchmarks too and show no regression. Baselines are fair (MemGPT, Letta, GPT-4V with captions). The 23% improvement on visual questions is substantial, but I’d want to see ablations: how much comes from identity resolution vs just storing more visual data? The paper doesn’t break this down cleanly.
Writing quality: The related work section is too defensive—half of it is explaining why prior work isn’t solving this problem, which we already know from the intro. The method section is clear but could use a worked example earlier. The benchmark construction (Section 3) is thorough but reads like an appendix. If I were revising, I’d move the benchmark details to supplementary material and expand the identity resolution mechanism with concrete examples in the main text.
Verdict: weak accept — Addresses a real problem with a reasonable solution and solid results, but the method is more incremental than transformative. The benchmark contribution may outlast the method itself.
Takeaways
For practitioners building memory systems: Don’t reduce images to captions. Store visual features and use conversational context to bind them to user entities. The identity resolution pattern (watch for possessives + pronouns, bind to visual features in a sliding window) is simple enough to implement without the full VisualMem architecture.
For researchers: The explicit/implicit evidence framing is useful beyond vision. Audio memory (voice patterns, background sounds), sensor data (location patterns, activity rhythms)—all have explicit and implicit components that text summaries lose. The structured memory approach generalizes.
For skeptics: If you’re building a chatbot that only answers factual questions, you don’t need this. But if you’re building an agent that remembers *you—your preferences, your people, your stuff—text-only memory is leaving half the signal on the table.
论文: 2605.28806 作者: Viet Nguyen, Thao Nguyen, Vishal M. Patel, Yuheng Li 分类: cs.CV, cs.CL, cs.IR
缺口
现有的 AI 智能体长期记忆系统把图像当二等公民。
用户分享一张照片时,MemGPT 或 Letta 这类系统会把它转成通用描述(“一个人站在公园里”),然后丢弃视觉数据。
回答”我上周末干了什么?”
这没问题,但回答”我的狗叫什么名字?”
或”我哪个朋友去过的城市最多?”
就不行了。
个人信息——反复出现的面孔、拥有的物品、视觉偏好——在转译中丢失了。
此前的工作假设:如果某事重要,用户会在文本中明说。
但人们不会像旁白一样叙述生活。
他们分享狗的照片,不会说”这是我的狗 Max”。
他们展示咖啡杯收藏,不会逐个列举。
视觉证据就在那里,但纯文本记忆系统对此视而不见。
问题:纯文本记忆丢失个人视觉信息
   |
   v
假设:图像承载文本未陈述的用户事实
   |
   v
方法:结构化视觉记忆 + 身份解析
   |
   v
证据:视觉问题提升 23%,文本无损失
   |
   v
结论:视觉记忆是独立组件
增量
一句话: 这篇论文之前,AI 智能体看过你的照片后就忘了你的脸;之后,它们能在对话中识别你、你的狗和你的咖啡杯。
核心机制
VisualMem 有三个协同工作的组件。
第一,文本记忆后端(任何现有系统如 MemGPT)照常存储对话文本。
第二,个人视觉记忆模块维护一个结构化数据库,存储与用户关联的实体:带身份标签的面孔、带所有权标签的物品、从上下文推断的视觉事实。
第三,身份解析层利用对话线索将视觉实体链接到用户事实——当你展示照片并说”我的狗”时,它把那张脸绑定到”用户的狗”。
数据流动如下:图像到达时,系统提取视觉特征(面孔、物品、场景)并放入暂存区。
随着对话展开,身份解析器监视语言锚点(“我的”、“这是”、所有格结构)并将暂存的视觉内容绑定到用户实体。
已解析的实体带着元数据(首次出现、最后出现、共现模式)进入持久视觉记忆。
问题到来时,系统同时查询文本记忆和视觉记忆,然后融合结果。
输入:图像 + 对话
   |
   v
[视觉特征提取] ---> 暂存区
   |                    |
   v                    v
[文本记忆] <--- [身份解析器] ---> [视觉记忆]
   |              ^                    |
   |              |                    |
   +-- 语言线索 --+                    |
   |                                   |
   v                                   v
[查询融合] <---------------------------+
   |
   v
输出:带视觉 + 文本证据的答案
把 VisualMem 想象成带智能标注的相册。
传统相册只按时间顺序存图——你翻看时自己回忆上下文。
纯文本系统像是有人在电话里给你描述照片——他们说”有条狗”但不能告诉你是哪条狗。
VisualMem 像是一本相册,每张照片都贴着便签:“这是 Max(你的狗)”、“这个杯子——你在东京买的”、“这个人出现在另外 8 张照片里”。
便签不是你写的;它们是从你翻相册时说的话推断出来的。
当你后来问”给我看所有有 Max 的照片”,相册知道哪条狗是 Max,因为它听到了你第一次说”我的狗”。
关键概念
- 显性与隐性视觉证据: 显性证据是图像中直接可见、可命名的信息——一张脸、一个标志、一个特定物品。
隐性证据是从视觉模式加上下文推断出的用户事实。
例子:如果你在两周内分享三张咖啡店照片,每张都展示不同的拉花风格,隐性事实是”用户在意咖啡呈现”。
单张图像不会陈述这点;模式加上对话上下文才会。
现有系统两者都捕获不了,因为它们在模式检测发生前就把图像压缩成描述了。
- 身份解析: 这是个人记忆的绑定问题。
当你展示照片并说”这是我妹妹”,系统必须把图像中的脸链接到知识图谱中的”用户的妹妹”实体。
挑战:代词和所有格在没有视觉基础时是模糊的。
“她喜欢徒步”可能指你妹妹、你朋友或三轮对话前提到的某人。
身份解析使用对话上下文(最近性、共指、所有格标记)加上视觉特征(面部嵌入、物品属性)来完成绑定。
一旦绑定,未来该面孔的图像会自动检索”用户的妹妹”实体,无需重新标注。
- 结构化视觉记忆: 不是把图像存成不透明块或简化成文本,结构化视觉记忆维护一个可查询的视觉实体数据库,带元数据。
每个实体有:(1) 视觉特征(嵌入、边界框),(2) 身份标签(从对话解析),(3) 时间元数据(首次/最后出现),(4) 关系链接(与 X 共现、用户拥有)。
这种结构支持”给我看所有有我的狗的照片”或”哪个朋友出现最频繁?”
这类查询,基于描述的记忆做不到。
框架转变
之前(基于描述的记忆):              之后(VisualMem):

用户:[展示狗的照片]                  用户:[展示狗的照片]
  |                                     |
  v                                     v
[图像 -> 描述]                        [图像 -> 视觉特征]
  |                                     |        |
  "公园里的一条狗"                      |        +---> 面孔/物品数据库
  |                                     |        |
  v                                     v        v
[文本记忆存储]                        [文本]  [视觉记忆]
  |                                     |        |
后来:"我的狗叫什么?"                  |        |
  |                                     +--------+
  v                                     |
[搜索文本:无匹配]                      v
  |                                   [融合:狗实体 + 上下文]
  v                                     |
"我没有这个信息"                        v
                                      "那是 Max,你在
                                       5月15日提到过他"
一句话: 从把图像压缩成有损文本到保留带对话基础的视觉实体,核心转变是把图像当作一等记忆对象。
专家评审
选题眼光: 真缺口。
记忆系统中的文本中心偏见是真实的局限,不是人造问题。
随着 AI 智能体走向长期个性化,无法记住视觉上下文是个瓶颈。
论文处于多模态理解和个性化 AI 的交叉点——这是个加速的轨迹。
方法成熟度: 扎实的工程加一个巧妙洞见(通过对话基础的身份解析)和一个蛮力组件(视觉特征提取器是现成的)。
身份解析器是承重想法;其余是称职的管道工作。
更简单的方法可能是:直接存图像嵌入,按相似度检索。
但这会错过绑定问题——你会检索到视觉相似的图像,却不知道哪条狗是你的狗。
实验诚意: 基准是定制的,这引发了泛化性的问题,但作者也在现有文本记忆基准上测试并显示无退化。
基线公平(MemGPT、Letta、带描述的 GPT-4V)。
视觉问题上 23% 的提升很可观,但我想看消融实验:多少来自身份解析,多少来自只是存储更多视觉数据?
论文没有清晰地分解这点。
写作功力: 相关工作部分过于防御——一半在解释为什么此前的工作没解决这个问题,而我们从引言已经知道了。
方法部分清晰但可以更早给出实例。
基准构建(第 3 节)很彻底但读起来像附录。
如果我修订,我会把基准细节移到补充材料,在正文中用具体例子扩展身份解析机制。
判决: 弱接收 — 用合理的解决方案和扎实的结果解决真实问题,但方法更多是渐进而非变革性的。
基准贡献可能比方法本身更持久。
要点总结
对于构建记忆系统的实践者: 不要把图像简化成描述。
存储视觉特征,用对话上下文把它们绑定到用户实体。
身份解析模式(监视所有格 + 代词,在滑动窗口中绑定到视觉特征)足够简单,不需要完整的 VisualMem 架构就能实现。
对于研究者: 显性/隐性证据框架在视觉之外也有用。
音频记忆(声音模式、背景声音)、传感器数据(位置模式、活动节奏)——都有文本摘要会丢失的显性和隐性组件。
结构化记忆方法可以泛化。
对于怀疑者: 如果你在构建只回答事实问题的聊天机器人,你不需要这个。
但如果你在构建记住你的智能体——你的偏好、你的人、你的东西——纯文本记忆把一半信号留在了桌上。