Paper: 2605.00814 Authors: Siyuan Huang, Xiaoye Qu, Yafu Li, Tong Zhu, Zefeng He, Muxin Fu, Daizong Liu, Wei-Long Zheng, Yu Cheng Categories: cs.CV, cs.AI
The Gap
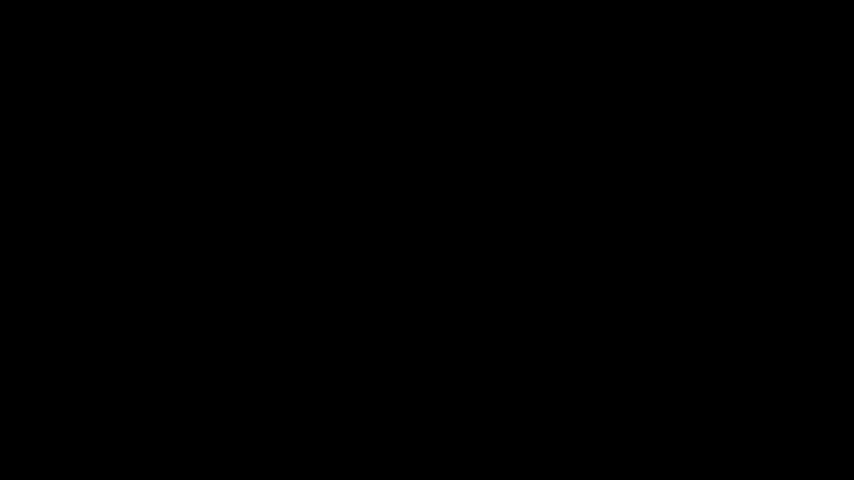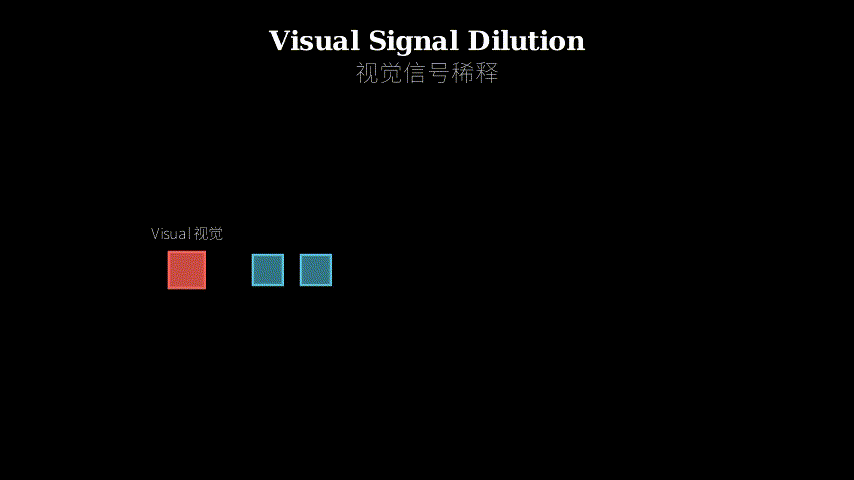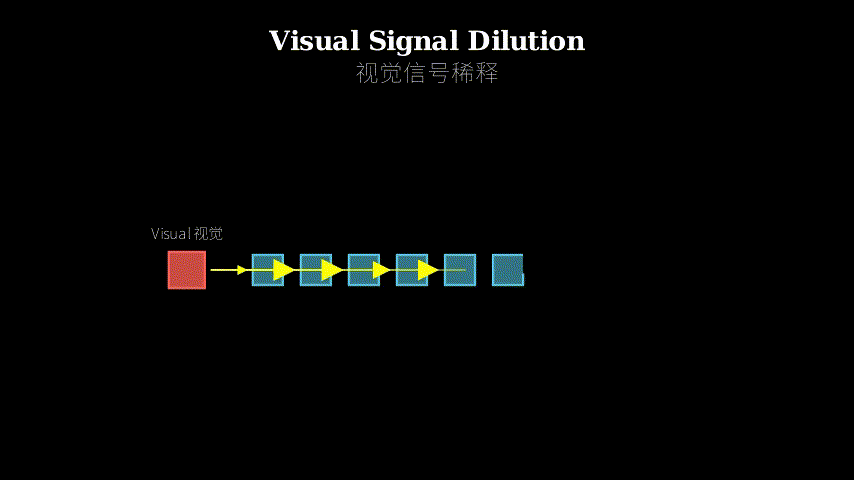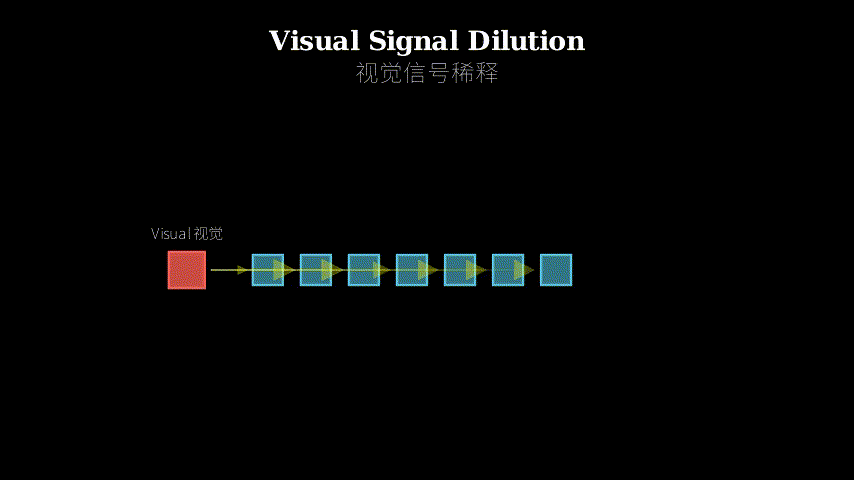
Autoregressive LVLMs like GPT-4V and Qwen-VL excel at multimodal tasks, but they suffer from “Visual Signal Dilution”: as the model generates more text tokens, the attention mechanism’s partition function grows, causing visual tokens to receive exponentially less attention. Prior work (LLaVA, Qwen-VL) treats this as an architectural given—visual tokens compete in the same attention pool as text tokens, and there’s no mechanism to maintain visual grounding as generation deepens. The result: models lose track of image details during long reasoning chains, exactly when visual precision matters most.
Problem: Visual attention decays ~ 1/sequence_length
   |
   v
Assumption: Need distance-agnostic visual access
   |
   v
Method: Parallel retrieval branch (PVM) bypassing attention decay
   |
   v
Evidence: +2.1% avg accuracy, stable attention across 512+ tokens
   |
   v
Conclusion: Structural bypass > fighting attention mechanics
The Increment
One sentence: Before—visual tokens fade into noise during long generation; after—a parallel memory lane keeps vision accessible regardless of text length.
Core Mechanism
PVM sits as a parallel branch next to the Feed-Forward Network (FFN) in each transformer layer. While the standard path processes tokens through self-attention → FFN, PVM creates a shortcut: it takes the current hidden state, uses it as a query to retrieve relevant visual embeddings from a persistent memory bank, and adds the retrieved visual features directly back into the residual stream. The memory bank stores visual embeddings from the image encoder, indexed by learned keys.
The retrieval is distance-agnostic—whether you’re at token 10 or token 500, the query-key matching cost is constant. This bypasses the attention mechanism’s fundamental limitation: in standard attention, visual tokens must compete with an ever-growing history of text tokens. PVM’s retrieval pathway doesn’t care about sequence position; it only cares about semantic relevance between the current reasoning state and stored visual features.
Training is lightweight: freeze the base LVLM, only train the query projection and memory keys. The module adds <1% parameters but provides a structural escape hatch from attention dilution.
Standard Path:              PVM Path (parallel):

Input -> Attention -> FFN   Input -> Query Proj.
  |                  |        |          |
  v                  v        v          v
Output <-------------+      Memory -> Retrieve -> Add to Output
                              Bank      Visual      ^
                               ^                    |
                               |                    |
                            [Image Encoder]    [Bypass attention
                                                competition]
Think of it like a library with two retrieval systems. The standard attention mechanism is the main reading room where everyone shares tables—as more people (text tokens) arrive, each person gets less space and attention. PVM is a private study carrel with a direct phone line to the archives. No matter how crowded the reading room gets, you can always call the archive and get the exact book (visual feature) you need delivered directly to your desk. The phone line’s speed doesn’t depend on how many people are in the reading room.
Key Concepts
-
Attention Partition Function: In softmax attention, the denominator sums exp(scores) over all tokens. As you generate more text, this sum grows, making each individual token’s contribution smaller—like splitting a pizza among more people. Visual tokens, fixed in number, get an ever-shrinking slice. This isn’t a bug; it’s how softmax normalization works. PVM sidesteps this by not using softmax attention for visual retrieval.
-
Distance-Agnostic Retrieval: Standard attention has O(n) cost to attend to a token n positions away because you compute attention over the full sequence. PVM uses learned query-key matching: the cost to retrieve a visual feature is O(1) relative to sequence length—you’re doing a fixed-size lookup, not scanning the entire history. It’s the difference between finding a book by its call number versus reading every spine in the library.
Framework Shift
Before (mainstream approach):        After (this paper):

[Visual] [Text Text Text...]         [Visual] [Text Text Text...]
    \      |   |   |                      |      |   |   |
     \     |   |   |                      |      |   |   |
      v    v   v   v                      v      v   v   v
    [Shared Attention Pool]            [Attention Pool]
           |                                 |
           v                                 v
    [Compete for signal]              [Text processing]
    [Visual fades as                        |
     text grows]                            +<---[PVM Memory]
                                             |        ^
                                             v        |
                                        [Output] [Direct visual
                                                  retrieval]
From shared-pool competition to dedicated visual lane, the core shift is structural separation of visual access from sequential attention dynamics.
Expert Assessment
Problem choice: Real and well-motivated. The attention dilution phenomenon is measurable and directly impacts performance on tasks requiring sustained visual grounding (e.g., multi-step visual reasoning, long-form image captioning). This isn’t a manufactured gap—it’s a consequence of autoregressive architecture meeting multimodal input.
Method maturity: Elegant in its simplicity. The parallel branch design is architecturally clean and doesn’t require retraining the base model. However, the paper doesn’t explore why learned retrieval is necessary—could a simpler fixed-attention mechanism (e.g., always attend to visual tokens with a minimum weight floor) achieve similar results? The comparison against such ablations is missing.
Experimental integrity: Solid but narrow. Experiments are on Qwen3-VL only (4B and 8B), which limits generalizability claims. Baselines are fair, but the paper doesn’t compare against other mitigation strategies like visual token reinjection or attention bias terms. The length-decay analysis (Figure 3) is convincing, but I’d want to see failure cases—when does PVM retrieve irrelevant visual features?
Writing quality: The abstract and introduction are crisp, but Section 3.2 (method details) buries the retrieval mechanism in notation. A clearer algorithmic walkthrough would help. The related work section conflates attention mechanisms with visual grounding strategies—tighter scoping would strengthen the positioning.
Verdict: weak accept — Addresses a real problem with a clean solution and solid evidence, but needs broader experimental validation and deeper ablation studies to justify the design choices.
Takeaways
Parallel bypass for persistent signals: When a critical input type (visual, audio, structured data) risks being drowned out by sequential generation, consider a parallel retrieval pathway that bypasses the main attention mechanism. This pattern generalizes beyond vision—think audio grounding in speech models or table lookups in data-to-text generation.
Distance-agnostic access matters: If your task requires consistent access to early-sequence information during long generation, attention’s quadratic cost and dilution effects work against you. Learned retrieval with fixed cost (query-key matching, hash tables, vector databases) can be a structural fix rather than fighting attention mechanics with tricks like attention biases.
Freeze-and-extend training: Adding a lightweight module to a frozen pretrained model is a practical deployment strategy. PVM shows you can get meaningful gains (<1% parameters, +2% accuracy) without full retraining. This is useful when you have a strong base model but need to patch a specific failure mode.
论文: 2605.00814 作者: Siyuan Huang, Xiaoye Qu, Yafu Li, Tong Zhu, Zefeng He, Muxin Fu, Daizong Liu, Wei-Long Zheng, Yu Cheng 分类: cs.CV, cs.AI
缺口
GPT-4V 和 Qwen-VL 这类自回归大型视觉语言模型在多模态任务上表现出色,但它们遭遇”视觉信号稀释”现象:模型生成的文本越多,注意力机制的配分函数就越大,导致视觉 token 获得的注意力呈指数级下降。
此前的工作(LLaVA、Qwen-VL)把这当作架构的既定事实——视觉 token 和文本 token 在同一个注意力池中竞争,没有机制能在生成深入时维持视觉锚定。
结果就是:模型在长推理链中丢失图像细节,恰恰是在最需要视觉精度的时候。
问题:视觉注意力衰减 ~ 1/序列长度
   |
   v
假设:需要与距离无关的视觉访问
   |
   v
方法:绕过注意力衰减的并行检索分支(PVM)
   |
   v
证据:平均准确率 +2.1%,512+ token 注意力稳定
   |
   v
结论:结构性绕过 > 对抗注意力机制
增量
一句话:之前——视觉 token 在长生成中淡化为噪声;之后——并行记忆通道让视觉访问不受文本长度影响。
核心机制
PVM 作为并行分支坐落在每个 transformer 层的前馈网络(FFN)旁边。
标准路径通过自注意力 → FFN 处理 token,PVM 则创建了一条捷径:它拿当前隐藏状态作为查询,从持久记忆库中检索相关的视觉嵌入,然后把检索到的视觉特征直接加回残差流。
记忆库存储来自图像编码器的视觉嵌入,用学习到的键索引。
检索与距离无关——无论你在第 10 个 token 还是第 500 个 token,查询-键匹配的成本都是恒定的。
这绕过了注意力机制的根本限制:在标准注意力中,视觉 token 必须与不断增长的文本 token 历史竞争。
PVM 的检索路径不关心序列位置;它只关心当前推理状态与存储的视觉特征之间的语义相关性。
训练很轻量:冻结基础 LVLM,只训练查询投影和记忆键。
模块增加的参数不到 1%,但提供了一个逃离注意力稀释的结构性出口。
标准路径:                  PVM 路径(并行):

输入 -> 注意力 -> FFN       输入 -> 查询投影
  |              |           |          |
  v              v           v          v
输出 <-----------+         记忆库 -> 检索 -> 加到输出
                              ^      视觉      ^
                              |                |
                           [图像编码器]    [绕过注意力
                                            竞争]
把它想象成一个有两套检索系统的图书馆。
标准注意力机制是主阅览室,大家共享桌子——随着更多人(文本 token)到来,每个人得到的空间和注意力都变少。
PVM 是一个私人学习隔间,有直通档案室的专线电话。
无论阅览室多拥挤,你都能随时打电话给档案室,让他们把你需要的确切书籍(视觉特征)直接送到你桌上。
电话线的速度不取决于阅览室有多少人。
关键概念
- 注意力配分函数:在 softmax 注意力中,分母对所有 token 的 exp(分数) 求和。
你生成的文本越多,这个和就越大,让每个单独 token 的贡献变小——就像把一张披萨分给更多人。
视觉 token 数量固定,得到的份额越来越小。
这不是 bug;这就是 softmax 归一化的工作方式。
PVM 通过不对视觉检索使用 softmax 注意力来绕过这个问题。
- 与距离无关的检索:标准注意力对距离 n 个位置的 token 进行注意的成本是 O(n),因为你要对整个序列计算注意力。
PVM 使用学习到的查询-键匹配:检索视觉特征的成本相对于序列长度是 O(1)——你在做固定大小的查找,而不是扫描整个历史。
这就像通过索书号找书和读遍图书馆每本书的书脊的区别。
框架转变
之前(主流方法):                之后(本文方法):

[视觉] [文本 文本 文本...]         [视觉] [文本 文本 文本...]
    \      |   |   |                   |      |   |   |
     \     |   |   |                   |      |   |   |
      v    v   v   v                   v      v   v   v
    [共享注意力池]                   [注意力池]
           |                              |
           v                              v
    [竞争信号]                       [文本处理]
    [视觉随文本                           |
     增长而淡化]                          +<---[PVM 记忆]
                                          |        ^
                                          v        |
                                     [输出] [直接视觉
                                             检索]
从共享池竞争到专用视觉通道,核心转变是将视觉访问从序列注意力动态中结构性分离。
专家评审
选题眼光:真实且动机充分。
注意力稀释现象是可测量的,直接影响需要持续视觉锚定的任务性能(如多步视觉推理、长篇图像描述)。
这不是人造缺口——这是自回归架构遇到多模态输入的必然结果。
方法成熟度:简洁优雅。
并行分支设计在架构上很干净,不需要重新训练基础模型。
但论文没有探讨为什么需要学习检索——更简单的固定注意力机制(比如始终给视觉 token 一个最小权重下限)能否达到类似效果?缺少这类消融对比。
实验诚意:扎实但狭窄。
实验只在 Qwen3-VL 上做(4B 和 8B),限制了泛化性声明。
基线公平,但论文没有与其他缓解策略比较,如视觉 token 重注入或注意力偏置项。
长度衰减分析(图 3)有说服力,但我想看失败案例——PVM 什么时候会检索不相关的视觉特征?
写作功力:摘要和引言简洁,但第 3.2 节(方法细节)把检索机制埋在符号里。
更清晰的算法演示会有帮助。
相关工作部分混淆了注意力机制和视觉锚定策略——更紧凑的范围界定会强化定位。
判决:弱接收 — 用干净的解决方案和扎实的证据解决真实问题,但需要更广泛的实验验证和更深入的消融研究来证明设计选择的合理性。
要点总结
持久信号的并行绕过:当关键输入类型(视觉、音频、结构化数据)有被序列生成淹没的风险时,考虑一条绕过主注意力机制的并行检索路径。
这个模式可以泛化到视觉之外——想想语音模型中的音频锚定或数据到文本生成中的表格查找。
与距离无关的访问很重要:如果你的任务需要在长生成过程中持续访问序列早期信息,注意力的二次成本和稀释效应会对你不利。
固定成本的学习检索(查询-键匹配、哈希表、向量数据库)可以是结构性修复,而不是用注意力偏置之类的技巧对抗注意力机制。
冻结-扩展训练:给冻结的预训练模型添加轻量级模块是实用的部署策略。
PVM 表明你可以在不完全重新训练的情况下获得有意义的收益(<1% 参数,+2% 准确率)。
当你有强大的基础模型但需要修补特定失效模式时,这很有用。