Paper: 2606.28322 Authors: Yana Wei, Hongbo Peng, Yanlin Lai, Liang Zhao, Kangheng Lin, En Yu, Keyu Lv, Han Zhou, Yin Tang, Haodong Li Categories: cs.CV
The Gap
Existing multimodal evaluation relies on holistic semantic matching — CLIP similarity, CIDEr, or LLM-as-judge — which give a single float from 0 to 100.
But these benchmarks are saturating: models score 90+ while still failing on concrete visual facts in dense scenes (e.g., “how many people are holding an umbrella?”).
Papers like VLM-Human try human annotation, but are sparse and expensive.
No one has assembled an atomic fact checklist per image with strict mandatory vs optional rules.
This paper identifies the gap: holistic scores mask conjunctive failures.
A model can describe “a man with a red umbrella” correctly but miss that there are three umbrellas — and get away with a high overall score.
The logical chain is:
[Problem: score saturation > hides brittleness]
    |
    v
[Assumption: holistic match is insufficient for dense scenes]
    |
    v
[Method: per-image Rubric with Must-Right + Easy-Wrong + Gated Score]
    |
    v
[Evidence: reliability gap, 8% open-closed stratification, human alignment]
    |
    v
[Conclusion: strict perceptual fidelity is prerequisite for reliable generation]
The Increment
One sentence: Before, metrics measured similarity; now, they audit atomic facts and punish critical failures with a binary gate.
Core Mechanism
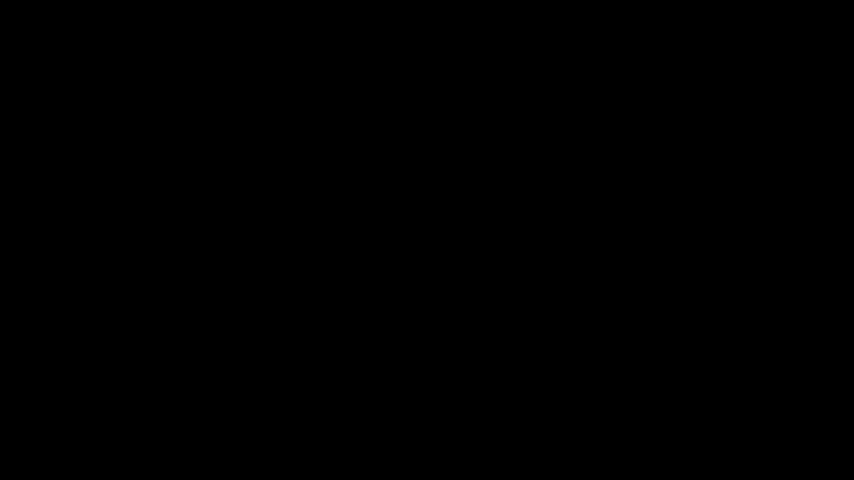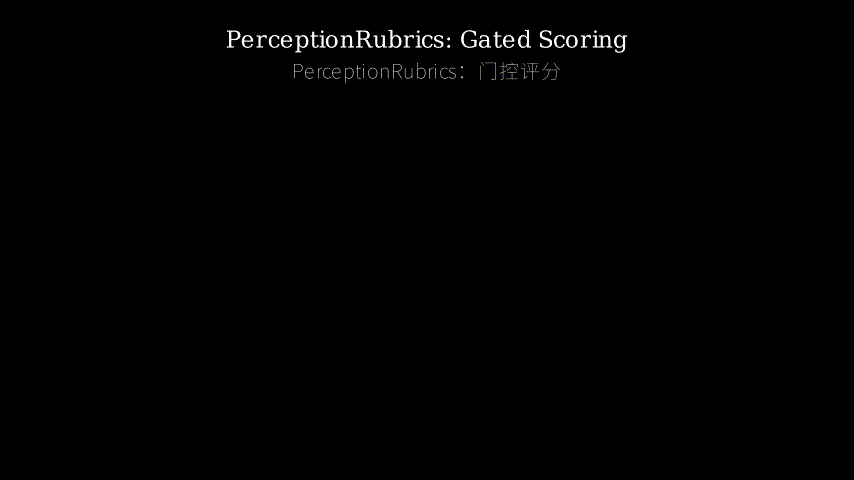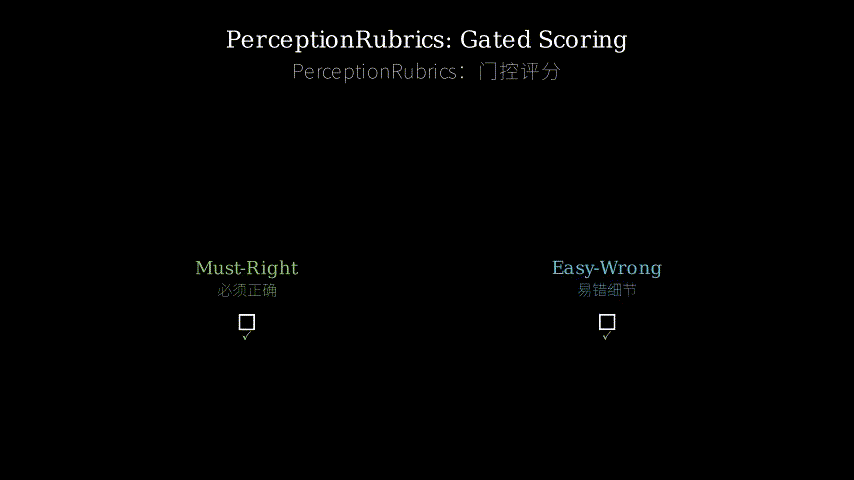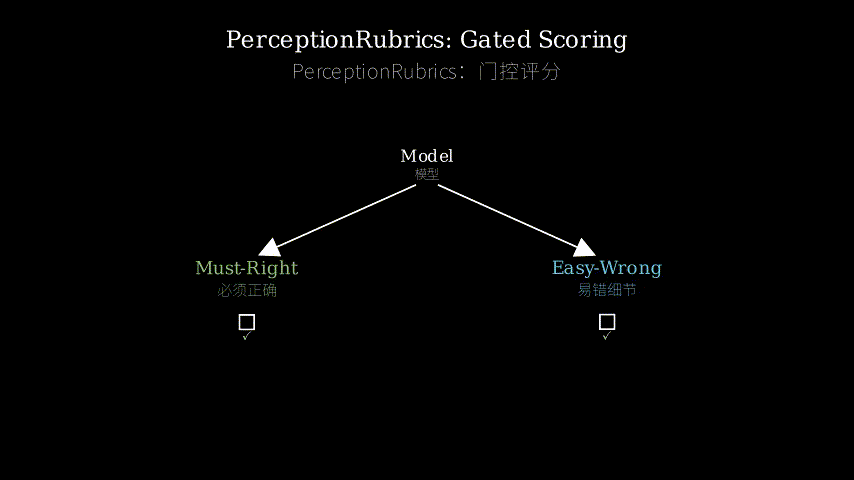
The framework has three components: a Rubric Bank derived from golden captions, a Dual-Stream Scoring (Must-Right vs Easy-Wrong), and a Gated Aggregator.
First, 1,038 information-dense images are paired with golden captions produced via a Circular Peer-Review Consensus pipeline — multiple captioners generate descriptions, cross-review, and iterate until consensus. From each golden caption, specific atomic rubrics are extracted: e.g., “the image contains exactly three dogs,” “the background is a beach,” etc. These are split into two streams: Must-Right (essential facts that must be correct) and Easy-Wrong (fine-grained details that are harder to get right but penalized less).
Scoring is not a weighted average. The Gated Scoring mechanism works as follows: if any Must-Right rubric fails (e.g., the model says 2 dogs but the golden says 3), the entire output receives 0 points — a hard binary penalty. Only after all Must-Right rubrics pass do the Easy-Wrong rubrics contribute partial credits.
[Model Output Caption]
       |
       v
[Rubric Comparator]
    /          \
   v            v
[Must-Right]  [Easy-Wrong]
  (all pass)   (partial credits)
       |            |
       +----[Gate]--+
            |
            v
[Final Score: 0 if any Must-Right fails; else weighted sum of Easy-Wrong]
Think of it like a driving test. The Must-Right rubrics are the essential safety checks: must stop at red lights, must signal turns. If you fail any of those, you fail the entire test — regardless of how smoothly you parallel park (Easy-Wrong). The Easy-Wrong items are the “nice to have” skills: maintaining constant speed, smooth gear changes. In the old evaluation (holistic matching), an examiner would give you 7/10 overall if you parallel parked well but ran a red light — which is absurd. PerceptionRubrics mirrors how real humans would evaluate: critical facts first, binary gate.
Key Concepts
-
Rubric: A per-image checklist of atomic statements, each with a ground truth answer (True/False or numeric). Unlike a generic caption similarity score, a rubric item is falsifiable — you can unambiguously say whether the model got it right. Example: for an image of a kitchen, a rubric item might be “the stove is on the left side of the refrigerator.” If the model says “stove on the right,” it’s wrong, period.
-
Gated Scoring: A decision rule where a necessary condition (all Must-Right rubrics pass) must be satisfied before any credit is given. This is radically different from average-based metrics where a high score on many items can compensate for a single catastrophic error. In practice, gated scoring finds that many models that score 90+ on CIDEr drop to 0 on certain images — revealing brittleness that traditional metrics miss.
-
Circular Peer-Review Consensus: A pipeline for constructing high-quality golden captions. Instead of one annotator, multiple captioners (human or model) generate an initial caption, then critique each other’s versions, then revise, repeating until agreement. This produces captions that are more reliable and less biased than single-source ones. The rubrics are then extracted from these agreed-upon golden captions.
Framework Shift
Before:
[Image + Caption] --> [Similarity Model (CLIP/GPT)] --> [Single Float Score]
(One number, no traceability to which facts were checked.)
After:
[Image + Caption] --> [Rubric Checklist with Gold Truth]
                        |-> Must-Right {all pass?}   (binary decision)
                        |-> Easy-Wrong {how many?}   (partial accumulation)
                        |-> Gate: if MR fails => 0
                        -> Final Score (interpretable, auditable)
From a single opaque score to an audit trail of atomic facts with a criticality gate.
Expert Assessment
Problem choice: Real and timely. The saturation of existing benchmarks is well-known; this paper precisely targets the *dense failure case that models are now hitting. It sits exactly where the field needs to move: from “can they answer?” to “do they see?”
Method maturity: Clever hybrid of human annotation and algorithmic rule. The Circular Peer-Review pipeline is not trivial but well-motivated. Scaling to thousands of images is reasonable. A simpler approach (e.g., random sampling of factoids) would miss the information-dense requirement, so the complexity is justified.
Experimental integrity: Baselines include recent VLMs (LLaVA, InternVL, GPT-4V) and standard metrics (CIDEr, CLIPScore). The 8% perception deficit between open/closed models is striking and consistent. One concern: the rubric construction was done by the same team who also designed the evaluation — potential for unconscious cherry-picking. But the paper reports inter-annotator agreement, so it’s not a fatal flaw.
Writing quality: Well-structured, but the “Circular Peer-Review” section could use a concrete worked example. As written, it’s somewhat abstract. If the authors added a sample with 3 rounds of review and how disagreements were resolved, the method would be much easier to replicate.
Verdict: weak accept — the core idea (atomic audit + gate) is publishable and useful, but the scale (1038 images) and manual effort limit immediate adoption. The metric itself could become a standard evaluation tool if the rubric database grows.
Takeaways
- Gated scoring for any factual verification task — e.g., in text summarization, if the summary must contain a key entity (Must-Right), fail the whole summary if missing.
- The decomposition of evaluation into atomic items makes model failures transparent — you can debug exactly which visual fact the model missed.
- The Circular Peer-Review method for ground truth construction is transferable to any annotation task — reduces bias and improves consensus quality.
论文: 2606.28322 作者: Yana Wei, Hongbo Peng, Yanlin Lai, Liang Zhao, Kangheng Lin, En Yu, Keyu Lv, Han Zhou, Yin Tang, Haodong Li 分类: cs.CV
缺口
现有的多模态评估依赖整体语义匹配——CLIP相似度、CIDEr或大模型打分。
这些基准分数已经饱和:模型常常得分90+,但在密集场景的具体视觉事实上却会出错(例如“图片里有几个人撑着雨伞?”)。
VLM-Human等尝试人工标注,但成本高、稀疏且不精细。
没人建立过每张图像的原子事实检查表,并且区分必需项与可选项。
这篇论文指出的缺口是:整体分数掩盖了合取失败。
模型能写出“一个拿着红伞的男人”,却漏掉照片里其实有三把伞——但整体分数仍然很高。
逻辑链条如下:
[问题:分数饱和 > 掩盖模型脆弱性]
    |
    v
[假设:整体语义匹配对密集场景不足]
    |
    v
[方法:每张图像的细目表 + 必对/易错双流 + 门控评分]
    |
    v
[证据:可靠性差距、8% 开源-闭源分层、与人类对齐]
    |
    v
[结论:严格感知保真度是可靠生成的前提]
增量
一句话: 之前评价看相似度;现在审计原子事实,并用二值门控惩罚关键失败。
核心机制
框架包含三个组件:从黄金标题导出的细目库、双流评分(必对项 vs 易错项)和门控聚合器。
首先,1038张信息密集的图像通过循环同行评议共识管道生成黄金标题——多位标注员生成描述、交叉评审、迭代修改直到达成一致。
从黄金标题中提取出每张图像的原子细目,例如“图像中恰好有三只狗”、“背景是沙滩”。
这些细目被分为两个流:必对项(必须正确的基本事实)和易错项(细节性强但扣分较轻)。
评分不是加权平均。门控评分机制的运作方式:如果任何一条必对项失败(例如模型说2只狗但黄金标注说3只),整个输出得到0分——硬性的二值惩罚。
只有所有必对项通过后,易错项才开始贡献部分分数。
[模型输出标题]
       |
       v
[细目比较器]
    /          \
   v            v
[必对项]      [易错项]
 (全部通过)    (部分得分)
       |            |
       +----[门控]--+
            |
            v
[最终分数:有必对项失败则0;否则易错项加权和]
把它想象成驾照考试。必对项是基本安全操作:红灯必须停、转弯必须打灯。
任何一项失败,整场考试就失败——不管侧方停车(易错项)停得多完美。
易错项是“锦上添花”的技巧:平稳加速、换挡流畅。
在旧评估(整体匹配)中,考官会因为你侧方停车漂亮但闯了红灯而给你7/10——这很荒谬。
PerceptionRubrics 模仿真实人类的评估方式:关键事实优先,二值门控。
关键概念
-
细目:每张图像的原子事实检查表,每条有一个正确答案(真/假或数值)。与通用标题相似度不同,一条细目是可证伪的——可以明确判断模型是否正确。例如:一张厨房图片,一条细目可能是“灶台在冰箱的左边”。如果模型说“灶台在右边”,那就是错的,没有模糊空间。
-
门控评分:一种决策规则:必要条件(所有必对项通过)必须先满足,然后才给分。这与基于平均的指标截然不同——高总分无法补偿单一灾难性错误。实践中,门控评分发现许多模型在CIDEr上得90+,但在某些图像上直接跌到0——暴露了传统指标掩盖的脆弱性。
-
循环同行评议共识:用于构建高质量黄金标题的管道。不是单个标注员,而是多位标注员(人类或模型)生成初始标题,然后互相评审对方的版本,再修改,重复直到达成一致。这样产生的标题比单来源的更加可靠、偏差更小。细目就是从这些达成共识的黄金标题中提取的。
框架转变
之前:
[图像 + 标题] --> [相似度模型 (CLIP/GPT)] --> [单个浮点数分数]
(一个数字,无从追溯具体检查了哪些事实。)
之后:
[图像 + 标题] --> [带黄金答案的细目检查表]
                        |-> 必对项 {全部通过?}    (二值判断)
                        |-> 易错项 {正确数?}     (部分累积)
                        |-> 门控:必对项失败 => 0
                        -> 最终分数 (可解释、可审计)
从一个不透明分数变成带有关键性门控的原子事实审计轨迹。
专家评审
选题眼光: 真实且及时。已有基准的饱和是公认问题;这篇论文精准打击了密集场景的失败案例,正是模型现在碰到的瓶颈。它在领域的轨迹上恰好处于从“能不能回答”转向“是否真的看到了”的位置。
方法成熟度: 巧妙的混合方法——结合人工标注与算法规则。循环同行评议管道虽不简单,但动机明确。扩展到数千张图像是合理的。更简单的方案(例如随机采样几个事实点)会错过“信息密集”的要求,因此复杂性是正当的。
实验诚意: 基线覆盖了近期VLM(LLaVA、InternVL、GPT-4V)和标准指标(CIDEr、CLIPScore)。开源与闭源之间8%的感知缺陷差距显著且一致。一个担忧:细目由同一团队构建,他们也自己来评估——可能存在无意识的挑选。但论文报告了标注者之间的一致性,所以不是致命缺陷。
写作功力: 结构清晰,但“循环同行评议”部分缺少具体实例。如果能加入一个示例展示三轮评审及分歧如何解决,方法会更容易复现。
判决: 弱接收 —— 核心想法(原子审计+门控)可发表且有用,但规模(1038张图像)和人工努力限制了即时采用。如果细目数据库能扩大,这个指标本身可能成为标准评估工具。
要点总结
- 将门控评分用于任何事实核查任务 —— 例如文本摘要中,如果摘要必须包含某个关键实体(必对项),缺失则整篇摘要判零分。
- 将评估分解为原子项使得模型失败透明 —— 可以精确调试模型漏掉了哪个视觉事实。
- 循环同行评议方法作为真值构建方法可迁移到任何标注任务 —— 减少偏差,提高共识质量。