Paper: 2603.13176 Authors: Dingcheng Huang, Xiaotong Zhang, Kamal Youcef-Toumi Categories: cs.CV
The Gap
Existing human-robot collaboration systems run multiple perception modules (vision, audio, context) in parallel on every single frame. This works fine when you’re processing recorded video offline, but in real-time streaming scenarios, it’s like trying to drink from a fire hose—the latency accumulates until your robot is responding to a world that’s already changed. Prior work introduced the concept of “Relevance” for scene understanding, but the field still lacks a systematic way to decide which perception modules actually need to run on which frames.
Problem: Parallel perception pipeline
   |
   v
Observation: Not everything changes every frame (information sparsity)
   |
   v
Method: Relevance-driven scheduler estimates module necessity
   |
   v
Evidence: 27.52% latency reduction, 72.73% recall improvement
   |
   v
Conclusion: Selective activation beats always-on execution
The Increment
One sentence: Before this paper, robots ran all perception modules on every frame and suffered latency; after, they selectively activate modules based on scene context and achieve real-time performance.
Core Mechanism
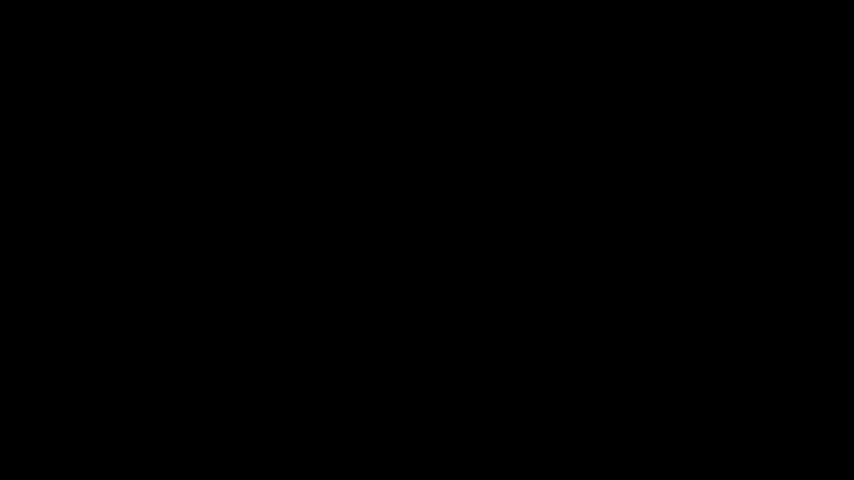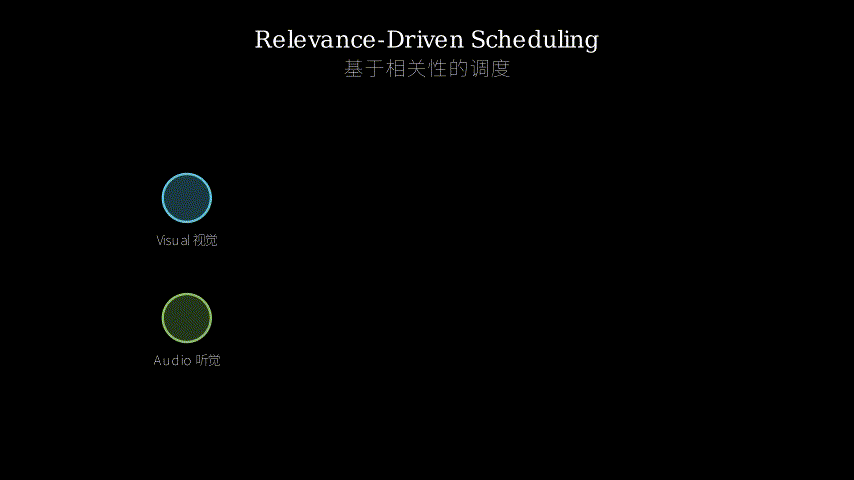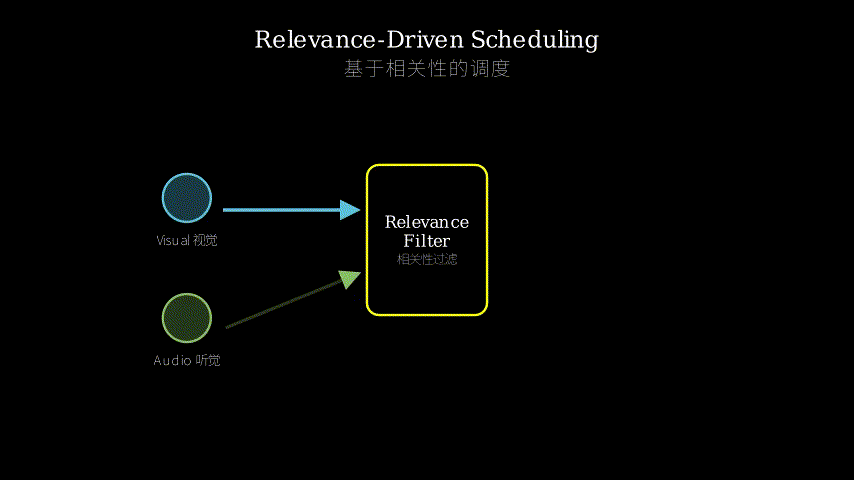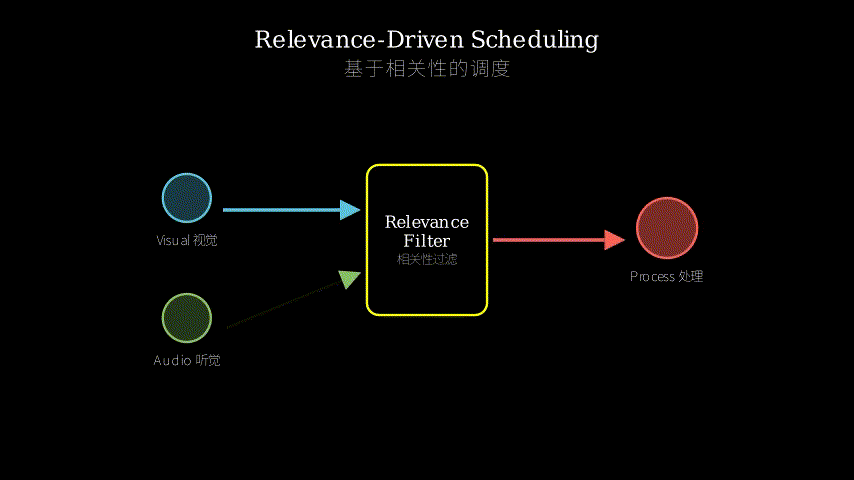
The framework operates in three stages. First, it analyzes outputs from the previous frame to understand what just happened in the scene. Second, it estimates which perception modules are actually necessary for the current frame based on scene context—if nothing’s moving, maybe you don’t need to run pose estimation. Third, it schedules only the necessary modules to execute, saving computational resources where they’re not needed.
The key insight is leveraging information sparsity in HRC events. In a typical human-robot collaboration scenario, most frames are similar to their predecessors. A person might be standing still, or moving slowly, or the robot might be waiting. The framework exploits this temporal coherence: instead of treating every frame as a blank slate requiring full perception, it treats each frame as a small delta from the previous one.
Frame t-1 outputs
   |
   v
[Context Analyzer] ---> Scene state estimate
   |                           |
   v                           v
[Necessity Estimator] <--- Historical patterns
   |
   v
Module activation decisions
   |
   +---> [Vision module] (if needed)
   +---> [Audio module] (if needed)
   +---> [Pose module] (if needed)
   |
   v
Frame t outputs ---> Feed to next frame
Think of it like a restaurant kitchen during dinner service. In a traditional setup (parallel pipeline), every chef is working on every dish that comes in—the sauté chef, the grill chef, the pastry chef all jump into action for each order. This creates chaos and delays. The head chef (scheduler) in this paper’s approach looks at each order and decides: “This is just a salad, we only need the cold station. This is a steak, activate grill and sauté. This is a repeat of table 5’s order from 2 minutes ago, we can optimize the prep.” The head chef uses knowledge of what just went out (previous frame), what’s typical for this time of night (scene context), and what’s actually on the order (necessity estimation) to activate only the relevant stations. The result: faster service, less wasted effort, and the kitchen doesn’t fall behind.
Key Concepts
-
Streaming Perception: Unlike offline video analysis where you can take your time processing each frame, streaming perception means you’re racing against the clock—new frames keep arriving whether you’re done with the previous one or not. If your perception pipeline takes 100ms but frames arrive every 33ms (30 fps), you’re accumulating a 67ms debt every frame. This debt manifests as latency: by the time your robot “sees” something and reacts, the world has moved on. The challenge is maintaining perception quality while keeping latency low enough that your robot’s actions remain relevant to the current state of the world, not the state from 500ms ago.
-
Relevance: Borrowed from prior work in scene understanding, this concept captures which aspects of a scene actually matter for the task at hand. Not every pixel needs equal attention. If a robot is helping someone assemble furniture, the person’s hand pose is highly relevant, but the pattern on their shirt is not. The framework uses this to prioritize computational resources—run expensive modules only when they’re likely to provide relevant information. It’s the difference between a security guard watching every camera feed simultaneously versus having a smart system that highlights feeds where something interesting is happening.
-
Information Sparsity in HRC Events: Human-robot collaboration isn’t a continuous stream of novel information—it’s punctuated by key moments separated by relative stability. A person reaches for a tool (keyframe), then moves it slowly (incremental changes), then holds it steady while working (minimal change). The framework exploits this sparsity: most frames can be handled with lightweight updates rather than full perception. It’s like how video compression works—you don’t need to encode every pixel of every frame when most of the scene stays the same.
Framework Shift
Before (parallel pipeline):          After (relevance-driven):

Frame --> [Vision]                   Frame --> [Scheduler]
      |-> [Audio]                            |
      |-> [Pose]                             +-> [Vision] (if relevant)
      |-> [Context]                          +-> [Audio] (if relevant)
      |                                      +-> [Pose] (if relevant)
      v                                      |
   All outputs                               v
   (high latency)                         Selected outputs
                                          (low latency)

Every module runs                        Modules run on demand
on every frame                           based on scene context
From “always-on perception” to “context-aware activation,” the core shift is treating perception as a resource allocation problem rather than a fixed pipeline.
Expert Assessment
Problem choice: This is a real gap, not manufactured. Streaming perception latency is a genuine bottleneck in robotics deployment, and the field has been stuck in the “throw more compute at it” paradigm. The problem sits at a practical inflection point—robots are moving from labs to real-world HRC scenarios where latency matters.
Method maturity: The approach is pragmatic rather than revolutionary. It’s essentially applying scheduling heuristics to perception pipelines, which isn’t conceptually novel, but the execution appears solid. The “Relevance” concept from prior work provides theoretical grounding. I’d like to see more detail on how the necessity estimator actually works—is it learned, rule-based, or hybrid? The paper could be more explicit about this.
Experimental integrity: The 27.52% latency reduction is meaningful but not dramatic. The 72.73% improvement in MMPose activation recall is more impressive, though I’m curious about the baseline—was the parallel pipeline missing poses due to latency, or is this measuring something else? The 98% keyframe accuracy is good but raises a question: what happens in the 2% of cases where it misses a keyframe? In HRC, missing a critical moment could be catastrophic. The paper would benefit from failure case analysis.
Writing quality: The abstract is clear, but I suspect the method section might be where things get hand-wavy. Papers in this space often gloss over the “how do we actually estimate necessity” part with vague references to “learning-based approaches.” If the authors spent more time on concrete implementation details and less on motivation, the paper would be stronger.
Verdict: weak accept — Addresses a real problem with a practical solution and shows meaningful improvements, but the novelty is incremental and the evaluation could be more thorough.
Takeaways
The core idea transfers well beyond robotics: anytime you have multiple expensive operations that don’t all need to run on every input, consider a lightweight scheduler that estimates necessity. This pattern applies to video analytics pipelines, real-time monitoring systems, and even web services with multiple microservices. The specific technique of using previous outputs to inform current scheduling decisions is simple but effective—you’re essentially building a cheap predictor that saves expensive computation. The 98% keyframe accuracy suggests that for many applications, you can safely skip processing on “boring” frames without missing important events. If you’re building any real-time perception system, steal the idea of separating “keyframe detection” (cheap) from “full perception” (expensive).
论文: 2603.13176 作者: Dingcheng Huang, Xiaotong Zhang, Kamal Youcef-Toumi 分类: cs.CV
缺口
现有的人机协作系统在每一帧上并行运行多个感知模块(视觉、音频、上下文)。
这在离线处理录制视频时没问题,但在实时流场景中,就像试图从消防水管喝水——延迟不断累积,直到你的机器人响应的是一个已经改变的世界。
先前的工作为场景理解引入了”相关性”概念,但该领域仍然缺乏一种系统化的方法来决定哪些感知模块实际上需要在哪些帧上运行。
问题:并行感知管道
   |
   v
观察:并非每帧都有变化(信息稀疏性)
   |
   v
方法:相关性驱动的调度器估计模块必要性
   |
   v
证据:延迟降低27.52%,召回率提升72.73%
   |
   v
结论:选择性激活优于常开执行
增量
一句话: 这篇论文之前,机器人在每帧上运行所有感知模块并遭受延迟;之后,它们根据场景上下文选择性激活模块并实现实时性能。
核心机制
该框架分三个阶段运作。
首先,它分析前一帧的输出以理解场景中刚刚发生了什么。
其次,它根据场景上下文估计当前帧实际需要哪些感知模块——如果没有东西在移动,也许你不需要运行姿态估计。
第三,它只调度必要的模块执行,在不需要的地方节省计算资源。
关键洞察是利用人机协作事件中的信息稀疏性。
在典型的人机协作场景中,大多数帧与其前一帧相似。
一个人可能站着不动,或缓慢移动,或机器人可能在等待。
该框架利用这种时间连贯性:不是将每一帧视为需要完整感知的白板,而是将每一帧视为与前一帧的小增量。
t-1帧输出
   |
   v
[上下文分析器] ---> 场景状态估计
   |                      |
   v                      v
[必要性估计器] <--- 历史模式
   |
   v
模块激活决策
   |
   +---> [视觉模块](如需要)
   +---> [音频模块](如需要)
   +---> [姿态模块](如需要)
   |
   v
t帧输出 ---> 传递给下一帧
把它想象成晚餐服务期间的餐厅厨房。
在传统设置(并行管道)中,每个厨师都在处理每道进来的菜——煎炒厨师、烧烤厨师、糕点厨师都为每个订单跳入行动。
这造成混乱和延迟。
本文方法中的主厨(调度器)查看每个订单并决定:“这只是沙拉,我们只需要冷菜台。
这是牛排,激活烧烤和煎炒。
这是5号桌2分钟前订单的重复,我们可以优化准备。
“主厨使用刚刚送出的知识(前一帧)、这个时间段的典型情况(场景上下文)以及订单上实际有什么(必要性估计)来只激活相关的工作站。
结果:更快的服务,更少的浪费,厨房不会落后。
关键概念
- 流式感知: 与离线视频分析不同(你可以慢慢处理每一帧),流式感知意味着你在与时钟赛跑——无论你是否完成前一帧,新帧都会不断到来。
如果你的感知管道需要100毫秒但帧每33毫秒到达一次(30 fps),你每帧都在累积67毫秒的债务。
这种债务表现为延迟:当你的机器人”看到”某物并做出反应时,世界已经改变了。
挑战在于保持感知质量的同时将延迟保持在足够低的水平,使机器人的行动与世界的当前状态相关,而不是500毫秒前的状态。
- 相关性: 从场景理解的先前工作中借用,这个概念捕捉场景的哪些方面对手头任务真正重要。
并非每个像素都需要同等关注。
如果机器人正在帮助某人组装家具,那个人的手部姿态高度相关,但他们衬衫上的图案则不相关。
该框架使用这一点来优先分配计算资源——只有在昂贵的模块可能提供相关信息时才运行它们。
这就像保安同时观看每个摄像头画面与拥有一个智能系统突出显示有趣事情发生的画面之间的区别。
- 人机协作事件中的信息稀疏性: 人机协作不是连续的新信息流——它是由相对稳定分隔的关键时刻组成的。
一个人伸手拿工具(关键帧),然后缓慢移动它(增量变化),然后在工作时稳定握住它(最小变化)。
该框架利用这种稀疏性:大多数帧可以用轻量级更新而不是完整感知来处理。
这就像视频压缩的工作原理——当场景的大部分保持不变时,你不需要编码每一帧的每个像素。
框架转变
之前(并行管道):              之后(相关性驱动):

帧 --> [视觉]                   帧 --> [调度器]
   |-> [音频]                          |
   |-> [姿态]                          +-> [视觉](如相关)
   |-> [上下文]                        +-> [音频](如相关)
   |                                   +-> [姿态](如相关)
   v                                   |
所有输出                               v
(高延迟)                          选定输出
                                   (低延迟)

每个模块在                          模块根据场景上下文
每帧上运行                          按需运行
从”常开感知”到”上下文感知激活”,核心转变是将感知视为资源分配问题而不是固定管道。
专家评审
选题眼光: 这是真实的缺口,不是人造的。
流式感知延迟是机器人部署中的真正瓶颈,该领域一直陷入”投入更多计算”的范式。
这个问题处于实际的拐点——机器人正在从实验室转向延迟重要的真实世界人机协作场景。
方法成熟度: 该方法务实而非革命性。
它本质上是将调度启发式应用于感知管道,这在概念上并不新颖,但执行似乎扎实。
先前工作的”相关性”概念提供了理论基础。
我想看到更多关于必要性估计器实际如何工作的细节——它是学习的、基于规则的,还是混合的?论文可以对此更明确。
实验诚意: 27.52%的延迟降低是有意义的但不戏剧性。
72.73%的MMPose激活召回率提升更令人印象深刻,尽管我好奇基线是什么——并行管道是因为延迟而错过姿态,还是这在测量其他东西?98%的关键帧准确率很好,但引发一个问题:在错过关键帧的2%情况下会发生什么?在人机协作中,错过关键时刻可能是灾难性的。
论文将受益于失败案例分析。
写作功力: 摘要清晰,但我怀疑方法部分可能是事情变得含糊的地方。
这个领域的论文经常用对”基于学习的方法”的模糊引用来掩盖”我们实际如何估计必要性”部分。
如果作者在具体实现细节上花更多时间,在动机上花更少时间,论文会更强。
判决: 弱接收 — 用实用解决方案解决真实问题并显示有意义的改进,但新颖性是增量的,评估可以更彻底。
要点总结
核心思想很好地迁移到机器人之外:任何时候你有多个昂贵的操作不需要在每个输入上都运行,考虑一个估计必要性的轻量级调度器。
这种模式适用于视频分析管道、实时监控系统,甚至具有多个微服务的Web服务。
使用先前输出来通知当前调度决策的具体技术简单但有效——你本质上是在构建一个廉价的预测器来节省昂贵的计算。
98%的关键帧准确率表明,对于许多应用,你可以安全地跳过”无聊”帧的处理而不会错过重要事件。
如果你正在构建任何实时感知系统,偷走将”关键帧检测”(廉价)与”完整感知”(昂贵)分离的想法。