Paper: 2605.28819 Authors: Yangyi Huang, Ruotian Peng, Zeju Qiu, Jiale Kang, Yandong Wen, Bernhard Schölkopf, Weiyang Liu Categories: cs.LG, cs.CL
The Gap
The field has embraced parameter-efficient finetuning (PEFT) methods like LoRA, adapters, and prefix tuning as the standard for adapting large language models. Evaluations focus almost exclusively on downstream task accuracy—does the model solve the target task better? But there’s a blind spot: nobody systematically measures what the model forgets during finetuning. The pretrained model arrives with broad capabilities (reasoning, world knowledge, instruction following). After PEFT, it might ace your sentiment classification task but lose the ability to write coherent essays or answer factual questions.
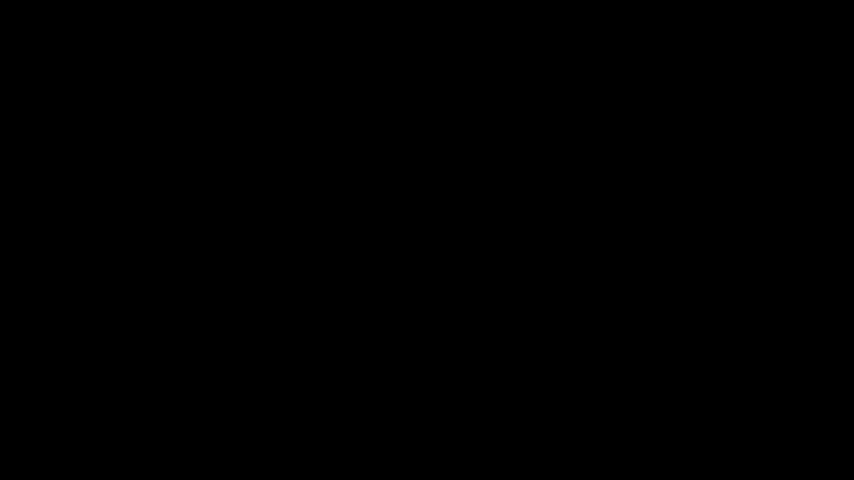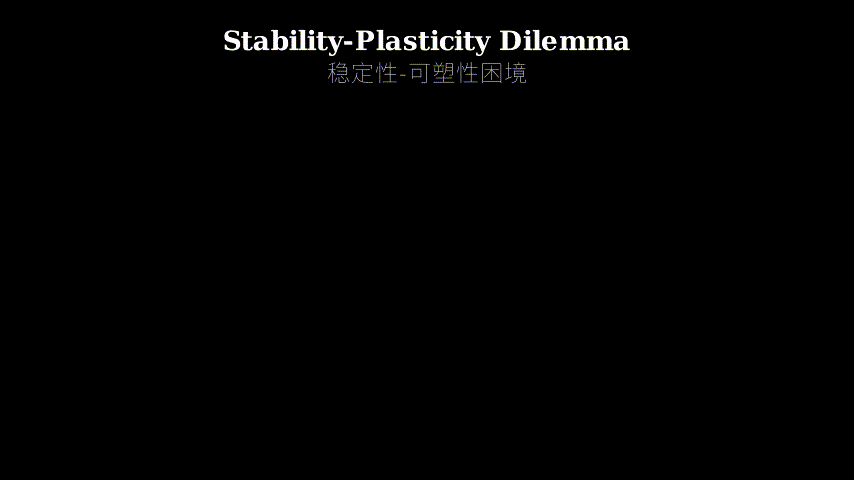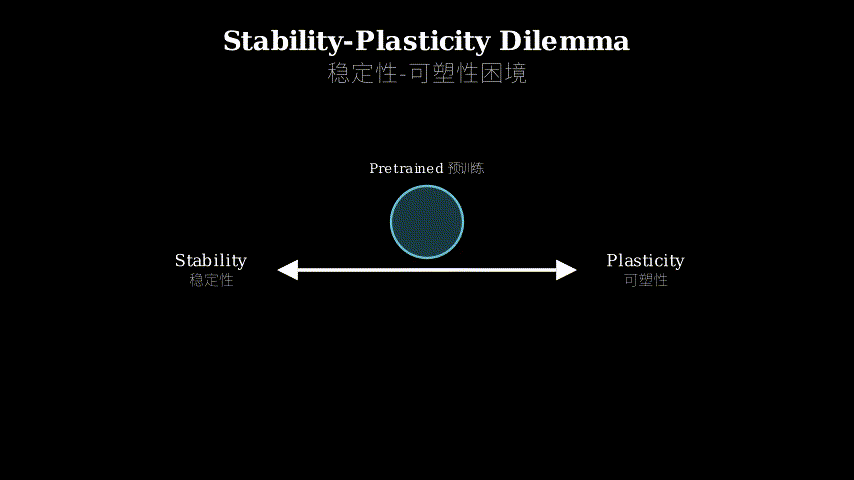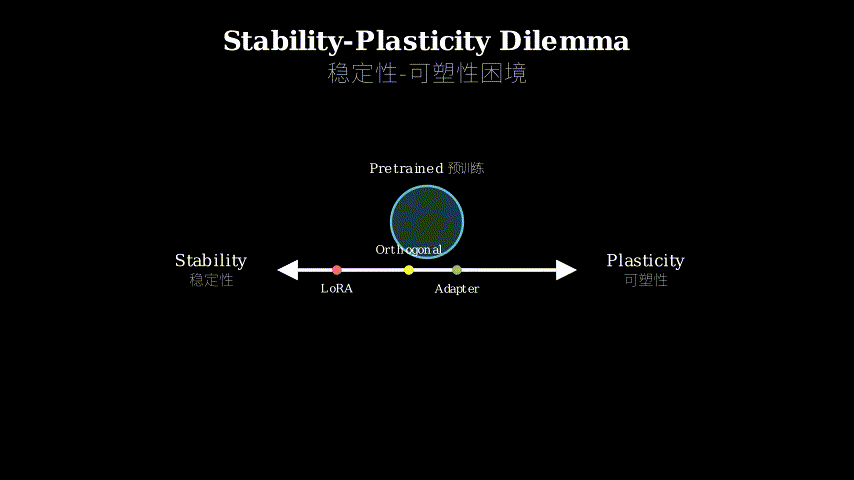
Prior work treats PEFT as a pure optimization problem: minimize task loss under parameter constraints. This paper reframes it as a stability-plasticity dilemma—the classic neuroscience trade-off between learning new information (plasticity) and retaining old knowledge (stability). Existing benchmarks don’t measure this trade-off, so we can’t tell which PEFT methods are actually better at balancing adaptation and retention.
Problem: PEFT evaluated only on task accuracy
   |
   v
Observation: Models forget pretrained capabilities
   |
   v
Hypothesis: PEFT methods differ in stability-plasticity profiles
   |
   v
Method: PEFT-Arena benchmark (task perf + retention metrics)
   |
   v
Evidence: Orthogonal finetuning dominates Pareto frontier
   |
   v
Analysis: Geometric view explains why (weight/activation space)
   |
   v
Conclusion: Retention matters; current checkpoints overshoot
The Increment
One sentence: Before this paper, PEFT was evaluated on task accuracy alone; after, we have a benchmark and geometric framework showing that orthogonal methods retain pretrained capabilities better, and that standard training often overshoots the optimal stability-plasticity operating point.
Core Mechanism
PEFT-Arena is a dual-axis benchmark. On one axis, it measures downstream task performance (the usual metric). On the other, it measures general capability retention across multiple dimensions: instruction following, world knowledge, reasoning, and safety alignment. For each PEFT method (LoRA, adapters, prefix tuning, orthogonal finetuning, etc.), the benchmark produces a stability-plasticity profile—a curve showing how task performance trades off against capability retention as you vary hyperparameters like learning rate or rank.
The analysis operates in two geometric spaces. In weight space, the authors decompose PEFT updates using singular value decomposition (SVD) of the pretrained weight matrices. They show that different PEFT parameterizations interact differently with the pretrained singular value structure—some methods align updates with top singular vectors (high forgetting), others spread updates orthogonally (low forgetting). In activation space, they track how finetuning distorts the representations of general-capability inputs. Forgetting correlates with non-isometric distortion: when the geometry of activation space gets warped, the model loses its ability to process inputs it previously handled well.
Input: Pretrained LLM + PEFT method + target task
   |
   v
[PEFT-Arena Benchmark]
   |
   +---> Task Performance (accuracy, F1, etc.)
   |
   +---> Retention Metrics:
         - Instruction following (IFEval)
         - World knowledge (MMLU)
         - Reasoning (GSM8K, BBH)
         - Safety (ToxiGen)
   |
   v
Stability-Plasticity Profile (Pareto curve)
   |
   v
[Geometric Analysis]
   |
   +---> Weight Space: SVD decomposition
   |     (How updates interact with pretrained structure)
   |
   +---> Activation Space: Representation distortion
         (Isometry preservation vs. forgetting)
   |
   v
Insight: Orthogonal methods dominate; checkpoints overshoot
Think of PEFT like renovating a house. The pretrained model is a fully furnished home with plumbing, electricity, and structural integrity. Your target task is adding a new room (say, a home office). Different PEFT methods are different renovation strategies:
- LoRA is like adding furniture and decorations to existing rooms—you’re modifying the space without changing the walls, but you might block doorways or cover up outlets (forgetting).
- Adapters are like building a small addition that connects to the main house—the new room is separate, but you still need to route utilities through the existing structure.
- Orthogonal finetuning is like building the new room on stilts above the house—it doesn’t touch the foundation or interfere with existing rooms. The plumbing and wiring stay intact.
The benchmark measures two things: how well the new room works (task performance) and whether the rest of the house still functions (retention). The geometric analysis is like hiring a structural engineer to explain why some renovation strategies damage the foundation while others don’t. Weight space analysis checks if you’re drilling into load-bearing walls (top singular vectors). Activation space analysis checks if the flow of people and utilities through the house (representations) is still smooth or now has bottlenecks and detours (non-isometric distortion).
Key Concepts
-
Stability-Plasticity Dilemma: In neuroscience, this is the trade-off between learning new information and retaining old memories. A perfectly plastic system learns everything instantly but forgets everything just as fast. A perfectly stable system never forgets but can’t learn anything new. Real brains—and now, we argue, PEFT methods—must balance these extremes. In the PEFT context, plasticity is how quickly the model adapts to the target task, and stability is how well it retains pretrained capabilities like reasoning or world knowledge. The dilemma is that most optimization pressures push toward plasticity (lower task loss) at the expense of stability (forgetting). A good PEFT method should reach high task performance without catastrophic retention loss—it should sit on the Pareto frontier of this trade-off.
-
Orthogonal Finetuning: Standard finetuning updates weights in whatever direction reduces task loss fastest. Orthogonal finetuning constrains updates to be orthogonal to the top singular vectors of the pretrained weight matrices. Why does this help? Pretrained weights have structure: the top singular vectors capture the most important patterns learned during pretraining (general language understanding, world knowledge). If you update along these directions, you’re overwriting that structure—forgetting. If you update orthogonally, you’re adding new information in “unused” dimensions, leaving the pretrained structure intact. It’s like writing in the margins of a book instead of crossing out the text. The method requires computing SVD of weight matrices and projecting gradient updates onto the orthogonal subspace, which adds computational cost but yields better retention.
-
Non-Isometric Representation Distortion: An isometry is a transformation that preserves distances and angles—like rotating or translating an object without stretching or squashing it. In activation space, each input produces a representation (a point in high-dimensional space). If finetuning is isometric, it moves these points around but preserves their relative geometry—inputs that were similar before are still similar after. Non-isometric distortion warps the space: some regions get compressed, others stretched. The paper shows that forgetting correlates with this distortion. When general-capability inputs (e.g., reasoning questions) land in distorted regions, the model can’t process them correctly anymore. Retention requires keeping the activation geometry roughly isometric for non-task inputs. Orthogonal methods achieve this by constraining weight updates to preserve the pretrained representation structure.
Framework Shift
Before (mainstream approach):        After (this paper):

PEFT Method                          PEFT Method
    |                                    |
    v                                    v
Optimize Task Loss                   Optimize Task Loss
    |                                    |
    v                                    +---> Measure Retention
Evaluate Task Accuracy                   |
    |                                    v
    v                                Stability-Plasticity Profile
Done                                     |
                                         +---> Geometric Analysis
                                         |     (Weight + Activation Space)
                                         v
                                     Understand Trade-offs
                                         |
                                         v
                                     Improve Operating Point
From single-axis evaluation (task accuracy) to dual-axis evaluation (task accuracy + retention), the core shift is recognizing that PEFT is not just an optimization problem but a knowledge preservation problem.
Expert Assessment
Problem choice: This is a real gap. The field has been flying blind—optimizing for task performance without measuring what’s lost. The stability-plasticity framing is borrowed from neuroscience, but the application to PEFT is novel and well-motivated. It sits at a critical juncture: as models get larger and more capable, preserving pretrained knowledge becomes more important, not less. The problem will only grow in relevance.
Method maturity: The benchmark design is solid—multiple retention dimensions, diverse tasks, fair comparisons. The geometric analysis is where the paper shines. Connecting forgetting to singular value structure and representation distortion is insightful, not just empirical pattern-matching. However, the orthogonal finetuning method itself isn’t new (prior work exists); the contribution is showing *why it works better through the geometric lens. The path-wise rewinding idea (rolling back to earlier checkpoints) is clever but underdeveloped—it’s a case study, not a full method.
Experimental integrity: Baselines are fair and comprehensive (LoRA, adapters, prefix tuning, full finetuning, orthogonal variants). The retention metrics span multiple capability dimensions, which is thorough. One concern: the tasks are mostly NLP benchmarks (sentiment analysis, NLI, QA). It’s unclear if the findings generalize to other domains like code generation or multimodal tasks. The Pareto frontier analysis is convincing, but the paper doesn’t deeply explore *why some tasks cause more forgetting than others—task characteristics matter, and that’s left underexplored.
Writing quality: The paper is dense but well-structured. The geometric analysis sections (weight space, activation space) are the hardest to parse—more intuitive explanations or visualizations would help. The related work section is thorough but could be trimmed; the space would be better spent on deeper ablations (e.g., how does retention vary with task difficulty or dataset size?). The path-wise rewinding section feels tacked on—it’s interesting but doesn’t integrate cleanly with the rest of the narrative.
Verdict: Strong accept — This paper reframes PEFT evaluation in a way that will influence how the community thinks about finetuning. The benchmark is immediately useful, and the geometric analysis provides actionable insights. It’s not perfect (some ideas are underdeveloped, generalization is unclear), but the core contribution is strong enough to shift the conversation.
Takeaways
-
Evaluate retention, not just task performance: If you’re deploying a finetuned model, test it on general-capability benchmarks (MMLU, GSM8K, instruction following) before and after finetuning. If retention drops significantly, you’ve overfit to the task at the expense of broader utility.
-
Orthogonal finetuning is underused: If you care about retention, try orthogonal methods (e.g., OFT, BOFT). They’re more expensive (SVD computation), but the retention gains are real. For production systems where pretrained capabilities matter, the cost is worth it.
-
Checkpoints overshoot: Standard training runs until task performance plateaus, but the paper shows that earlier checkpoints often have better retention with only slightly worse task performance. Try early stopping based on a retention metric, or use path-wise rewinding to roll back to a better operating point.
-
Geometric intuition transfers: The idea that updates aligned with top singular vectors cause forgetting applies beyond PEFT. If you’re doing any kind of finetuning or continual learning, think about how your updates interact with the pretrained structure. Orthogonality is a general principle for preserving prior knowledge.
-
Stability-plasticity is a design axis: When designing PEFT methods, explicitly consider the trade-off. Don’t just minimize task loss—add a retention term to the objective, or constrain updates to preserve pretrained geometry. The field has been optimizing for plasticity alone; there’s low-hanging fruit in balancing it with stability.
论文: 2605.28819 作者: Yangyi Huang, Ruotian Peng, Zeju Qiu, Jiale Kang, Yandong Wen, Bernhard Schölkopf, Weiyang Liu 分类: cs.LG, cs.CL
缺口
业界已经把参数高效微调(PEFT)方法——比如 LoRA、适配器、前缀调优——当作适配大语言模型的标准做法。
评估几乎只关注下游任务准确率:模型在目标任务上表现更好了吗?
但有个盲区:没人系统地测量模型在微调过程中遗忘了什么。
预训练模型带着广泛的能力(推理、世界知识、指令遵循)到来。
微调之后,它可能在你的情感分类任务上表现完美,但失去了写连贯文章或回答事实问题的能力。
先前工作把 PEFT 当作纯优化问题:在参数约束下最小化任务损失。
本文将其重新定义为稳定性-可塑性困境——神经科学中学习新信息(可塑性)与保留旧知识(稳定性)之间的经典权衡。
现有基准不测量这种权衡,所以我们无法判断哪些 PEFT 方法真正更擅长平衡适应与保持。
问题:PEFT 只用任务准确率评估
   |
   v
观察:模型遗忘预训练能力
   |
   v
假设:PEFT 方法的稳定性-可塑性特征不同
   |
   v
方法:PEFT-Arena 基准(任务性能 + 保持指标)
   |
   v
证据:正交微调主导帕累托前沿
   |
   v
分析:几何视角解释原因(权重/激活空间)
   |
   v
结论:保持很重要;当前检查点过冲
增量
一句话:这篇论文之前,PEFT 只用任务准确率评估;之后,我们有了一个基准和几何框架,显示正交方法更好地保留预训练能力,且标准训练常常过冲最优稳定性-可塑性操作点。
核心机制
PEFT-Arena 是一个双轴基准。
一个轴测量下游任务性能(常规指标)。
另一个轴测量通用能力保持,跨多个维度:指令遵循、世界知识、推理、安全对齐。
对每个 PEFT 方法(LoRA、适配器、前缀调优、正交微调等),基准生成一个稳定性-可塑性轮廓——一条曲线,显示当你改变超参数(如学习率或秩)时,任务性能如何与能力保持权衡。
分析在两个几何空间中进行。
在权重空间,作者用预训练权重矩阵的奇异值分解(SVD)分解 PEFT 更新。
他们展示不同 PEFT 参数化与预训练奇异值结构的交互方式不同——有些方法将更新对齐到顶部奇异向量(高遗忘),其他方法正交地分散更新(低遗忘)。
在激活空间,他们跟踪微调如何扭曲通用能力输入的表示。
遗忘与非等距扭曲相关:当激活空间的几何被扭曲时,模型失去处理它以前能处理的输入的能力。
输入:预训练 LLM + PEFT 方法 + 目标任务
   |
   v
[PEFT-Arena 基准]
   |
   +---> 任务性能(准确率、F1 等)
   |
   +---> 保持指标:
         - 指令遵循(IFEval)
         - 世界知识(MMLU)
         - 推理(GSM8K、BBH)
         - 安全(ToxiGen)
   |
   v
稳定性-可塑性轮廓(帕累托曲线)
   |
   v
[几何分析]
   |
   +---> 权重空间:SVD 分解
   |     (更新如何与预训练结构交互)
   |
   +---> 激活空间:表示扭曲
         (等距保持 vs. 遗忘)
   |
   v
洞察:正交方法主导;检查点过冲
把 PEFT 想象成翻新房子。
预训练模型是一个配备齐全的家,有管道、电力和结构完整性。
你的目标任务是增加一个新房间(比如家庭办公室)。
不同的 PEFT 方法是不同的翻新策略:
-
LoRA 就像在现有房间里添加家具和装饰——你在修改空间而不改变墙壁,但你可能会堵住门道或盖住插座(遗忘)。
-
适配器就像建一个连接到主屋的小扩建——新房间是独立的,但你仍然需要通过现有结构布线。
-
正交微调就像在房子上方用高跷建新房间——它不触及地基或干扰现有房间。
管道和布线保持完好。
基准测量两件事:新房间工作得如何(任务性能)以及房子的其余部分是否仍然运作(保持)。
几何分析就像雇一个结构工程师来解释为什么某些翻新策略会损坏地基而其他策略不会。
权重空间分析检查你是否在钻承重墙(顶部奇异向量)。
激活空间分析检查人和公用设施通过房子的流动(表示)是否仍然顺畅,还是现在有瓶颈和绕道(非等距扭曲)。
关键概念
- 稳定性-可塑性困境:在神经科学中,这是学习新信息与保留旧记忆之间的权衡。
完全可塑的系统立即学习一切,但也同样快地遗忘一切。
完全稳定的系统永不遗忘,但无法学习任何新东西。
真实的大脑——现在我们认为 PEFT 方法也是——必须平衡这些极端。
在 PEFT 语境中,可塑性是模型适应目标任务的速度,稳定性是它保留预训练能力(如推理或世界知识)的程度。
困境在于大多数优化压力推向可塑性(更低的任务损失),以牺牲稳定性(遗忘)为代价。
好的 PEFT 方法应该在不造成灾难性保持损失的情况下达到高任务性能——它应该位于这种权衡的帕累托前沿上。
- 正交微调:标准微调沿着最快降低任务损失的方向更新权重。
正交微调约束更新与预训练权重矩阵的顶部奇异向量正交。
为什么这有帮助?
预训练权重有结构:顶部奇异向量捕获预训练期间学到的最重要模式(通用语言理解、世界知识)。
如果你沿着这些方向更新,你就在覆盖那个结构——遗忘。
如果你正交更新,你就在”未使用”的维度中添加新信息,保持预训练结构完整。
这就像在书的边缘写字而不是划掉文本。
该方法需要计算权重矩阵的 SVD 并将梯度更新投影到正交子空间,这增加了计算成本,但产生更好的保持。
- 非等距表示扭曲:等距是一种保持距离和角度的变换——就像旋转或平移物体而不拉伸或压扁它。
在激活空间中,每个输入产生一个表示(高维空间中的一个点)。
如果微调是等距的,它移动这些点但保持它们的相对几何——之前相似的输入之后仍然相似。
非等距扭曲使空间变形:某些区域被压缩,其他区域被拉伸。
论文显示遗忘与这种扭曲相关。
当通用能力输入(例如推理问题)落在扭曲区域时,模型无法再正确处理它们。
保持需要为非任务输入保持激活几何大致等距。
正交方法通过约束权重更新以保持预训练表示结构来实现这一点。
框架转变
之前(主流方法):                之后(本文方法):

PEFT 方法                         PEFT 方法
    |                                 |
    v                                 v
优化任务损失                       优化任务损失
    |                                 |
    v                                 +---> 测量保持
评估任务准确率                        |
    |                                 v
    v                             稳定性-可塑性轮廓
完成                                  |
                                      +---> 几何分析
                                      |     (权重 + 激活空间)
                                      v
                                  理解权衡
                                      |
                                      v
                                  改进操作点
从单轴评估(任务准确率)到双轴评估(任务准确率 + 保持),核心转变是认识到 PEFT 不仅是优化问题,而且是知识保存问题。
专家评审
选题眼光:这是真缺口。
业界一直在盲飞——优化任务性能而不测量损失了什么。
稳定性-可塑性框架借自神经科学,但应用到 PEFT 是新颖且动机充分的。
它处于关键节点:随着模型变得更大更有能力,保留预训练知识变得更重要,而不是更不重要。
这个问题只会越来越相关。
方法成熟度:基准设计扎实——多个保持维度、多样化任务、公平比较。
几何分析是论文的亮点。
将遗忘与奇异值结构和表示扭曲联系起来是有洞察力的,不仅仅是经验模式匹配。
然而,正交微调方法本身并不新(先前工作存在);贡献在于通过几何视角展示为什么它工作得更好。
路径回退想法(回滚到早期检查点)很聪明但欠发达——它是案例研究,不是完整方法。
实验诚意:基线公平且全面(LoRA、适配器、前缀调优、全微调、正交变体)。
保持指标跨越多个能力维度,这很彻底。
一个担忧:任务主要是 NLP 基准(情感分析、NLI、QA)。
不清楚发现是否推广到其他领域,如代码生成或多模态任务。
帕累托前沿分析令人信服,但论文没有深入探索为什么某些任务比其他任务造成更多遗忘——任务特征很重要,这被留下未探索。
写作功力:论文密集但结构良好。
几何分析部分(权重空间、激活空间)最难解析——更直观的解释或可视化会有帮助。
相关工作部分彻底但可以修剪;空间最好花在更深的消融上(例如,保持如何随任务难度或数据集大小变化?)。
路径回退部分感觉是附加的——它很有趣,但与叙述的其余部分整合得不够干净。
判决:强接收 — 这篇论文以一种将影响社区如何思考微调的方式重新定义了 PEFT 评估。
基准立即有用,几何分析提供可操作的洞察。
它不完美(一些想法欠发达,泛化不清楚),但核心贡献足够强大,可以转变对话。
要点总结
- 评估保持,不仅仅是任务性能:如果你在部署微调模型,在微调前后在通用能力基准(MMLU、GSM8K、指令遵循)上测试它。
如果保持显著下降,你已经过拟合到任务,以牺牲更广泛的效用为代价。
- 正交微调被低估:如果你关心保持,尝试正交方法(例如 OFT、BOFT)。
它们更昂贵(SVD 计算),但保持收益是真实的。
对于预训练能力重要的生产系统,成本是值得的。
- 检查点过冲:标准训练运行直到任务性能平稳,但论文显示早期检查点通常有更好的保持,任务性能只略差。
尝试基于保持指标的早停,或使用路径回退回滚到更好的操作点。
- 几何直觉可迁移:与顶部奇异向量对齐的更新导致遗忘的想法适用于 PEFT 之外。
如果你在做任何类型的微调或持续学习,思考你的更新如何与预训练结构交互。
正交性是保留先前知识的通用原则。
- 稳定性-可塑性是设计轴:在设计 PEFT 方法时,明确考虑权衡。
不要只是最小化任务损失——向目标添加保持项,或约束更新以保持预训练几何。
业界一直只优化可塑性;在平衡它与稳定性方面有低垂的果实。