Paper: 2606.06470 Authors: Senmiao Wang, Tiantian Fang, Haoran Zhang, Yushun Zhang, Kunxiang Zhao, Alex Schwing, Ruoyu Sun Categories: cs.LG, cs.AI
The Gap
Training instability in large language models often traces back to weight matrix conditioning. Standard transformers allow singular values to grow unchecked during training, leading to gradient explosion, vanishing gradients, and optimization pathologies. Existing solutions—careful learning rate schedules, aggressive clipping, specialized optimizers—treat symptoms rather than root causes. The weight matrices themselves remain poorly conditioned.
Problem: Weight matrices develop extreme singular value ratios
   |
   v
Observation: Ill-conditioned weights cause optimization instability
   |
   v
Hypothesis: Controlling singular value spectrum → stable training
   |
   v
Method: Polynomial preconditioner P(W) reshapes spectrum during training
   |
   v
Evidence: Llama-1B training shows improved stability + performance
   |
   v
Conclusion: Spectrum control is effective, inference-free control mechanism
The Increment
One sentence: Before this paper, weight conditioning was a consequence of training dynamics; after, it’s an explicit design parameter controlled throughout training with zero inference overhead.
Core Mechanism
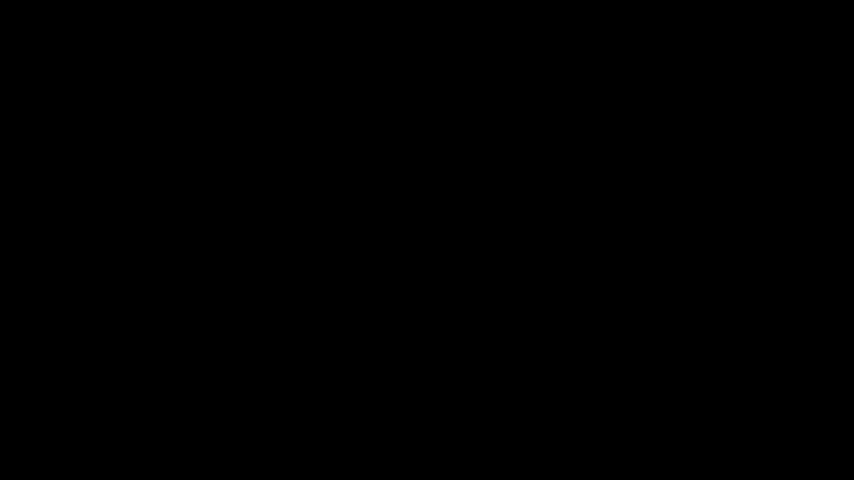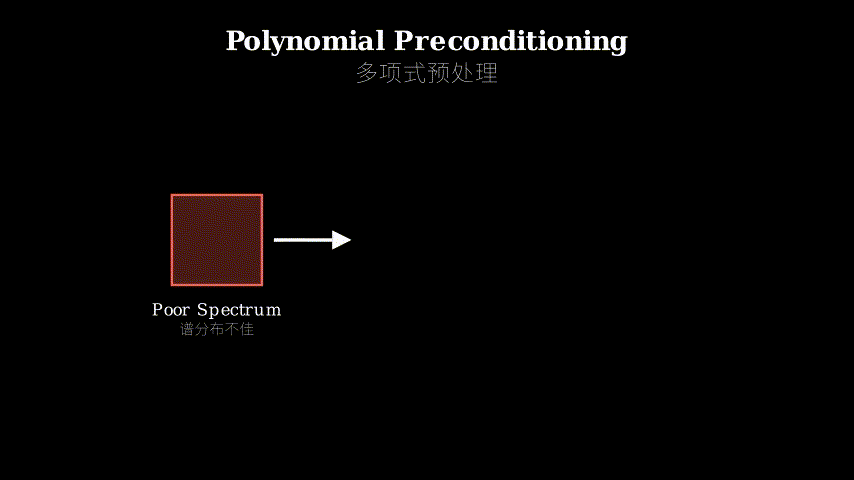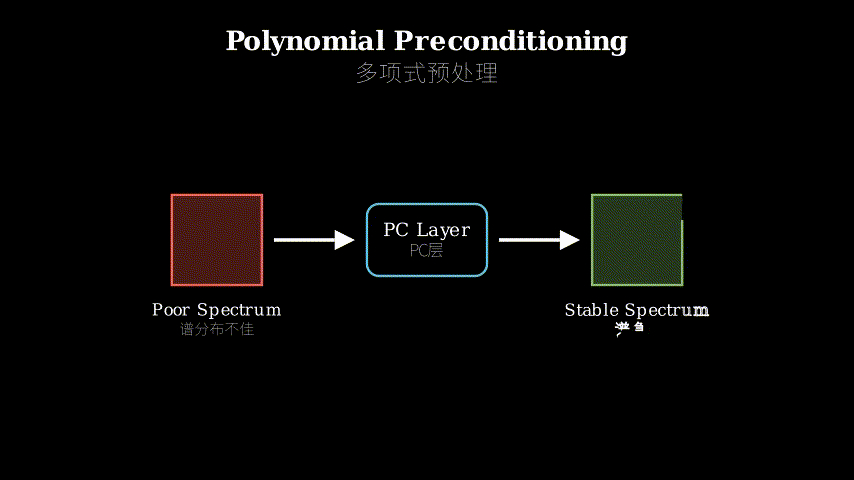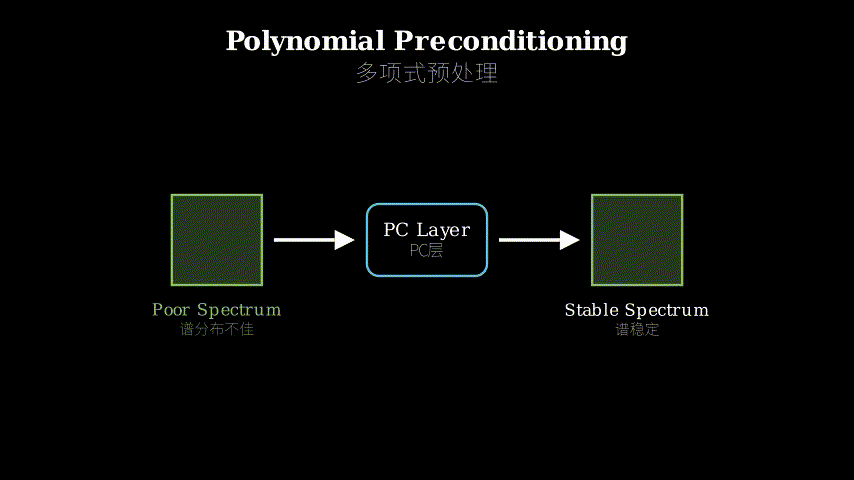
The PC layer wraps each weight matrix W in a polynomial preconditioner. During training, you optimize a base matrix W, but the actual weight used in forward/backward passes is P(W) = W · (I + αW^T W)^(-1). This polynomial in W^T W compresses the singular value spectrum—large singular values get shrunk more than small ones, keeping the condition number bounded.
The magic is in the mathematics: P(W) has a computable gradient with respect to W, so backpropagation flows through the preconditioner naturally. After training converges, you compute P(W) once and freeze it as a regular weight matrix. The preconditioner disappears—no runtime cost, no architectural change, just better-conditioned weights.
Training Flow:

 W (learnable) ----> P(W) = W(I+αW^T W)^(-1) ----> Forward Pass
    ^                        |
    |                        | (singular values compressed)
    |                        v
    +-------- Gradient ----- Backward Pass


Deployment Flow:

 W_trained ----> compute P(W) once ----> freeze as W_final
                                              |
                                              v
                                         Standard inference
                                         (no preconditioner)
Think of it like a hydraulic press for weight matrices. During training, the press is active—it continuously compresses the spectrum, preventing any singular value from growing too large relative to others. The optimizer adjusts the uncompressed matrix W, while the network sees only the pressed version P(W). Once training finishes, you remove the press and keep the final compressed shape. The weights stay well-conditioned even without the active compression mechanism, because they were trained under that constraint.
Key Concepts
-
Singular value spectrum: Every weight matrix W can be decomposed as W = UΣV^T, where Σ is a diagonal matrix of singular values. These values measure how much W stretches space in different directions. If the largest singular value is 1000× the smallest, W is “ill-conditioned”—small changes in input cause wildly different output magnitudes. In neural networks, ill-conditioned weights make gradients unpredictable: sometimes vanishing, sometimes exploding. The PC layer’s job is to keep the ratio of largest-to-smallest singular values bounded throughout training.
-
Polynomial preconditioning: Instead of directly constraining singular values (expensive), the PC layer applies a polynomial function P(W) = W · (I + αW^T W)^(-1). This specific polynomial has a useful property: it shrinks large singular values more aggressively than small ones. If W has singular values [100, 10, 1], then P(W) might have [10, 5, 1]—the range compressed, but relative ordering preserved. The polynomial is chosen because (1) it’s differentiable, so gradients flow through it, and (2) the inverse can be computed efficiently via matrix decomposition.
-
Zero inference overhead: During training, every forward pass computes P(W) from W, adding computational cost. But this is only a training-time mechanism. After convergence, you compute P(W_final) exactly once, obtaining a standard weight matrix with good conditioning. At inference, there’s no preconditioner—just a regular matrix multiply with the well-conditioned weights. This is different from techniques like LoRA or quantization, which change the inference architecture permanently.
Framework Shift
Before (standard training):          After (PC layer):

W (weights)                          W (base weights)
  |                                    |
  v                                    v
Linear(x) = Wx                       P(W) = W(I+αW^T W)^(-1)
  |                                    |
  | (conditioning drifts)              | (spectrum controlled)
  v                                    v
Gradient update W                    Linear(x) = P(W)x
  |                                    |
  | (optimizer fights drift)           v
  v                                  Gradient through P
Loss                                   |
                                       v
                                     Update W
                                       |
                                       | (after training)
                                       v
                                     Freeze P(W) → W_final
                                     (no runtime cost)
From passive acceptance of weight conditioning to active shaping during training, then collapsing to a standard matrix at deployment.
Expert Assessment
Problem choice: Real gap. Weight conditioning issues are well-documented in deep learning, but most solutions (gradient clipping, careful initialization) are band-aids. Targeting the spectrum directly is theoretically motivated—the paper cites a theorem proving that bounded singular values guarantee convergence in deep linear networks. However, the leap from linear theory to transformers is non-trivial, and the paper doesn’t fully bridge that gap.
Method maturity: Clever middle ground. Explicit spectral normalization (dividing by largest singular value) is simpler but requires expensive SVD every step. The polynomial preconditioner approximates spectral control cheaply. The form (I + αW^T W)^(-1) is well-chosen—it’s a rational function that can be inverted via Cholesky decomposition in O(d^3), cheaper than SVD’s O(d^3) but with a smaller constant. That said, for very large matrices (e.g., 8192×8192 in Llama), even O(d^3) adds up. The paper doesn’t report wall-clock time overhead.
Experimental integrity: Baselines are fair—standard Llama architecture, same training data, same optimizers (AdamW and Muon). The experiments show consistent improvements: lower loss, better downstream performance on reasoning benchmarks. However, the experiments are limited to 1B-scale models. Scaling behavior is unclear—does the O(d^3) preconditioning cost become prohibitive at 7B or 70B? The paper also doesn’t compare against simpler spectral regularization (e.g., adding ||W||_2 to the loss). One red flag: the theoretical guarantee only applies to deep linear networks, yet the empirical gains appear in nonlinear transformers. The connection is hand-wavy.
Writing quality: The method is clearly explained, but the theory section oversells. Theorem 1 proves convergence for deep linear networks with bounded singular values—interesting, but linear networks are trivial to train. The leap to “this justifies PC layers in transformers” is unsupported. The paper would be stronger if it either (1) proved something about nonlinear networks, or (2) positioned the theory as motivation rather than justification. The experiments section is solid but could use ablation studies: what happens if you vary the polynomial degree? What’s the trade-off between α (compression strength) and final performance?
Verdict: Weak accept—the method is practical and shows consistent gains, but the theoretical grounding is shaky and experiments are limited in scale. It’s a useful technique for practitioners training moderate-sized models, not a fundamental breakthrough.
Takeaways
Steal this: The insight that you can parameterize weights as W_eff = f(W_learnable) during training, then freeze W_eff at deployment, unlocks a design space. Any differentiable function f that improves training dynamics while being inference-free is worth exploring. Examples: low-rank bottlenecks, orthogonal constraints, or custom sparsity patterns—all applied during training, then baked into standard weights.
Concrete technique: If you’re training models and seeing gradient instability despite standard fixes (clipping, warm-up), try wrapping large weight matrices in a spectral normalization variant. Even simple ||W||_2 normalization (dividing W by its largest singular value) can stabilize training. The PC layer’s polynomial preconditioner is a fancier version, but the core principle—keep singular values bounded—applies broadly.
Transferable framing: “Training-time constraints that collapse to standard architectures” is powerful. It separates optimization concerns (what helps SGD converge?) from deployment concerns (what runs fast?). In other domains: train quantized networks with full-precision gradients, train sparse networks with dense backward passes, train low-rank networks with full-rank auxiliary losses—then freeze the efficient version.
论文: 2606.06470 作者: Senmiao Wang, Tiantian Fang, Haoran Zhang, Yushun Zhang, Kunxiang Zhao, Alex Schwing, Ruoyu Sun 分类: cs.LG, cs.AI
缺口
大语言模型训练不稳定的根源常常追溯到权重矩阵的条件数。
标准的Transformer允许奇异值在训练期间无约束增长,导致梯度爆炸、梯度消失和优化病态。
现有解决方案——精心设计的学习率调度、激进的梯度裁剪、专门的优化器——都在治标不治本。
权重矩阵本身依然条件数不佳。
问题:权重矩阵产生极端的奇异值比率
   |
   v
观察:病态条件的权重导致优化不稳定
   |
   v
假设:控制奇异值谱 → 稳定训练
   |
   v
方法:多项式预处理器P(W)在训练期间重塑谱
   |
   v
证据:Llama-1B训练显示稳定性与性能提升
   |
   v
结论:谱控制有效,推理时无开销
增量
一句话: 这篇论文之前,权重条件数是训练动态的副产品;
之后,它成为贯穿训练全程的显式设计参数,且推理时零开销。
核心机制
PC层用多项式预处理器包裹每个权重矩阵W。
训练时,你优化的是基础矩阵W,但前向和反向传播实际使用的权重是P(W) = W · (I + αW^T W)^(-1)。
这个关于W^T W的多项式压缩奇异值谱——大奇异值被压缩得比小奇异值更多,从而保持条件数有界。
奇妙之处在于数学:P(W)对W有可计算的梯度,所以反向传播自然地流过预处理器。
训练收敛后,你计算一次P(W)并将其冻结为常规权重矩阵。
预处理器消失——无运行时成本,无架构改变,只留下条件数更好的权重。
训练流程:

 W(可学习) ----> P(W) = W(I+αW^T W)^(-1) ----> 前向传播
    ^                        |
    |                        | (奇异值被压缩)
    |                        v
    +-------- 梯度 --------- 反向传播


部署流程:

 W_trained ----> 计算P(W)一次 ----> 冻结为W_final
                                         |
                                         v
                                    标准推理
                                    (无预处理器)
把它想象成权重矩阵的液压机。
训练时,液压机处于激活状态——它持续压缩谱,防止任何奇异值相对其他值增长过大。
优化器调整未压缩的矩阵W,而网络只看到压缩后的版本P(W)。
训练结束后,你移除液压机,保留最终的压缩形状。
权重即使没有主动压缩机制也保持良好条件数,因为它们是在该约束下训练出来的。
关键概念
- 奇异值谱: 每个权重矩阵W都可以分解为W = UΣV^T,其中Σ是奇异值的对角矩阵。
这些值衡量W在不同方向上拉伸空间的程度。
如果最大奇异值是最小奇异值的1000倍,W就是”病态的”——输入的微小变化导致输出幅度剧烈不同。
在神经网络中,病态权重使梯度不可预测:有时消失,有时爆炸。
PC层的任务是在整个训练过程中保持最大与最小奇异值的比率有界。
- 多项式预处理: PC层不直接约束奇异值(开销大),而是应用多项式函数P(W) = W · (I + αW^T W)^(-1)。
这个特定多项式有一个有用的性质:它对大奇异值的收缩比小奇异值更激进。
如果W的奇异值是[100, 10, 1],那么P(W)可能是[10, 5, 1]——范围被压缩,但相对顺序保持。
选择这个多项式是因为(1)它可微,梯度可以流过它,(2)逆矩阵可以通过矩阵分解高效计算。
- 推理零开销: 训练时,每次前向传播都从W计算P(W),增加计算成本。
但这只是训练时机制。
收敛后,你精确计算一次P(W_final),得到条件数良好的标准权重矩阵。
推理时没有预处理器——只是用条件数良好的权重做常规矩阵乘法。
这与LoRA或量化等技术不同,那些技术永久改变推理架构。
框架转变
之前(标准训练):                  之后(PC层):

W(权重)                          W(基础权重)
  |                                   |
  v                                   v
Linear(x) = Wx                      P(W) = W(I+αW^T W)^(-1)
  |                                   |
  | (条件数漂移)                      | (谱受控)
  v                                   v
梯度更新W                           Linear(x) = P(W)x
  |                                   |
  | (优化器对抗漂移)                  v
  v                                 梯度流过P
损失                                  |
                                      v
                                    更新W
                                      |
                                      | (训练后)
                                      v
                                    冻结P(W) → W_final
                                    (无运行时成本)
从被动接受权重条件数到训练期间主动塑造,然后在部署时折叠为标准矩阵。
专家评审
选题眼光: 真实缺口。
权重条件数问题在深度学习中有充分记录,但大多数解决方案(梯度裁剪、精心初始化)都是创可贴。
直接针对谱是有理论动机的——论文引用了一个定理,证明有界奇异值保证深度线性网络的收敛。
然而,从线性理论跃迁到Transformer是非平凡的,论文没有完全弥合这个鸿沟。
方法成熟度: 巧妙的中间路线。
显式谱归一化(除以最大奇异值)更简单,但每步都需要昂贵的SVD。
多项式预处理器廉价地近似谱控制。
形式(I + αW^T W)^(-1)选得很好——它是一个有理函数,可以通过Cholesky分解在O(d^3)时间求逆,比SVD的O(d^3)便宜(常数更小)。
话虽如此,对于非常大的矩阵(如Llama中的8192×8192),即使O(d^3)也会累积。
论文没有报告实际时间开销。
实验诚意: 基线公平——标准Llama架构,相同训练数据,相同优化器(AdamW和Muon)。
实验显示一致的改进:更低的损失,推理基准上更好的下游性能。
然而,实验仅限于1B规模模型。
缩放行为不明确——在7B或70B规模时,O(d^3)预处理成本会不会成为瓶颈?
论文也没有与更简单的谱正则化比较(如在损失中加||W||_2)。
一个警示:理论保证只适用于深度线性网络,但经验增益出现在非线性Transformer中。
这个联系是模糊的。
写作功力: 方法解释清晰,但理论部分过度推销。
定理1证明了具有有界奇异值的深度线性网络的收敛——有趣,但线性网络训练很简单。
跃迁到”这证明了PC层在Transformer中的合理性”是没有支撑的。
论文如果(1)证明关于非线性网络的东西,或(2)将理论定位为动机而非论证,会更强。
实验部分扎实,但可以增加消融研究:如果改变多项式次数会怎样?
α(压缩强度)与最终性能之间的权衡是什么?
判决: 弱接收——方法实用且显示一致增益,但理论基础薄弱,实验规模有限。
对于训练中等规模模型的实践者是有用的技术,不是根本性突破。
要点总结
偷走这个: 训练期间将权重参数化为W_eff = f(W_learnable),然后在部署时冻结W_eff的洞见,打开了一个设计空间。
任何改善训练动态且推理时无开销的可微函数f都值得探索。
例子:低秩瓶颈、正交约束、或自定义稀疏模式——都在训练时应用,然后烘焙进标准权重。
具体技术: 如果你在训练模型,尽管采用了标准修复(裁剪、预热)仍看到梯度不稳定,试着用谱归一化变体包裹大型权重矩阵。
即使是简单的||W||_2归一化(用最大奇异值除W)也能稳定训练。
PC层的多项式预处理器是更花哨的版本,但核心原则——保持奇异值有界——广泛适用。
可迁移框架: “折叠为标准架构的训练时约束”很强大。
它分离了优化关注点(什么帮助SGD收敛?)
和部署关注点(什么跑得快?)。
在其他领域:用全精度梯度训练量化网络,用稠密反向传播训练稀疏网络,用全秩辅助损失训练低秩网络——然后冻结高效版本。