
Paper: 2602.21045 Authors: Anna Martin-Boyle, Cara A. C. Leckey, Martha C. Brown, Harmanpreet Kaur Categories: cs.HC, cs.CL
Abstract
Large language models are increasingly deployed in scholarly question-answering systems to help researchers synthesize literature at scale. However, these systems frequently produce subtle errors including unsupported claims and omissions that are difficult to detect with traditional citation-based provenance mechanisms. This paper introduces PaperTrail, an interface that decomposes both LLM-generated answers and source documents into atomic claims and evidence units, then maps them to reveal which assertions are supported, unsupported, or omitted. A within-subjects study with 26 researchers performing scholarly editing tasks found that while PaperTrail significantly reduced trust in LLM outputs compared to a baseline interface, this heightened skepticism did not change actual usage behavior—participants continued relying on LLM-generated content to avoid cognitively demanding verification work.
Key Contributions
- A novel claim-evidence decomposition interface that provides granular provenance tracking for LLM-generated scholarly content
- Empirical evidence from 26 researchers showing that increased transparency about LLM errors reduces trust but not reliance
- Design insights revealing the tension between cognitive burden and verification rigor in scholarly AI tools
- A framework for understanding how provenance information must be presented to actually influence researcher behavior
The Provenance Problem in Scholarly AI
Traditional citation mechanisms in LLM-based scholarly tools operate at the document level, linking entire papers to generated text. This granularity is insufficient for rigorous scholarly verification, where researchers need to validate specific claims against precise evidence. The challenge is compounded by LLMs’ tendency to produce plausible-sounding but subtly incorrect content—hallucinated claims, misrepresented findings, or strategic omissions that preserve coherence while sacrificing accuracy.
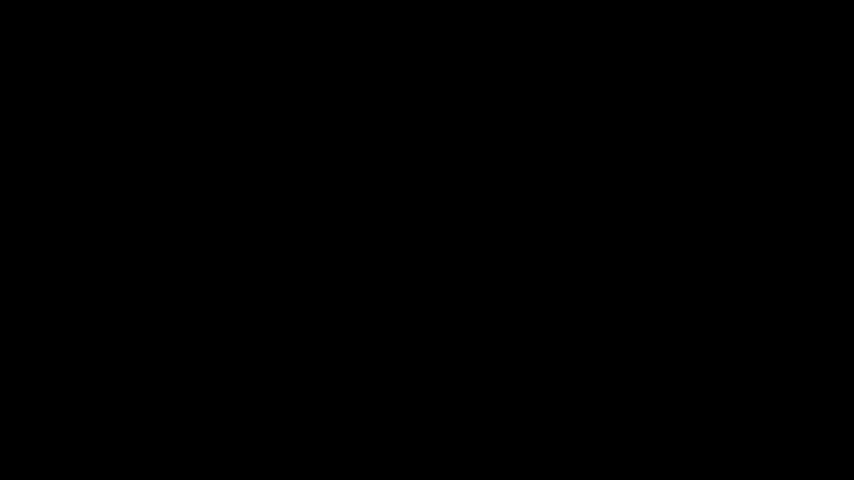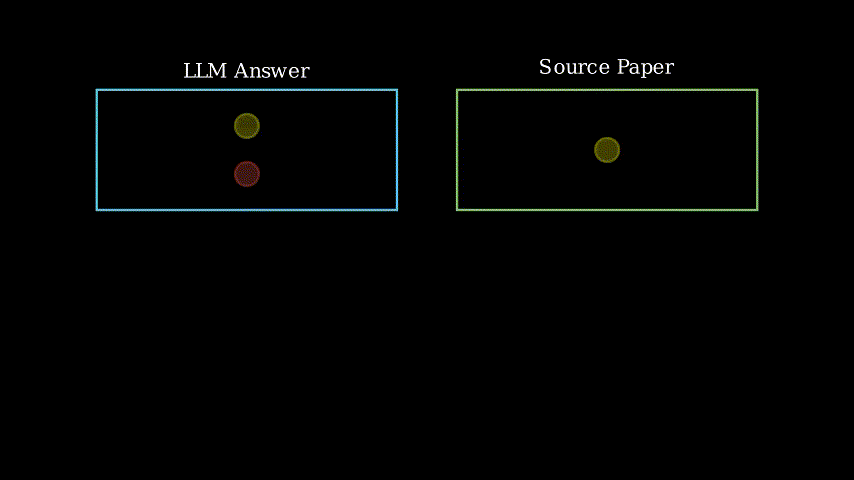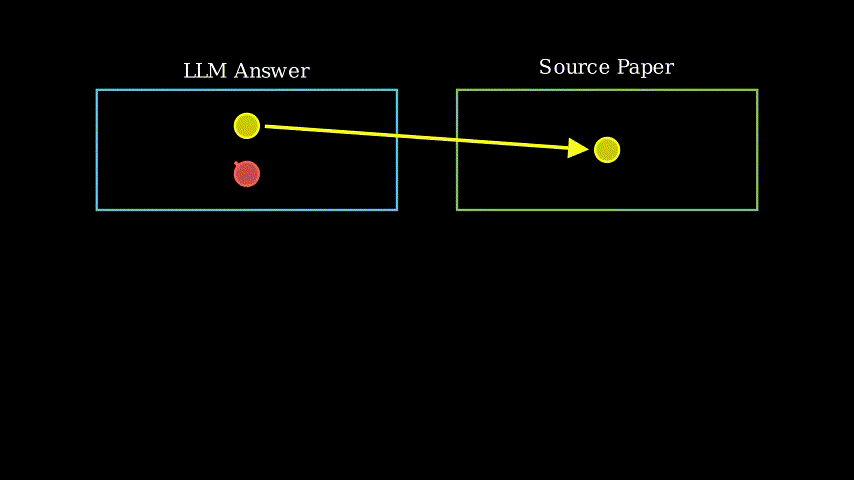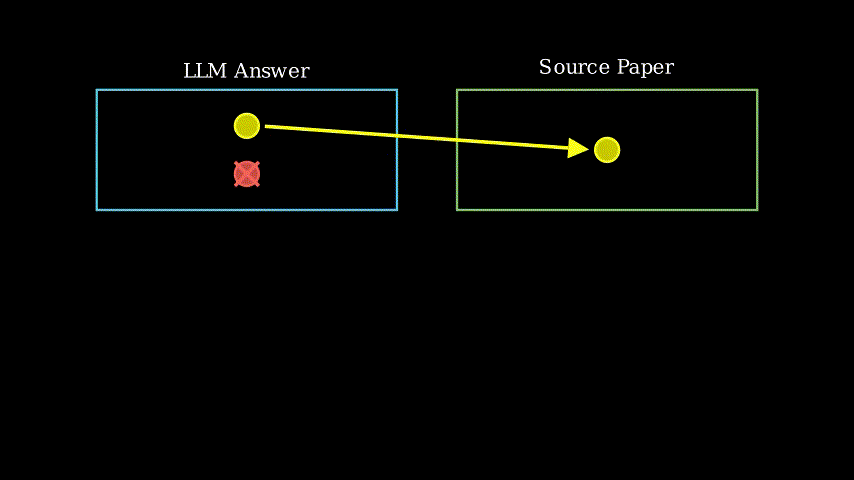
PaperTrail addresses this by implementing a three-layer provenance model: (1) decomposing LLM outputs into atomic claims, (2) extracting corresponding evidence from source documents, and (3) establishing explicit mappings between claims and evidence. This granular approach makes visible three critical categories of LLM behavior: supported claims with clear evidence, unsupported claims lacking source backing, and omitted information present in sources but absent from the generated text.
Methodology and Study Design
The researchers conducted a within-subjects study where 26 participants (researchers and graduate students) performed two scholarly editing tasks. Each participant used both PaperTrail and a baseline interface with traditional document-level citations, with task order counterbalanced to control for learning effects.
The editing tasks involved reviewing LLM-generated text that synthesized research literature, then editing it for accuracy and completeness. The baseline interface presented source documents with standard citations, while PaperTrail displayed the claim-evidence decomposition with visual mappings showing support relationships. Both interfaces had access to identical source materials and LLM-generated content.
Researchers collected quantitative metrics including task completion time, edit counts, and trust ratings, alongside qualitative data from think-aloud protocols and post-task interviews. The study design specifically examined whether increased provenance transparency would translate into behavioral changes in how researchers interact with LLM-generated scholarly content.
Results: The Trust-Behavior Paradox
The study revealed a striking disconnect between trust and behavior. PaperTrail significantly reduced participants’ reported trust in LLM-generated content (p<0.01), with researchers expressing greater skepticism about claim accuracy when confronted with explicit evidence mappings. Participants could clearly identify unsupported claims and omissions using the interface.
However, this reduced trust did not translate into substantively different editing behavior. Participants using PaperTrail made only marginally more edits than those using the baseline interface, and the types of edits were similar across conditions. Most critically, participants continued to accept the majority of LLM-generated content even when PaperTrail explicitly flagged claims as unsupported.
Qualitative analysis revealed the mechanism behind this paradox: verification is cognitively expensive. Even when provided with tools that make errors visible, researchers opted to accept LLM outputs rather than engage in the demanding work of checking every claim against source evidence. As one participant noted, “I can see it’s probably wrong, but fixing it properly would take longer than just leaving it.”
Design Implications for Scholarly AI Tools
The findings suggest that simply providing more granular provenance information is necessary but insufficient for improving scholarly AI tool reliability. The research identifies several key design challenges:
Cognitive load management: Interfaces must present provenance information in ways that reduce rather than increase the mental effort required for verification. PaperTrail’s comprehensive claim-evidence mapping, while informative, may have overwhelmed users with too much information to process efficiently.
Actionable transparency: Provenance mechanisms should not just reveal problems but facilitate their resolution. Future designs might automatically suggest corrections for unsupported claims or highlight high-confidence evidence that contradicts LLM assertions.
Selective verification support: Rather than requiring users to verify everything, interfaces could use confidence scores or other signals to direct attention to claims most likely to be problematic, allowing researchers to allocate verification effort strategically.
Integration with scholarly workflows: Verification tools must fit naturally into existing research practices rather than requiring researchers to adopt entirely new workflows. The cognitive burden of verification may be reduced if it’s distributed across the research process rather than concentrated in a single editing phase.
Takeaways
-
Granular claim-evidence provenance tracking can successfully reduce trust in LLM-generated scholarly content, making errors and omissions visible to researchers.
-
Reduced trust does not automatically translate to changed behavior—researchers continue relying on LLM outputs even when aware of potential errors, primarily to avoid cognitive burden.
-
The tension between verification rigor and cognitive effort represents a fundamental challenge in designing scholarly AI tools that researchers will actually use as intended.
-
Effective provenance interfaces must go beyond transparency to actively reduce the cognitive cost of verification, potentially through automated correction suggestions or intelligent attention direction.
-
Future scholarly AI systems should consider distributing verification across research workflows rather than concentrating it in discrete editing phases, making rigorous checking more manageable.
论文: 2602.21045 作者: Anna Martin-Boyle, Cara A. C. Leckey, Martha C. Brown, Harmanpreet Kaur 分类: cs.HC, cs.CL
摘要
大语言模型越来越多地被部署在学术问答系统中,帮助研究人员大规模综合文献。然而,这些系统经常产生微妙的错误,包括无根据的声明和遗漏,这些错误很难通过传统的基于引用的溯源机制检测出来。本文介绍了PaperTrail,一个将大语言模型生成的答案和源文档分解为原子声明和证据单元的界面,然后映射它们以揭示哪些断言得到支持、不支持或被遗漏。一项有26名研究人员参与的被试内研究发现,虽然与基线界面相比,PaperTrail显著降低了对大语言模型输出的信任,但这种增强的怀疑态度并未改变实际使用行为——参与者继续依赖大语言模型生成的内容以避免认知负担重的验证工作。
主要贡献
- 提出了一种新颖的声明-证据分解界面,为大语言模型生成的学术内容提供细粒度的溯源追踪
- 来自26名研究人员的实证证据表明,提高大语言模型错误的透明度会降低信任但不会降低依赖
- 揭示了学术AI工具中认知负担与验证严谨性之间的张力的设计洞察
- 提出了一个框架,用于理解如何呈现溯源信息才能真正影响研究人员的行为
学术AI中的溯源问题
基于大语言模型的学术工具中的传统引用机制在文档级别运作,将整篇论文链接到生成的文本。这种粒度对于严格的学术验证来说是不够的,研究人员需要针对精确的证据验证特定的声明。大语言模型倾向于产生听起来合理但微妙错误的内容——幻觉声明、误传的发现或战略性遗漏,这些在保持连贯性的同时牺牲了准确性,使挑战变得更加复杂。
PaperTrail通过实施三层溯源模型来解决这个问题:(1)将大语言模型输出分解为原子声明,(2)从源文档中提取相应的证据,(3)在声明和证据之间建立明确的映射。这种细粒度方法使大语言模型行为的三个关键类别变得可见:有明确证据支持的声明、缺乏来源支持的无根据声明,以及源文档中存在但生成文本中缺失的遗漏信息。
方法论与研究设计
研究人员进行了一项被试内研究,26名参与者(研究人员和研究生)执行了两项学术编辑任务。每个参与者都使用了PaperTrail和具有传统文档级引用的基线界面,任务顺序进行了平衡以控制学习效应。
编辑任务涉及审查综合研究文献的大语言模型生成文本,然后编辑其准确性和完整性。基线界面呈现带有标准引用的源文档,而PaperTrail显示声明-证据分解,并通过可视化映射显示支持关系。两个界面都可以访问相同的源材料和大语言模型生成的内容。
研究人员收集了定量指标,包括任务完成时间、编辑次数和信任评分,以及来自出声思考协议和任务后访谈的定性数据。研究设计专门检查了增加的溯源透明度是否会转化为研究人员与大语言模型生成的学术内容交互方式的行为变化。
研究结果:信任与行为的悖论
研究揭示了信任与行为之间的显著脱节。PaperTrail显著降低了参与者对大语言模型生成内容的报告信任度(p<0.01),当面对明确的证据映射时,研究人员对声明准确性表达了更大的怀疑。参与者可以使用该界面清楚地识别无根据的声明和遗漏。
然而,这种降低的信任并未转化为实质性不同的编辑行为。使用PaperTrail的参与者比使用基线界面的参与者仅进行了略多的编辑,并且各条件下的编辑类型相似。最关键的是,即使PaperTrail明确标记声明为无根据,参与者仍继续接受大部分大语言模型生成的内容。
定性分析揭示了这一悖论背后的机制:验证在认知上是昂贵的。即使提供了使错误可见的工具,研究人员也选择接受大语言模型输出,而不是从事检查每个声明与源证据的繁重工作。正如一位参与者所说:“我能看出它可能是错的,但正确修复它所需的时间比直接保留它要长。“
学术AI工具的设计启示
研究结果表明,仅仅提供更细粒度的溯源信息是必要的,但不足以提高学术AI工具的可靠性。研究确定了几个关键的设计挑战:
认知负荷管理: 界面必须以减少而不是增加验证所需心理努力的方式呈现溯源信息。PaperTrail的全面声明-证据映射虽然信息丰富,但可能用太多需要有效处理的信息压倒了用户。
可操作的透明度: 溯源机制不应仅仅揭示问题,还应促进其解决。未来的设计可能会自动为无根据的声明建议更正,或突出显示与大语言模型断言相矛盾的高置信度证据。
选择性验证支持: 界面可以使用置信度分数或其他信号将注意力引导到最可能出现问题的声明上,而不是要求用户验证所有内容,允许研究人员战略性地分配验证努力。
与学术工作流程的集成: 验证工具必须自然地融入现有的研究实践,而不是要求研究人员采用全新的工作流程。如果验证分布在整个研究过程中,而不是集中在单个编辑阶段,验证的认知负担可能会减少。
要点总结
-
细粒度的声明-证据溯源追踪可以成功降低对大语言模型生成的学术内容的信任,使研究人员能够看到错误和遗漏。
-
降低的信任不会自动转化为行为改变——即使意识到潜在错误,研究人员仍继续依赖大语言模型输出,主要是为了避免认知负担。
-
验证严谨性与认知努力之间的张力代表了设计研究人员实际按预期使用的学术AI工具的根本挑战。
-
有效的溯源界面必须超越透明度,积极降低验证的认知成本,可能通过自动更正建议或智能注意力引导。
-
未来的学术AI系统应考虑在研究工作流程中分配验证,而不是将其集中在离散的编辑阶段,使严格的检查更易于管理。