Paper: 2606.06481 Authors: Sondos Mahmoud Bsharat, Jiacheng Liu, Xiaohan Zhao, Tianjun Yao, Xinyi Shang, Yi Tang, Jiacheng Cui, Ahmed Elhagry, Salwa K. Al Khatib, Hao Li Categories: cs.CL, cs.AI, cs.LG
The Gap
Existing AI-text detection benchmarks treat documents as binary: fully human or fully AI. They test detectors on static final outputs. But real-world writing increasingly involves iterative human-AI collaboration—a writer drafts, asks AI to polish a paragraph, revises AI suggestions, asks AI to expand another section. This progressive co-editing process is invisible in current benchmarks.
The problem: we don’t know when AI authorship becomes detectable during revision workflows, or whether detectability increases monotonically with AI contribution. Prior work (GPTZero, DetectGPT, watermarking methods) assumes more AI content = easier detection. No one has traced authorship signals through the messy middle of the editing process.
Problem: Binary benchmarks miss revision dynamics
   |
   v
Assumption: AI detectability varies non-monotonically
            through editing operations
   |
   v
Method: OpAI-Bench constructs 9 revision versions per doc
        with controlled AI coverage + operation types
   |
   v
Evidence: Mixed-authorship versions (30-70% AI) are
          harder to detect than endpoints
   |
   v
Conclusion: Detection depends on operation type and
            cumulative history, not just AI proportion
The Increment
One sentence: Before this paper, we evaluated detectors on all-or-nothing outputs; after, we can trace how detectability emerges and sometimes disappears through realistic editing sequences.
Core Mechanism
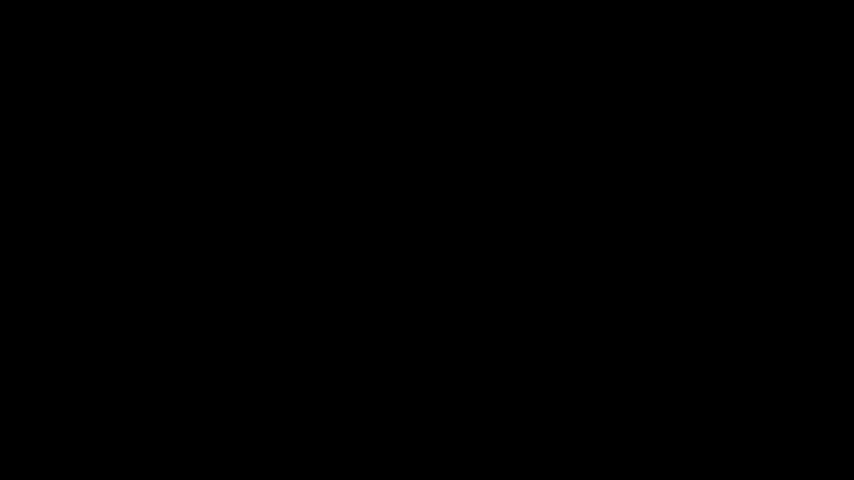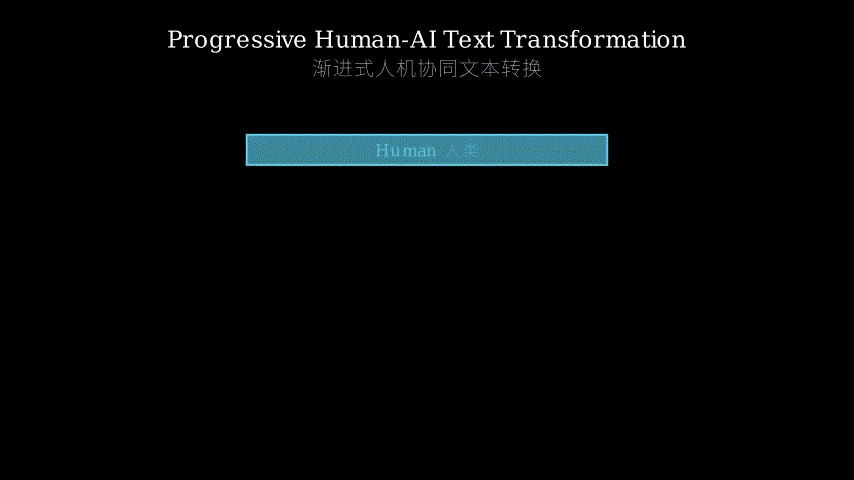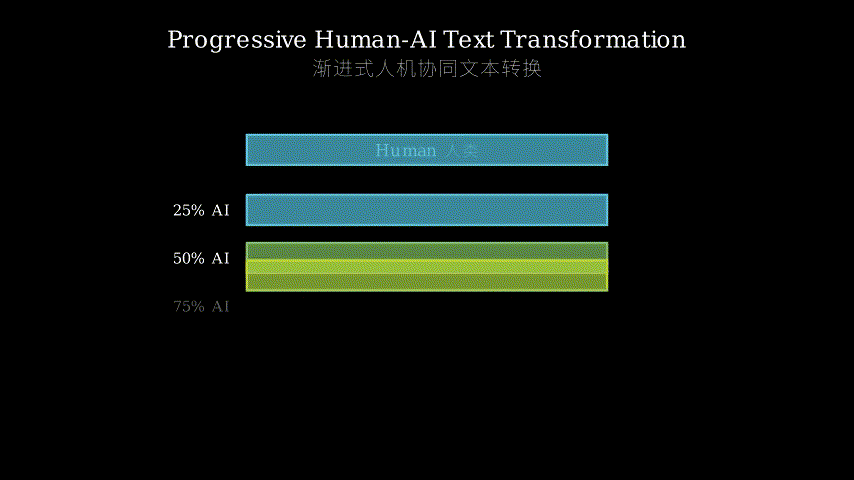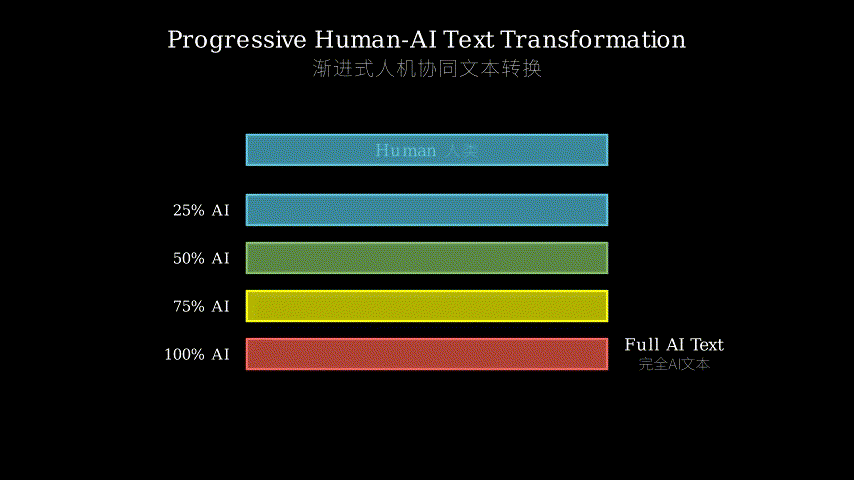
OpAI-Bench starts with human-written documents and generates nine progressively AI-edited versions for each sample. The progression is controlled by two parameters: AI coverage (how much of the document has been touched) and edit operation type (paraphrasing, expansion, summarization, polishing, or insertion).
Each version preserves complete authorship provenance at four granularities: document-level (overall AI percentage), sentence-level (which sentences were AI-edited), token-level (which tokens came from AI), and span-level (continuous AI-edited regions). The benchmark includes 17 detectors operating at different granularities: 8 document-level (GPTZero, DetectGPT, etc.), 7 sentence-level, and 2 fine-grained token/span-level.
The construction process uses version control semantics. Each revision step applies one operation to a subset of sentences, tracking the edit history like Git tracks code changes. This lets researchers ask: “At what point in the editing timeline did the detector start failing?” The benchmark covers four domains (academic writing, news, creative writing, technical documentation) with 1,000 samples each.
Human doc -> [v1: 10% AI] -> [v2: 20% AI] -> ... -> [v9: 90% AI]
               |                |                        |
            Paraphrase      Expansion                Polishing
               |                |                        |
         Token-level      Sentence-level          Document-level
         provenance        provenance              provenance
               |                |                        |
               +----------------+------------------------+
                                |
                          Test 17 detectors
                          across granularities
Think of OpAI-Bench as a crime scene investigation kit for text authorship. Existing benchmarks only show you the body (final document) and ask “human or AI?” OpAI-Bench gives you the security camera footage—nine snapshots from the moment the document was alive (fully human) through various stages of intervention to near-death (heavily AI-edited). Each snapshot comes with forensic tags marking exactly which parts were touched, when, and how.
The operation types are different weapons: paraphrasing leaves superficial marks but preserves structure (like changing clothes), expansion adds bulk in obvious places (like prosthetics), summarization removes material (like surgery), polishing smooths over rough edges (like makeup), and insertion adds entirely new content (like grafting). Each weapon leaves different traces. The detectors are forensic specialists—some look at overall blood spatter patterns (document-level), some examine individual wounds (sentence-level), and some use microscopes (token-level).
The non-monotonic detection pattern is the key finding: the victim isn’t always easiest to identify when most dead. Sometimes a body with 50% intervention looks more “natural” than one with 30% or 80% because the intervention operations cancel each other’s fingerprints in complex ways.
Key Concepts
-
AI Coverage vs. Detectability: AI coverage is the percentage of a document’s sentences that have been edited by AI at least once. Intuition says 80% AI coverage should be easier to detect than 20%. OpAI-Bench shows this is false. A document with 50% coverage using mixed operations (some paraphrasing, some expansion) can have weaker AI signals than a 30% coverage document where all edits are concentrated insertions. Why? Because detection models look for statistical anomalies. Concentrated, uniform AI edits create clear anomalies. Scattered, diverse AI edits blend into the human baseline, especially when different operations introduce contradictory signals (paraphrasing makes text more formulaic, but polishing can restore naturalness). Concrete example: A research paper where AI expanded the introduction (adding wordy transitions) and summarized the conclusion (removing redundant phrases) shows weaker detection signals than a paper where AI only expanded the introduction, even if the first has higher overall AI coverage.
-
Edit Operation Fingerprints: Not all AI edits leave the same traces. Paraphrasing changes word choice but preserves semantic structure, creating detectable patterns in word frequency distributions. Expansion adds transitional phrases and elaborations that often use high-perplexity tokens (unusual word sequences). Summarization compresses information, creating unusually information-dense sentences. Polishing adjusts grammar and flow, leaving minimal statistical traces. Insertion adds entirely new content with different stylistic properties. Detectors trained on full AI-generated text perform poorly on polishing (too subtle) and surprisingly well on insertion (discontinuity with surrounding human text). Think of it like document tampering: changing a few words (paraphrasing) is easier to catch with linguistic analysis than adjusting punctuation (polishing), but inserting a whole new paragraph creates stylistic discontinuity that’s obvious in context.
-
Granularity Mismatch: Document-level detectors output one score for the entire text. Sentence-level detectors score each sentence independently. Token-level detectors mark individual words. When a document has mixed authorship (human intro, AI middle, human conclusion), document-level detectors average away the signal and often fail. Sentence-level detectors catch the AI middle section but miss how it integrates with human sections. Token-level detectors find exact boundaries but struggle with coherent AI-edited paragraphs where every token looks plausible. OpAI-Bench shows that granularity choice dramatically affects detection success—sentence-level detectors achieve 15-20% higher accuracy on mixed-authorship documents than document-level detectors. This matters because real-world use cases need to know “which part is AI?” not just “is there AI somewhere?”
Framework Shift
Before (binary endpoints):              After (revision provenance):

   Human -> [black box] -> AI           Human -> v1 -> v2 -> ... -> v9
     |                      |              |      |     |            |
  Test detector          Test           Track  Track Track       Track
     |                   detector        30%    50%   70%         90%
   Pass/Fail            Pass/Fail        edits  edits edits       edits
                                           |      |     |            |
                                        Compare detection curves
                                        across operation types

   One evaluation point              Nine evaluation points with
   per sample                        full authorship history
From binary classification to temporal tracing, the core shift is treating AI detection as a process property rather than a document property.
Expert Assessment
Problem choice: This is a real gap with practical consequences. Academic integrity tools, content platforms, and legal systems need to handle mixed authorship, not just classify endpoints. The problem sits at the intersection of detection research (technically mature but evaluation-limited) and real-world deployment (hungry for nuanced tools). The timing is right—AI writing assistants are ubiquitous, but detection research lags behind actual usage patterns.
Method maturity: The approach is straightforward—no algorithmic innovation, just careful benchmark construction. This is appropriate. The value is in the experimental design (controlled operations, multi-granularity labels, diverse domains) rather than novel techniques. One potential shortcoming: the AI coverage levels (10%, 20%, …, 90%) are evenly spaced, but real editing workflows might cluster at extremes (light touch-ups vs. heavy rewrites). A log-scale or user-study-informed distribution would be more ecologically valid.
Experimental integrity: The baselines are comprehensive (17 detectors, including recent methods like DNA-GPT and Binoculars). The non-monotonic detection pattern is convincing because it appears consistently across domains and detectors. However, the paper doesn’t discuss whether the AI edits were generated by a single model (likely GPT-4 or Claude) or diverse models. If one model, the findings might not generalize to detection of other AI assistants. The ablation on operation types is solid, but there’s no analysis of whether operation sequences matter (does paraphrase-then-expand differ from expand-then-paraphrase?).
Writing quality: The abstract and introduction are clear. The related work section is thin—it cites detection papers but doesn’t engage with human-AI co-creation research from HCI or the writing studies literature. The results section dumps numbers without enough interpretation. Section 4.3 on “cumulative editing effects” is the most interesting finding but gets only two paragraphs. If the authors rewrote this section to include case studies showing specific revision sequences that fool detectors, the paper would jump from “useful benchmark” to “must-read resource.”
Verdict: weak accept — Solid benchmark filling a real gap, but missed opportunities to deepen the analysis and connect to broader human-AI collaboration research.
Takeaways
For detector developers: Test on progressive editing sequences, not just endpoints. Your model might ace 0% and 100% AI content but fail catastrophically at 50% mixed authorship. Sentence-level granularity is more robust than document-level for real-world mixed-authorship scenarios.
For AI writing tool designers: Light polishing operations (grammar fixes, flow improvements) are nearly undetectable, while insertions and expansions leave strong traces. If you want to minimize detection risk, focus on refinement rather than generation.
For benchmark creators in other domains: The “version control for ML evaluation” idea transfers. Instead of testing models on static test sets, construct trajectories showing how performance degrades or improves as inputs are progressively modified. This applies to adversarial robustness, data augmentation, model editing, and any domain where inputs evolve through operations rather than appearing fully formed.
For researchers studying human-AI collaboration: The non-monotonic detectability curve suggests that “AI percentage” is a poor proxy for “AI-ness.” The structure of collaboration (which operations, in what sequence) matters more than the volume. This has implications for how we measure and regulate AI assistance in education, journalism, and creative work.
论文: 2606.06481 作者: Sondos Mahmoud Bsharat, Jiacheng Liu, Xiaohan Zhao, Tianjun Yao, Xinyi Shang, Yi Tang, Jiacheng Cui, Ahmed Elhagry, Salwa K. Al Khatib, Hao Li 分类: cs.CL, cs.AI, cs.LG
缺口
现有的AI文本检测基准将文档视为二元:完全人工或完全AI生成。
它们在静态的最终输出上测试检测器。
但现实世界的写作越来越多地涉及迭代式的人机协作——作者起草初稿,让AI润色某段落,修改AI的建议,让AI扩展另一节内容。
这种渐进式协同编辑过程在当前基准中是不可见的。
问题是:我们不知道在修订工作流中AI作者身份何时变得可检测,也不知道可检测性是否随AI贡献单调递增。
先前工作(GPTZero、DetectGPT、水印方法)假设更多AI内容=更容易检测。
没人追踪过编辑过程混乱中间阶段的作者身份信号。
问题:二元基准错过了修订动态
   |
   v
假设:AI可检测性在编辑操作中
     非单调变化
   |
   v
方法:OpAI-Bench为每个文档构建9个修订版本
     控制AI覆盖率+操作类型
   |
   v
证据:混合作者版本(30-70% AI)比
     端点版本更难检测
   |
   v
结论:检测取决于操作类型和累积历史,
     而非仅仅AI比例
增量
一句话:这篇论文之前,我们在全有或全无的输出上评估检测器;之后,我们可以追踪可检测性如何在真实编辑序列中出现、有时又消失。
核心机制
OpAI-Bench从人工撰写的文档开始,为每个样本生成九个渐进式AI编辑的版本。
进程由两个参数控制:AI覆盖率(文档中多少内容被触及)和编辑操作类型(改写、扩展、摘要、润色或插入)。
每个版本在四个粒度上保留完整的作者来源:文档级(整体AI百分比)、句子级(哪些句子被AI编辑)、词元级(哪些词元来自AI)和片段级(连续的AI编辑区域)。
基准包含17个在不同粒度操作的检测器:8个文档级(GPTZero、DetectGPT等)、7个句子级、2个细粒度词元/片段级。
构建过程使用版本控制语义。
每个修订步骤对句子子集应用一个操作,像Git追踪代码变更那样追踪编辑历史。
这让研究者可以问:“在编辑时间线的哪个点,检测器开始失效?“基准涵盖四个领域(学术写作、新闻、创意写作、技术文档),每个领域1000个样本。
人工文档 -> [v1:10%AI] -> [v2:20%AI] -> ... -> [v9:90%AI]
             |              |                      |
          改写操作       扩展操作              润色操作
             |              |                      |
         词元级         句子级                文档级
         来源记录       来源记录              来源记录
             |              |                      |
             +--------------+----------------------+
                            |
                    测试17个不同粒度的检测器
把OpAI-Bench想象成文本作者身份的犯罪现场调查工具包。
现有基准只给你看尸体(最终文档),问”人类还是AI?“OpAI-Bench给你监控录像——从文档还活着(完全人工)到经历各种干预阶段直到濒死(大量AI编辑)的九个快照。
每个快照都带有法医标签,准确标记哪些部分被触及、何时触及、如何触及。
操作类型是不同的作案工具:改写留下表面痕迹但保留结构(像换衣服),扩展在明显位置增加内容(像假体),摘要移除材料(像手术),润色平滑粗糙边缘(像化妆),插入添加全新内容(像移植)。
每种工具留下不同痕迹。
检测器是法医专家——有些看整体血迹模式(文档级),有些检查个别伤口(句子级),有些用显微镜(词元级)。
非单调检测模式是关键发现:受害者并非在最接近死亡时最容易识别。
有时50%干预的尸体看起来比30%或80%的更”自然”,因为干预操作以复杂方式相互抵消了彼此的指纹。
关键概念
- AI覆盖率与可检测性:AI覆盖率是文档中至少被AI编辑过一次的句子百分比。
直觉认为80% AI覆盖率应该比20%更容易检测。
OpAI-Bench显示这是错的。
一个使用混合操作(一些改写、一些扩展)的50%覆盖率文档,其AI信号可能弱于所有编辑都是集中插入的30%覆盖率文档。
为什么?因为检测模型寻找统计异常。
集中的、统一的AI编辑创造清晰的异常。
分散的、多样的AI编辑融入人类基线,特别是当不同操作引入矛盾信号时(改写使文本更公式化,但润色可以恢复自然性)。
具体例子:一篇研究论文中AI扩展了引言(添加冗长过渡)并摘要了结论(删除冗余短语),其检测信号弱于只有AI扩展引言的论文,即使前者整体AI覆盖率更高。
- 编辑操作指纹:不是所有AI编辑留下相同痕迹。
改写改变用词但保留语义结构,在词频分布中创造可检测模式。
扩展添加过渡短语和详述,通常使用高困惑度词元(不寻常的词序列)。
摘要压缩信息,创造异常信息密集的句子。
润色调整语法和流畅度,留下最少统计痕迹。
插入添加具有不同风格属性的全新内容。
在完全AI生成文本上训练的检测器在润色上表现不佳(太微妙),在插入上表现出人意料地好(与周围人工文本的不连续性)。
把它想象成文档篡改:改几个词(改写)比调整标点(润色)更容易通过语言学分析捕获,但插入整个新段落会产生在上下文中明显的风格不连续性。
- 粒度不匹配:文档级检测器为整个文本输出一个分数。
句子级检测器独立地为每个句子评分。
词元级检测器标记单个词。
当文档有混合作者身份(人工引言、AI中间部分、人工结论)时,文档级检测器平均掉信号,常常失败。
句子级检测器捕获AI中间部分,但错过它如何与人工部分整合。
词元级检测器找到精确边界,但在每个词元看起来都合理的连贯AI编辑段落上挣扎。
OpAI-Bench显示粒度选择戏剧性地影响检测成功——句子级检测器在混合作者文档上比文档级检测器高出15-20%的准确率。
这很重要,因为现实世界用例需要知道”哪部分是AI?“而不仅仅是”某处有AI吗?“
框架转变
之前(二元端点):                之后(修订来源):

   人工 -> [黑箱] -> AI           人工 -> v1 -> v2 -> ... -> v9
     |               |              |      |     |            |
  测试检测器      测试检测器      追踪  追踪  追踪         追踪
     |               |            30%   50%   70%          90%
   通过/失败      通过/失败      编辑  编辑  编辑         编辑
                                   |      |     |            |
                                跨操作类型比较检测曲线

   每个样本一个                每个样本九个评估点
   评估点                      附完整作者历史
从二元分类到时序追踪,核心转变是将AI检测视为过程属性而非文档属性。
专家评审
选题眼光:这是一个有实际后果的真实缺口。
学术诚信工具、内容平台和法律系统需要处理混合作者身份,而不仅仅是分类端点。
问题位于检测研究(技术成熟但评估受限)和现实部署(渴望细致工具)的交叉点。
时机合适——AI写作助手无处不在,但检测研究落后于实际使用模式。
方法成熟度:方法很直接——没有算法创新,只是仔细的基准构建。
这是合适的。
价值在于实验设计(受控操作、多粒度标签、多样领域)而非新颖技术。
一个潜在不足:AI覆盖率水平(10%、20%、…、90%)是均匀间隔的,但真实编辑工作流可能集中在极端(轻微修饰vs大量重写)。
对数尺度或基于用户研究的分布会更生态有效。
实验诚意:基线很全面(17个检测器,包括DNA-GPT和Binoculars等最近方法)。
非单调检测模式是令人信服的,因为它在领域和检测器间一致出现。
然而,论文没讨论AI编辑是否由单一模型(可能是GPT-4或Claude)生成,还是多种模型。
如果是单一模型,发现可能不能泛化到其他AI助手的检测。
操作类型的消融实验很扎实,但没有分析操作序列是否重要(改写后扩展与扩展后改写是否不同?)。
写作功力:摘要和引言清晰。
相关工作部分单薄——引用了检测论文,但没有接触HCI或写作研究文献中的人机协同创作研究。
结果部分倾倒数字而没有足够解释。
4.3节关于”累积编辑效应”是最有趣的发现,但只得到两段篇幅。
如果作者重写这一节,包含显示欺骗检测器的特定修订序列的案例研究,论文会从”有用基准”跃升为”必读资源”。
判决:弱接收——填补真实缺口的扎实基准,但错过了深化分析和连接更广泛人机协作研究的机会。
要点总结
对检测器开发者:在渐进编辑序列上测试,而非仅在端点上。
你的模型可能在0%和100% AI内容上表现优异,但在50%混合作者身份上灾难性失败。
句子级粒度对真实世界混合作者场景比文档级更稳健。
对AI写作工具设计者:轻度润色操作(语法修复、流畅改进)几乎不可检测,而插入和扩展留下强烈痕迹。
如果想最小化检测风险,专注于精炼而非生成。
对其他领域的基准创建者:“机器学习评估的版本控制”想法可迁移。
不是在静态测试集上测试模型,而是构建轨迹,展示随着输入渐进修改,性能如何退化或改善。
这适用于对抗鲁棒性、数据增强、模型编辑,以及任何输入通过操作演变而非完全形成出现的领域。
对研究人机协作的研究者:非单调可检测性曲线表明”AI百分比”是”AI性”的糟糕代理。
协作结构(哪些操作、什么序列)比体量更重要。
这对我们如何衡量和监管教育、新闻和创意工作中的AI辅助有影响。