Paper: 2606.13649 Authors: Nathaniel Bottman, Yinhong Liu, Kyle Richardson Categories: cs.CL, cs.LG
The Gap
Existing methods for detecting LLM reasoning failures without ground-truth labels fall into two camps: (1) sampling-based approaches like self-consistency (CoT-SC) and semantic entropy, which rely on multiple independent outputs from the same question, and (2) self-evaluation approaches like P(True), where the model judges its own confidence. Both treat the model as a black box and ignore the structure of the reasoning—specifically, whether the model’s answer is consistent with its own decomposition of the question.
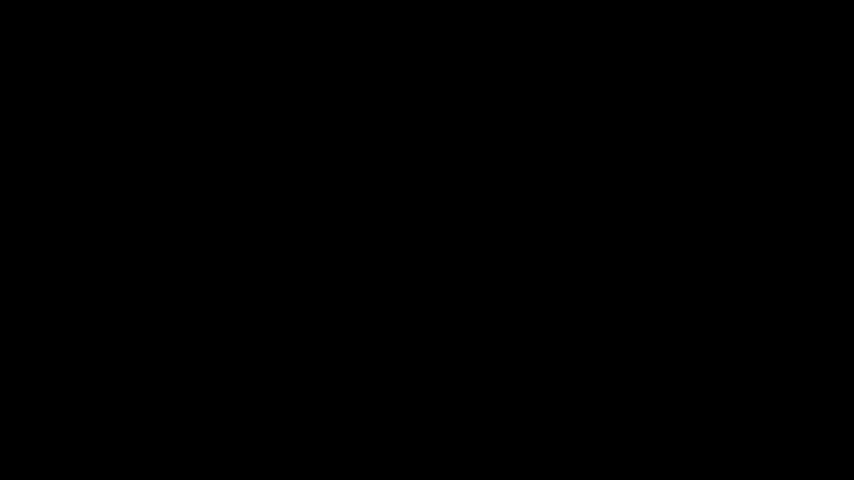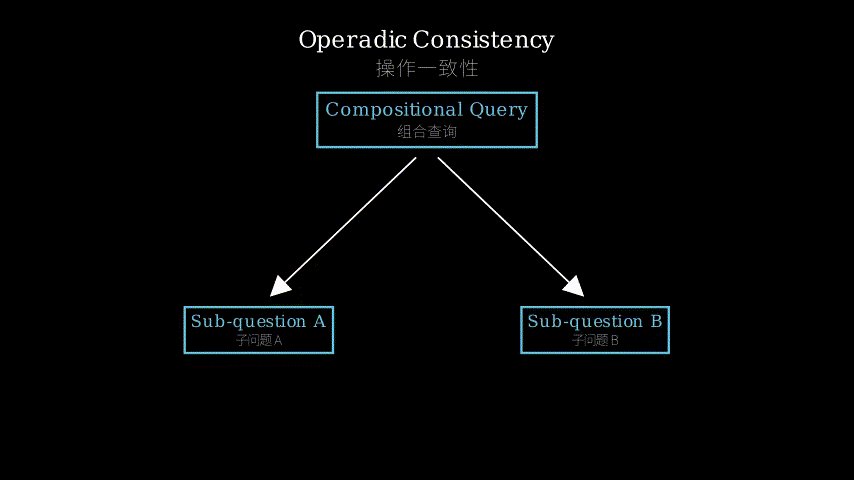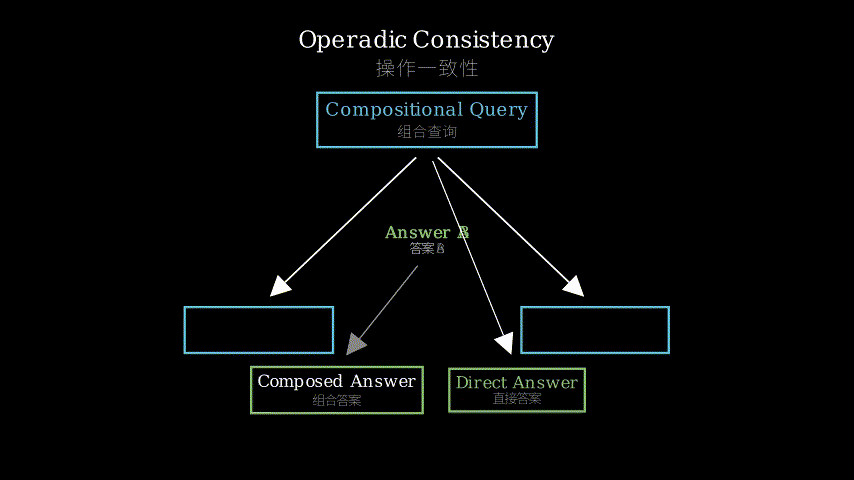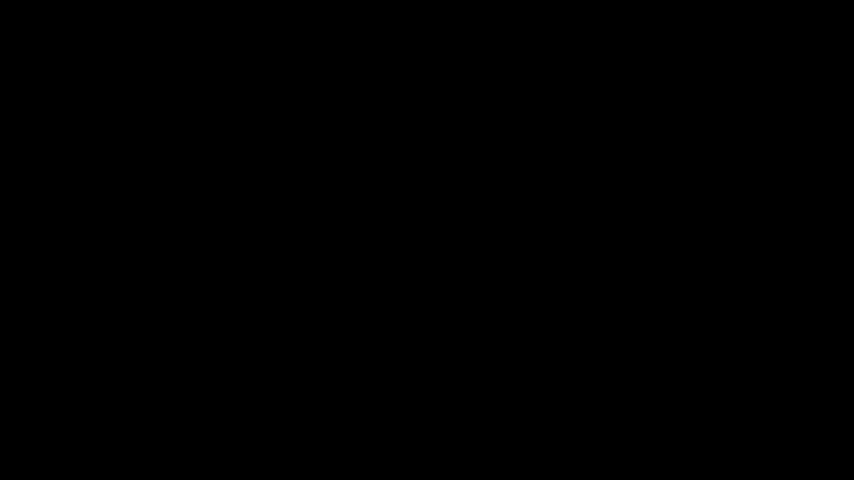
The paper identifies a blind spot: for compositional (multi-hop) questions, a model should produce the same answer whether it answers directly or first breaks the question into sub-questions, answers each, then composes the results. No prior work formalized this as a diagnostic. The authors fill this gap by borrowing operad theory (a formalism for systems built by iterated substitution) and grounding a simple comparison: direct answer vs. composed answer.
        +------------------------------+
        | Problem: No label-free signal|
        | for compositional failure   |
        +-------------+---------------+
                      |
                      v
        +-------------+---------------+
        | Assumption: For composition |
        | queries, direct answer      |
        | should equal composed       |
        | answer from decomposition   |
        +-------------+---------------+
                      |
                      v
        +-------------+---------------+
        | Method: Compute OC =        |
        | agreement( direct answer,   |
        | compose( decompose( Q ) ) ) |
        +-------------+---------------+
                      |
                      v
        +-------------+---------------+
        | Evidence: OC correlates     |
        | with accuracy (r 0.86-0.94) |
        | across 12 models, 4 datasets|
        +-------------+---------------+
                      |
                      v
        +-------------+---------------+
        | Conclusion: OC is a         |
        | label-free signal for       |
        | compositional failure       |
        +------------------------------+
The Increment
One sentence: Before this paper, reasoning failure detection relied on output statistics or self-evaluation; after this paper, we gain a structural consistency check that exploits the model’s own decomposition of the query, providing complementary signal at little extra cost.
Core Mechanism
Operadic consistency works in three steps:
-
Extract decomposition: Given a multi-hop question Q, prompt the model to produce a decomposition into sub-questions (e.g., via chain-of-thought or a separate prompt). Also record the model’s direct answer A_direct.
-
Compose sub-answers: For each sub-question, obtain the model’s answer (using the same model or a copy). Then define a composition function that combines the sub-answers into a full answer A_composed. The composition function depends on the decomposition structure—e.g., if the sub-questions are linear, answers are simply concatenated or a final answer is derived.
-
Compare: Compute the agreement (e.g., exact match or a soft score based on lexical overlap or probability) between A_direct and A_composed. This agreement is the operadic consistency score—higher agreement signals higher confidence that the model’s reasoning is correct.
The whole pipeline is inference-only, requires no training, and for the K-shot budget (K=3) adds negligible latency.
                           +---------------------+
                           | Input Question Q    |
                           +----------+----------+
                                      |
                  +-------------------+-------------------+
                  |                                       |
                  v                                       v
     +------------+------------+             +------------+------------+
     | Decompose Q into        |             | Direct answer:          |
     | sub-questions q1..qn    |             | A_direct = model(Q)    |
     +------------+------------+             +------------+------------+
                  |                                       |
                  v                                       |
     +------------+------------+                           |
     | Answer each sub-q       |                           |
     | -> a1 = model(q1), etc |                           |
     +------------+------------+                           |
                  |                                       |
                  v                                       |
     +------------+------------+                           |
     | Compose answers:        |                           |
     | A_composed = compose(   |                           |
     |   a1..an )              |                           |
     +------------+------------+                           |
                  |                                       |
                  +-------+-------------------------------+
                          |
                          v
                +---------+---------+
                | Compare A_direct  |
                | vs A_composed     |
                | -> OC score       |
                +-------------------+
Structural metaphor: the jigsaw puzzle check.
Imagine you have an assembled jigsaw puzzle (the question Q). You can either glance at the full picture and announce “it’s a castle” (direct answer), or you can follow an instruction sheet that tells you to separate the puzzle into four corner pieces, examine each, then mentally reassemble them to decide “it’s a castle” (decomposition + composition). If your first answer and your assembled answer match, you likely understood the picture; if they contradict, something went wrong—maybe you misread a corner piece, or the sheet was wrong, or you hallucinated a dragon. The operadic consistency score is the “match signal”. Each component maps: the instruction sheet = decomposition prompt; examining each corner = answering sub-questions; mental reassembly = composition; final verbal claim = direct answer.
Key Concepts
-
Operadic consistency (OC)
Operad theory studies systems where complex structures are built by plugging simpler pieces into slots. In language, a multi-hop question is an operad: the top-level query has “slots” for sub-question answers. OC checks that the model respects this plugging operation—i.e., that the output of the full query equals the result of inserting sub-answers into the slots. It’s a formal way of saying “the model’s answers are self-consistent under decomposition”. -
Multi-hop QA
Questions that require reasoning across multiple facts, e.g., “What is the capital of the country where the Eiffel Tower is located?” The first hop locates France, the second hop finds Paris. Multi-hop datasets (HotpotQA, MuSiQue, StrategyQA) are a natural testbed because decomposition is explicit and composition is well-defined. -
Self-consistency (CoT-SC)
A baseline that samples multiple reasoning paths and aggregates by majority vote. It detects failures when different paths converge to different answers. OC differs: it uses a single path (the decomposition) and checks internal consistency, not aggregation of multiple paths. The two signals are complementary—OC captures structural errors that CoT-SC might miss when all paths hallucinate the same wrong answer.
Framework Shift
The core shift is from aggregating distributional statistics to checking structural agreement.
Before (mainstream approach):
   Q --> [LLM x K] --> {answers} --> majority vote / entropy --> confidence
   The decomposition structure is ignored; only output patterns matter.

After (this paper):
   Q --> [LLM] --> A_direct
   Q --> [LLM] --> decomposition --> sub-answers --> compose --> A_composed
         OC = match(A_direct, A_composed)
   Structure is front-and-center: consistency under plugging reveals failures.
From output statistics to structural consistency: the old view treats each answer as an independent draw; the new view exploits the fact that reasoning has internal dependencies that should be invariant under decomposition.
Expert Assessment
Problem choice: Real gap. Researchers knew self-consistency and semantic entropy had blind spots (e.g., when all sampled paths are wrong), but no one formalized the decomposition-as-consistency-check. This sits squarely in the “confidence calibration for reasoning” trajectory and is timely given the proliferation of multi-hop QA evaluations.
Method maturity: Clever but simple. The authors resisted overcomplicating—they directly compare answers, no learned model, no extra training. The elegance is the insight, not the algorithm. However, a simpler baseline (e.g., checking if the final answer appears in the CoT) would have been nice to see; the paper’s strength is in the controlled comparisons they do provide.
Experimental integrity: Solid. 12 models from 4B to 671B, 4 datasets, multiple baselines (CoT-SC, semantic entropy, P(True)). They report cluster-robust p-values, controlling for multiple comparisons. The equal-cost comparison (K=3) is fair because they match inference budget. No obvious red flags—results are consistent and effect sizes are large. The only minor concern: the decomposition extraction procedure uses the model’s own CoT, which introduces a confound (the decomposition may be poor), but this is addressed in ablation (they also use human-written decompositions).
Writing quality: The abstract and introduction are clear. The paper could benefit from a standalone example walkthrough—the operad formalism might scare some readers. The “Related Work” section is terse but adequate. If I could rewrite one part, it would be Section 3 (Method): add a fully worked example with actual questions and answers to make the pipeline concrete.
Verdict: strong accept — a novel, well-executed signal for detecting compositional reasoning failures, backed by comprehensive experiments and rigorous statistics.
Takeaways
-
Decompose and check: For any multi-step reasoning task, you can derive a cheap consistency check by asking the model to decompose the problem and comparing the direct answer with the composed answer. This can be added on top of existing confidence pipelines with no training.
-
Use own CoT as decomposition: The paper shows that extracting sub-questions from the model’s own chain-of-thought works well (even when the CoT is imperfect). Practitioners can reuse existing CoT prompts.
-
Selective prediction lift: The OC signal improves accuracy-at-fixed-coverage over tuned CoT-SC when both use the same K=3 budget. This means you can filter low-OC samples and achieve higher accuracy on the remaining queries—a practical tool for deployment.
-
Transferable framing: The idea of “structural consistency” is broader than QA. It likely applies to instruction following, tool use, and any pipeline where a model’s output should be invariant under decomposition and recomposition.
论文: 2606.13649 作者: Nathaniel Bottman, Yinhong Liu, Kyle Richardson 分类: cs.CL, cs.LG
缺口
现有无标注的 LLM 推理失败检测方法分为两类:一是基于采样的方法,如自一致性(CoT-SC)和语义熵,依赖同一问题的多次独立输出; 二是自评估方法,如 P(True),让模型自我判断置信度。 两者都将模型视为黑盒,忽略了推理的结构——即模型的回答是否与其自身对问题的分解保持一致。
论文指出了一个盲区:对于组合(多跳)问题,模型无论是直接回答,还是将问题分解为子问题、逐一回答再组合结果,其最终答案应当一致。 此前没有任何工作将此作为诊断信号正式提出。 作者借用操作范畴论(一种描述迭代替换系统的形式化工具),将这一比较具体化为操作一致性(OC)。
        +------------------------------+
        | 问题:缺乏针对组合推理失败的 |
        | 无标注检测信号              |
        +-------------+---------------+
                      |
                      v
        +-------------+---------------+
        | 假设:对于组合查询,         |
        | 直接回答应等于分解后组合回答 |
        +-------------+---------------+
                      |
                      v
        +-------------+---------------+
        | 方法:计算 OC =              |
        | 一致性(直接回答,             |
        |   组合(分解(问题)))          |
        +-------------+---------------+
                      |
                      v
        +-------------+---------------+
        | 证据:OC 与准确率高度相关    |
        | (r 0.86-0.94),           |
        | 横跨12个模型、4个数据集      |
        +-------------+---------------+
                      |
                      v
        +-------------+---------------+
        | 结论:OC 是组合推理失败的     |
        | 无标注检测信号              |
        +------------------------------+
增量
一句话:本文之前,推理失败检测依赖输出统计或自评估; 本文之后,我们获得了一种结构一致性检查,利用模型自身的分解信息, 在几乎为零的额外成本下提供互补信号。
核心机制
操作一致性分为三步:
-
提取分解:给定一个多跳问题 Q,提示模型生成分解(子问题列表), 同时记录模型的直接回答 A_direct。
-
组合子回答:对每个子问题获取模型的回答, 然后定义一个组合函数将子回答合并成完整回答 A_composed。 组合方式取决于分解结构——例如,如果子问题是线性的, 可直接拼接或推导出最终答案。
-
比较:计算 A_direct 与 A_composed 之间的一致性 (精确匹配或基于词重叠的软分数)。 该一致性分数即为操作一致性得分——数值越高, 表示模型的推理越可能正确。
整个流程仅需推理、无需训练,且在 K=3 的预算下延迟增量可忽略。
                           +---------------------+
                           | 输入问题 Q          |
                           +----------+----------+
                                      |
                  +-------------------+-------------------+
                  |                                       |
                  v                                       v
     +------------+------------+             +------------+------------+
     | 将 Q 分解为子问题       |             | 直接回答:              |
     | q1..qn                 |             | A_direct = model(Q)    |
     +------------+------------+             +------------+------------+
                  |                                       |
                  v                                       |
     +------------+------------+                           |
     | 回答每个子问题          |                           |
     | -> a1 = model(q1)...   |                           |
     +------------+------------+                           |
                  |                                       |
                  v                                       |
     +------------+------------+                           |
     | 组合回答:              |                           |
     | A_composed = 组合(      |                           |
     |   a1..an )             |                           |
     +------------+------------+                           |
                  |                                       |
                  +-------+-------------------------------+
                          |
                          v
                +---------+---------+
                | 比较 A_direct     |
                | 与 A_composed     |
                | -> OC 分数       |
                +-------------------+
结构化比喻:拼图复核。 想象你有一幅已经拼好的拼图(问题 Q)。 你可以瞥一眼整体画面直接说“这是一座城堡”(直接回答), 也可以按照一张说明书的指引,先把拼图拆成四个角,逐一检查每个角, 然后在大脑中重新组合并得出结论“这是一座城堡”(分解+组合)。 如果两次结论一致,说明你对画面的理解很可能正确; 如果矛盾,说明某处出了错——可能是看错了某个角、 说明书有问题、或者你产生了幻觉。 操作一致性分数就是“结论匹配信号”。 每个组件的映射:说明书 = 分解提示; 检查每个角 = 回答子问题;大脑重组 = 组合;直接结论 = 直接回答。
关键概念
-
操作一致性(OC)
操作范畴论研究如何通过将简单组件插入“槽位”来构建复杂系统。 在多跳问题中,顶层查询有容纳子问题答案的“槽位”。 OC 检验模型是否尊重这种插入操作—— 即完整查询的输出是否等于插入子回答后的结果。 简单说,就是“模型的回答在分解下是否自洽”。 -
多跳 QA
需要跨多个事实推理的问题,例如“埃菲尔铁塔所在国家的首都是什么?” 第一跳定位法国,第二跳找到巴黎。 多跳数据集(HotpotQA, MuSiQue, StrategyQA)是天然测试床, 因为分解显式、组合定义清晰。 -
自一致性(CoT-SC)
一种基线方法:对同一问题采样多个推理路径, 然后用多数投票聚合答案。 它检测不同路径是否收敛到不同答案。 OC 不同:它只使用一条路径(分解本身), 检验内部一致性而非聚合多条路径。 两者互补——当所有路径都给出相同错误答案时, OC 可能捕捉到 CoT-SC 遗漏的结构性错误。
框架转变
核心转变从聚合分布统计转向检查结构一致性。
之前(主流方法):
   Q --> [LLM × K] --> {回答} --> 多数投票/熵 --> 置信度
   分解结构未被利用,只关心输出模式。

之后(本文方法):
   Q --> [LLM] --> A_direct
   Q --> [LLM] --> 分解 --> 子回答 --> 组合 --> A_composed
         OC = 匹配(A_direct, A_composed)
   结构被置于核心:在插入操作下的不变性揭示了失败。
从输出统计到结构一致性:旧观点将每次回答视为独立采样; 新观点利用推理中的内部依赖关系,这些依赖在分解下应保持不变。
专家评审
选题眼光:真缺口。 此前研究人员知道自一致性和语义熵有盲区(例如所有采样路径都错时), 但没人将“分解后自洽性”形式化为诊断信号。 该工作恰好在多跳 QA 评估泛滥的时机出现, 在置信度校准领域有清晰定位。
方法成熟度:巧劲而非蛮力。 作者拒绝过度复杂化——直接比较回答, 无训练、无学习模型。 洞见而非算法才是亮点。 不过,如果能提供一个更简单的基线 (例如检查最终答案是否出现在 CoT 中)会更好; 本文已做受控比较,这足以支撑结论。
实验诚意:扎实。 12 个模型(4B 至 671B)、4 个数据集、多种基线 (CoT-SC、语义熵、P(True))。 报告了聚类稳健 p 值,控制多重比较。 等成本比较(K=3)公平合理。 结果一致且效应量大。 唯一小问题是分解提取使用了模型自身的 CoT, 可能引入混淆(分解质量差时), 但作者通过分离实验(也用了人工编写的分解)加以验证。
写作功力:摘要和引言清晰。 论文最好包含一个完整示例的逐步讲解—— 操作范畴论可能吓跑部分读者。 相关工作部分简洁但够用。 若可重写,我会改进第三节(方法), 加入实际问题和回答的完整例子,使流程具体化。
判决:强接收 —— 一个新颖且执行良好的信号, 用于检测组合推理失败, 全面实验和严谨统计提供了有力支持。
要点总结
-
分解后检查:对于任何多步推理任务, 你可以通过让模型分解问题并比较直接回答与组合回答, 获得一个廉价的置信度检查, 且无需训练即可叠加到现有管线。
-
用自身 CoT 作为分解:论文表明, 即使模型自身的思维链不完美, 从中提取子问题也效果不错。 实践者可直接复用现有的 CoT 提示。
-
选择性预测提升:当 OC 与 CoT-SC 使用相同 K=3 预算时, OC 信号可提高定覆盖率下的准确率。 这意味着你可以过滤掉低 OC 样本, 在剩余查询上获得更高的准确率——一个实用的部署工具。
-
可迁移的框架:“结构一致性”思想不限于问答。 它很可能适用于指令遵循、工具使用, 以及任何模型输出应在分解和重组后保持不变的流水线。