Paper: 2605.04036 Authors: Yuwen Du, Rui Ye, Shuo Tang, Keduan Huang, Xinyu Zhu, Yuzhu Cai, Siheng Chen Categories: cs.AI, cs.CL
The Gap
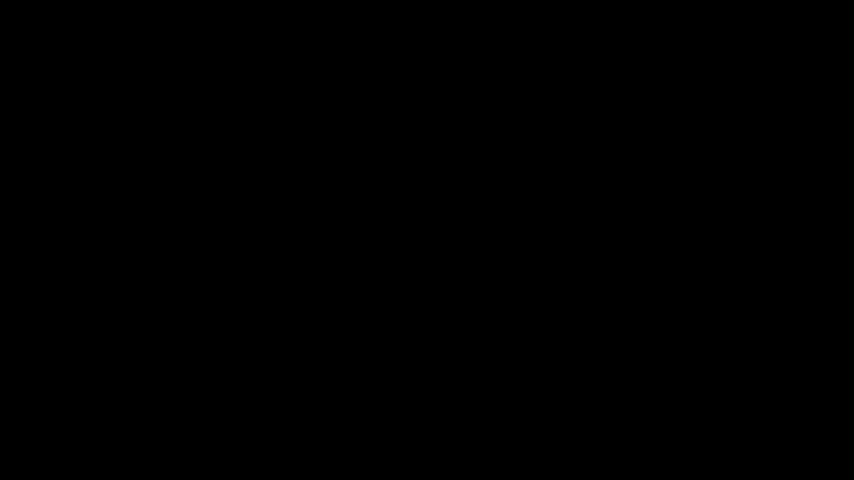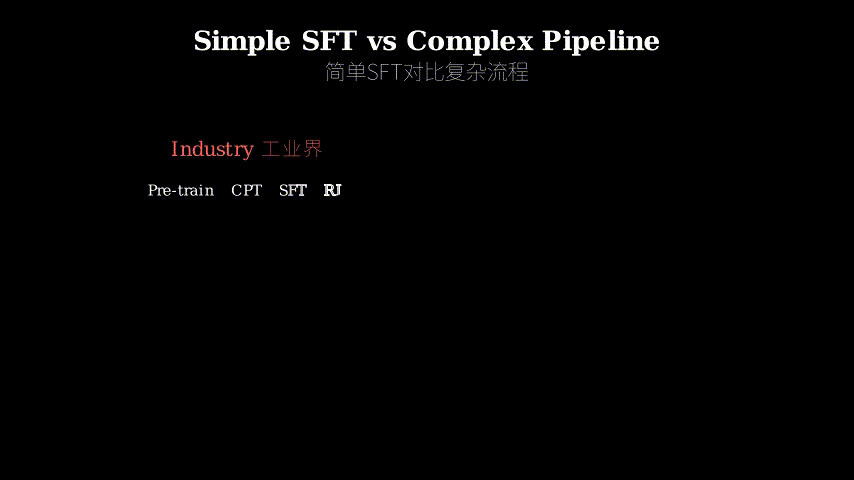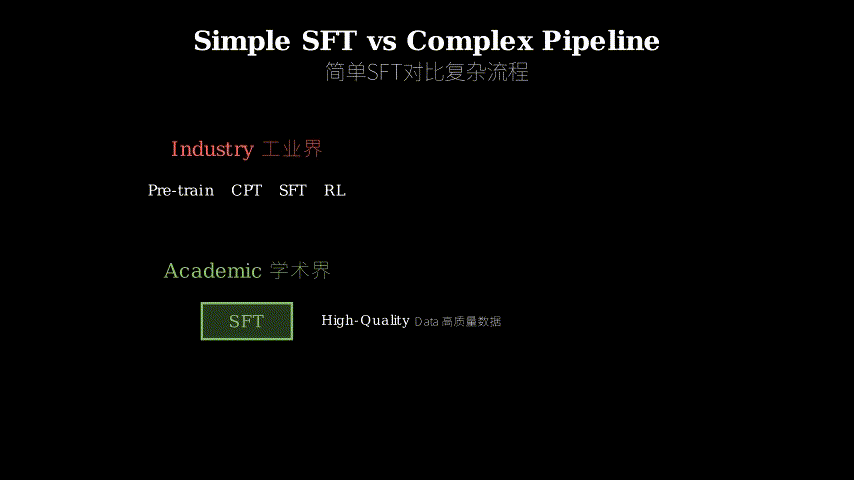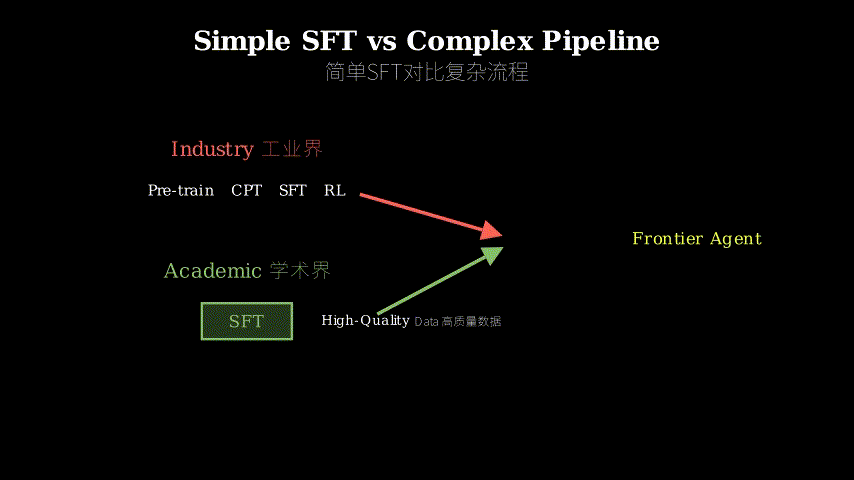
Industry has established a recipe for training frontier search agents: pre-training → continual pre-training (CPT) → supervised fine-tuning (SFT) → reinforcement learning (RL). This pipeline requires massive compute and data infrastructure that only tech giants can afford. Academic teams are effectively locked out of pushing the state-of-the-art in search agents. The assumption has been that you need all four stages to reach frontier performance.
This paper challenges that assumption. What if the bottleneck isn’t the training pipeline, but the quality and difficulty of the training data itself?
Problem: Academic teams can't compete in search agents
   |
   v
Assumption: Industry's 4-stage pipeline is necessary
   |
   v
Method: SFT-only with informative + high-difficulty data
   |
   +---> Scale knowledge graphs (richer exploration)
   +---> Expand tool sets (broader functionality)
   +---> Strict low-step filtering (harder problems)
   |
   v
Evidence: 10.6k examples → beats CPT+SFT+RL systems
   |
   v
Conclusion: Data quality > pipeline complexity
The Increment
One sentence: Before this paper, frontier search agents required industrial-scale multi-stage training; after, a 10k-example SFT dataset with the right properties can match or exceed them.
Core Mechanism
OpenSeeker-v2 synthesizes training trajectories by having an LLM agent solve complex multi-hop questions using web search and tools. The key is in how they construct these trajectories. First, they scale up the knowledge graphs used to generate questions—larger graphs force the agent to explore more diverse paths. Second, they expand the tool set beyond just search to include calculators, code execution, and knowledge retrieval, broadening the agent’s functional repertoire. Third, they apply strict filtering: only keep trajectories that solve problems in few steps, which selects for high-difficulty tasks that require efficient reasoning.
The training data flows through three stages: question generation from scaled knowledge graphs, trajectory collection via agent exploration with expanded tools, and aggressive filtering that keeps only the hardest 10.6k examples. Each trajectory is a complete search session—query formulation, tool calls, information synthesis, and final answer.
Knowledge Graph (scaled) --> Question Generator
                                    |
                                    v
                            Complex Questions
                                    |
                                    v
                    Agent (expanded tool set) --> Trajectories
                                                      |
                                                      v
                                            Low-step Filter
                                                      |
                                                      v
                                            10.6k Hard Examples
                                                      |
                                                      v
                                                SFT Training
Think of it like training a chess player. The industry approach is like having them play millions of games at all skill levels, then getting coaching, then competing in tournaments with feedback loops. OpenSeeker-v2 instead curates 10,000 master-level games where every move matters—no filler, no easy wins. The player studies only these dense, instructive games. The knowledge graph scaling is like expanding the opening book so the player sees more board positions. The tool expansion is like teaching them endgame techniques beyond just piece movement. The low-step filtering is like keeping only games where both sides played near-perfectly and the outcome hinged on deep calculation. You learn more from one Kasparov game than from a hundred beginner matches.
Key Concepts
-
Informative trajectories: A trajectory is informative when it demonstrates non-trivial reasoning patterns that generalize. In search agents, this means the path from question to answer involves multiple decision points where the agent must choose between plausible alternatives. For example, answering “What was the GDP of the country that hosted the 2008 Olympics in the year before?” requires: (1) identifying the host country (China), (2) determining the target year (2007), (3) retrieving the GDP figure. An uninformative trajectory might have the answer directly in the first search result. An informative one requires the agent to chain facts across multiple sources. The paper achieves this by scaling knowledge graphs—larger graphs naturally produce questions whose answers aren’t co-located in single documents.
-
High-difficulty filtering: Not all hard problems are useful for training. A problem is high-difficulty in the useful sense when it can be solved efficiently by an expert but requires sophisticated reasoning. The paper’s “strict low-step filtering” keeps only trajectories that solve complex problems in few steps. This filters out two failure modes: (1) easy problems that happen to take many steps due to inefficient search, and (2) impossible problems where the agent thrashes. What remains are problems that demand tight, purposeful reasoning—the agent must plan ahead, use tools strategically, and synthesize information cleanly. It’s the difference between a maze with one long path (high step count, low difficulty) and a maze with many dead ends that requires backtracking intelligence (low step count, high difficulty).
Framework Shift
Before (Industry Pipeline):          After (OpenSeeker-v2):

Pre-training (general)               [Skip - use base model]
       |                                      |
       v                                      v
CPT (domain adapt)                   Data Synthesis:
       |                              - Scale KG size
       v                              - Expand tools
SFT (task learning)                  - Filter hard cases
       |                                      |
       v                                      v
RL (optimization)                    SFT (10.6k examples)
       |                                      |
       v                                      v
Frontier Agent                       Frontier Agent

Resource: Massive                    Resource: Modest
Stages: 4                            Stages: 1
Focus: Pipeline depth                Focus: Data quality
From multi-stage pipeline optimization to single-stage data curation, the core shift is trading compute breadth for data depth.
Expert Assessment
Problem choice: This is a real and important gap. The democratization of frontier AI capabilities matters for research velocity and institutional diversity. The problem sits at the intersection of efficiency research and capability research—showing that academic teams can compete changes the field’s power dynamics.
Method maturity: The approach is refreshingly simple but not simplistic. The three modifications (scale KG, expand tools, filter hard) are individually straightforward, but their combination is non-obvious. The insight that data difficulty can substitute for pipeline complexity is clever. However, there’s a lurking question: are they discovering a new training paradigm, or are they just distilling the outputs of existing strong models more efficiently? The trajectories are generated by LLMs that were themselves trained with industrial pipelines.
Experimental integrity: The baselines are fair and the benchmarks are diverse (BrowseComp, BrowseComp-ZH, Humanity’s Last Exam, xbench). The comparison to Tongyi DeepResearch is particularly meaningful since it represents the full industrial pipeline. The numbers are strong across the board. One minor concern: the paper doesn’t deeply analyze failure modes or provide error analysis. What kinds of queries does OpenSeeker-v2 still fail on? Are there systematic gaps?
Writing quality: The paper is clear and well-structured. The abstract efficiently conveys the main result. The method section could be stronger—the three modifications are described but not deeply motivated. Why these three specifically? Were others tried? The related work section does a good job positioning the work but could engage more critically with prior SFT-only attempts. The conclusion is appropriately humble about limitations.
Verdict: strong accept — Demonstrates that academic teams can achieve frontier search agent performance with orders of magnitude less resources by focusing on data quality over pipeline complexity, with strong empirical results across multiple benchmarks.
Takeaways
For practitioners building agents: Don’t default to complex multi-stage pipelines. Invest in data curation first. Specifically: (1) Generate training data from harder problem distributions—scale up the complexity of your source materials. (2) Filter aggressively for efficiency—keep only examples where the agent solves hard problems in few steps. (3) Expand the action space during data collection even if you don’t use all tools at inference—it forces the model to learn when to use what.
For researchers: This paper provides a template for academic teams to compete in domains dominated by industry. The key is identifying which components of the industrial recipe are load-bearing and which are cargo cult. Here, CPT and RL turned out to be less critical than data quality. Look for similar opportunities in other domains where the assumed “necessary” pipeline might be overkill.
Transferable technique: The “strict low-step filtering” heuristic is broadly applicable. In any sequential decision-making domain, you can filter training data for examples that achieve complex goals efficiently. This selects for demonstrations of planning and strategic thinking rather than trial-and-error. It’s a simple proxy for “this example contains compressed expertise.”
论文: 2605.04036 作者: Yuwen Du, Rui Ye, Shuo Tang, Keduan Huang, Xinyu Zhu, Yuzhu Cai, Siheng Chen 分类: cs.AI, cs.CL
缺口
工业界已经确立了训练前沿搜索智能体的配方:预训练 → 持续预训练(CPT)→ 监督微调(SFT)→ 强化学习(RL)。
这条流水线需要海量的算力和数据基础设施,只有科技巨头才负担得起。
学术团队实际上被锁在了推动搜索智能体最优性能的大门之外。
此前的假设是:你需要全部四个阶段才能达到前沿性能。
本文挑战了这个假设。
如果瓶颈不在训练流水线,而在训练数据本身的质量和难度呢?
问题:学术团队无法在搜索智能体上竞争
   |
   v
假设:工业界的四阶段流水线是必需的
   |
   v
方法:仅用SFT + 信息丰富且高难度的数据
   |
   +---> 扩大知识图谱(更丰富的探索)
   +---> 扩展工具集(更广泛的功能)
   +---> 严格的低步数过滤(更难的问题)
   |
   v
证据:1.06万样本 → 击败CPT+SFT+RL系统
   |
   v
结论:数据质量 > 流水线复杂度
增量
一句话:这篇论文之前,前沿搜索智能体需要工业级的多阶段训练;之后,一个具有正确属性的1万样本SFT数据集就能匹敌甚至超越它们。
核心机制
OpenSeeker-v2通过让LLM智能体使用网络搜索和工具解决复杂的多跳问题来合成训练轨迹。
关键在于他们如何构造这些轨迹。
首先,他们扩大了用于生成问题的知识图谱——更大的图谱迫使智能体探索更多样化的路径。
其次,他们将工具集扩展到搜索之外,包括计算器、代码执行和知识检索,拓宽了智能体的功能范围。
第三,他们应用严格的过滤:只保留用少量步骤解决问题的轨迹,这筛选出了需要高效推理的高难度任务。
训练数据流经三个阶段:从扩大的知识图谱生成问题,通过带扩展工具的智能体探索收集轨迹,以及激进的过滤只保留最难的1.06万个样本。
每条轨迹都是一个完整的搜索会话——查询构造、工具调用、信息综合和最终答案。
知识图谱(扩大)--> 问题生成器
                        |
                        v
                    复杂问题
                        |
                        v
        智能体(扩展工具集)--> 轨迹
                                  |
                                  v
                            低步数过滤
                                  |
                                  v
                        1.06万困难样本
                                  |
                                  v
                            SFT训练
把它想象成训练一个国际象棋选手。
工业界的方法就像让他们在所有技能水平上下数百万盘棋,然后接受指导,然后在有反馈循环的锦标赛中竞争。
OpenSeeker-v2则是精选1万盘大师级对局,每一步都很关键——没有填充,没有轻松获胜。
选手只研究这些密集、有启发性的对局。
知识图谱扩大就像扩展开局库,让选手看到更多棋盘局面。
工具扩展就像教他们超越单纯移动棋子的残局技巧。
低步数过滤就像只保留双方都近乎完美发挥、结果取决于深度计算的对局。
你从一盘卡斯帕罗夫的对局中学到的,比从一百盘初学者对局中学到的更多。
关键概念
- 信息丰富的轨迹:当一条轨迹展示了可泛化的非平凡推理模式时,它就是信息丰富的。
在搜索智能体中,这意味着从问题到答案的路径涉及多个决策点,智能体必须在看似合理的备选方案之间做出选择。
例如,回答”2008年奥运会主办国在前一年的GDP是多少?“需要:(1)识别主办国(中国),(2)确定目标年份(2007),(3)检索GDP数字。
一条信息贫乏的轨迹可能在第一个搜索结果中就直接有答案。
一条信息丰富的轨迹需要智能体跨多个来源串联事实。
本文通过扩大知识图谱来实现这一点——更大的图谱自然产生答案不在单个文档中共同定位的问题。
- 高难度过滤:并非所有困难问题都对训练有用。
一个问题在有用意义上是高难度的,当它可以被专家高效解决但需要复杂推理时。
本文的”严格低步数过滤”只保留用少量步骤解决复杂问题的轨迹。
这过滤掉了两种失败模式:(1)由于低效搜索而碰巧需要很多步骤的简单问题,(2)智能体反复尝试的不可能问题。
剩下的是需要紧凑、有目的推理的问题——智能体必须提前规划,策略性地使用工具,干净地综合信息。
这就像迷宫只有一条长路径(高步数,低难度)和有许多死胡同需要回溯智能的迷宫(低步数,高难度)之间的区别。
框架转变
之前(工业流水线):              之后(OpenSeeker-v2):

预训练(通用)                    [跳过 - 使用基础模型]
     |                                    |
     v                                    v
CPT(领域适配)                   数据合成:
     |                             - 扩大KG规模
     v                             - 扩展工具
SFT(任务学习)                   - 过滤困难案例
     |                                    |
     v                                    v
RL(优化)                        SFT(1.06万样本)
     |                                    |
     v                                    v
前沿智能体                        前沿智能体

资源:海量                        资源:适度
阶段:4                           阶段:1
焦点:流水线深度                  焦点:数据质量
从多阶段流水线优化到单阶段数据策展,核心转变是用算力广度换数据深度。
专家评审
选题眼光:这是一个真实且重要的缺口。
前沿AI能力的民主化对研究速度和机构多样性很重要。
这个问题位于效率研究和能力研究的交叉点——证明学术团队可以竞争改变了该领域的权力动态。
方法成熟度:这个方法令人耳目一新地简单,但不简陋。
三个修改(扩大KG、扩展工具、过滤困难)单独来看都很直接,但它们的组合并不显而易见。
数据难度可以替代流水线复杂度的洞察很巧妙。
然而,有一个潜在的问题:他们是在发现一种新的训练范式,还是只是更高效地蒸馏现有强模型的输出?轨迹是由本身用工业流水线训练的LLM生成的。
实验诚意:基线公平,基准多样(BrowseComp、BrowseComp-ZH、Humanity’s Last Exam、xbench)。
与通义深度研究的比较特别有意义,因为它代表了完整的工业流水线。
数字在各方面都很强。
一个小担忧:论文没有深入分析失败模式或提供错误分析。
OpenSeeker-v2在什么类型的查询上仍然失败?有系统性的差距吗?
写作功力:论文清晰且结构良好。
摘要有效地传达了主要结果。
方法部分可以更强——三个修改被描述了但没有深入动机。
为什么特别是这三个?尝试过其他的吗?相关工作部分很好地定位了工作,但可以更批判性地讨论之前的仅SFT尝试。
结论对局限性适当谦虚。
判决:强接收 — 证明了学术团队可以通过关注数据质量而非流水线复杂度,用少几个数量级的资源达到前沿搜索智能体性能,在多个基准上有强大的实证结果。
要点总结
对于构建智能体的实践者:不要默认使用复杂的多阶段流水线。
首先投资于数据策展。
具体来说:(1)从更难的问题分布生成训练数据——扩大源材料的复杂度。
(2)激进地过滤效率——只保留智能体用少量步骤解决困难问题的样本。
(3)在数据收集期间扩展动作空间,即使你在推理时不使用所有工具——它迫使模型学习何时使用什么。
对于研究者:本文为学术团队在工业主导的领域竞争提供了模板。
关键是识别工业配方的哪些组件是承重的,哪些是货物崇拜。
在这里,CPT和RL被证明不如数据质量关键。
在其他领域寻找类似的机会,假定的”必要”流水线可能是过度的。
可迁移技术:“严格低步数过滤”启发式广泛适用。
在任何顺序决策领域,你都可以过滤训练数据,寻找高效实现复杂目标的样本。
这选择了规划和战略思维的演示,而不是试错。
这是”此样本包含压缩专业知识”的简单代理。