Paper: 2607.02510 Authors: Mona Schirmer, Metod Jazbec, Alexander Timans, Christian Naesseth, Maja Waldron, Eric Nalisnick Categories: cs.AI, cs.CL, cs.LG, stat.AP, stat.ML
The Gap
So, you’re deploying a large language model. You’ve done your best to align it, but you know it can still go off the rails in the wild—generating harmful content, hallucinating wildly, or giving dangerous advice. The core problem is real-time safety monitoring. Existing approaches either require expensive, slow classifiers run on every output (like another LLM doing a safety check), or they use methods from sequential hypothesis testing (like SPRT). The issue with the latter is they often rely on strong statistical assumptions that don’t hold in practice, or they’re just computationally heavy. The field needed a simpler, more statistically rigorous way to decide: “Is this LLM’s stream of outputs still safe, or do I need to shut it down right now?”
Problem: LLM safety degrades unpredictably at deployment.
Assumption: We have an external "verifier" that scores output safety (0 to 1).
Method: Set a fixed threshold on the score to raise an alarm.
Gap: How to choose the threshold? Ad-hoc tuning has no safety guarantee.
Solution: Use risk control to calibrate the threshold for a desired false alarm rate.
Evidence: Simple thresholding matches or beats complex sequential tests on math & red-team tasks.
Conclusion: A principled, simple, and effective monitor is viable.
The Increment
One sentence: Before this paper, real-time LLM safety monitoring required complex, assumption-heavy statistical tests; after, a simple, calibrated threshold is shown to be equally effective and far more practical.
Core Mechanism
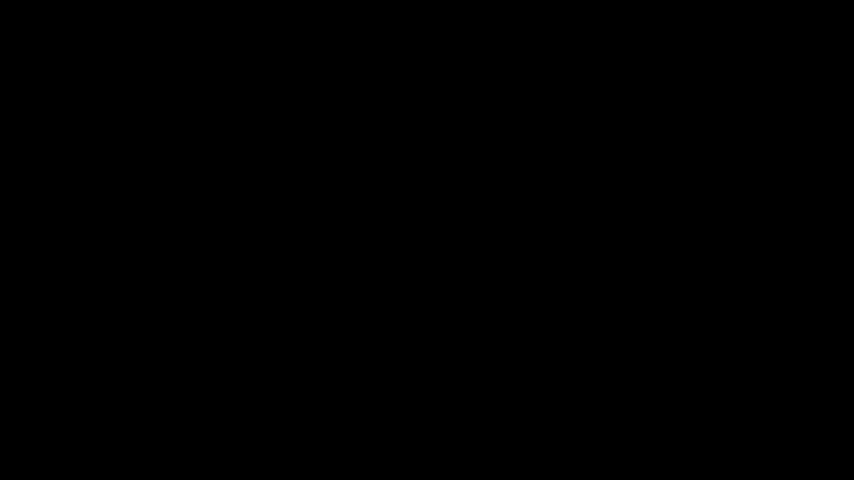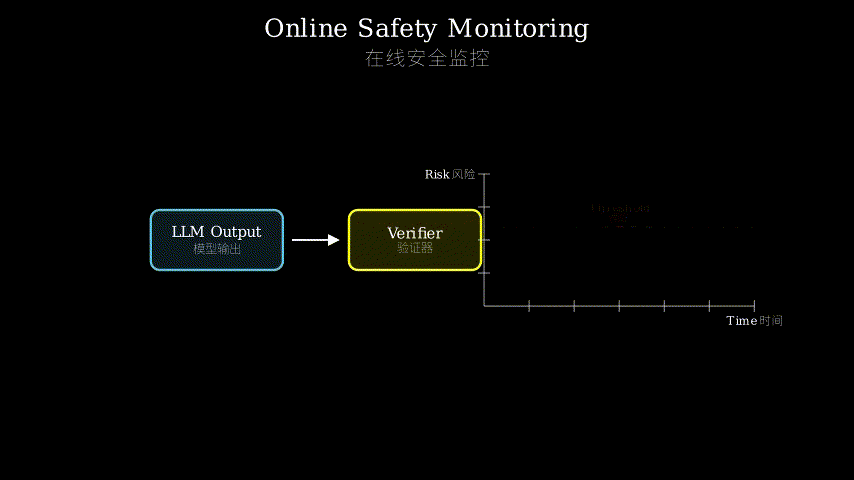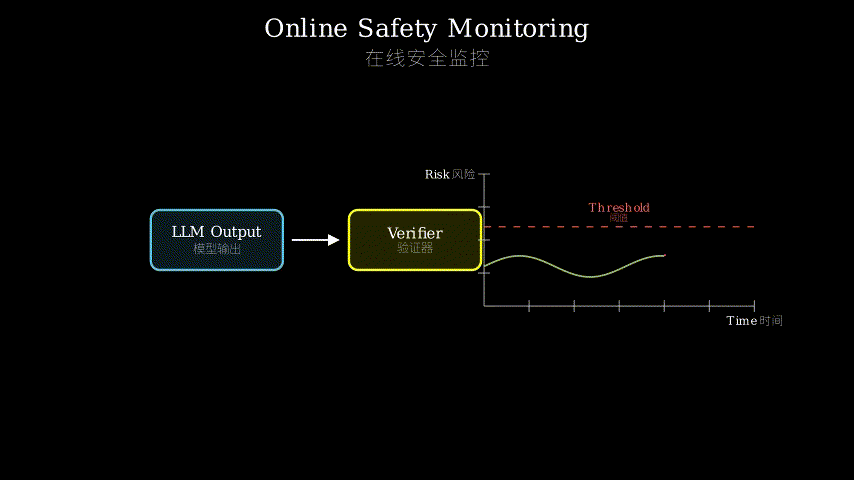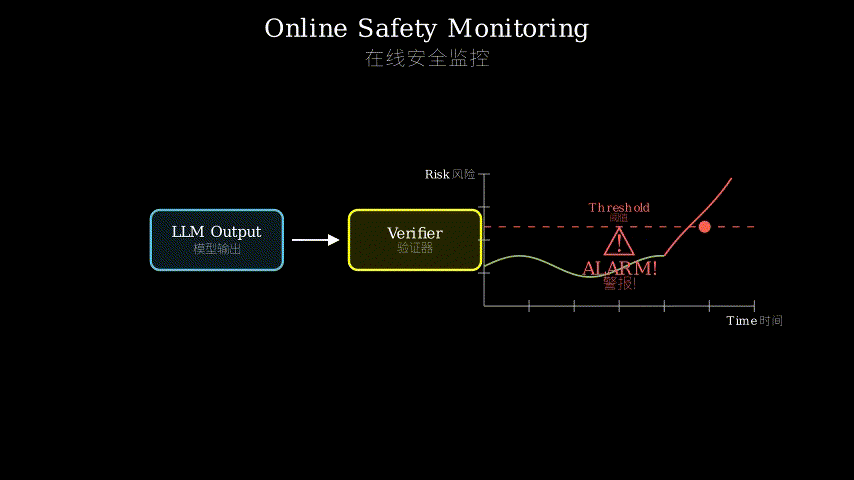
The method is beautifully straightforward. First, you have your deployed LLM generating a stream of outputs. For each output, a separate, trusted model (the “verifier”) produces a safety score, like a probability that the output is unsafe. The monitoring system’s only job is to look at these scores over time and sound an alarm if things look bad. The innovation is in how it decides “bad.”
Instead of using a moving average or a complex sequential test, it applies a fixed threshold to the safety score. If the score for any single output exceeds this threshold, the alarm is raised immediately. The magic is in how this threshold, let’s call it τ, is set. It’s not picked by gut feeling. The authors use risk control techniques. You start with a desired false alarm rate (e.g., “I want at most a 5% chance of raising a false alarm on safe outputs”). You then use a calibration dataset of known-safe outputs to find the value of τ that empirically achieves this rate. In essence, you’re statistically guaranteeing that the alarm won’t cry wolf more often than you’re comfortable with.
[LMM Output] --> [Verifier Model] --> [Safety Score (0-1)]
                                          |
                                          v
                               +-------------------+
                               |  Threshold (τ)    |
                               |  (Calibrated via  |
                               |   risk control)   |
                               +-------------------+
                                          |
                                          v
                              [Alarm if Score > τ]
Think of it like a smoke detector in a server room. The “verifier” is a sensitive sensor that measures particle density in the air (the safety score). The old way to decide if there’s a fire was to analyze the pattern of particle readings over time with a complex algorithm (sequential testing). This paper’s way is to set a single, scientifically calibrated particle density threshold on the sensor. If the reading ever crosses it, the sprinklers go off. You calibrate the threshold not by guessing, but by testing it in a room with controlled, safe amounts of dust to ensure it almost never goes off accidentally. The result is a system that’s dead simple to implement, fast, and statistically reliable.
Key Concepts
- Risk Control: This is the key statistical tool. Imagine you’re designing a spam filter. You want it to catch spam, but you *really don’t want it to delete important emails (false positives). Risk control lets you say, “I am willing to accept that, at most, 1 in 100 important emails gets wrongly flagged.” You then tune your filter’s sensitivity on a set of known important emails until it meets that strict 1% error rate. This paper does the same thing for safety alarms: it calibrates the threshold to control the “false alarm rate” on safe data.
- Verifier Signal: This is the external “judge.” The paper doesn’t focus on building this judge. It assumes you have a model that can look at an LLM’s output and produce a scalar score indicating how unsafe it is (e.g., a toxicity classifier). The monitor’s job is purely to make a robust decision based on this signal. The elegance is separating the *detection problem (the verifier) from the decision problem (the monitor).
Framework Shift
Before (mainstream approach):        After (this paper):
[Stream of LLM outputs]             [Stream of LLM outputs]
         |                                    |
         v                                    v
[Complex Sequential Hypothesis Test] [Simple Threshold on Verifier Score]
(Tracks cumulative evidence,        (Decision on each output,
 needs distribution assumptions,     threshold calibrated with
 computationally intensive)          statistical risk control)
         |                                    |
         v                                    v
[Alarm based on pattern analysis]    [Alarm based on single-event crossing]
From complex pattern analysis to single-event decision rules, the core shift is trusting a well-calibrated simple rule over a complicated one.
Expert Assessment
Problem choice: Excellent. Real-time safety monitoring for deployed LLMs is a critical, underexplored practical problem. It sits at the intersection of ML deployment, statistics, and AI safety—a very relevant spot.
Method maturity: High. The insight is clever in its simplicity. They realized that the sequential testing approach was overkill if you could calibrate a threshold properly. They leveraged mature statistical tools (risk control) in a novel context. Simpler approaches *were being overlooked in favor of more complex ones that sounded more “academic.”
Experimental integrity: Solid. They compare against meaningful baselines (fixed thresholds, CUSUM, SPRT) on relevant datasets (math reasoning, red-teaming). The key results are convincing: the simple calibrated threshold performs as well as or better than the more complex methods, especially in terms of balancing detection rate and false alarms. A minor note: they rely on a pre-trained verifier model, so the overall system’s performance is bounded by the verifier’s quality.
Writing quality: Very clear and well-structured. The paper reads like a good systems paper: problem, simple idea, solid validation. The “Related Work” section could be slightly deeper in contrasting with the practical deployment constraints of methods like SPRT, but this is minor.
Verdict: strong accept — A clean, practical, and well-validated solution to an important problem that demonstrates the power of applying basic statistical principles correctly.
Takeaways
The main stealable idea is the application of risk control to operational thresholds. If you have any system that needs to make a binary decision (alarm/no-alarm, flag/not-flag, pass/fail) based on a continuous score, and you have historical data on the “normal” class, you can use risk control to set that decision threshold with a formal guarantee on your false positive rate. This applies far beyond LLM safety—think anomaly detection in metrics, quality control in manufacturing, or fraud detection in finance. The paper provides a cookbook for making a “good enough” rule statistically rigorous.
论文: 2607.02510 作者: Mona Schirmer, Metod Jazbec, Alexander Timans, Christian Naesseth, Maja Waldron, Eric Nalisnick 分类: cs.AI, cs.CL, cs.LG, stat.AP, stat.ML
缺口
部署大语言模型时,即使经过对齐训练,它仍可能在运行中输出不安全内容。 实时监控这些输出,一旦发现危险苗头就立即报警,至关重要。 现有的监控方法主要有两种思路: 一是用另一个模型(如分类器)对每条输出进行安全评分,然后基于此做决策。 二是借鉴序列假设检验(如SPRT)的统计方法。 但前者决策依据往往不明确,后者则依赖于难以验证的强统计假设,且计算复杂。 领域内缺少一种既简单、又在统计上足够严谨的实时监控方法。
问题:LLM在部署时安全性能会不可预测地退化。
假设:我们拥有一个外部“验证器”,能为每条输出打出安全分(0到1)。
方法:设定一个固定阈值,分数超标即报警。
缺口:阈值如何选取?凭感觉调优缺乏安全保证。
解决方案:使用风险控制来校准阈值,以达到期望的误报率。
证据:在数学推理和对抗性数据集上,简单的阈值法与复杂的序列测试法效果相当甚至更好。
结论:一种有原则、简单且有效的监控器是可行的。
增量
一句话:在此之前,实时监控LLM安全需要复杂且假设繁多的统计检验;在此之后,一个经过校准的简单阈值被证明同样有效且远为实用。
核心机制
这个方法的核心简洁得漂亮。 首先,你的被部署LLM在持续生成输出流。 对每一条输出,一个独立、可信的模型(“验证器”)会给出一个安全评分,比如该输出不安全的概率。 监控系统的任务就是观察这些评分序列,并在情况不妙时发出警报。 创新之处在于它如何定义“不妙”。
它没有使用移动平均或复杂的序列检验,而是对安全评分应用一个固定阈值(记为 τ)。
如果任何单条输出的评分超过这个阈值,警报立即响起。
魔法发生在这个阈值 τ 的设定上。
它不是凭直觉选的。
作者使用了风险控制技术。
你先定义一个期望的误报率(例如:“我允许在安全输出上产生误报的概率不超过5%”)。
然后,你使用一个包含已知安全输出的校准数据集,通过经验找到能实际达到该误报率的 τ 值。
本质上,你在统计上保证了警报“误报”的频率不会超过你所能接受的水平。
[LLM输出] --> [验证器模型] --> [安全评分(0-1)]
                                        |
                                        v
                              +---------------------+
                              |  阈值(τ)          |
                              |  (通过风险控制校准)|
                              +---------------------+
                                        |
                                        v
                              [若评分 > τ 则报警]
把它想象成服务器机房的烟雾报警器。 “验证器”就是一个敏感的粒子密度传感器(输出安全评分)。 旧的方法判断是否着火,是用一个复杂算法去分析粒子读数的时序模式(序列检验)。 而本文的方法,就是基于科学校准,给传感器设定一个单一的粒子密度阈值。 一旦读数超过它,喷淋系统就启动。 你校准阈值不是靠猜,而是通过在受控的、安全的粉尘环境中测试,确保它几乎不会误报。 结果就是一个实现极其简单、响应飞快、且统计上可靠的系统。
关键概念
- 风险控制:这是核心的统计工具。 假设你在设计垃圾邮件过滤器。 你想拦截垃圾邮件,但你绝对不想误删重要邮件(假阳性)。 风险控制允许你声明:“我最多能接受1%的重要邮件被错误标记。” 然后,你在一组已知的重要邮件上调整过滤器的灵敏度,直到满足这个严格的1%错误率。 本文对安全警报做了同样的事:它校准阈值,以控制在安全数据上的“误报率”。
- 验证器信号:这是外部的“裁判”。 本文不专注于构建这个裁判。 它假设你拥有一个模型,能查看LLM的输出,并生成一个标量分数,指示其不安全的程度(例如,毒性分类器)。 监控器的职责纯粹是基于这个信号做出稳健的决策。 其巧妙之处在于将检测问题(验证器)与决策问题(监控器)分离开来。
框架转变
之前(主流方法):                之后(本文方法):
[LLM输出流]                      [LLM输出流]
       |                                 |
       v                                 v
[复杂序列假设检验]               [基于验证器评分的简单阈值]
(跟踪累积证据,                (对每条输出做决策,
 需要分布假设,                  阈值通过统计风险控制校准)
 计算量大)                             |
       |                                 v
       v                     [基于单一事件超限的报警]
[基于模式分析的报警]
从复杂的模式分析到基于单一事件的决策规则,核心转变是相信一个校准良好的简单规则胜过一个复杂规则。
专家评审
选题眼光:优秀。 实时监控已部署的LLM安全是一个关键且探索不足的实际问题。 它处于ML部署、统计和AI安全的交叉点——位置非常相关。
方法成熟度:高。 其洞见在于用简单性制胜。 他们意识到,如果能够正确校准阈值,序列检验方法就显得大材小用了。 他们在新的场景中利用了成熟的风险控制统计工具。 更简单的方法确实曾被忽视,学者们更偏爱听起来更“学术”的复杂方法。
实验诚意:扎实。 他们与有意义的基线(固定阈值、CUSUM、SPRT)在相关数据集(数学推理、对抗性测试)上进行了比较。 关键结果令人信服:简单校准阈值的表现与更复杂方法相当甚至更好,尤其是在检测率和误报率的平衡上。 一个小注意点:他们依赖一个预训练的验证器模型,因此整个系统的性能受限于该验证器的质量。
写作功力:非常清晰,结构良好。 论文读起来像一篇好的系统论文:问题、简单想法、扎实验证。 “相关工作”部分在对比SPRT等方法的实际部署约束方面可以稍深入,但这无伤大雅。
判决:强接收 — 一个清晰、实用且经过充分验证的解决方案,针对一个重要问题,展示了正确应用基础统计原理的力量。
要点总结
最值得“偷”走的核心思想是将风险控制应用于操作阈值。 如果你的系统需要基于一个连续分数做出二元决策(报警/不报警,标记/不标记,通过/不通过),并且你拥有“正常”类别的历史数据,那么你就可以使用风险控制来设定该决策阈值,并对你假阳性率做出形式化保证。 这远远超出了LLM安全的范畴——想想指标异常检测、制造业质量控制或金融欺诈检测。 这篇论文提供了一个“如何将足够好的规则变得统计上严谨”的操作手册。