Paper: 2603.16856 Authors: Tianzhu Ye, Li Dong, Qingxiu Dong, Xun Wu, Shaohan Huang, Furu Wei Categories: cs.CL
The Gap
LLMs are trained offline — on curated datasets, human annotations, or simulated rollouts — and then frozen at deployment. Once a model is live, every interaction it has, every mistake it makes, every clever shortcut it discovers, vanishes. The model that served user #1,000,000 is identical to the one that served user #1. That’s a massive waste.
Prior work has tried to close this loop in a few ways. RLHF and DPO use human feedback, but require expensive annotation pipelines and don’t scale to continuous deployment. Online RL (like in game-playing agents) can adapt in real time, but it requires the training process to have live access to the environment — which is often impossible when the environment is a user’s private system or a third-party service. Retrieval-augmented approaches can surface past trajectories at inference time, but they don’t actually update the model’s weights, so the “learning” is shallow and context-dependent.
The specific gap: there’s no principled way to take the raw experience a deployed model accumulates and turn it into durable, weight-level improvements — especially when the training process can’t reach back into the deployment environment.
Problem: Deployed LLMs don't learn from experience
    |
    v
Assumption: Raw trajectories contain transferable knowledge,
            but are too noisy to distill directly
    |
    v
Method: Extract -> Accumulate -> Distill (on-policy)
    |
    v
Evidence: Consistent gains over iterations on text games,
          better token efficiency, OOD performance preserved
    |
    v
Conclusion: On-policy context distillation from extracted
            knowledge closes the offline/online gap
The Increment
One sentence: Before this paper, deployment experience was a dead end; after it, there’s a concrete two-stage loop that turns interaction history into weight-level improvements without needing live environment access.
Core Mechanism
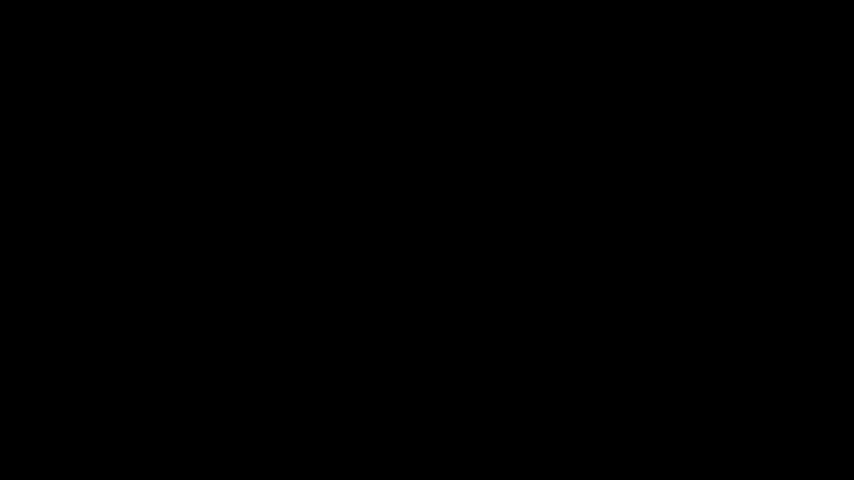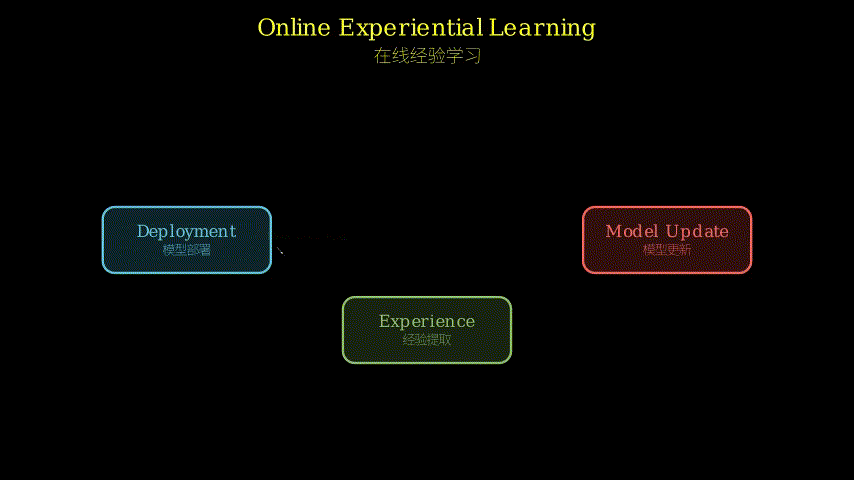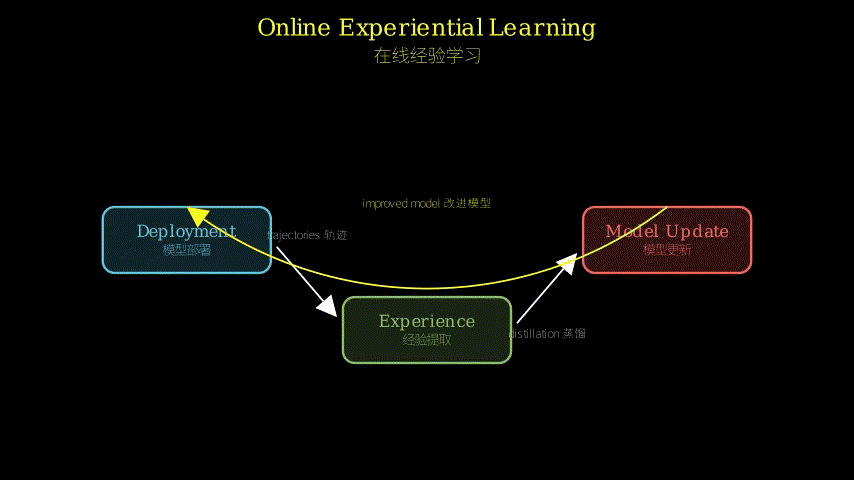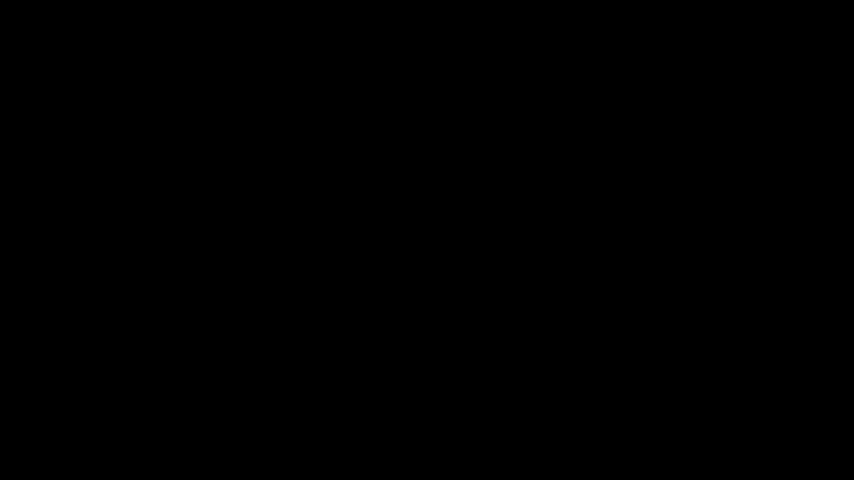
OEL has two alternating stages that form a closed loop. In Stage 1 (knowledge extraction), the deployed model collects interaction trajectories from real users. These raw trajectories are messy — they contain failed attempts, redundant steps, and model-specific reasoning that doesn’t generalize. So a knowledge extractor (likely a prompted LLM) processes these trajectories and distills them into compact, transferable “experiential knowledge” — think of it as lessons learned, stripped of the noise.
In Stage 2 (knowledge consolidation), this extracted knowledge is used to update the model’s weights via on-policy context distillation. The key constraint here is that Stage 2 has no access to the original user-side environment. Instead, the extracted knowledge is treated as context, and the model is trained to internalize it — to produce the same outputs it would if it had that knowledge in context, but without needing the context at inference time. This is the “distillation” part: compress the knowledge from context into weights.
The loop then closes: the improved model goes back to deployment, collects better trajectories (because it’s smarter now), which yield richer extracted knowledge, which leads to better distillation in the next round. Each iteration compounds.
  Deployment                    Training
  (user side)                   (model side)
      |                              |
  [Model v_n]                        |
      |                              |
  collects trajectories              |
      |                              |
  [Raw Trajectories]                 |
      |                              |
  [Knowledge Extractor]              |
      |                              |
  [Experiential Knowledge] --------> |
                                     |
                              [On-Policy Context
                               Distillation]
                                     |
                              [Model v_(n+1)] ---> back to deployment
Think of it like a chef who works a busy restaurant service (deployment), then at the end of the night writes up a clean recipe card summarizing what worked (knowledge extraction), and then drills those techniques until they’re muscle memory (distillation). The next service, they’re faster and more precise. The raw chaos of the dinner rush doesn’t go directly into the recipe card — it gets filtered and formalized first. And the recipe card doesn’t stay on the counter during service — it gets internalized so the chef can cook without looking at notes. That’s the whole loop: experience → lesson → muscle memory → better experience.
Key Concepts
-
On-policy context distillation: Regular knowledge distillation trains a student model to mimic a teacher’s outputs. Context distillation is a variant where the “teacher” is the same model but with extra context prepended (e.g., “here’s what you learned last week”). The student learns to produce those outputs without the context. “On-policy” means the student being trained is the same model that generated the trajectories — this matters because if you train model A on trajectories from model B, there’s a distribution mismatch that hurts learning. The paper argues this consistency is critical.
-
Transferable experiential knowledge: Raw trajectories are like a transcript of someone fumbling through a task. Transferable knowledge is the extracted principle — “when you see X, do Y, not Z.” The extraction step is what separates OEL from naive replay-based methods. The paper shows empirically that extracted knowledge significantly outperforms raw trajectories as a training signal.
-
Online learning loop: Not “online” in the web sense, but in the ML sense — the model updates based on data it generates itself during deployment, rather than a fixed offline dataset. The loop structure means improvements compound: better model → better data → better model.
Framework Shift
Before (mainstream approach):        After (this paper):

  [Offline Data]                       [Deployment]
       |                                    |
  [Train Once]                        [Trajectories]
       |                                    |
  [Deploy]                           [Extract Knowledge]
       |                                    |
  [Collect Experience] --> /dev/null   [Distill into Weights]
                                            |
                                       [Better Model]
                                            |
                                       [Back to Deployment]
                                            ^
                                            |_____(loop)
From static offline training to a living feedback loop, the core shift is: deployment experience is no longer discarded, it’s the training signal.
Expert Assessment
Problem choice: This is a real gap, not a manufactured one. The “deployed models don’t learn” problem is obvious to anyone who’s run a production LLM system. The specific contribution — handling the case where training can’t access the deployment environment — is a practically important constraint that prior work glosses over. The field is clearly moving toward continual learning for LLMs, and this paper is a reasonable early stake in the ground.
Method maturity: The two-stage design is clean and the on-policy consistency argument is well-motivated. That said, the knowledge extraction step is doing a lot of heavy lifting and relies on a prompted LLM — which means the quality of extracted knowledge depends on the extractor’s capability, and the paper doesn’t deeply analyze failure modes here. It’s a clever insight, but the extraction step feels underspecified. A skeptic could ask: isn’t this just “use a strong LLM to summarize your logs and fine-tune on the summaries”? The answer is yes, roughly, but the on-policy distillation framing and the iterative loop are the real contributions.
Experimental integrity: Text-based games are a reasonable testbed — they have clear reward signals and controllable complexity. Testing across multiple model scales and thinking/non-thinking variants is good practice. The OOD evaluation is a nice touch; many continual learning papers ignore catastrophic forgetting entirely. That said, text games are a narrow domain. The paper would be significantly stronger with one real-world deployment scenario (even a synthetic one that’s more realistic than a game). The baselines seem fair but the paper would benefit from a stronger ablation on the extractor quality.
Writing quality: The paper is technically clear but the knowledge extraction step — arguably the most novel and fragile part — gets the least scrutiny. The section describing how extraction actually works (what prompts, what format, what failure modes) reads like it was written last and under time pressure. Rewriting that section with concrete examples of raw trajectory → extracted knowledge would make the whole paper more convincing.
Verdict: weak accept — solid problem, clean framing, but the extraction mechanism needs more rigorous treatment and the evaluation domain is too narrow to fully trust the generalization claims.
Takeaways
A few concrete things worth stealing:
-
The “extract then distill” pattern is broadly applicable. If you have noisy demonstration data (from users, from simulations, from web scraping), don’t fine-tune on it raw — run it through an extraction step first to get clean, generalizable principles. This is underused in practice.
-
On-policy consistency as a design constraint. When building any self-improvement loop, make sure the model generating the training signal is the same model (or a close ancestor) being trained. Distribution mismatch between data source and policy is a silent killer in these setups.
-
The iterative loop structure — where each round’s improved model generates better training data for the next round — is a general recipe for compounding gains in any domain where you can collect deployment feedback. The paper gives you a concrete instantiation to adapt.
论文: 2603.16856 作者: Tianzhu Ye, Li Dong, Qingxiu Dong, Xun Wu, Shaohan Huang, Furu Wei 分类: cs.CL
缺口
大语言模型的训练是离线的——用精心整理的数据集、人工标注或模拟环境跑完训练,然后冻结权重,部署上线。
模型上线之后,它经历的每一次交互、犯下的每一个错误、摸索出的每一个捷径,全部消失。 服务了第一百万个用户的模型,和服务第一个用户时一模一样。 这是巨大的浪费。
前人尝试过几种方式来弥合这个裂缝。 RLHF 和 DPO 依赖人工反馈,标注成本高,无法持续扩展。 在线强化学习(比如游戏智能体)可以实时适应,但要求训练过程能直接访问环境——而当环境是用户的私有系统或第三方服务时,这往往做不到。 检索增强方法可以在推理时调出历史轨迹,但不更新模型权重,“学习”是浅层的、依赖上下文的。
具体的缺口在于:没有一种有原则的方式,能把部署中积累的原始经验转化为持久的、权重层面的改进——尤其是在训练过程无法触及部署环境的情况下。
问题:已部署的 LLM 无法从经验中学习
    |
    v
假设:原始轨迹包含可迁移知识,
      但噪声太大,无法直接蒸馏
    |
    v
方法:提取 -> 积累 -> 策略蒸馏
    |
    v
证据:在文字游戏上多轮迭代持续提升,
      token 效率更高,OOD 性能保留
    |
    v
结论:基于提取知识的策略蒸馏
      能有效弥合离线/在线的鸿沟
增量
一句话:这篇论文之前,部署经验是死路一条;之后,有了一个具体的两阶段循环,能把交互历史转化为权重层面的改进,且不需要访问原始环境。
核心机制
OEL 由两个交替进行的阶段构成,形成一个闭合循环。
第一阶段是知识提取。 部署中的模型从真实用户那里收集交互轨迹。 这些原始轨迹很嘈杂——包含失败尝试、冗余步骤、以及模型特有的、不具泛化性的推理过程。 因此,一个知识提取器(通常是一个被提示的 LLM)处理这些轨迹,将其蒸馏成紧凑的、可迁移的”经验知识”——可以理解为去除噪声后的经验教训。
第二阶段是知识固化。 提取出的知识通过策略蒸馏写回模型权重。 关键约束是:第二阶段无法访问用户侧的原始环境。 取而代之的是,将提取的知识作为上下文,训练模型将其内化——让模型在没有上下文的情况下,也能产生与有上下文时相同的输出。 这就是”蒸馏”:把知识从上下文压缩进权重。
循环随即闭合:改进后的模型回到部署,收集更好的轨迹(因为它更聪明了),产生更丰富的提取知识,带来下一轮更好的蒸馏。 每一轮都在复利积累。
  部署侧(用户端)                训练侧(模型端)
      |                              |
  [模型 v_n]                         |
      |                              |
  收集交互轨迹                        |
      |                              |
  [原始轨迹]                          |
      |                              |
  [知识提取器]                        |
      |                              |
  [经验知识] -----------------------> |
                                     |
                              [策略上下文蒸馏]
                                     |
                              [模型 v_(n+1)] ---> 回到部署
                                        ^
                                        |_______(循环)
用一个比喻来理解整个流程:想象一位厨师在繁忙的餐厅服务(部署),收工后把今晚哪道菜出了问题、哪个手法奏效,整理成一张干净的食谱卡(知识提取),然后反复练习直到形成肌肉记忆(蒸馏)。 下一次服务,他更快、更精准。 晚餐高峰的混乱不会直接变成食谱卡——它先被过滤和提炼。 食谱卡也不会在服务时摆在台面上——它被内化了,厨师不需要看笔记就能烹饪。 这就是整个循环:经验 → 教训 → 肌肉记忆 → 更好的经验。
关键概念
-
策略上下文蒸馏(On-policy context distillation):普通知识蒸馏是让学生模型模仿教师模型的输出。上下文蒸馏是一种变体:把同一个模型加上额外上下文(比如”这是你上周学到的”)当作”教师”,训练学生在没有上下文的情况下产生相同输出。“策略上”(on-policy)意味着被训练的模型和生成轨迹的模型是同一个——如果用模型 B 的轨迹训练模型 A,分布不匹配会严重损害学习效果。论文认为这种一致性至关重要。
-
可迁移经验知识(Transferable experiential knowledge):原始轨迹就像一份记录某人摸索完成任务的逐字稿。可迁移知识是提取出来的原则——“遇到 X 时,做 Y 而不是 Z”。提取步骤是 OEL 区别于朴素回放方法的关键。论文实验表明,提取后的知识作为训练信号,显著优于原始轨迹。
-
在线学习循环(Online learning loop):这里的”在线”是机器学习意义上的——模型基于自己在部署中生成的数据进行更新,而不是固定的离线数据集。循环结构意味着改进会复利:更好的模型 → 更好的数据 → 更好的模型。
框架转变
之前(主流方法):                    之后(本文方法):

  [离线数据]                           [部署]
      |                                   |
  [一次性训练]                        [收集轨迹]
      |                                   |
  [部署上线]                         [提取知识]
      |                                   |
  [积累经验] --> /dev/null            [蒸馏进权重]
                                          |
                                     [更好的模型]
                                          |
                                     [回到部署]
                                          ^
                                          |______(循环)
从静态的离线训练到活的反馈循环,核心转变是:部署经验不再被丢弃,它本身就是训练信号。
专家评审
选题眼光:这是真缺口,不是人造的。 “已部署模型不会学习”这个问题,任何跑过生产 LLM 系统的人都感受过。 论文聚焦的具体约束——训练侧无法访问部署环境——是一个实践中非常重要、但前人常常绕过的限制。 持续学习显然是 LLM 领域的下一个战场,这篇论文是一个合理的早期占位。
方法成熟度:两阶段设计干净,策略一致性的论证有说服力。 但知识提取步骤承担了大量工作,依赖一个被提示的 LLM——这意味着提取质量取决于提取器的能力,而论文对这里的失败模式分析不足。 是巧劲,但提取步骤感觉规格不够清晰。 怀疑论者会问:这不就是”用强 LLM 总结你的日志,然后在摘要上微调”吗? 大致是的,但策略蒸馏的框架和迭代循环才是真正的贡献。
实验诚意:文字游戏是合理的测试床——有清晰的奖励信号,复杂度可控。 在多个模型规模和思考/非思考变体上测试是好习惯。 OOD 评估是加分项,很多持续学习论文完全忽略灾难性遗忘。 但文字游戏领域太窄了。 如果能有一个更贴近真实部署的场景(哪怕是合成的),论文说服力会强很多。 基线看起来公平,但对提取器质量的消融实验可以更深入。
写作功力:论文技术上清晰,但知识提取步骤——可以说是最新颖也最脆弱的部分——得到的审视最少。 描述提取如何实际运作的那一节(用什么提示、什么格式、什么失败模式),读起来像是最后赶工写的。 如果用具体例子展示”原始轨迹 → 提取知识”的转化过程,整篇论文的说服力会上一个台阶。
判决:弱接收——问题选得好,框架清晰,但提取机制需要更严格的处理,评估领域太窄,泛化性主张难以完全信服。
要点总结
几个值得直接拿走用的东西:
第一,“先提取再蒸馏”的模式有广泛适用性。 如果你手头有嘈杂的示范数据(来自用户、模拟、网络爬取),不要直接在原始数据上微调——先跑一个提取步骤,得到干净的、可泛化的原则。 这在实践中被严重低估。
第二,策略一致性作为设计约束。 构建任何自我改进循环时,确保生成训练信号的模型和被训练的模型是同一个(或近亲)。 数据来源和策略之间的分布不匹配是这类系统的隐形杀手。
第三,迭代循环结构本身——每轮改进后的模型为下一轮生成更好的训练数据——是一个通用配方,适用于任何能收集部署反馈的领域。 论文给了你一个具体的实例可以直接改造。