Paper: 2604.14149 Authors: Zheyu Zhang, Ziqi Pang, Shixing Chen, Xiang Hao, Vimal Bhat, Yu-Xiong Wang Categories: cs.CV
The Gap
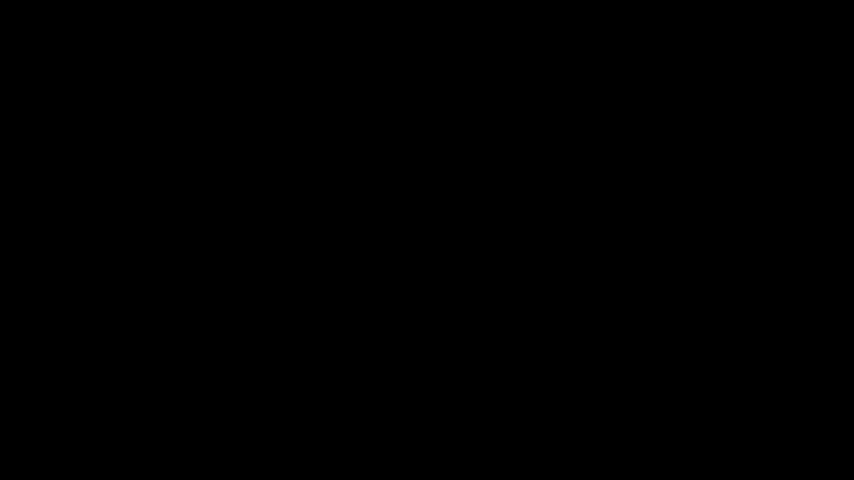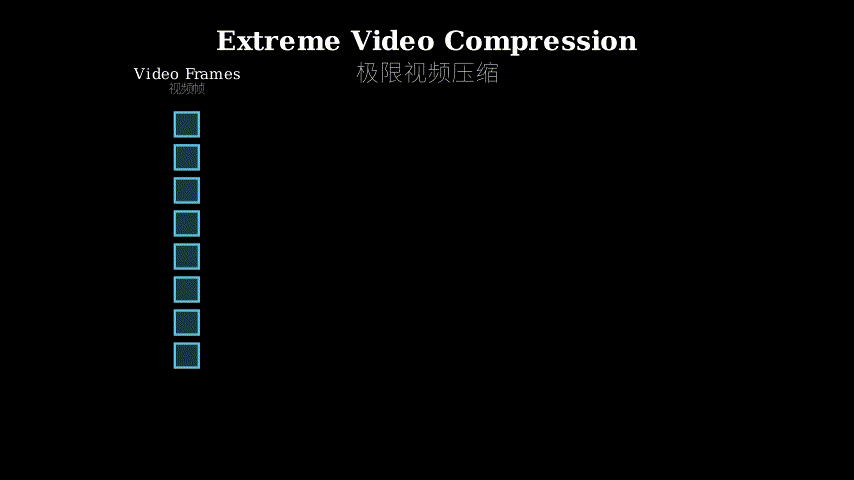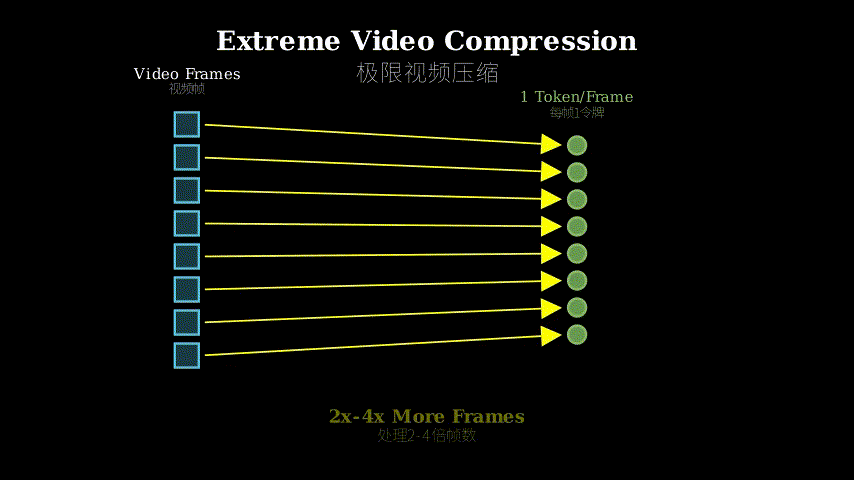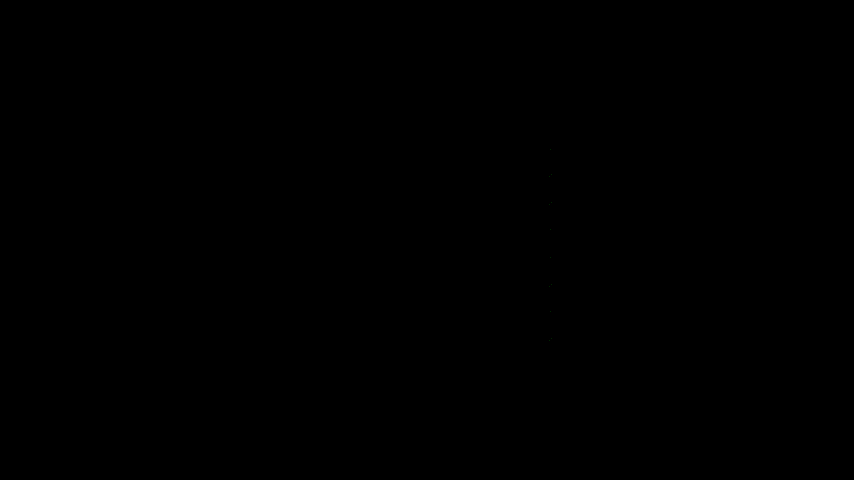
Vision-language models (VLMs) for video understanding hit a hard wall: each frame explodes into tens or hundreds of tokens, and LLMs have fixed context windows. Existing approaches like VideoChat, LLaVA-Video, and LongVA use heuristic compression (uniform sampling, clustering, pooling) to fit videos into context limits. The problem? Heuristics are blind to what matters. They compress before knowing the question, lose temporal coherence, and still can’t handle truly long videos densely.
The specific boundary: prior work achieves ~10-20 tokens per frame at best, forcing sparse sampling (1 FPS or less for hour-long videos). This creates a trilemma: sample densely and run out of tokens, sample sparsely and miss events, or use heuristics and lose information.
Problem: Long video (1000s frames) + Limited context (4K-32K tokens)
   |
   v
Assumption: Compression must be (1) learnable not heuristic
            (2) progressive across LLM layers (3) query-aware
   |
   v
Method: LP-Comp (token-level) + QC-Comp (frame-level)
   |
   v
Evidence: 1 token/frame, 2-4x denser sampling, +3.3% on LVBench
   |
   v
Conclusion: Extreme compression enables dense long video understanding
The Increment
One sentence: Before this paper, VLMs compressed videos heuristically before processing; after, compression is learned progressively through LLM layers and conditioned on the question, achieving 1 token per frame.
Core Mechanism
The method has two compression stages working in tandem. First, LP-Comp (Learnable Progressive Compression) operates at the token level within each frame. Instead of heuristically pooling frame tokens before the LLM, it inserts lightweight compression modules between LLM layers. Each module learns to merge tokens progressively—early layers preserve detail, deeper layers aggressively compress. By the final layer, each frame is squeezed to exactly one token. This is supervised: the model is trained to predict which tokens to merge using ground-truth labels from attention patterns.
Second, QC-Comp (Question-Conditioned Compression) operates at the frame level. After LP-Comp produces one token per frame, QC-Comp selects which frames to keep based on the question. It uses the LLM’s internal attention scores—specifically, how much the question tokens attend to each frame token—as a relevance signal. Frames with high attention survive; others are dropped. Crucially, to avoid LLM’s position bias (over-attending to start/end), videos are split into short segments and local attention is computed within each segment.
Input: Video frames (N frames, each ~100 tokens)
   |
   v
[LP-Comp: Token-level compression]
   Layer 1-8:  100 tokens/frame -> 50 tokens/frame
   Layer 9-16: 50 tokens/frame  -> 10 tokens/frame
   Layer 17+:  10 tokens/frame  -> 1 token/frame
   |
   v
Intermediate: N frames, 1 token each
   |
   v
[QC-Comp: Frame-level compression]
   Split into segments -> Compute local attention
   -> Rank frames by question relevance
   -> Keep top K frames
   |
   v
Output: K frames (K << N), 1 token each -> LLM final layers
Think of it like packing for a trip with a tiny suitcase. LP-Comp is folding each piece of clothing (frame) into the smallest possible bundle—you start by folding loosely (early layers), then tighter and tighter (deeper layers) until each item is vacuum-sealed to a single compact cube. QC-Comp is then deciding which cubes to actually pack based on your itinerary (the question)—if you’re going to the beach, you keep swimwear cubes and ditch the winter coat cubes. The segment-based attention is like checking each cube’s relevance within its category (tops, bottoms, accessories) rather than comparing a swimsuit directly to a winter coat, which would be biased by their positions in your closet.
Key Concepts
-
Progressive compression across LLM layers: Traditional VLMs compress video tokens before feeding them to the LLM—it’s a one-shot, all-or-nothing operation. Progressive compression instead spreads the compression across the LLM’s depth. Early layers see high-resolution token representations and learn semantic groupings. Middle layers merge related tokens. Deep layers perform aggressive compression. Why does this work? Because LLM layers naturally form a hierarchy of abstraction—early layers capture low-level features, deep layers capture high-level semantics. By aligning compression with this hierarchy, the model can make informed decisions about what to discard at each level. Concrete example: In a cooking video, early layers might preserve tokens for “hand,” “knife,” “onion” separately; middle layers merge “hand + knife” into “cutting action”; final layers compress the entire frame to “food preparation.”
-
Attention-based frame selection with position bias mitigation: LLMs exhibit position bias in long contexts—they over-attend to the first and last tokens, even if middle tokens are more relevant. This is catastrophic for video understanding: if you ask “What happened in the middle of the video?” the model might still focus on the opening and closing frames. The solution: split the video into short segments (e.g., 10 frames each) and compute attention locally within each segment. Now, within each segment, the “first” and “last” positions rotate, so every frame gets a fair chance to be selected based on actual relevance, not position. Example: In a 100-frame video, instead of computing attention over all 100 frames (where frames 1, 2, 99, 100 dominate), split into 10 segments of 10 frames each, compute attention within each segment, then aggregate. Frame 50 can now be selected if it’s relevant to the question, even though it’s in the middle.
-
Supervised compression tuning: The compression modules (which tokens to merge, which frames to keep) need to learn what’s important. But “importance” is task-dependent—what matters for action recognition differs from what matters for question answering. Supervised compression tuning trains these modules using a small amount of labeled data (2.5% of the full fine-tuning dataset) where the model learns to compress in a way that preserves task-relevant information. The supervision signal comes from comparing compressed vs. uncompressed representations on downstream tasks. Think of it like training a summarizer: you don’t just teach it to shorten text, you teach it to shorten text while preserving the answer to specific questions.
Framework Shift
Before (mainstream approach):        After (this paper):

Video frames                         Video frames
     |                                    |
     v                                    v
[Heuristic compression]              [LLM Layer 1-8]
(pooling/sampling)                        |
     |                                    v
     v                               [LP-Comp module]
[Fixed tokens]                       (merge tokens)
     |                                    |
     v                                    v
[LLM processes]                      [LLM Layer 9-16]
     |                                    |
     v                                    v
[Output]                             [LP-Comp module]
                                     (merge more)
                                          |
                                          v
                                     [LLM Layer 17+]
                                          |
                                          v
                                     [1 token/frame]
                                          |
                                          v
                                     [QC-Comp: frame selection]
                                          |
                                          v
                                     [Output]

Compression: Before LLM              Compression: During + After LLM
Decision: Blind to content           Decision: Informed by layers + query
From blind pre-compression to informed progressive compression, the core shift is making compression a learned, query-aware process integrated into the model’s reasoning, not a preprocessing step.
Expert Assessment
Problem choice: Real gap. Long video understanding is a genuine bottleneck—hour-long videos are increasingly common (lectures, surveillance, movies), and current VLMs choke on them. The trilemma (dense sampling vs. context limits vs. information loss) is not manufactured. However, the problem sits in a crowded space—many recent papers (LongVA, VideoChat2, LLaMA-VID) tackle the same issue. The novelty is in the solution approach, not the problem identification.
Method maturity: Clever insight with some brute force. The progressive compression idea is elegant—it aligns with how LLMs naturally process information hierarchically. The attention-based frame selection is smart. But the position bias mitigation (splitting into segments) feels like a workaround rather than a principled solution—it’s patching an LLM limitation rather than addressing it. Also, the method requires a separate supervised compression tuning stage, which adds complexity. A simpler approach might be end-to-end training with a compression loss, but the authors don’t explore this.
Experimental integrity: Baselines are fair—they compare against strong recent models (VideoChat-Flash, LLaVA-Video). The numbers are solid: +3.3% on LVBench, improvements on EgoSchema, VideoMME. However, there’s a red flag: the supervised compression tuning uses only 2.5% of data, yet yields large gains. This suggests the base model (VideoChat-Flash) was undertrained or poorly tuned for long videos. The gains might be partially from better training, not just better compression. Also, the paper doesn’t report inference speed—extreme compression should speed things up, but no numbers are provided.
Writing quality: The paper is dense and assumes familiarity with recent VLM literature. The method section jumps between token-level and frame-level compression without clearly delineating them first—a reader unfamiliar with the space will get lost. The ablation studies are thorough, but buried in the appendix. If the authors rewrote Section 3 to first give a high-level overview (two-stage compression: token then frame), then dive into each stage separately, the paper would be far more accessible. Also, the name “XC” (extreme compression) is generic and unmemorable.
Verdict: Weak accept — solid contribution to a real problem, but incremental over recent work and the writing could be clearer. The method is clever but not groundbreaking, and the experimental gains, while consistent, are modest.
Takeaways
Progressive compression across model layers: Don’t compress all at once before your model. If your model has a hierarchical structure (like transformers), insert compression modules at multiple depths. Early layers preserve detail, deep layers compress aggressively. This is applicable beyond video—think long documents, multi-image inputs, or time-series data.
Attention scores as a relevance signal: If you need to select a subset of inputs based on a query, use your model’s internal attention scores. They’re already computed, they’re query-conditioned, and they’re free. Just watch out for position bias in long sequences.
Segment-based processing to mitigate position bias: If your model over-attends to the start/end of long sequences, split the sequence into short segments and process locally. This is a simple, effective hack for any long-context task.
Supervised compression tuning as a separate stage: If your compression is learnable, you can train it with a small amount of labeled data (2-5% of your full dataset) as a separate stage. This is data-efficient and lets you adapt compression to specific tasks without full retraining.
论文: 2604.14149 作者: Zheyu Zhang, Ziqi Pang, Shixing Chen, Xiang Hao, Vimal Bhat, Yu-Xiong Wang 分类: cs.CV
缺口
视觉语言模型(VLM)在视频理解上撞了南墙:每一帧会膨胀成几十上百个令牌,而大语言模型(LLM)的上下文窗口是固定的。
现有方法如VideoChat、LLaVA-Video、LongVA使用启发式压缩(均匀采样、聚类、池化)把视频塞进上下文限制里。
问题在哪?启发式方法对重要信息视而不见。
它们在知道问题之前就压缩,丢失时间连贯性,仍然无法密集处理真正的长视频。
具体边界:现有工作最多做到每帧约10-20个令牌,迫使稀疏采样(小时级视频只能1 FPS或更低)。
这造成了一个三难困境:密集采样会耗尽令牌,稀疏采样会错过事件,使用启发式会丢失信息。
问题:长视频(数千帧)+ 有限上下文(4K-32K令牌)
   |
   v
假设:压缩必须(1)可学习而非启发式
     (2)跨LLM层渐进(3)查询感知
   |
   v
方法:LP-Comp(令牌级)+ QC-Comp(帧级)
   |
   v
证据:每帧1令牌,2-4倍密集采样,LVBench +3.3%
   |
   v
结论:极限压缩实现密集长视频理解
增量
一句话:这篇论文之前,VLM在处理前启发式压缩视频;之后,压缩通过LLM层渐进学习并以问题为条件,达到每帧1个令牌。
核心机制
该方法有两个协同工作的压缩阶段。
首先,LP-Comp(可学习渐进式压缩)在每帧内的令牌级别操作。
它不是在LLM之前启发式池化帧令牌,而是在LLM层之间插入轻量级压缩模块。
每个模块学习渐进式合并令牌——早期层保留细节,深层激进压缩。
到最后一层,每帧被压缩到恰好一个令牌。
这是有监督的:模型被训练使用来自注意力模式的真实标签来预测合并哪些令牌。
其次,QC-Comp(问题条件压缩)在帧级别操作。
LP-Comp为每帧生成一个令牌后,QC-Comp根据问题选择保留哪些帧。
它使用LLM的内部注意力分数——具体来说,问题令牌对每个帧令牌的关注程度——作为相关性信号。
高注意力的帧存活;其他被丢弃。
关键是,为了避免LLM的位置偏差(过度关注序列开头和结尾),视频被分割成短片段,在每个片段内计算局部注意力。
输入:视频帧(N帧,每帧约100令牌)
   |
   v
[LP-Comp:令牌级压缩]
   第1-8层:  100令牌/帧 -> 50令牌/帧
   第9-16层: 50令牌/帧  -> 10令牌/帧
   第17+层:  10令牌/帧  -> 1令牌/帧
   |
   v
中间状态:N帧,每帧1令牌
   |
   v
[QC-Comp:帧级压缩]
   分割成片段 -> 计算局部注意力
   -> 按问题相关性排序帧
   -> 保留前K帧
   |
   v
输出:K帧(K << N),每帧1令牌 -> LLM最终层
把它想象成用一个小行李箱打包旅行。
LP-Comp是把每件衣服(帧)折叠成尽可能小的包——你开始时松松地折(早期层),然后越折越紧(深层),直到每件物品都被真空压缩成一个紧凑的立方体。
QC-Comp然后根据你的行程(问题)决定实际打包哪些立方体——如果你去海滩,你保留泳装立方体,扔掉冬季外套立方体。
基于片段的注意力就像在每个类别(上衣、裤子、配饰)内检查每个立方体的相关性,而不是直接比较泳装和冬季外套,后者会因为它们在衣柜中的位置而产生偏差。
关键概念
- 跨LLM层的渐进式压缩:传统VLM在将视频令牌送入LLM之前压缩它们——这是一次性的、全有或全无的操作。
渐进式压缩则将压缩分散到LLM的深度上。
早期层看到高分辨率令牌表示并学习语义分组。
中间层合并相关令牌。
深层执行激进压缩。
为什么有效?因为LLM层自然形成抽象层次——早期层捕获低级特征,深层捕获高级语义。
通过将压缩与这个层次对齐,模型可以在每个级别做出明智的决定,决定丢弃什么。
具体例子:在烹饪视频中,早期层可能分别保留”手”、“刀”、“洋葱”的令牌;中间层将”手+刀”合并为”切割动作”;最终层将整个帧压缩为”食物准备”。
- 基于注意力的帧选择与位置偏差缓解:LLM在长上下文中表现出位置偏差——它们过度关注第一个和最后一个令牌,即使中间令牌更相关。
这对视频理解是灾难性的:如果你问”视频中间发生了什么?“模型可能仍然关注开头和结尾帧。
解决方案:将视频分割成短片段(例如每段10帧)并在每个片段内局部计算注意力。
现在,在每个片段内,“第一”和”最后”位置轮换,所以每一帧都有公平的机会根据实际相关性而非位置被选中。
例子:在100帧视频中,不是对所有100帧计算注意力(其中帧1、2、99、100占主导),而是分成10个10帧片段,在每个片段内计算注意力,然后聚合。
如果帧50与问题相关,现在可以被选中,即使它在中间。
- 监督压缩调优:压缩模块(合并哪些令牌,保留哪些帧)需要学习什么是重要的。
但”重要性”取决于任务——动作识别重要的内容与问答重要的内容不同。
监督压缩调优使用少量标注数据(完整微调数据集的2.5%)训练这些模块,模型学习以保留任务相关信息的方式压缩。
监督信号来自在下游任务上比较压缩与未压缩表示。
把它想象成训练一个摘要器:你不只是教它缩短文本,而是教它在缩短文本的同时保留特定问题的答案。
框架转变
之前(主流方法):                之后(本文方法):

视频帧                            视频帧
     |                                 |
     v                                 v
[启发式压缩]                      [LLM第1-8层]
(池化/采样)                          |
     |                                 v
     v                            [LP-Comp模块]
[固定令牌]                        (合并令牌)
     |                                 |
     v                                 v
[LLM处理]                         [LLM第9-16层]
     |                                 |
     v                                 v
[输出]                            [LP-Comp模块]
                                  (进一步合并)
                                       |
                                       v
                                  [LLM第17+层]
                                       |
                                       v
                                  [每帧1令牌]
                                       |
                                       v
                                  [QC-Comp:帧选择]
                                       |
                                       v
                                  [输出]

压缩:LLM之前                     压缩:LLM期间+之后
决策:对内容盲目                  决策:由层+查询告知
从盲目的预压缩到知情的渐进式压缩,核心转变是使压缩成为一个学习的、查询感知的过程,集成到模型的推理中,而不是预处理步骤。
专家评审
选题眼光:真实缺口。
长视频理解是真正的瓶颈——小时级视频越来越常见(讲座、监控、电影),当前VLM在它们面前卡壳。
三难困境(密集采样 vs 上下文限制 vs 信息丢失)不是人造的。
然而,这个问题处于拥挤的空间——许多近期论文(LongVA、VideoChat2、LLaMA-VID)解决同样的问题。
新颖性在于解决方案方法,而非问题识别。
方法成熟度:巧妙洞察加一些蛮力。
渐进式压缩想法很优雅——它与LLM自然分层处理信息的方式对齐。
基于注意力的帧选择很聪明。
但位置偏差缓解(分割成片段)感觉像是权宜之计而非原则性解决方案——它在修补LLM限制而非解决它。
此外,该方法需要单独的监督压缩调优阶段,增加了复杂性。
更简单的方法可能是带压缩损失的端到端训练,但作者没有探索这个。
实验诚意:基线公平——他们与强大的近期模型(VideoChat-Flash、LLaVA-Video)比较。
数字扎实:LVBench +3.3%,EgoSchema、VideoMME上有改进。
然而,有一个警示信号:监督压缩调优只使用2.5%的数据,却产生大幅增益。
这表明基础模型(VideoChat-Flash)对长视频训练不足或调优不佳。
增益可能部分来自更好的训练,而不仅仅是更好的压缩。
此外,论文没有报告推理速度——极限压缩应该加速,但没有提供数字。
写作功力:论文密集,假设读者熟悉近期VLM文献。
方法部分在令牌级和帧级压缩之间跳跃,没有先清楚地划分它们——不熟悉该领域的读者会迷失。
消融研究很彻底,但埋在附录里。
如果作者重写第3节,首先给出高层概述(两阶段压缩:令牌然后帧),然后分别深入每个阶段,论文会更易理解。
此外,名称”XC”(极限压缩)很通用且不易记。
判决:弱接收——对真实问题的扎实贡献,但相对近期工作是增量式的,写作可以更清晰。
方法巧妙但不是突破性的,实验增益虽然一致,但适度。
要点总结
跨模型层的渐进式压缩:不要在模型之前一次性压缩所有内容。
如果你的模型有分层结构(如transformer),在多个深度插入压缩模块。
早期层保留细节,深层激进压缩。
这适用于视频之外——想想长文档、多图像输入或时间序列数据。
注意力分数作为相关性信号:如果你需要根据查询选择输入子集,使用模型的内部注意力分数。
它们已经计算好了,它们是查询条件的,而且是免费的。
只需注意长序列中的位置偏差。
基于片段的处理以缓解位置偏差:如果你的模型过度关注长序列的开头/结尾,将序列分割成短片段并局部处理。
这是任何长上下文任务的简单有效技巧。
监督压缩调优作为单独阶段:如果你的压缩是可学习的,你可以用少量标注数据(完整数据集的2-5%)作为单独阶段训练它。
这是数据高效的,让你无需完全重新训练就能使压缩适应特定任务。