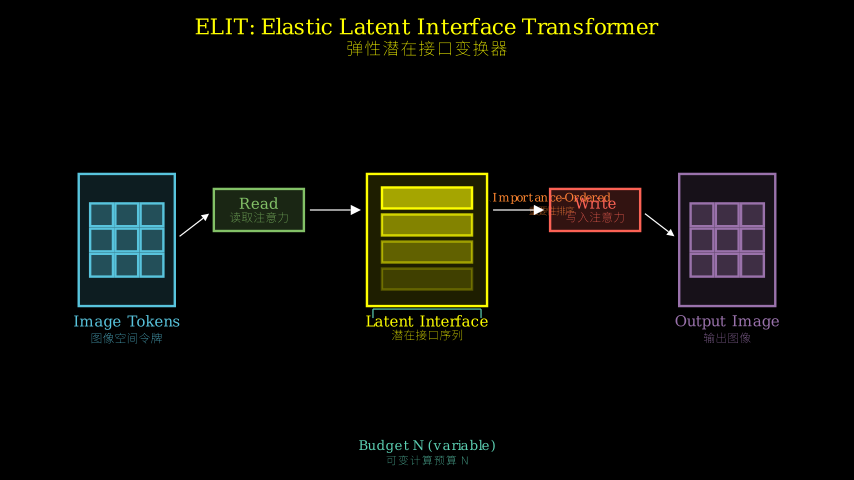
Paper: 2603.12245 Authors: Moayed Haji-Ali, Willi Menapace, Ivan Skorokhodov, Dogyun Park, Anil Kag, Michael Vasilkovsky, Sergey Tulyakov, Vicente Ordonez, Aliaksandr Siarohin Categories: cs.CV
The Gap
Diffusion Transformers (DiTs) are the current backbone of high-quality image generation — think Stable Diffusion 3, FLUX, and similar systems. They work by treating image patches as tokens and running self-attention over them. The problem: transformer self-attention scales quadratically with the number of tokens, and the number of tokens is directly tied to image resolution. Want a 512px image instead of 256px? You just quadrupled your compute. There’s no knob to turn.
Prior work tried to address compute efficiency in diffusion models through token pruning (drop unimportant tokens mid-forward-pass), early exit