Paper: 2606.26091 Authors: Andrei Liviu Nicolicioiu, Mohammad Pezeshki, Aaron Courville Categories: cs.LG, cs.AI
The Gap
Existing self-distillation methods (e.g., Conditional Training, Self-Consistency, Expert Iteration) focus narrowly on boosting pass@1 accuracy. They treat the teacher’s conditioning on a correct demonstration as a harmless source of dense feedback. The implicit assumption is that this feedback is unbiased — it simply rewards correct patterns. Prior work had not investigated whether this conditioning introduces systematic biases that affect the distribution of generated rollouts.
This paper identifies a concrete blind spot: on-policy self-distillation with sampled demonstrations reduces output diversity, flattening pass@k curves and degrading out-of-distribution performance. The logical path from gap to conclusion is:
+--- Problem: pass@k flattens under self-distillation ---+
|                                                        |
v                                                        v
+--- Assumption: teacher feedback is unbiased -----------+
|                                                        |
v                                                        v
+--- Method: derive optimal self-distillation policy ---+
|          as CMI-weighted tilt of base distribution     |
|                                                        |
v                                                        v
+--- Evidence: graph path-finding + science QA ----------+
|   (GSM8K, MMLU, ARC) — compare RL vs self-distill     |
|                                                        |
v                                                        v
+--- Conclusion: self-distillation amplifies existing    |
|   probability gaps; RL preserves ratio among correct   |
|   rollouts; diversity loss is structural, not random   |
+--------------------------------------------------------+
The Increment
One sentence: Before this paper, practitioners used self-distillation to boost pass@1 without realizing that it systematically reduces output diversity. After this paper, we understand that the degradation arises from a conditional mutual information (CMI) weighting that amplifies existing biases in the model’s own distribution.
Core Mechanism
The method is primarily an analytical diagnosis, supported by controlled experiments. The core insight is that self-distillation with a sampled demonstration as teacher context changes the learning objective in a subtle but critical way compared to on-policy RL.
In standard on-policy RL (e.g., policy gradient), the model generates rollouts, receives a reward based on whether each rollout leads to a correct final answer, and updates to increase the probability of correct rollouts. Crucially, among equally correct rollouts, the policy is free to maintain or even spread probability mass — RL does not penalize diversity as long as all correct actions are rewarded. The optimal policy under RL simply redistributes mass uniformly among rewarding actions (in the simplest case).
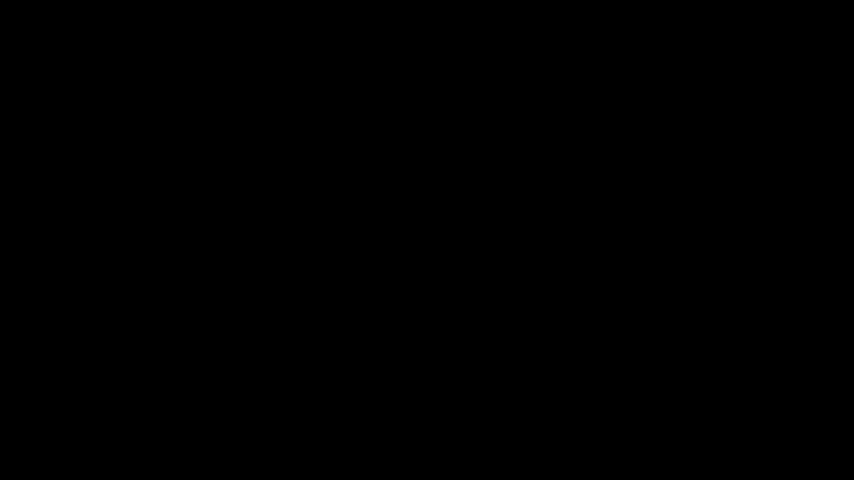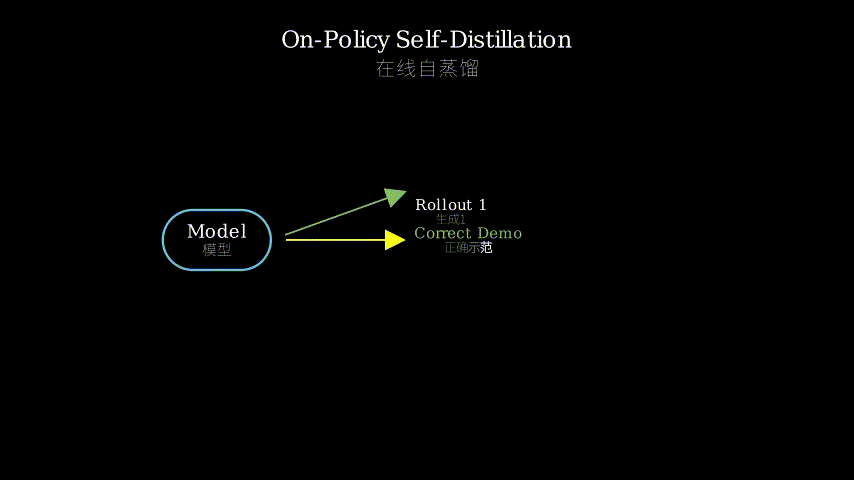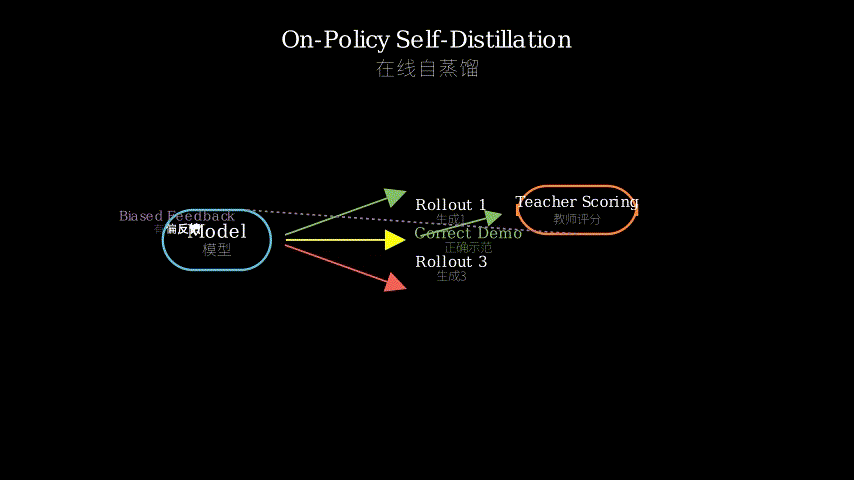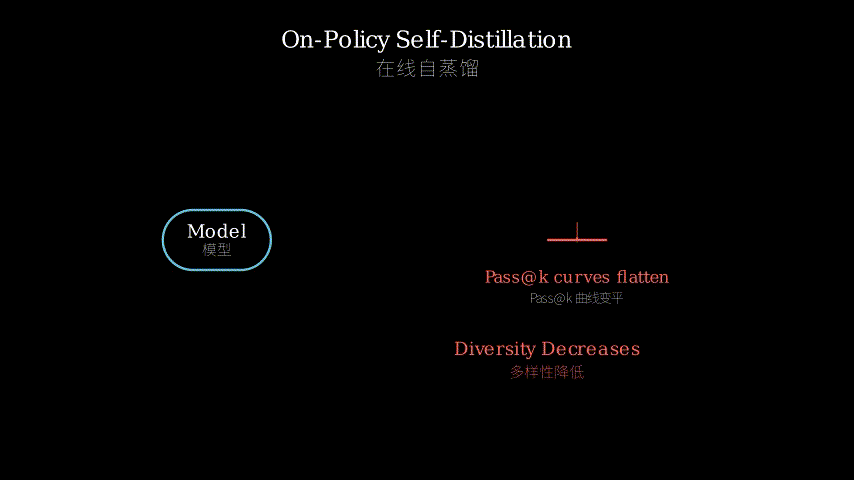
In on-policy self-distillation, the teacher is the same model, but it is conditioned on a correct demonstration sampled from the model’s own distribution. The teacher then scores each student rollout based on its similarity to that demonstration (implicitly, through the token-level feedback). This conditioning introduces a bias: the teacher prefers rollouts that resemble the demonstration, even if they differ only in style or strategy. The paper shows analytically that the optimal policy under this objective tilts the base distribution by a term proportional to the conditional mutual information between the student’s rollout and the demonstration.
Data flow in self-distillation:

+----------+               +--------------------------+
|  Model   | -> rollouts ->| Teacher (conditioned on  |
| (student)|               |  sampled correct demo)   |
+----------+               +--------------------------+
     ^                           |
     | (same model,              | (scores: high if similar to demo)
     |  different roles)         v
     +--- correct demo ---+   +----------+
                          +-->| Update   |
                              +----------+

Data flow in on-policy RL:

+----------+               +--------------------------+
|  Model   | -> rollouts ->| Reward (outcome-based:   |
|          |               |  1 if correct, 0 if not) |
+----------+               +--------------------------+
                                |
                                v
                           +----------+
                           | Update   |
                           +----------+
Structural metaphor: Think of a writing class. The student writes several essays (rollouts). In the RL world, the teacher grades purely on factual correctness (e.g., “does the conclusion match the data?”). All correct essays are rewarded equally, so the student can freely explore different arguments. In the self-distillation world, the teacher picks one correct essay from the student’s own previous work (the demonstration), and then grades new essays based on how similar they are to that chosen essay — rewarding similar phrasing, structure, and examples. The student quickly learns to mimic that one essay style, abandoning all other equally correct ways of writing. The bias comes from the teacher using a reference written by the student himself: it reinforces the student’s existing stylistic preferences, creating a positive feedback loop that collapses diversity.
Key Concepts
-
Pass@1 vs. Pass@k: Pass@1 measures the accuracy of a single sampled generation. Pass@k measures the probability that at least one of k independent generations contains a correct answer. High pass@k requires diversity: if all k rollouts are identical, pass@k = pass@1. This paper shows that self-distillation improves pass@1 but flattens pass@k, meaning the model becomes a one-trick pony — it generates the same correct answer over and over, wasting the capacity of multiple samples.
-
Conditional Mutual Information (CMI): Intuitively, CMI measures how much information a rollout carries about the correct demonstration, beyond what is already known from the input. The paper proves that the optimal self-distillation policy reweights the base distribution by a factor proportional to the pointwise CMI between the rollout and the demonstration. This means rollouts that are statistically similar to the demonstration get boosted, while equally correct but dissimilar rollouts are suppressed. Concretely, if two reasoning paths lead to the same answer, but one shares more tokens with the demonstration, the teacher favors that one, gradually collapsing variety.
-
Out-of-Distribution (OOD) Generalization: When the model faces a new problem that requires a strategy it has suppressed during self-distillation (e.g., a different path in the graph, or a different method for a science question), it fails because that strategy no longer has enough probability mass. This is the practical cost of reduced diversity.
Framework Shift
Below is a napkin sketch comparing the mainstream view before this paper with the updated understanding after.
Before (mainstream assumption):        After (this paper's insight):
+----------------------------+         +----------------------------+
| Self-distillation          |         | Self-distillation          |
|   = RL + dense feedback    |         |   = RL + biased feedback   |
|   = better learning        |         |   = better pass@1         |
|                             |         |   but worse pass@k        |
| Assumed effect on diversity:|         | Real effect on diversity: |
|   neutral or slightly +    |         |   negative (amplifies     |
|   (more feedback -> more   |         |   existing modes, kills   |
|    exploration?)           |         |   alternative strategies) |
+----------------------------+         +----------------------------+

Key structural difference:
Before: Teacher uses external correctness signal => unbiased.
After: Teacher uses a demonstration sampled from the student itself => self-referential bias.
One sentence: From treating self-distillation as a harmless upgrade to RL, the core shift is recognizing that conditioning on a sampled correct demo turns the teacher into a self-referential scoring function that systematically reduces diversity.
Expert Assessment
Problem choice: This is a real and timely gap. As LLM-based reasoning systems increasingly use self-consistency and self-distillation, the hidden cost of diversity loss has practical consequences for reliability and OOD performance. The field had been rushing to improve pass@1 without monitoring pass@k. This paper sits at a critical juncture — it’s not a manufacturing gap.
Method maturity: The theoretical derivation (CMI tilt) is a clean analytic result that explains the observed behavior. The controlled graph-path task is a well-chosen “minimal model” to isolate the effect. The science QA benchmarks are standard. If anything, the paper could have explored more diverse transformer architectures, but the core insight is robust. Not brute force — clever and parsimonious.
Experimental integrity: Baselines are fair: they compare self-distillation against on-policy RL with the same model, same number of rollouts, same compute. The metrics include pass@1, pass@k, distinct n-grams, and OOD accuracy. No obvious red flags. One could argue for more diverse OOD settings, but the evidence is convincing.
Writing quality: The paper is well-structured, but the theory section could be more intuition-friendly. The paper uses mutual information without a walkthrough example, which may lose readers. If the authors added a concrete calculation of CMI for a simple symbolic sequence, the paper would be much more accessible. The experimental section is solid.
Verdict: Weak accept — the discovery is important and the evidence is sufficient, but the contribution is more diagnostic than prescriptive (no new algorithm is proposed). Nonetheless, this paper will change how practitioners evaluate self-distillation.
Takeaways
- Monitoring diversity is cheap and mandatory: Whenever you use self-distillation, track pass@k for several k values and compare against a pure RL baseline. Also compute distinct-n-gram ratio or self-BLEU to quantify collapse.
- For problems requiring diverse strategies (code generation, open-ended QA, multi-step reasoning), prefer on-policy RL over self-distillation, or add a diversity regularizer (e.g., KL penalty against a uniform prior over correct rollouts).
- If you must use self-distillation, consider replacing the sampled demonstration with a fixed external set of correct demonstrations (e.g., from a human-written corpus) to break the self-referential bias. This paper’s CMI analysis suggests that the bias comes from sampling the demo from the model itself.
- The theoretical framework (CMI-weighted policy tilt) can be applied to other self-training paradigms — for example, self-imitation learning in offline RL, or bootstrapped DQN in reinforcement learning. The general lesson: conditioning on a self-generated “expert” trajectory can collapse exploration.
论文: 2606.26091 作者: Andrei Liviu Nicolicioiu, Mohammad Pezeshki, Aaron Courville 分类: cs.LG, cs.AI
缺口
现有自蒸馏方法(如Conditional Training、Self-Consistency、Expert Iteration)主要聚焦于提升pass@1准确率。 它们隐含假设:教师使用正确示范作为条件仅提供密集反馈,且这种反馈是无偏的。 但该假设从未被验证。 本文发现了一个具体盲区:基于采样式示范的在线自蒸馏会降低输出多样性,使pass@k曲线变平,并损害分布外泛化。 逻辑路径如下:
+--- 问题:自蒸馏下pass@k变平 ------------+
|                                          |
v                                          v
+--- 隐含假设:教师反馈无偏 ---------------+
|                                          |
v                                          v
+--- 方法:推导最优自蒸馏策略 -------------+
|         为基于条件互信息的分布倾斜        |
|                                          |
v                                          v
+--- 证据:图路径寻找 + 科学问答 ----------+
|   (GSM8K, MMLU, ARC) — 对比RL与自蒸馏  |
|                                          |
v                                          v
+--- 结论:自蒸馏放大已有概率差距 ---------+
|   RL保持正确抽样之间的比例;多样性损失    |
|   是结构性的,而非随机噪声                |
+------------------------------------------+
增量
一句话: 这篇论文之前,实践者使用自蒸馏提升pass@1而不知多样性会系统性下降。 这篇论文之后,人们明白退化源于条件互信息加权放大了模型自身分布的固有偏差。
核心机制
该方法以理论分析为主,辅以受控实验进行验证。 核心洞察是:与在线策略RL相比,使用采样示范作为教师上下文会微妙但关键地改变学习目标。
在标准在线RL(如策略梯度)中,模型生成抽样,收到基于每个抽样是否得到正确答案的奖励,然后更新以增加正确抽样的概率。 关键在于,在同样正确的抽样之间,策略可以自由地保持甚至分散概率质量——RL不会惩罚多样性,只要所有正确动作都得到奖励。 RL的最优策略简单地在正确动作之间均匀分布质量。
在在线自蒸馏中,教师与模型相同,但它以从模型自身分布中采样的正确示范为条件。 教师随后根据每个学生抽样与该示范的相似度打分(通过token级反馈隐含实现)。 这种条件引入偏差:教师偏好与示范相似的抽样,即使它们仅在风格或策略上不同。 本文分析表明,该目标下的最优策略会将基础分布倾斜一个与抽样和示范之间的条件互信息成正比的项。
自蒸馏的数据流:

+----------+               +--------------------------+
|  模型    | -> 抽样 ----->| 教师(以采样正确示范    |
| (学生) |               |  作为条件)               |
+----------+               +--------------------------+
     ^                           |
     | (同一模型,               | (分数:与示范相似则高)
     |  不同角色)                v
     +--- 正确示范 ---+      +----------+
                      +----->| 更新     |
                             +----------+

在线RL的数据流:

+----------+               +--------------------------+
|  模型    | -> 抽样 ----->| 奖励(基于结果:        |
|          |               |  1正确,0错误)          |
+----------+               +--------------------------+
                                |
                                v
                           +----------+
                           | 更新     |
                           +----------+
结构性比喻:想象一个写作班。 学生写多篇论文(抽样)。 在RL世界里,老师只根据事实正确性打分(例如“结论是否与数据匹配?”)。 所有正确论文获得相同奖励,学生可以自由探索不同论证。 在自蒸馏世界里,老师从学生自己之前写的论文中挑一篇正确的(示范),然后根据新论文与那篇示范的相似程度打分——奖励相似的措辞、结构和例子。 学生很快学会模仿那一篇论文风格,放弃所有其他同样正确的写作方式。 偏差源于老师使用了学生自己写的参考:它强化了学生已有的风格偏好,形成正反馈循环,导致多样性崩塌。
关键概念
-
Pass@1 vs Pass@k:Pass@1衡量单次生成准确率。 Pass@k衡量在k次独立生成中至少有一次包含正确答案的概率。 高pass@k需要多样性:如果所有k个抽样都相同,pass@k = pass@1。 本文表明自蒸馏提升了pass@1但压平了pass@k,意味着模型成为“一招鲜”——它反复生成相同的正确答案,浪费了多次抽样的能力。
-
条件互信息(CMI):直观上,CMI衡量一个抽样在已知输入的情况下,携带多少关于正确示范的信息。 本文证明最优自蒸馏策略会依据抽样与示范之间的逐点条件互信息对基础分布进行加权。 这意味着与示范统计相似的抽样被提升,而同样正确但不相似的抽样被压制。 具体来说,如果两个推理路径都得到相同答案,但一个与示范共享更多token,教师就会偏袒它,逐渐使多样性消失。
-
分布外泛化(OOD):当模型面对一个需要它已在自蒸馏中压制过的策略的新问题时(例如图中的不同路径,或科学问题的不同方法),它会失败,因为该策略不再具有足够的概率质量。 这是多样性降低的实际代价。
框架转变
以下是主流观点与本文观点在“餐巾纸速写”上的对比。
之前(主流假设):                   之后(本文洞察):
+----------------------------+      +----------------------------+
| 自蒸馏                      |      | 自蒸馏                      |
|   = RL + 密集反馈           |      |   = RL + 有偏反馈           |
|   = 更好的学习              |      |   = 更好的pass@1           |
|                             |      |   但更差的pass@k           |
| 对多样性的假设效果:         |      | 对多样性的真实效果:        |
|   中性或略正                |      |   负(放大既有模式,        |
|   (更多反馈 → 更多探索?)  |      |   扼杀备选策略)            |
+----------------------------+      +----------------------------+

关键结构差异:
之前:教师使用外部正确性信号 → 无偏。
之后:教师使用从学生自身采样的示范 → 自我参照偏差。
一句话: 从认为自蒸馏是RL的无害升级,到认识到以采样正确示范为条件会使教师变成自我参照的评分函数并系统性降低多样性——这是核心转变。
专家评审
选题眼光: 这是一个真实且及时的缺口。 随着基于LLM的推理系统越来越多地使用自一致性和自蒸馏,多样性损失的隐性代价对可靠性和OOD性能有实际影响。 领域此前急于提升pass@1而忽略了监控pass@k。 本文位于关键转折点——是真正的缺口而非人为制造。
方法成熟度: 理论推导(CMI倾斜)是一个干净的分析结果,很好地解释了观察到的行为。 受控的图路径任务是一个精心选择的“最小模型”,能隔离效应。 科学QA基准是标准的。 如果要说不足,可以探索更多不同的变换器架构,但核心洞察是稳健的。 不蛮力——巧妙且简洁。
实验诚意: 基线公平:他们使用相同模型、相同抽样数量、相同计算量比较自蒸馏和在线RL。 指标包括pass@1、pass@k、不同n元组数量和OOD准确率。 没有明显的危险信号。 可以争论需要更多样化的OOD设置,但证据令人信服。
写作功力: 论文结构良好,但理论部分可以更直观。 论文使用互信息但没有提供逐步实例,可能让读者迷失。 如果作者对一个简单符号序列进行CMI的具体计算,文章会容易理解得多。 实验部分扎实。
判决: 弱接收——这一发现很重要且证据充分,但贡献更偏向诊断性而非建设性(没有提出新算法)。 尽管如此,这篇论文将改变实践者评估自蒸馏的方式。
要点总结
- 监控多样性的成本很低且是必需的:当使用自蒸馏时,跟踪多个k值的pass@k,并与纯RL基线对比。 同时计算不同n元组比或自BLEU来量化坍塌。
- 对于需要多种策略的问题(代码生成、开放式问答、多步推理),优先使用在线RL而非自蒸馏,或添加多样性正则化器(例如针对正确抽样的均匀先验的KL惩罚)。
- 如果非用自蒸馏不可,考虑用固定外部正确示范集(例如来自人工编写的语料)替代采样示范,以打破自我参照偏差。 本文的CMI分析表明,偏差来自从模型自身采样示范。
- 理论框架(CMI加权策略倾斜)可应用于其他自训练范式——例如离线RL中的自模仿学习,或强化学习中的引导式DQN。 一般教训:以自生成的“专家”轨迹为条件会坍塌探索。