Paper: 2603.12265 Authors: Yibin Yan, Jilan Xu, Shangzhe Di, Haoning Wu, Weidi Xie Categories: cs.CV
The Gap
Vision foundation models have gotten very good — but only in narrow lanes. CLIP and its descendants nail semantic alignment but are blind to geometry. DPT and depth estimators understand 3D structure but can’t reason about language. Video transformers like VideoMAE model temporal dynamics but process clips offline in batch mode. And none of them are designed to run frame-by-frame in a live stream while maintaining memory of what came before.
The result is that anyone building a real-world visual agent — a robot, a drone, an AR system — has to stitch together a pipeline of specialists. That stitching is expensive, brittle, and architecturally incoherent. Each specialist was trained with different assumptions about what “a good representation” means.
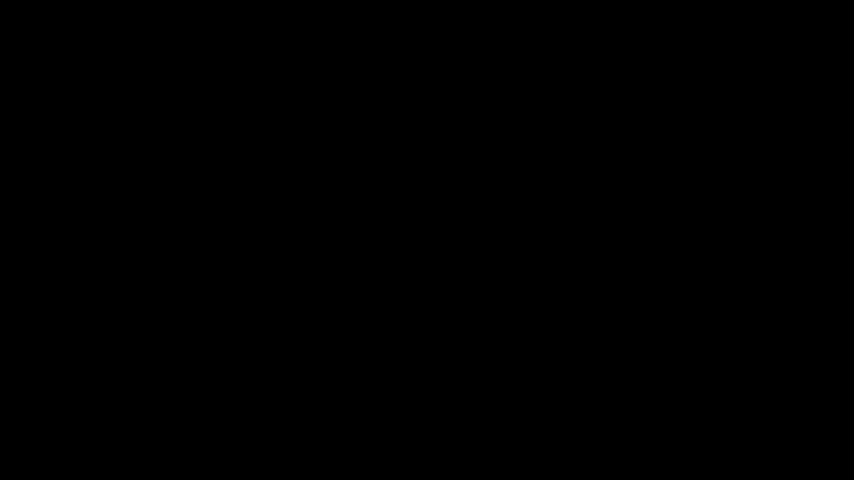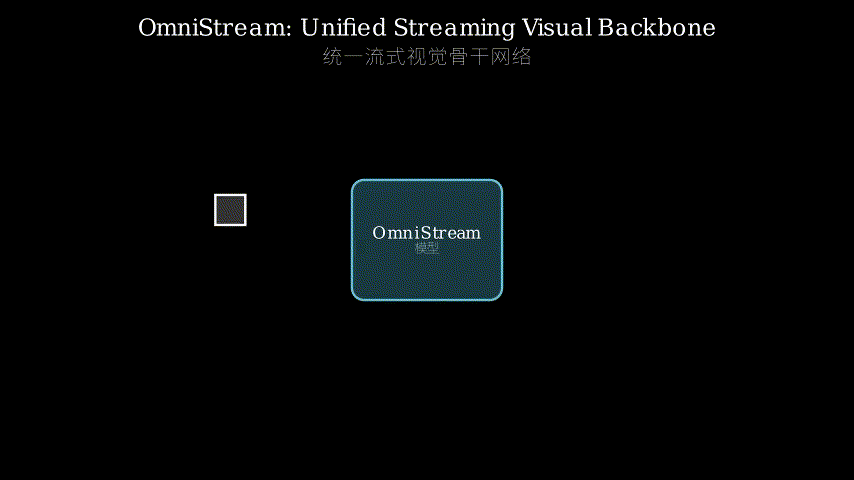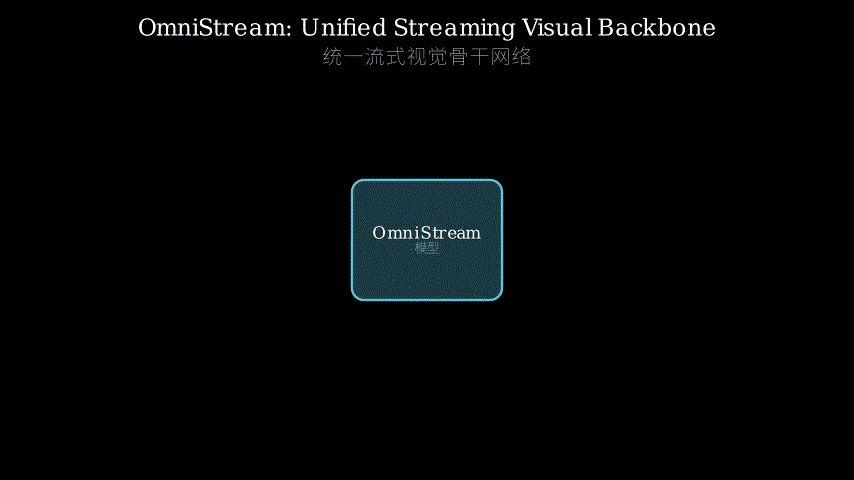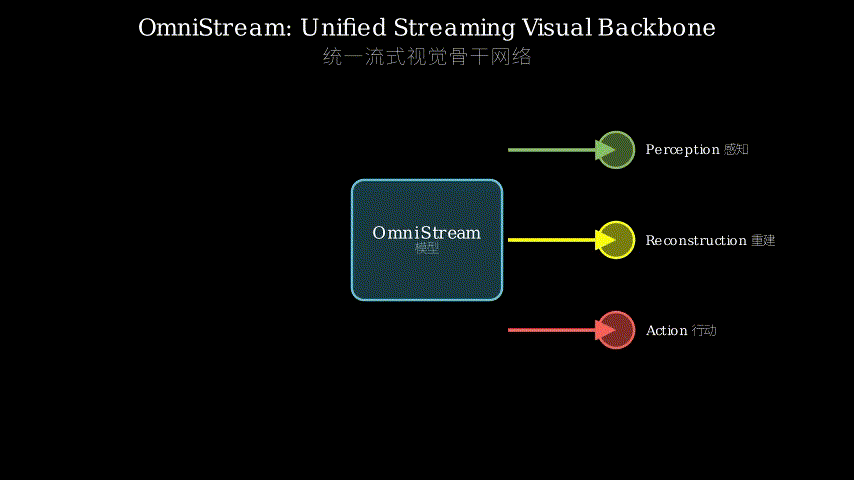
The specific boundary this paper pushes against: no single frozen backbone can simultaneously serve semantic understanding, streaming 3D reconstruction, and downstream robotic control. The authors argue this fragmentation isn’t inevitable — it’s a consequence of how we’ve been training, not a fundamental limit of what a single model can learn.
Problem: Vision models are specialists, not generalists
  |
  v
Assumption: A shared causal spatiotemporal representation
            can serve semantic + geometric + action tasks
  |
  v
Method: OmniStream
  - Causal spatiotemporal attention (no future leakage)
  - 3D-RoPE for position encoding across space + time
  - Multi-task pre-training on 29 datasets
  - Persistent KV-cache for online streaming
  |
  v
Evidence:
  - Competitive with specialists on image/video probing
  - Streaming depth/geometry reconstruction
  - Zero-shot transfer to robotic manipulation
  |
  v
Conclusion: A single frozen backbone can generalize
            across semantic, spatial, and temporal tasks
The Increment
One sentence: Before this paper, you needed a different backbone for each modality of visual understanding; after it, there’s evidence that one causally-structured, multi-task-trained backbone can cover all three without fine-tuning.
Core Mechanism
OmniStream is a transformer backbone with two architectural choices that do most of the heavy lifting. First, all attention is causal — each token can only attend to past and present tokens, never future ones. This isn’t just a training trick; it’s what makes the model deployable in a real-time stream where future frames literally don’t exist yet. Second, positional encoding uses 3D-RoPE, which extends rotary position embeddings to encode height, width, and time simultaneously. This gives the model a coherent sense of where and when each patch is, without needing separate positional heads for spatial vs. temporal reasoning.
The pre-training is a four-way multi-task setup. Task one: static image representation learning (think masked autoencoding or contrastive objectives). Task two: temporal video representation learning across clips. Task three: streaming geometric reconstruction — predicting depth and 3D structure from the causal stream. Task four: vision-language alignment, connecting visual tokens to text. These four tasks are trained jointly, not sequentially, which forces the shared backbone to find representations that are simultaneously useful for all of them.
At inference, the model maintains a persistent KV-cache across frames. As each new frame arrives, its keys and values are appended to the cache, and attention is computed over the full causal history. This is the same mechanism that makes autoregressive language models efficient — here it’s applied to video, enabling constant-time per-frame processing regardless of how long the stream has been running.
Input stream: ...frame_t-2, frame_t-1, frame_t, frame_t+1...
                                              ^
                                         only up to here

Each frame -> patch tokens
                  |
                  v
         3D-RoPE encoding
         (x, y, t coordinates)
                  |
                  v
    Causal Spatiotemporal Attention
    [attends to KV-cache of all past frames]
                  |
         +--------+--------+--------+--------+
         |        |        |        |        |
         v        v        v        v        v
      Semantic  Temporal  Depth   3D Geo   Lang
      probing   probing   recon   recon    align
Think of OmniStream like a court stenographer who’s also a structural engineer and a translator — all at once. The stenographer writes down everything in real time (causal, no peeking ahead). The 3D-RoPE is like the page-and-line numbering system: every word gets tagged with exactly when and where it appeared, so you can always reconstruct the spatial and temporal layout of the room. The KV-cache is the stenographer’s running transcript — they don’t re-read the whole session from scratch each time someone speaks; they just append the new line and reference back as needed. The multi-task pre-training is what makes this stenographer unusual: they were trained simultaneously in courtrooms, construction sites, and translation booths, so the same note-taking habits serve all three contexts. When a robotics task shows up — a context they’ve never seen — the underlying note-taking discipline transfers anyway.
Key Concepts
-
Causal attention: In a standard transformer, every token can attend to every other token — past and future. That’s fine for offline processing but impossible in a live stream. Causal attention adds a mask that blocks any token from looking at tokens that come after it in time. Concretely: when processing frame 47, the model can use information from frames 1–47 but not frame 48. This constraint is what makes the model deployable in real time, and it’s also what forces the model to learn representations that are genuinely predictive rather than retrospective.
-
3D-RoPE (Rotary Position Embedding in 3D): RoPE is a way of encoding position by rotating the query and key vectors in attention by an angle proportional to their position. The rotation means that the dot product between two tokens naturally encodes their relative distance — nearby tokens have similar rotations, distant ones diverge. The 3D extension applies this idea across three axes: horizontal pixel position, vertical pixel position, and time. So every patch token carries a compact, geometry-aware address in space-time, and the attention mechanism can reason about “how far apart are these two patches in 3D?” without any explicit coordinate regression head.
-
Persistent KV-cache for video: In autoregressive language models, the KV-cache stores the key and value projections of all previous tokens so you don’t recompute them on every new token. OmniStream applies this to video: as each frame is processed, its KV pairs are appended to a running cache. The next frame attends over the full cache. This means per-frame compute is O(1) in the number of past frames (just one attention pass over the cache), not O(n²). The “persistent” part means the cache isn’t cleared between frames — it accumulates across the entire stream, giving the model a long-term memory of what it has seen.
-
Multi-task pre-training: Rather than training separate models for semantic understanding, depth estimation, and temporal modeling, OmniStream trains one backbone on all tasks simultaneously. The loss is a weighted sum of task-specific objectives. This forces the model to learn a shared representation space where semantic, geometric, and temporal information coexist. The result is a backbone that can be frozen and probed for any of these tasks without task-specific fine-tuning.
Why It Matters
The practical impact is that you can now deploy a single frozen backbone for real-time visual agents. No more stitching together CLIP for semantics, DPT for depth, and VideoMAE for temporal reasoning. One model, one forward pass per frame, constant memory, and it generalizes to robotic manipulation tasks it was never explicitly trained on.
The conceptual impact is that causal spatiotemporal attention might be the right inductive bias for visual foundation models. If you want a model that can run in the real world — where the future doesn’t exist yet and you need to make decisions frame by frame — then causal attention isn’t just a nice-to-have, it’s the only coherent choice. And if you train that causally-structured model on a diverse enough mix of tasks, it learns representations that transfer across modalities without further tuning.
This paper doesn’t claim to have solved vision. But it does show that the fragmentation of vision models into specialists isn’t inevitable. A single backbone, trained the right way, can be a generalist.
论文: 2603.12265 作者: Yibin Yan, Jilan Xu, Shangzhe Di, Haoning Wu, Weidi Xie 分类: cs.CV
问题所在
视觉基础模型已经很强大了——但只在狭窄的领域内。CLIP及其衍生模型擅长语义对齐,但对几何结构视而不见。DPT和深度估计器理解3D结构,但无法进行语言推理。像VideoMAE这样的视频transformer能建模时序动态,但只能离线批处理视频片段。而且它们都不是为逐帧处理实时流并保持对之前内容的记忆而设计的。
结果就是,任何构建真实世界视觉智能体的人——机器人、无人机、AR系统——都必须拼接一个专家流水线。这种拼接既昂贵又脆弱,在架构上也不连贯。每个专家都是基于不同的假设来训练”好的表征”应该是什么样的。
本文要突破的具体边界是:没有单一的冻结骨干网络能够同时服务于语义理解、流式3D重建和下游机器人控制。作者认为这种碎片化并非不可避免——这是我们训练方式的结果,而非单一模型能力的根本限制。
问题:视觉模型是专家,而非通才
  |
  v
假设:共享的因果时空表征
      可以服务于语义+几何+动作任务
  |
  v
方法:OmniStream
  - 因果时空注意力(无未来泄漏)
  - 3D-RoPE用于空间+时间的位置编码
  - 在29个数据集上进行多任务预训练
  - 用于在线流式处理的持久KV缓存
  |
  v
证据:
  - 在图像/视频探测上与专家模型竞争
  - 流式深度/几何重建
  - 零样本迁移到机器人操作
  |
  v
结论:单一冻结骨干网络可以泛化
      到语义、空间和时序任务
核心进展
一句话总结:在本文之前,你需要为每种视觉理解模态使用不同的骨干网络;在本文之后,有证据表明一个因果结构化、多任务训练的骨干网络可以覆盖所有三种模态,无需微调。
核心机制
OmniStream是一个transformer骨干网络,有两个架构选择承担了大部分工作。首先,所有注意力都是因果的——每个token只能关注过去和当前的token,永远不能关注未来的token。这不仅仅是训练技巧;这使得模型可以部署在实时流中,因为未来的帧实际上还不存在。其次,位置编码使用3D-RoPE,它将旋转位置嵌入扩展到同时编码高度、宽度和时间。这使模型对每个patch的位置和时间有连贯的感知,无需为空间和时序推理设置单独的位置头。
预训练是一个四路多任务设置。任务一:静态图像表征学习(类似掩码自编码或对比目标)。任务二:跨片段的时序视频表征学习。任务三:流式几何重建——从因果流预测深度和3D结构。任务四:视觉-语言对齐,将视觉token连接到文本。这四个任务是联合训练的,而非顺序训练,这迫使共享骨干网络找到对所有任务同时有用的表征。
在推理时,模型在帧之间维护一个持久的KV缓存。当每个新帧到达时,其键和值被追加到缓存中,注意力在完整的因果历史上计算。这与使自回归语言模型高效的机制相同——这里应用于视频,无论流运行多长时间,都能实现每帧恒定时间处理。
输入流:...frame_t-2, frame_t-1, frame_t, frame_t+1...
                                          ^
                                     只到这里

每帧 -> patch tokens
          |
          v
     3D-RoPE编码
     (x, y, t坐标)
          |
          v
  因果时空注意力
  [关注所有过去帧的KV缓存]
          |
 +--------+--------+--------+--------+
 |        |        |        |        |
 v        v        v        v        v
语义    时序    深度    3D几何   语言
探测    探测    重建    重建     对齐
把OmniStream想象成一个既是结构工程师又是翻译的法庭速记员——三者合一。速记员实时记录一切(因果的,不偷看未来)。3D-RoPE就像页码和行号系统:每个词都标记了它出现的确切时间和位置,所以你总能重建房间的空间和时间布局。KV缓存是速记员的运行记录——他们不会在每次有人说话时从头重读整个会话;他们只是追加新行并根据需要回溯引用。多任务预训练使这个速记员与众不同:他们同时在法庭、建筑工地和翻译室接受训练,所以相同的记录习惯适用于所有三种场景。当机器人任务出现时——一个他们从未见过的场景——底层的记录规则仍然可以迁移。
关键概念
-
因果注意力:在标准transformer中,每个token可以关注所有其他token——过去和未来。这对离线处理没问题,但在实时流中不可能。因果注意力添加了一个掩码,阻止任何token查看时间上在它之后的token。具体来说:处理第47帧时,模型可以使用第1-47帧的信息,但不能使用第48帧。这个约束使模型可以实时部署,也迫使模型学习真正具有预测性而非回顾性的表征。
-
3D-RoPE(三维旋转位置嵌入):RoPE是一种通过将查询和键向量旋转与其位置成比例的角度来编码位置的方法。旋转意味着两个token之间的点积自然编码它们的相对距离——相邻token有相似的旋转,远距离token则发散。3D扩展将这个想法应用于三个轴:水平像素位置、垂直像素位置和时间。因此每个patch token在时空中携带一个紧凑的、几何感知的地址,注意力机制可以推理”这两个patch在3D中相距多远?“而无需任何显式的坐标回归头。
-
视频的持久KV缓存:在自回归语言模型中,KV缓存存储所有先前token的键和值投影,这样你就不必在每个新token上重新计算它们。OmniStream将此应用于视频:当每帧被处理时,其KV对被追加到运行缓存中。下一帧关注完整的缓存。这意味着每帧计算在过去帧数量上是O(1)(只需对缓存进行一次注意力传递),而不是O(n²)。“持久”部分意味着缓存不会在帧之间清除——它在整个流中累积,为模型提供了对所见内容的长期记忆。
-
多任务预训练:OmniStream不是为语义理解、深度估计和时序建模训练单独的模型,而是在所有任务上同时训练一个骨干网络。损失是任务特定目标的加权和。这迫使模型学习一个共享的表征空间,其中语义、几何和时序信息共存。结果是一个可以冻结并探测任何这些任务的骨干网络,无需任务特定的微调。
为什么重要
实际影响是,你现在可以为实时视觉智能体部署单一的冻结骨干网络。不再需要拼接CLIP用于语义、DPT用于深度、VideoMAE用于时序推理。一个模型,每帧一次前向传递,恒定内存,并且它可以泛化到从未明确训练过的机器人操作任务。
概念影响是,因果时空注意力可能是视觉基础模型的正确归纳偏置。如果你想要一个可以在真实世界中运行的模型——未来还不存在,你需要逐帧做出决策——那么因果注意力不仅仅是锦上添花,它是唯一连贯的选择。如果你在足够多样化的任务组合上训练这个因果结构化的模型,它会学习到跨模态迁移的表征,无需进一步调整。
本文并未声称已经解决了视觉问题。但它确实表明,将视觉模型碎片化为专家并非不可避免。一个以正确方式训练的单一骨干网络可以成为通才。