Paper: 2604.28197 Authors: Junyoung Lee, Sookwan Han, Jeonghwan Kim, Inhee Lee, Mingi Choi, Jisoo Kim, Wonjung Woo, Hanbyul Joo Categories: cs.RO, cs.CV
The Gap
Human-robot collaboration research has focused on dyadic settings (one human, one robot) or sequential handoffs. Real homes need multiadic collaboration: multiple humans and robots working simultaneously on interleaved tasks in close proximity. The problem? When humans, robots, and objects crowd together, they constantly occlude each other. Existing motion capture systems use markers (impractical for homes), single viewpoints (fail under occlusion), or offline processing (too slow for real-time control). No platform provides room-scale, occlusion-robust, real-time 3D tracking needed to make multiadic collaboration experimentally tractable.
Problem: Multiadic collaboration regime unexplored
   |
   v
Bottleneck: Occlusion + real-time tracking impossible
   |
   +---> Prior work: Markers (unnatural)
   +---> Prior work: Single camera (occlusion-prone)
   +---> Prior work: Offline processing (not real-time)
   |
   v
Assumption: Dense multi-view coverage can resolve occlusion
   |
   v
Method: 48 synchronized cameras + markerless tracking
   |
   v
Evidence: Real-time tracking enables safety + anticipation
   |
   v
Conclusion: Multiadic regime now experimentally tractable
The Increment
One sentence: Before this paper, multiadic human-robot collaboration was a theoretical regime; after, it’s an experimentally accessible platform with demonstrated safety and anticipation capabilities.
Core Mechanism
OmniRobotHome instruments a residential apartment with 48 hardware-synchronized RGB cameras arranged to provide dense coverage from multiple angles. The cameras capture at 30 FPS and feed into a markerless 3D tracking pipeline that reconstructs human poses and object positions in real-time. Two Franka Panda robot arms operate in the same space, receiving live scene state updates to coordinate their actions with humans and each other. Everything—cameras, tracking, and robot control—operates in a unified world coordinate frame with temporal alignment.
The tracking pipeline uses multi-view geometry to resolve occlusions: when one camera’s view is blocked, others compensate. Human pose estimation runs on each camera view, then triangulates 3D joint positions across views. Object tracking combines visual features with geometric constraints. The system maintains persistent identity tracking across frames, building up trajectory histories that capture long-term behavior patterns.
Camera Array (48 units)
   |
   +---> [Sync Trigger] ---> Simultaneous capture
   |
   v
Multi-view Images (30 FPS)
   |
   +---> Per-view pose estimation
   +---> Per-view object detection
   |
   v
Triangulation + Fusion
   |
   +---> 3D human poses
   +---> 3D object positions
   |
   v
World Frame State
   |
   +---> Robot controllers (real-time)
   +---> Trajectory database (long-term)
Think of it like air traffic control for a busy kitchen. A single radar can’t see planes behind mountains—you need multiple stations triangulating positions. Here, each camera is a radar station, and occlusion is the mountain. When your body blocks one camera’s view of a cup, three other cameras still see it. The control tower (tracking system) fuses all reports into a single authoritative position. The planes (robots) receive continuous updates and adjust their flight paths accordingly. The flight recorder (trajectory database) logs everything, learning typical routes so controllers can anticipate where planes usually go next.
Key Concepts
-
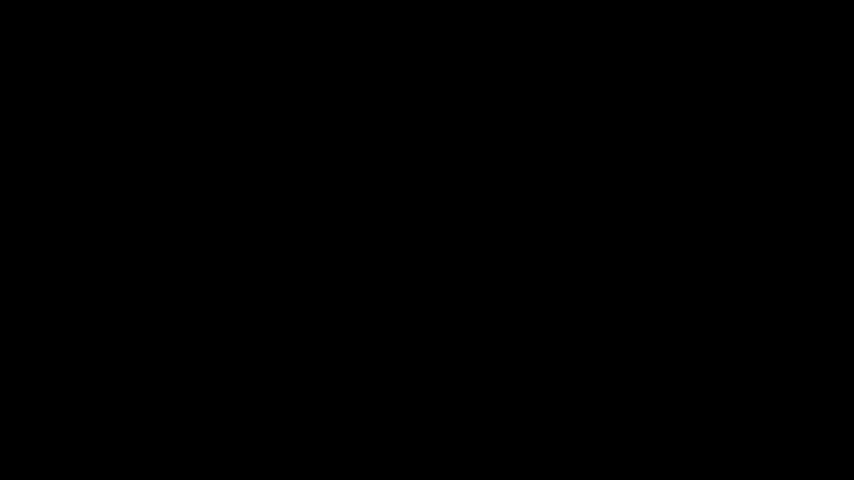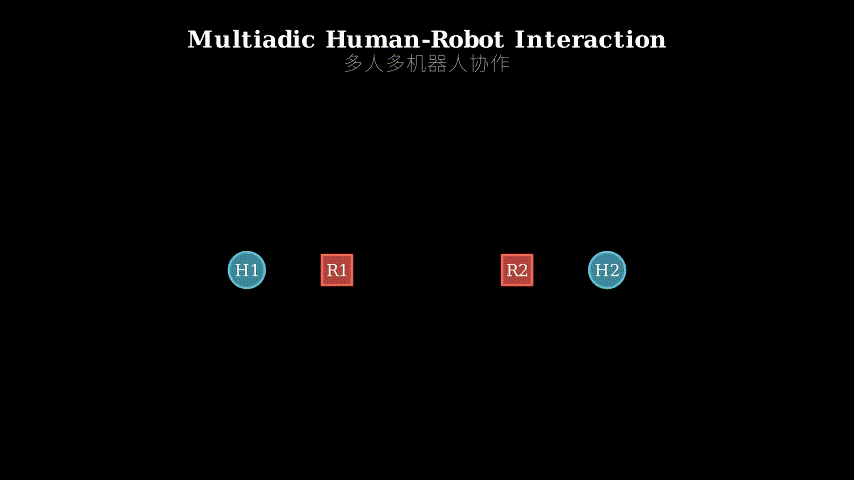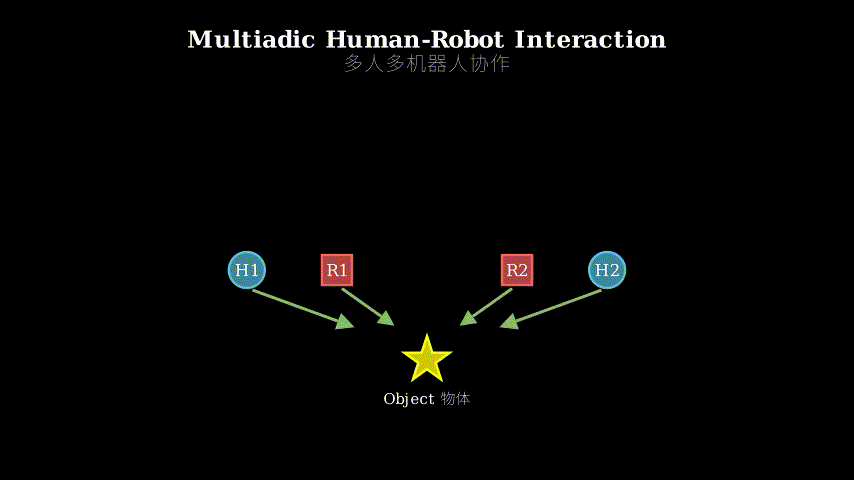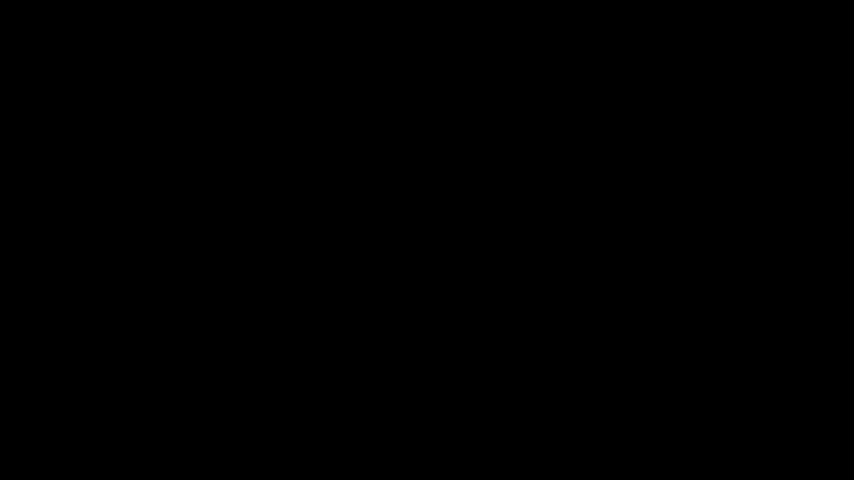
Multiadic collaboration: Unlike dyadic (one human, one robot) or sequential (take turns) interaction, multiadic means multiple agents acting concurrently on interleaved subtasks with tight spatial and temporal coupling. Imagine cooking dinner: you’re chopping vegetables while your partner stirs a pot and a robot retrieves ingredients from the fridge—all happening simultaneously in overlapping workspace zones. The challenge isn’t just coordination but handling the constant occlusion and rapid state changes when everyone moves at once.
-
Occlusion-robust tracking: When objects or people block each other from a camera’s view, single-viewpoint systems lose track. Multi-view systems solve this by ensuring that if one camera can’t see something, others can. The key is geometric redundancy: 48 cameras means any point in the room is visible from multiple angles. Even if a human’s torso blocks their hand from 10 cameras, the remaining 38 still triangulate its position. This isn’t about higher resolution—it’s about eliminating blind spots through spatial diversity.
-
Shared world frame: All sensors and actuators must agree on what “position (x, y, z)” means. Without this, the robot thinks the cup is 10cm left of where cameras see it, leading to grasping failures. Calibration establishes a single coordinate system: cameras know where they sit in the room, robots know where their base is, and tracking outputs positions in room coordinates. Temporal synchronization ensures everyone’s talking about the same moment—a camera frame at t=0.5s aligns with robot state at t=0.5s, not t=0.3s.
Framework Shift
Before (mainstream approach):        After (this paper):

Dyadic or Sequential                 Multiadic Concurrent

Human <---> Robot                    Human-A ----+
  ^                                             |
  |                                    Human-B -+-> Shared
  v                                             |   Space
Single camera                         Robot-1 -+
or markers                                      |
                                      Robot-2 --+
Offline processing
                                     48-camera array
Limited workspace                    (real-time fusion)

                                     Room-scale coverage
From isolated dyads to concurrent multiadic interaction, the core shift is treating the entire room as a single observable system rather than tracking individual agent pairs.
Expert Assessment
Problem choice: This is a real infrastructure gap, not manufactured. The field has been stuck in dyadic settings because the perception problem was genuinely unsolved. The authors correctly identify that multiadic collaboration is where home robotics must go, and that occlusion is the blocker. The problem sits at a critical juncture: lab demos are saturated, but real homes remain out of reach.
Method maturity: This is engineering execution, not algorithmic novelty. The tracking pipeline uses standard multi-view geometry and off-the-shelf pose estimators. The insight is that 48 cameras is the right density to make occlusion-robust tracking work in practice. Some might argue this is brute force, but sometimes the simple approach (more cameras) is the right one when clever algorithms have failed for a decade. The platform design is mature; the tracking algorithms are borrowed.
Experimental integrity: The safety and anticipation experiments are proof-of-concept demonstrations, not rigorous benchmarks. Baselines are reasonable (single-view tracking, no anticipation), but the paper doesn’t compare against other multi-view systems because none exist at this scale. The numbers show clear gains, but sample sizes are small and scenarios are controlled. The real contribution is making the experiments possible at all, not definitive performance claims.
Writing quality: The paper front-loads the platform description, which is correct—the platform is the contribution. However, the application sections (safety, anticipation) feel rushed. The anticipation experiment in particular would benefit from deeper analysis of what behavior patterns the system learned and why they generalize. The related work section is thorough but could better articulate why prior multi-view systems (sports capture, VR tracking) don’t transfer to this domain.
Verdict: weak accept — This is infrastructure work that unblocks a research direction. The platform is well-executed and the problem is real, but the scientific insights are limited. It’s a strong workshop paper or a systems track contribution, not a methods breakthrough.
Takeaways
Dense sensor coverage beats clever algorithms under occlusion: If your application involves close-proximity interaction, don’t try to solve occlusion with better tracking models. Add more viewpoints until occlusion becomes geometrically impossible. The 48-camera number is a data point: for a ~30 square meter apartment, that density works.
Shared world frame is non-negotiable for multi-agent systems: Calibration and synchronization are boring but critical. If you’re building any system where multiple sensors feed multiple actuators, invest in rock-solid spatial and temporal alignment infrastructure first. The authors use hardware sync triggers and careful calibration—steal that pattern.
Trajectory databases enable anticipation: Logging long-term behavior creates a memory that reactive systems lack. If you’re building assistive robots, don’t just react to current state—accumulate trajectories and learn typical patterns. The paper shows this works for predicting human intent, but the idea transfers to any domain with repetitive behavior (manufacturing, healthcare, logistics).
Platform papers are undervalued: This won’t win best paper awards, but it might enable a dozen future papers. If you’re in a field where infrastructure is the bottleneck, building and open-sourcing a platform is high-impact work even if the immediate scientific novelty is low.
论文: 2604.28197 作者: Junyoung Lee, Sookwan Han, Jeonghwan Kim, Inhee Lee, Mingi Choi, Jisoo Kim, Wonjung Woo, Hanbyul Joo 分类: cs.RO, cs.CV
缺口
人机协作研究主要聚焦于二元场景(一人一机)或顺序交接。
真实家庭需要多方协作:多个人和机器人在近距离同时执行交错任务。
问题在哪?
当人、机器人和物体挤在一起时,它们不断互相遮挡。
现有动作捕捉系统要么用标记点(家庭场景不现实),要么单视角(遮挡时失效),要么离线处理(无法实时控制)。
没有平台能提供房间尺度、抗遮挡、实时3D追踪,让多方协作在实验上可行。
问题:多方协作机制未被探索
   |
   v
瓶颈:遮挡 + 实时追踪不可能
   |
   +---> 先前工作:标记点(不自然)
   +---> 先前工作:单摄像头(易遮挡)
   +---> 先前工作:离线处理(非实时)
   |
   v
假设:密集多视角覆盖可解决遮挡
   |
   v
方法:48个同步摄像头 + 无标记追踪
   |
   v
证据:实时追踪实现安全性 + 预判能力
   |
   v
结论:多方协作机制现在实验可行
增量
一句话: 这篇论文之前,多方人机协作是理论设想;
之后,它成为可实验的平台,具备已验证的安全和预判能力。
核心机制
OmniRobotHome在住宅公寓中布置48个硬件同步的RGB摄像头,排列成密集的多角度覆盖。
摄像头以30帧每秒捕获,输入无标记3D追踪管线,实时重建人体姿态和物体位置。
两个Franka Panda机械臂在同一空间操作,接收实时场景状态更新,协调它们与人类及彼此的动作。
所有组件——摄像头、追踪、机器人控制——在统一的世界坐标系中运行,时间对齐。
追踪管线使用多视角几何解决遮挡:当一个摄像头视野被挡,其他摄像头补偿。
人体姿态估计在每个摄像头视角运行,然后跨视角三角测量3D关节位置。
物体追踪结合视觉特征和几何约束。
系统跨帧维持持久身份追踪,积累轨迹历史,捕获长期行为模式。
摄像头阵列(48个单元)
   |
   +---> [同步触发] ---> 同时捕获
   |
   v
多视角图像(30帧/秒)
   |
   +---> 单视角姿态估计
   +---> 单视角物体检测
   |
   v
三角测量 + 融合
   |
   +---> 3D人体姿态
   +---> 3D物体位置
   |
   v
世界坐标系状态
   |
   +---> 机器人控制器(实时)
   +---> 轨迹数据库(长期)
把它想象成繁忙厨房的空中交通管制。
单个雷达看不到山后的飞机——你需要多个站点三角定位。
这里,每个摄像头是一个雷达站,遮挡是那座山。
当你的身体挡住一个摄像头看杯子的视线时,另外三个摄像头仍能看到它。
控制塔(追踪系统)融合所有报告,得出单一权威位置。
飞机(机器人)接收连续更新,相应调整飞行路径。
飞行记录仪(轨迹数据库)记录一切,学习典型路线,让管制员能预判飞机通常下一步去哪。
关键概念
- 多方协作: 不同于二元(一人一机)或顺序(轮流)交互,多方协作意味着多个主体同时执行交错子任务,具有紧密的空间和时间耦合。
想象做晚饭:你在切菜,伴侣在搅拌锅,机器人从冰箱取食材——所有事情同时发生在重叠的工作空间。
挑战不仅是协调,还要处理所有人同时移动时的持续遮挡和快速状态变化。
- 抗遮挡追踪: 当物体或人互相遮挡摄像头视野时,单视角系统失去追踪。
多视角系统通过确保如果一个摄像头看不到某物,其他摄像头能看到来解决这个问题。
关键是几何冗余:48个摄像头意味着房间中任何点都能从多个角度看到。
即使人的躯干从10个摄像头挡住了他们的手,剩余38个仍能三角测量其位置。
这不是更高分辨率的问题——而是通过空间多样性消除盲点。
- 共享世界坐标系: 所有传感器和执行器必须对”位置(x, y, z)“的含义达成一致。
没有这个,机器人认为杯子在摄像头看到位置左边10厘米,导致抓取失败。
标定建立单一坐标系统:摄像头知道它们在房间中的位置,机器人知道它们底座在哪,追踪输出房间坐标中的位置。
时间同步确保所有人谈论同一时刻——t=0.5秒的摄像头帧与t=0.5秒的机器人状态对齐,而非t=0.3秒。
框架转变
之前(主流方法):                之后(本文方法):

二元或顺序                        多方并发

人类 <---> 机器人                  人类-A ----+
  ^                                          |
  |                                 人类-B -+-> 共享
  v                                          |   空间
单摄像头                            机器人-1 -+
或标记点                                      |
                                   机器人-2 --+
离线处理
                                   48摄像头阵列
有限工作空间                        (实时融合)

                                   房间尺度覆盖
从孤立的二元交互到并发多方交互,核心转变是将整个房间视为单一可观测系统,而非追踪单个主体对。
专家评审
选题眼光: 这是真实的基础设施缺口,不是人造的。
该领域一直困在二元场景,因为感知问题确实未解决。
作者正确识别出多方协作是家庭机器人必须前进的方向,遮挡是阻碍。
问题处于关键节点:实验室演示已饱和,但真实家庭仍遥不可及。
方法成熟度: 这是工程执行,不是算法创新。
追踪管线使用标准多视角几何和现成的姿态估计器。
洞见是48个摄像头是让抗遮挡追踪在实践中工作的正确密度。
有人可能认为这是蛮力,但当巧妙算法失败了十年,有时简单方法(更多摄像头)就是正确的。
平台设计成熟;
追踪算法是借用的。
实验诚意: 安全和预判实验是概念验证演示,不是严格基准。
基线合理(单视角追踪、无预判),但论文没有与其他多视角系统比较,因为这个规模没有其他系统存在。
数字显示明确增益,但样本量小,场景受控。
真正贡献是让实验本身成为可能,而非确定性的性能声明。
写作功力: 论文前置平台描述,这是正确的——平台是贡献。
然而,应用部分(安全、预判)感觉仓促。
特别是预判实验,如果能更深入分析系统学到了什么行为模式以及为何泛化,会更好。
相关工作部分详尽,但可以更好地阐明为何先前的多视角系统(体育捕捉、VR追踪)不能迁移到这个领域。
判决: 弱接收 — 这是解锁研究方向的基础设施工作。
平台执行良好,问题真实,但科学洞见有限。
这是强workshop论文或系统赛道贡献,不是方法突破。
要点总结
密集传感器覆盖在遮挡下胜过巧妙算法: 如果你的应用涉及近距离交互,不要试图用更好的追踪模型解决遮挡。
增加更多视角,直到遮挡在几何上变得不可能。
48摄像头这个数字是数据点:对于约30平方米的公寓,这个密度有效。
共享世界坐标系对多主体系统不可妥协: 标定和同步很无聊但关键。
如果你在构建任何多传感器输入多执行器的系统,首先投资于坚如磐石的空间和时间对齐基础设施。
作者使用硬件同步触发和仔细标定——偷走这个模式。
轨迹数据库实现预判: 记录长期行为创造了反应式系统缺乏的记忆。
如果你在构建辅助机器人,不要只对当前状态反应——积累轨迹并学习典型模式。
论文显示这对预测人类意图有效,但想法可迁移到任何有重复行为的领域(制造、医疗、物流)。
平台论文被低估: 这不会赢得最佳论文奖,但可能促成十几篇未来论文。
如果你在基础设施是瓶颈的领域,构建并开源平台是高影响力工作,即使直接科学新颖性低。