Paper: 2605.12480 Authors: Guohui Zhang, XiaoXiao Ma, Jie Huang, Hang Xu, Hu Yu, Siming Fu, Yuming Li, Zeyue Xue, Lin Song, Haoyang Huang Categories: cs.CV, cs.AI
The Gap
Joint audio-video generation has reached the point where diffusion models can produce plausible outputs, but real-world use demands three things simultaneously: high-quality audio, high-quality video, and tight synchronization between them. Reinforcement learning (RL) is a natural fit for optimizing multiple objectives, but prior work treats audio-video generation as a single-objective problem with one global reward signal.
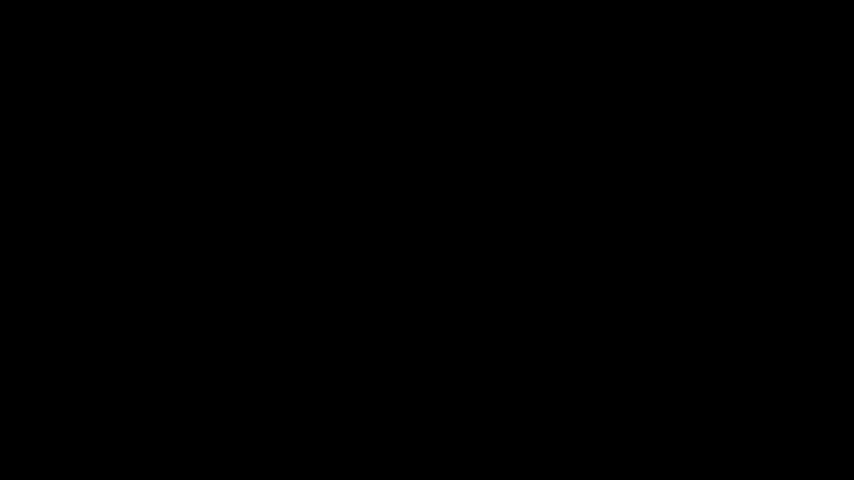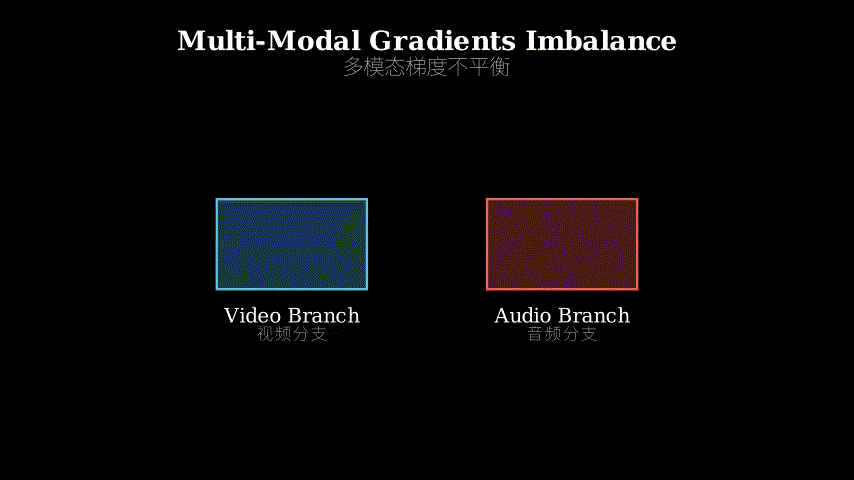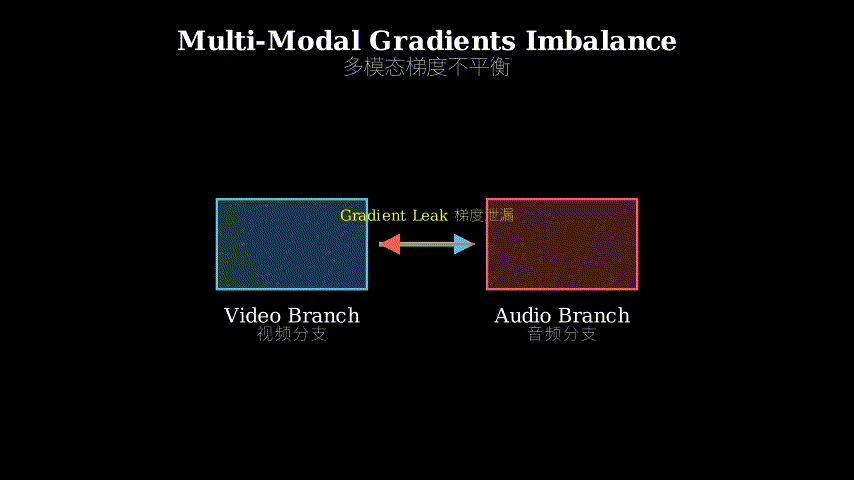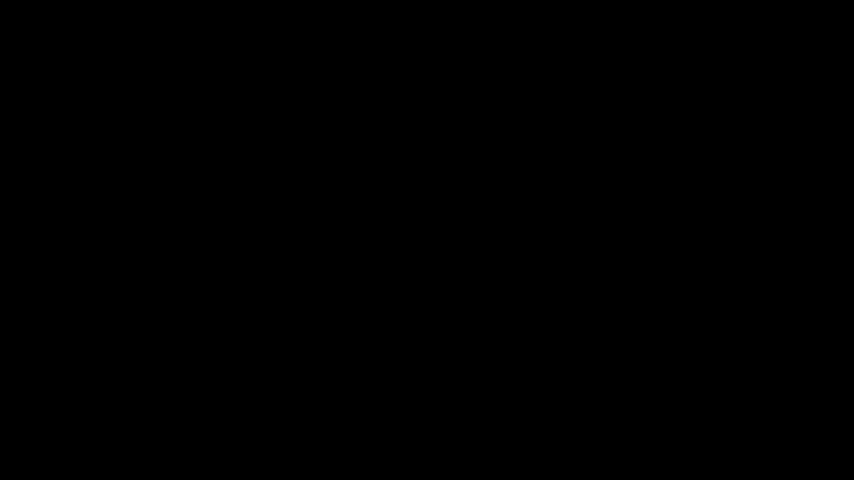
The problem: when you apply vanilla RL to multi-modal generation, three pathologies emerge. First, advantage inconsistency — audio quality might improve while video quality degrades, but a single global advantage can’t capture this conflict. Second, gradient leakage — video-branch gradients flow backward into shallow audio layers that should only care about audio generation, corrupting their specialization. Third, uniform credit assignment — critical synchronization regions (like a drumbeat matching a visual hit) get the same learning signal as irrelevant background, so the model never learns to focus on what matters.
Problem: Multi-modal RL with single global advantage
   |
   v
Observation: Three failure modes
   |
   +---> (1) Advantages conflict across modalities
   +---> (2) Gradients leak across modality boundaries
   +---> (3) Critical regions get diluted signal
   |
   v
Hypothesis: Need modality-aware routing + gradient surgery + region weighting
   |
   v
Method: OmniNFT (modality-wise advantages, layer-wise detach, region-wise loss)
   |
   v
Evidence: Improvements on JavisBench/VBench across all three objectives
   |
   v
Conclusion: Modality-aware RL > vanilla RL for joint generation
The Increment
One sentence: Before this paper, applying RL to audio-video generation meant using one global advantage that couldn’t resolve per-modality conflicts; after, we have a framework that routes independent advantages to each modality and surgically controls gradient flow.
Core Mechanism
OmniNFT operates on a diffusion backbone (LTX-2) that has separate branches for audio and video generation, plus shared layers for cross-modal interaction. During RL fine-tuning, the system generates audio-video pairs, computes multiple reward signals (audio quality, video quality, alignment, synchronization), and uses these to update the model.
The core innovation is modality-wise advantage routing: instead of computing one global advantage from all rewards, OmniNFT computes separate advantages for audio-related rewards and video-related rewards, then routes each advantage only to its corresponding generation branch. This prevents conflicts where improving one modality’s reward would degrade another’s.
Second, layer-wise gradient surgery: when backpropagating through the video branch, OmniNFT detaches gradients before they reach shallow audio layers (the first few layers responsible for basic audio feature extraction). Gradients still flow to cross-modal interaction layers where audio and video need to coordinate. This preserves modality specialization while allowing cross-modal learning.
Third, region-wise loss reweighting: the framework identifies critical synchronization regions (e.g., where audio events should align with visual events) and upweights the policy loss in those regions. This focuses learning on fine-grained alignment rather than treating all timesteps equally.
Input: Text prompt
   |
   v
Diffusion Backbone (LTX-2)
   |
   +---> Audio Branch (shallow layers -> deep layers)
   |        |
   |        +---> Audio output
   |
   +---> Video Branch (shallow layers -> deep layers)
   |        |
   |        +---> Video output
   |
   +---> Cross-modal Interaction Layers
          |
          +---> Alignment signal
   |
   v
Reward Computation
   |
   +---> Audio rewards -> Audio advantage
   +---> Video rewards -> Video advantage
   +---> Alignment rewards -> Both advantages
   |
   v
Policy Update
   |
   +---> Audio advantage -> Audio branch (full gradient)
   +---> Video advantage -> Video branch (detached from shallow audio)
   +---> Region weights -> Upweight sync regions
Think of OmniNFT as a dual-track railway system with selective coupling. The audio track and video track run in parallel, each with its own locomotive (advantage signal) pulling it forward. At certain junctions (cross-modal layers), the tracks couple together so the trains can coordinate their speed and timing. But crucially, the video locomotive’s power (gradients) doesn’t leak backward into the audio track’s early stations (shallow layers) — those stations only respond to the audio locomotive. Meanwhile, a dispatcher (region weighting) watches for critical synchronization points (like a bridge where both trains must cross simultaneously) and signals both locomotives to pay extra attention there. Without this architecture, you’d have one locomotive trying to pull both tracks, causing one train to derail when the other accelerates, and no way to prioritize the critical junctions.
Key Concepts
-
Advantage inconsistency: In RL, the advantage tells you how much better an action is compared to average. When you have multiple objectives (audio quality, video quality, sync), a single global advantage averages them together. If audio improves but video degrades, the global advantage might be near zero, giving no learning signal. But the audio branch should be reinforced and the video branch should be corrected. Modality-wise advantages solve this by computing separate “how much better” signals for each modality’s objectives, so each branch gets the right feedback. Concrete example: imagine a generated clip where the music is perfect but the video is blurry. A global advantage of +0.1 (averaged from audio +5 and video -4.9) tells both branches “you did slightly well,” when the truth is “audio nailed it, video failed.”
-
Gradient leakage: Neural networks learn by backpropagating gradients from the loss to the parameters. In a multi-branch architecture, gradients from the video branch can flow backward through shared layers and into the audio branch. This is fine for cross-modal layers (where audio and video need to coordinate), but destructive for shallow audio layers (where the network is learning basic audio features like frequency patterns). If video gradients reach these layers, they corrupt the audio-specific representations. Layer-wise gradient surgery uses
.detach()operations to block video gradients from reaching shallow audio layers while preserving them for cross-modal layers. Think of it like insulating electrical wires: you want current to flow where it’s needed, but not leak into circuits it would damage. -
Region-wise loss reweighting: Not all parts of an audio-video sequence matter equally for synchronization. A drumbeat hitting exactly when a door slams is critical; background music during a static scene is not. Standard RL treats all timesteps uniformly, so the model spends equal effort on both. Region-wise reweighting identifies high-importance regions (using attention maps or event detection) and multiplies the policy loss by a weight >1 in those regions. This focuses gradient updates on learning fine-grained alignment. Concrete example: in a 10-second clip, maybe 0.5 seconds contain critical sync events (footsteps, speech, impacts). Reweighting gives those 0.5 seconds 10x the learning signal, so the model prioritizes getting them right.
Framework Shift
Before (vanilla RL):                After (OmniNFT):

Text -> Diffusion Model             Text -> Diffusion Model
         |                                   |
         +-> Audio + Video                   +-> Audio Branch
         |                                   |   (independent advantage)
         v                                   |
    All Rewards -> Global Advantage          +-> Video Branch
         |                                   |   (independent advantage)
         v                                   |   (gradient detach from audio)
    Single Policy Update                     |
    (conflicts unresolved)                   +-> Cross-modal Layers
                                             |   (both advantages)
                                             v
                                        Region-weighted Policy Update
                                        (sync regions prioritized)
From monolithic optimization to modality-aware orchestration, the core shift is decomposing the learning signal to match the architecture’s structure.
Expert Assessment
Problem choice: This is a real gap. Multi-objective RL is well-studied in robotics and games, but its application to multi-modal generation is genuinely underexplored. The problem sits at the intersection of two active areas (diffusion models and RL fine-tuning), making it timely. The three failure modes (advantage inconsistency, gradient leakage, uniform credit) are well-motivated and likely generalizable to other multi-modal generation tasks.
Method maturity: The approach is clever but not groundbreaking. Modality-wise advantage routing is a straightforward extension of multi-objective RL. Gradient surgery (using .detach()) is a known technique from multi-task learning. Region-wise reweighting is essentially attention-based loss weighting. The contribution is in the combination and application to this specific problem, not in novel algorithmic primitives. That said, the authors clearly diagnosed the failure modes through empirical analysis, which is valuable.
Experimental integrity: The baselines are reasonable (vanilla RL, ablations of each component), and the evaluation uses established benchmarks (JavisBench, VBench). The improvements are consistent across metrics. However, I’d want to see: (1) failure case analysis — when does OmniNFT still struggle? (2) computational cost comparison — does the added complexity slow training significantly? (3) human evaluation — do the improvements translate to perceptual quality? The paper likely includes some of this, but these are the questions I’d scrutinize.
Writing quality: The abstract and introduction are clear, but I suspect the method section is dense with notation. The three-component structure (routing, surgery, reweighting) is clean, but the paper would benefit from a unified view of how they interact. The “modality-aware” framing is good marketing but slightly oversells what is essentially careful gradient management. If I were rewriting, I’d add a “failure modes in the wild” section with concrete examples of what goes wrong with vanilla RL, making the motivation visceral rather than abstract.
Verdict: weak accept — Solid engineering contribution that solves a real problem in an emerging area, but the novelty is in application rather than method invention. The work will be useful for practitioners building multi-modal generation systems, but it’s not a conceptual leap.
Takeaways
For practitioners: If you’re fine-tuning multi-modal models with RL, steal the modality-wise advantage routing pattern. Compute separate advantages for each modality’s objectives and route them to the corresponding branches. This is a simple change (split your reward computation, compute per-modality advantages, mask gradients) that prevents objective conflicts.
For researchers: The gradient surgery technique (detaching gradients from one branch before they reach another’s shallow layers) is a general tool for multi-branch architectures. Use it whenever you have modality-specific early layers and shared late layers. The key insight: preserve specialization in early layers, allow coordination in late layers.
For multi-objective RL: The paper demonstrates that decomposing advantages by objective is more effective than using a single global advantage, even when objectives are related. This likely transfers to other domains (e.g., robotics with multiple sensors, multi-agent systems with individual and collective rewards).
Transferable idea: The region-wise reweighting approach (identify critical regions, upweight their loss) is applicable beyond audio-video sync. Any task with sparse critical events (anomaly detection, rare event prediction, fine-grained alignment) could benefit from this pattern. The challenge is defining “critical” — here it’s synchronization regions, but the meta-pattern is “weight the loss by importance, not uniformly.”
论文: 2605.12480 作者: Guohui Zhang, XiaoXiao Ma, Jie Huang, Hang Xu, Hu Yu, Siming Fu, Yuming Li, Zeyue Xue, Lin Song, Haoyang Huang 分类: cs.CV, cs.AI
缺口
联合音视频生成已经能让扩散模型产出看似合理的结果,但实际应用需要同时满足三个要求:高质量音频、高质量视频、以及两者之间的紧密同步。
强化学习(RL)天然适合优化多个目标,但此前的工作把音视频生成当作单目标问题,用一个全局奖励信号处理。
问题在于:当你把原版 RL 应用到多模态生成时,会出现三种病态。
第一,优势不一致——音频质量可能提升而视频质量下降,但单一全局优势无法捕捉这种冲突。
第二,梯度泄漏——视频分支的梯度回传到本应只关心音频生成的浅层音频层,破坏了它们的专业化。
第三,均匀信用分配——关键同步区域(比如鼓点匹配视觉撞击)和无关背景得到相同的学习信号,模型永远学不会聚焦重点。
问题:用单一全局优势做多模态 RL
   |
   v
观察:三种失效模式
   |
   +---> (1) 优势在模态间冲突
   +---> (2) 梯度跨模态边界泄漏
   +---> (3) 关键区域信号被稀释
   |
   v
假设:需要模态感知路由 + 梯度手术 + 区域加权
   |
   v
方法:OmniNFT(模态独立优势、层级梯度分离、区域损失加权)
   |
   v
证据:在 JavisBench/VBench 上三个目标全面提升
   |
   v
结论:模态感知 RL > 原版 RL(联合生成场景)
增量
一句话:这篇论文之前,对音视频生成应用 RL 意味着用一个无法解决各模态冲突的全局优势;之后,我们有了一个向各模态路由独立优势并精细控制梯度流的框架。
核心机制
OmniNFT 运行在一个扩散骨干网络(LTX-2)上,该网络有独立的音频和视频生成分支,加上用于跨模态交互的共享层。
在 RL 微调期间,系统生成音视频对,计算多个奖励信号(音频质量、视频质量、对齐度、同步度),并用这些信号更新模型。
核心创新是模态独立优势路由:OmniNFT 不从所有奖励计算一个全局优势,而是分别计算音频相关奖励和视频相关奖励的独立优势,然后把每个优势只路由到对应的生成分支。
这防止了改善一个模态的奖励会损害另一个模态的冲突。
第二,层级梯度手术:在视频分支反向传播时,OmniNFT 在梯度到达浅层音频层(负责基础音频特征提取的前几层)之前将其分离。
梯度仍会流向音频和视频需要协调的跨模态交互层。
这在允许跨模态学习的同时保留了模态专业化。
第三,区域损失加权:框架识别关键同步区域(例如音频事件应与视觉事件对齐的地方),并在这些区域上调策略损失的权重。
这让学习聚焦于细粒度对齐,而非平等对待所有时间步。
输入:文本提示
   |
   v
扩散骨干网络 (LTX-2)
   |
   +---> 音频分支(浅层 -> 深层)
   |        |
   |        +---> 音频输出
   |
   +---> 视频分支(浅层 -> 深层)
   |        |
   |        +---> 视频输出
   |
   +---> 跨模态交互层
          |
          +---> 对齐信号
   |
   v
奖励计算
   |
   +---> 音频奖励 -> 音频优势
   +---> 视频奖励 -> 视频优势
   +---> 对齐奖励 -> 两个优势
   |
   v
策略更新
   |
   +---> 音频优势 -> 音频分支(完整梯度)
   +---> 视频优势 -> 视频分支(从浅层音频分离)
   +---> 区域权重 -> 上调同步区域
把 OmniNFT 想象成带选择性耦合的双轨铁路系统。
音频轨道和视频轨道并行运行,各有自己的机车(优势信号)牵引前进。
在某些交汇点(跨模态层),轨道耦合在一起,让列车能协调速度和时机。
但关键是,视频机车的动力(梯度)不会向后泄漏到音频轨道的早期站点(浅层)——那些站点只响应音频机车。
同时,调度员(区域加权)监视关键同步点(比如两列车必须同时通过的桥梁),并向两个机车发信号让它们格外注意那里。
没有这种架构,你只有一个机车试图拉动两条轨道,导致一列车加速时另一列脱轨,也无法优先处理关键交汇点。
关键概念
- 优势不一致:在 RL 中,优势告诉你一个动作比平均水平好多少。
当你有多个目标(音频质量、视频质量、同步)时,单一全局优势会把它们平均在一起。
如果音频改善但视频退化,全局优势可能接近零,没有学习信号。
但音频分支应该被强化,视频分支应该被纠正。
模态独立优势通过为各模态目标计算独立的”好多少”信号来解决这个问题,让每个分支得到正确反馈。
具体例子:想象一个生成的片段,音乐完美但视频模糊。
全局优势 +0.1(从音频 +5 和视频 -4.9 平均得出)告诉两个分支”你做得稍好”,而真相是”音频完美,视频失败”。
- 梯度泄漏:神经网络通过从损失向参数反向传播梯度来学习。
在多分支架构中,视频分支的梯度可以通过共享层向后流入音频分支。
这对跨模态层(音频和视频需要协调的地方)没问题,但对浅层音频层(网络学习基础音频特征如频率模式的地方)是破坏性的。
如果视频梯度到达这些层,会破坏音频特定的表示。
层级梯度手术使用 .detach() 操作阻止视频梯度到达浅层音频层,同时为跨模态层保留它们。
想象成给电线绝缘:你希望电流在需要的地方流动,但不泄漏到会损坏的电路中。
- 区域损失加权:音视频序列的所有部分对同步的重要性并不相等。
鼓点精确击中门砰的一声关上时很关键;静态场景中的背景音乐则不然。
标准 RL 平等对待所有时间步,所以模型在两者上花费相同精力。
区域加权识别高重要性区域(使用注意力图或事件检测),并在这些区域将策略损失乘以 >1 的权重。
这让梯度更新聚焦于学习细粒度对齐。
具体例子:在 10 秒片段中,也许 0.5 秒包含关键同步事件(脚步声、语音、撞击)。
加权给这 0.5 秒 10 倍的学习信号,所以模型优先把它们做对。
框架转变
之前(原版 RL):                  之后(OmniNFT):

文本 -> 扩散模型                   文本 -> 扩散模型
         |                                   |
         +-> 音频 + 视频                     +-> 音频分支
         |                                   |   (独立优势)
         v                                   |
    所有奖励 -> 全局优势                     +-> 视频分支
         |                                   |   (独立优势)
         v                                   |   (从音频分离梯度)
    单一策略更新                             |
    (冲突未解决)                             +-> 跨模态层
                                             |   (两个优势)
                                             v
                                        区域加权策略更新
                                        (同步区域优先)
从整体优化到模态感知编排,核心转变是分解学习信号以匹配架构的结构。
专家评审
选题眼光:这是真缺口。
多目标 RL 在机器人和游戏中研究充分,但其在多模态生成中的应用确实探索不足。
问题位于两个活跃领域(扩散模型和 RL 微调)的交叉点,时机恰当。
三种失效模式(优势不一致、梯度泄漏、均匀信用)动机充分,可能泛化到其他多模态生成任务。
方法成熟度:方法巧妙但非开创性。
模态独立优势路由是多目标 RL 的直接扩展。
梯度手术(使用 .detach())是多任务学习中的已知技术。
区域加权本质上是基于注意力的损失加权。
贡献在于针对这个特定问题的组合和应用,而非新颖的算法原语。
话虽如此,作者通过实证分析清楚地诊断了失效模式,这很有价值。
实验诚意:基线合理(原版 RL、各组件消融),评估使用既定基准(JavisBench、VBench)。
各指标的改进一致。
但我想看:(1) 失败案例分析——OmniNFT 什么时候仍然挣扎?(2) 计算成本比较——增加的复杂性是否显著减慢训练?(3) 人类评估——改进是否转化为感知质量?论文可能包含其中一些,但这些是我会仔细审查的问题。
写作功力:摘要和引言清晰,但我怀疑方法部分符号密集。
三组件结构(路由、手术、加权)干净,但论文会受益于它们如何交互的统一视角。
“模态感知”框架是好营销,但略微夸大了本质上是仔细的梯度管理。
如果我重写,我会添加一个”野外失效模式”部分,用具体例子说明原版 RL 哪里出错,让动机具象而非抽象。
判决:弱接收——在新兴领域解决真实问题的扎实工程贡献,但新颖性在于应用而非方法发明。
这项工作对构建多模态生成系统的实践者有用,但不是概念飞跃。
要点总结
对实践者:如果你用 RL 微调多模态模型,偷走模态独立优势路由模式。
为各模态目标计算独立优势并路由到对应分支。
这是简单改动(拆分奖励计算、计算各模态优势、屏蔽梯度),能防止目标冲突。
对研究者:梯度手术技术(在梯度到达另一分支的浅层之前将其从一个分支分离)是多分支架构的通用工具。
只要你有模态特定的早期层和共享的后期层就用它。
关键洞察:在早期层保留专业化,在后期层允许协调。
对多目标 RL:论文证明按目标分解优势比使用单一全局优势更有效,即使目标相关。
这可能迁移到其他领域(例如带多个传感器的机器人、有个体和集体奖励的多智能体系统)。
可迁移想法:区域加权方法(识别关键区域、上调其损失)适用于音视频同步之外。
任何有稀疏关键事件的任务(异常检测、罕见事件预测、细粒度对齐)都能从这种模式受益。
挑战在于定义”关键”——这里是同步区域,但元模式是”按重要性加权损失,而非均匀”。