Paper: 2604.02289 Authors: Chongjie Ye, Cheng Cao, Chuanyu Pan, Yiming Hao, Yihao Zhi, Yuanming Hu, Xiaoguang Han Categories: cs.CV, cs.AI
The Gap
The paper is going after a pretty specific bottleneck in current 3D generation.
We already have strong native multimodal models for text and images: one model, one token space, many tasks. But 3D has mostly lagged behind for two reasons. First, there just is not enough high-quality 3D data. Second, a lot of current text-to-3D systems are not really “3D-native” in the same sense that modern text-image models are native. They often work by generating or editing images first, then lifting those results into 3D through optimization, score distillation, multi-view fitting, or reconstruction stages. That works surprisingly often, but it is a brittle workaround.
The abstract is clearly positioning against those indirect pipelines: methods that use strong 2D priors and then recover 3D through optimization. The problem with that family is familiar: geometry is under-constrained, multi-view consistency is fragile, and the system inherits artifacts from the image model rather than learning a unified 3D-capable representation. In other words, existing methods can produce 3D outputs, but they do not really internalize 3D as a first-class modality.
So the gap is not just “better 3D quality.” It is this:
- Can you build a 3D-native foundation model instead of a 2D-first lifting pipeline?
- Can you do it without requiring massive aligned text-image-3D triplets, which basically do not exist at scale?
- Can abundant 2D data be used not merely as supervision for rendering, but as a structural prior for 3D?
That is the hole Omni123 tries to fill. The move is conceptually elegant: if images and 3D describe the same object from different angles of abstraction, maybe consistency across those modalities can itself serve as the missing geometric regularizer.
[Problem]
limited 3D data
indirect 2D_to_3D pipelines
weak geometry consistency
        |
        v
[Assumption]
image and 3D consistency
can act as implicit structure
        |
        v
[Method]
shared token space for
text image 3D
+
interleaved X_to_X training
on heterogeneous pairs
+
semantic visual geometric cycles
        |
        v
[Evidence]
better text_guided 3D generation
better editing
improved multi_view consistency
        |
        v
[Conclusion]
2D abundance can regularize 3D
inside a single 3D_native
autoregressive foundation model
The Increment
One sentence: Before this paper, text-to-3D mostly borrowed intelligence from image models and reconstructed upward; after this paper, there is a clearer recipe for learning text, images, and 3D jointly in one autoregressive model even when fully aligned 3-way data is scarce.
Core Mechanism
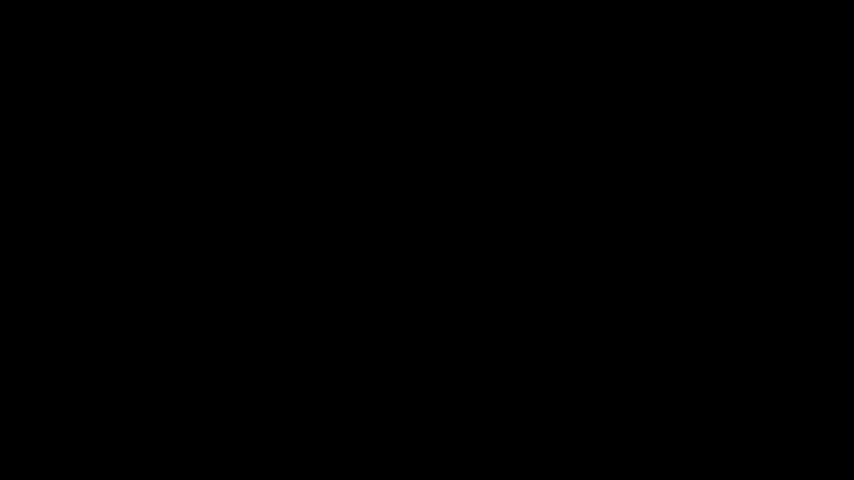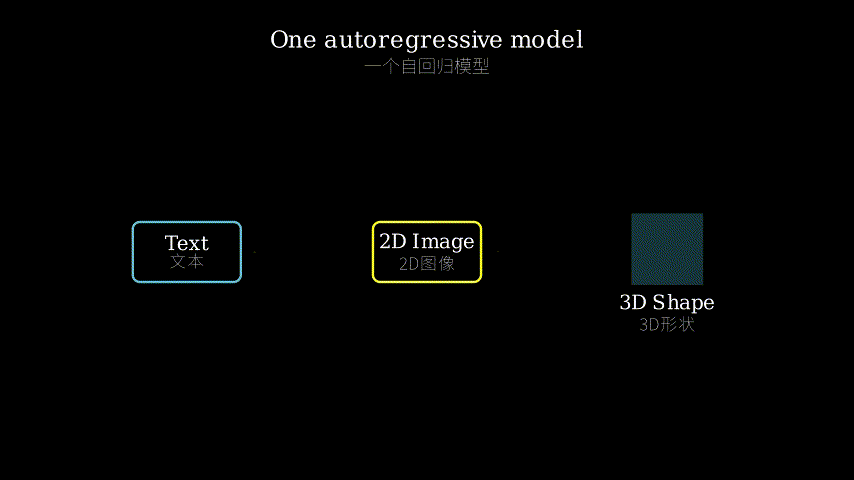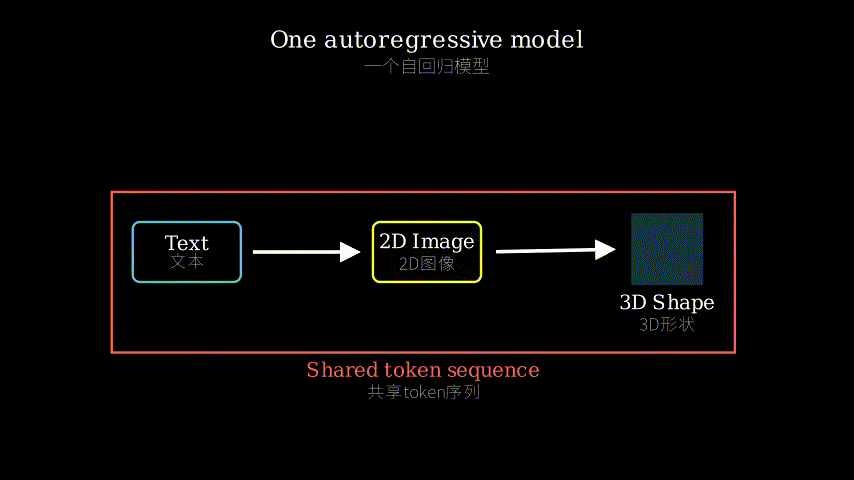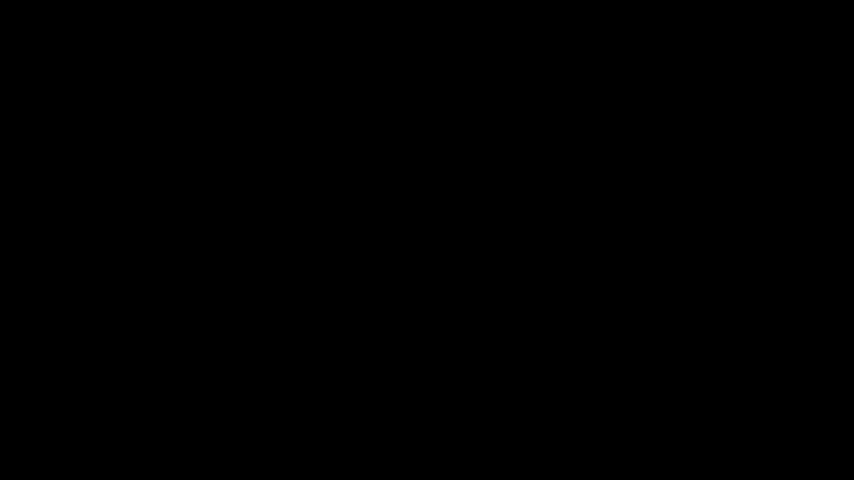
At the center of Omni123 is a unification trick: text, images, and 3D are all represented as discrete tokens in one sequence space, so a single autoregressive model can learn to continue sequences across modalities. Instead of saying “this is a text model plus an image model plus a 3D reconstructor,” the paper says: treat all three as different dialects of the same token language. Then text-to-image, text-to-3D, image-to-3D, 3D-to-image, and editing tasks become different prompting patterns for the same next-token predictor.
The important part is how they train with incomplete data. They do interleaved X-to-X training over heterogeneous paired datasets, meaning they do not require every example to have text, image, and 3D all at once. Some samples may be text-image, some image-3D, some text-3D. By interleaving different cross-modal tasks in sequence form, the model can stitch together a shared representation indirectly. This is the practical answer to the data scarcity problem: instead of waiting for perfect triplets, exploit partial alignments and let the model triangulate.
The other key ingredient is the use of semantic-visual-geometric cycles inside autoregressive sequences. The abstract gives paths like text to image to 3D to image. That matters because it introduces consistency pressure from several directions at once. Text should preserve semantics, image should preserve appearance cues, and 3D should preserve view-consistent geometry. If the model can traverse these loops reliably, then 2D data is no longer just extra supervision; it becomes a scaffold that helps shape better 3D structure.
[text tokens] ---> [shared tokenizer space] ---> [autoregressive transformer] ---> [image tokens]
      |                     |                           |                           ^
      |                     |                           |                           |
      |                     |                           v                           |
      |                     |                      [3D tokens] ---------------------|
      |                     |
      v                     v
[paired datasets]     [interleaved X_to_X sequences]

[text image]
[image 3D]
[text 3D]

training paths:
text > image
text > 3D
image > 3D
3D > image
text > image > 3D > image
text > 3D > image
A load-bearing metaphor here is a three-language translation school.
Imagine you are training one translator who must work across English, sketches, and CAD blueprints. The problem is that you have tons of English-sketch pairs, a modest number of sketch-blueprint pairs, and very few perfectly aligned English-sketch-blueprint triplets. The usual approach would be: translate English into sketches really well, then try to infer blueprints afterward. That gets you plausible drawings, but shaky engineering.
Omni123 instead trains one multilingual translator with a shared internal phrasebook. Text is one language, images are another, 3D is the third. The “interleaved X-to-X” setup is like giving the student mixed homework: sometimes English to sketch, sometimes sketch to blueprint, sometimes blueprint back to sketch. The cycle text to image to 3D to image is like asking the student not just to translate, but to round-trip the meaning and preserve what matters at each step. If the sketch changes too much after passing through the blueprint, you know the blueprint translation lost structure. That is exactly how the model uses 2D abundance to discipline 3D learning.
Key Concepts
-
Shared discrete token space:
Foundation models are good at sequence modeling. So if you can turn text, images, and 3D into token sequences, one model can learn all of them with the same machinery. Think of turning very different media into LEGO bricks of the same connector type. The bricks still mean different things, but now one machine can assemble them in a common process. For example, text tokens might say “a red chair,” image tokens encode how that chair looks in pixels, and 3D tokens encode its shape. Once all are sequences, generating 3D from text becomes “continue this mixed-modality sentence.” -
Cross-modal consistency as implicit supervision:
If you do not have enough 3D labels, you can still force 3D to make sense by checking whether it agrees with images and text. This is like learning the shape of a mug not from a perfect CAD database, but from many photos and captions that all have to line up. If the generated 3D mug renders into views that stop matching the image side of the training signal, the model gets corrected. The geometry is not supervised directly at every point, but it is constrained indirectly by having to stay compatible with other modalities. -
Interleaved X-to-X training:
Instead of training separate systems for separate tasks, you mix tasks into one stream. Sometimes the model sees text and predicts image; sometimes image and predicts 3D; sometimes a longer chain. This matters because the model does not learn “task A” and “task B” in isolation. It learns that all these tasks are connected projections of one latent world. A concrete analogy: rather than taking separate classes in speaking, listening, and writing, you do integrated language drills where each skill supports the others.
Framework Shift
Before (mainstream approach):        After (this paper):

[text]                               [text]
  |                                    |
  v                                    v
[2D image model]                     [shared token space]
  |                                    |
  v                                    v
[optimization lift]                 [one autoregressive model]
  |                                  /   |    \
  v                                 v    v     v
[3D asset]                       [image] [3D] [mixed cycles]
  |
  v
[render check]

text and image do the heavy         text image and 3D are co trained
lifting first                       in one sequence framework
3D is recovered later               with cross modal round trips
From 2D-first reconstruction pipelines to joint autoregressive world modeling across text, image, and 3D, the core shift is treating cross-modal consistency as the training signal that makes scarce 3D data go further.
Expert Assessment
Problem choice: This is a real gap, not a manufactured one. The field has gotten very good at making 3D by leaning on 2D diffusion and optimization, but that recipe is hitting a conceptual ceiling. If people want actual multimodal world models rather than fancy lifting tricks, they need native 3D representations trained under data scarcity. This paper sits right on that transition.
Method maturity: The central insight is clever rather than purely brute force: use shared tokenization plus heterogeneous cross-modal training to squeeze more value out of limited 3D data. That said, this is still a “system paper” in spirit. A lot depends on tokenizer quality, sequence design, and exactly how 3D is discretized. If those pieces are weak, the grand unification story can collapse into engineering fragility. So the idea is strong, but the maturity depends heavily on implementation details that the abstract alone cannot verify.
Experimental integrity: Based on the abstract, the claims are plausible and appropriately scoped: improved text-guided 3D generation and editing, not “solved 3D.” The main thing I would want to inspect closely is baseline selection. For a paper like this, it is easy to compare against older lifting pipelines without fully matching data scale, compute budget, or editing setup. I would also want strong multi-view consistency diagnostics, not just cherry-picked visuals. No obvious red flag from the abstract, but this is exactly the kind of paper where qualitative examples can oversell if the evaluation suite is soft.
Writing quality: The paper seems to have a solid high-level story, but the risk is vagueness around the hardest part: what exactly are the 3D tokens, and how do cycles operationally enforce geometry rather than just encourage modality agreement? If I could rewrite one section, it would be the method section around sequence construction and tokenization. That is the section that determines whether readers see a real foundation-model contribution or just a loosely unified training recipe.
Verdict: weak accept — the problem is important and the framing is genuinely fresh, but the paper will live or die on whether the empirical section proves this is more than a neat unification narrative.
Takeaways
A practitioner can steal several concrete ideas here:
-
Use partial pairings instead of waiting for perfect multimodal triplets.
If your domain has text-image and image-structure data but almost no text-image-structure triples, you can still train a joint model by interleaving tasks. -
Make cycles do regularization work.
Round-trip paths like A to B to C to B are a practical way to impose consistency when direct supervision is sparse. This idea should transfer well to robotics, medical imaging, remote sensing, and audio-video-language setups. -
Treat abundant modalities as priors for scarce ones inside the model, not only in post-processing.
That is the subtle but useful reframing. Do not just use rich modalities to initialize or guide optimization afterward; bake them into training so the scarce modality inherits stronger structure. -
Unified sequence modeling is most compelling when the tasks actually constrain each other.
The lesson is not “tokenize everything because transformers like tokens.” The real payoff comes when one modality can catch another modality’s mistakes.
论文: 2604.02289 作者: Chongjie Ye, Cheng Cao, Chuanyu Pan, Yiming Hao, Yihao Zhi, Yuanming Hu, Xiaoguang Han 分类: cs.CV, cs.AI
缺口
这篇文章抓的不是泛泛的“3D生成还不够好”,而是一个更硬的结构性瓶颈。
现在文本和图像领域已经有了比较像样的统一基础模型:同一个模型里,理解和生成可以共存,很多任务都能塞进一个序列框架里。
但3D这边一直差一口气,核心原因很朴素:高质量3D资产太少,而3D本身又比2D更欠约束。
一张图像只要看起来像就行,一个3D物体却要在多视角下都说得通。
所以过去主流路线,往往不是“原生学会3D”,而是“先借2D模型的脑子,再把结果抬升成3D”。
比如先生成单张或多张图,再通过优化、蒸馏、重建,把它拟合成3D表示。
这条路能出结果,但毛病也很稳定:几何容易飘,多视角一致性差,编辑时容易顾此失彼。
说白了,系统的真正能力还是偏2D,3D更像后处理产物。
Omni123要补的空缺,是下面这个组合问题:
- 能不能做一个3D原生的统一模型,而不是2D先行、3D补票。
- 能不能在没有大规模 text image 3D 三元组的前提下训练起来。
- 能不能把海量2D数据从“辅助监督”升级成“几何先验”。
它的答案很有意思:
图像和3D虽然形式不同,但它们描述的是同一个对象。
如果把这种跨模态一致性用好,它本身就可以变成一种隐式的结构约束,替代一部分本来缺失的3D监督。
[问题]
3D数据稀缺
主流方法先2D后抬升
几何一致性不稳
        |
        v
[假设]
图像和3D之间的一致性
本身可充当结构约束
        |
        v
[方法]
文本 图像 3D
进入共享token空间
+
交错式X_to_X训练
利用异构配对数据
+
语义 视觉 几何循环
        |
        v
[证据]
文本到3D生成更好
3D编辑更稳
多视角一致性提升
        |
        v
[结论]
可用海量2D数据
在统一自回归模型内
补强3D原生能力
增量
一句话: 在这篇论文之前,大家主要是借2D模型“曲线救3D”;在这篇论文之后,至少出现了一条更像基础模型的路子:把文本 图像 3D 放进同一个自回归系统里联合学,并且不依赖完整三模态对齐数据。
核心机制
先说最核心的设计:
Omni123把文本、图像、3D都表示成离散token,然后交给同一个自回归模型去做“下一段序列预测”。
这件事的意义,不只是工程上统一接口。
更关键的是,一旦三种模态都被翻译成同一种序列语言,那么 text to image、text to 3D、image to 3D、3D to image,乃至各种编辑任务,就都变成了“给前缀,续后缀”的同一类问题。
第二个关键是它怎么处理数据不完整。
现实里几乎没有足够多高质量的 text image 3D 三元组。
但有不少 text image 对,也有一些 image 3D 对,可能还有少量 text 3D 对。
Omni123提出的 interleaved X to X 训练,本质上就是把这些不同来源、不同配对关系的数据都编进训练序列里。
模型不要求每个样本三者齐全,而是在不同任务之间来回切换,逐渐把共享表示拼出来。
第三个关键是“循环”。
论文强调 semantic visual geometric cycles,比如 text to image to 3D to image。
这不是花哨写法,它真在承担约束作用。
文本负责盯住语义别跑偏,图像负责盯住外观细节,3D负责盯住跨视角几何别塌。
当模型必须能在这些路径里来回走通,它就被迫学到一种更稳定的跨模态内部结构。
这样一来,海量2D数据就不只是“帮忙生成好看的图”,而是真正参与塑形3D能力。
[text tokens] ---> [共享token空间] ---> [自回归模型] ---> [image tokens]
      |                    |                   |                  ^
      |                    |                   |                  |
      |                    |                   v                  |
      |                    |               [3D tokens] -----------|
      |                    |
      v                    v
[异构配对数据]        [交错式任务序列]

[text image]
[image 3D]
[text 3D]

训练路径:
text > image
text > 3D
image > 3D
3D > image
text > image > 3D > image
text > 3D > image
这里我觉得最适合的核喻是三语翻译学校。
想象你在训练一个翻译员,他要同时会三种“语言”:自然语言、照片、工程蓝图。
现在的问题是,你有很多“自然语言和照片”的对照教材,也有一些“照片和蓝图”的教材,但几乎没有“三者完全对齐”的教材。
旧方法相当于先把自然语言翻译成照片,再拿照片去猜蓝图。
这样做,表面上像是完成了任务,但工程结构往往不牢。
Omni123更像是在训练一个真正的三语翻译员。
它先让三种语言共享一本内部词典,也就是共享token空间。
然后让学生做交错作业:有时语言到照片,有时照片到蓝图,有时蓝图再回照片。
最关键的是“往返翻译”:
如果一句描述先变成照片,再变成蓝图,再渲染回照片,最后还应该保留原来的核心外观和结构。
一旦往返后变形严重,就说明中间那步丢了结构。
这就是这篇论文的脑子:
它不是直接告诉模型“什么是正确3D”,而是通过跨模态来回校对,让模型自己长出更稳的3D表示。
关键概念
-
共享离散token空间:
你可以把它理解成“给不同模态发同一种规格的积木接口”。
文本、图像、3D本来是三种很不一样的数据,但如果都能被编码成token序列,那同一个自回归模型就能处理它们。
重点不在于它们变成了一样的东西,而在于它们现在可以进入同一个句法系统。
例如“一个红色扶手椅”的文本描述、它的图片、它的3D形状,虽然内容层次不同,但都能被放进同一条序列里做条件生成。 -
跨模态一致性作为隐式监督:
当3D标注不够时,你可以不直接告诉模型“这个顶点该在哪”。
你改为要求它生成的3D,必须和文本语义对得上,渲染回图像时也得和视觉外观对得上。
这像是在没有标准工程图的情况下,通过很多照片和描述去逼近一个合理结构。
监督不是逐点给的,而是通过“不允许彼此矛盾”施加的。 -
交错式 X to X 训练:
传统做法容易把 text to image、image to 3D、3D编辑拆成几个独立任务。
交错式训练则把它们混进一个统一训练流里。
这带来的好处是,模型不再把每个任务当孤岛,而是逐渐学会它们都在描述同一个对象世界。
直觉上,这比“每门课单独上”更像“综合训练”,知识更容易互相借力。
框架转变
之前(主流方法):                之后(本文方法):

[text]                            [text]
  |                                 |
  v                                 v
[2D生成模型]                      [共享token空间]
  |                                 |
  v                                 v
[优化式抬升到3D]                 [统一自回归模型]
  |                               /   |    \
  v                              v    v     v
[3D结果]                      [image] [3D] [循环路径]
  |
  v
[再做渲染一致性检查]

先让2D模型承担主要智能               文本 图像 3D一起训练
再从图像往上补3D                     用跨模态循环共同约束结构
一句话:从先有图再补几何,到把语义 视觉 几何放进同一个生成语法里一起学,核心转变是把跨模态一致性从后验检查变成前向训练信号。
专家评审
选题眼光: 这是真缺口。
而且是这个方向迟早都得面对的缺口。
如果3D领域继续只靠2D扩散模型做蒸馏和抬升,那么上限会越来越明显:看起来像,但内部世界模型始终是空心的。
这篇文章踩在一个很对的时间点上,属于“该有人认真把这事往 foundation model 方向推了”。
方法成熟度: 核心想法是有巧劲的。
不是简单堆算力,而是用共享token空间和异构配对训练,把本来稀缺的3D监督放大。
不过它也有明显的系统型风险。
这种方法最后能不能站住,很吃3D离散化方式、序列组织方式、不同任务采样比例这些细节。
也就是说,概念上挺漂亮,工程上不一定轻松。
如果这些底层设计不够扎实,统一框架很容易退化成“看起来统一,实际上每个模态各学各的”。
实验诚意: 从摘要看,作者没有乱吹成“通用3D世界模型已完成”,这一点是加分的。
但我会特别警惕两件事。
第一,基线是否真的公平。
这种论文很容易拿自己训练更大、更杂数据的统一模型去打一些老式两阶段方法。
第二,评测是否过度依赖视觉样例。
3D论文最怕精美案例图很多,系统性多视角一致性和编辑稳定性指标却不够硬。
所以我会说:目前没有明显红旗,但必须看正文实验设计和消融,尤其是不同配对数据各自贡献了什么。
写作功力: 高层故事是顺的。
但这类论文最容易偷懒的地方,恰恰是最关键的技术桥梁:
3D到底如何tokenize。
循环约束究竟怎样具体落地。
它们为什么真的能提升几何,而不是只提升模态间表面一致性。
如果要重写一段,我会重写方法部分里关于序列构造和3D表示的章节。
那一节写清楚了,整篇论文的说服力会直接上一个档次。
判决: 弱接收 — 问题重要,切入角度也新,像是通往3D原生基础模型的一步;但是否足够扎实,最终还得看实验是不是把“统一叙事”落实成了可验证的几何收益。
要点总结
如果你是实践者,这篇论文里有几样东西是可以直接“偷”的。
-
不要死等完整三模态数据。
如果你手里只有 AB 配对和 BC 配对,缺少 ABC 三元组,仍然可以通过交错训练去逼近联合建模。
这在机器人、多传感器感知、医学影像里都很实用。 -
把循环路径当作正则器。
像 A to B to C to B 这种往返路径,不只是为了好看,而是能在直接监督稀缺时提供稳定约束。
这个思路可迁移性很强。 -
让富数据模态在训练时补强稀缺模态。
很多人会把富模态只用在预训练或后处理里。
这篇论文更值得偷的点是:把它直接放进联合生成框架,让它持续给稀缺模态施压。 -
统一模型不是目标,互相纠错才是目标。
不是“万物皆token”就自动高级。
真正有价值的是,一个模态能暴露另一个模态的错误。
图像能帮你抓3D几何崩坏,3D能帮你抓图像多视角不一致。
这才是统一建模最硬的收益。