Paper: 2602.22197 Authors: Xavier Pleimling, Sifat Muhammad Abdullah, Gunjan Balde, Peng Gao, Mainack Mondal, Murtuza Jadliwala, Bimal Viswanath Categories: cs.CV, cs.AI
Abstract
This paper exposes a fundamental weakness in current image protection schemes designed to prevent unauthorized use by generative AI systems. The authors demonstrate that off-the-shelf image-to-image models can be trivially repurposed as generic “denoisers” to remove protective perturbations added to images. Through 8 comprehensive case studies covering 6 different protection mechanisms—including anti-style mimicry, anti-deepfake, and adversarial perturbation schemes—the research shows that a simple text prompt approach not only defeats these protections but often outperforms specialized attacks. This finding suggests that many existing protection methods provide only a false sense of security and highlights the urgent need for more robust defense mechanisms that can withstand attacks from readily available GenAI tools.
Key Contributions
- Demonstrates that off-the-shelf image-to-image GenAI models can serve as universal attack vectors against image protection schemes without requiring specialized training or adaptation
- Evaluates the attack across 6 diverse protection mechanisms spanning multiple threat models, including Glaze, Mist, PhotoGuard, Anti-DreamBooth, and adversarial perturbations
- Shows that the generic denoising approach outperforms existing purpose-built attacks while maintaining high image utility for adversarial purposes
- Provides empirical evidence that current protection schemes are fundamentally vulnerable to a class of attacks that require minimal technical sophistication
- Establishes a new baseline requirement that future protection mechanisms must be benchmarked against off-the-shelf GenAI model attacks
Methodology and Attack Framework
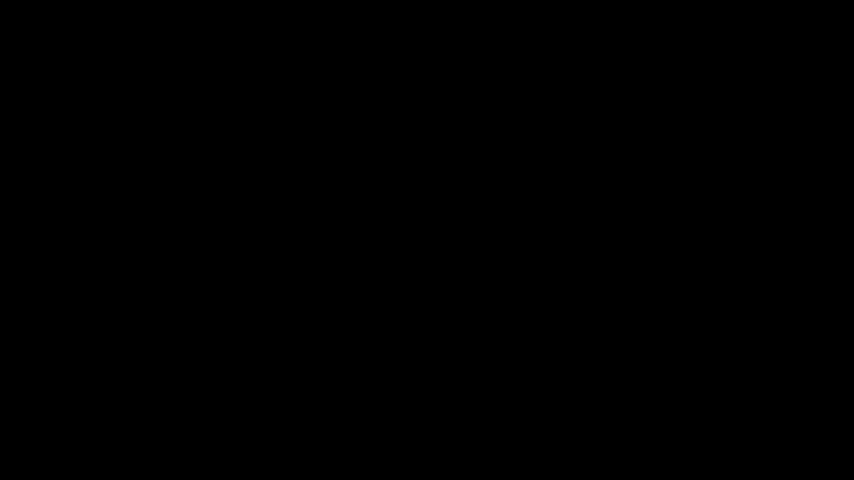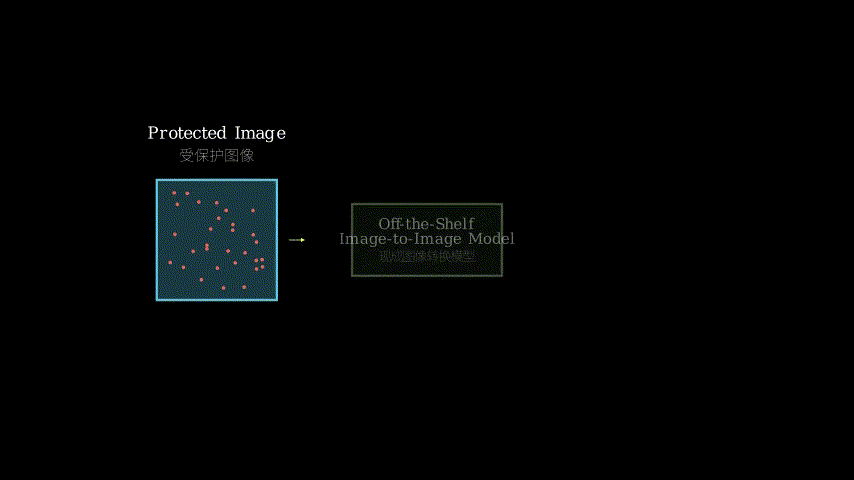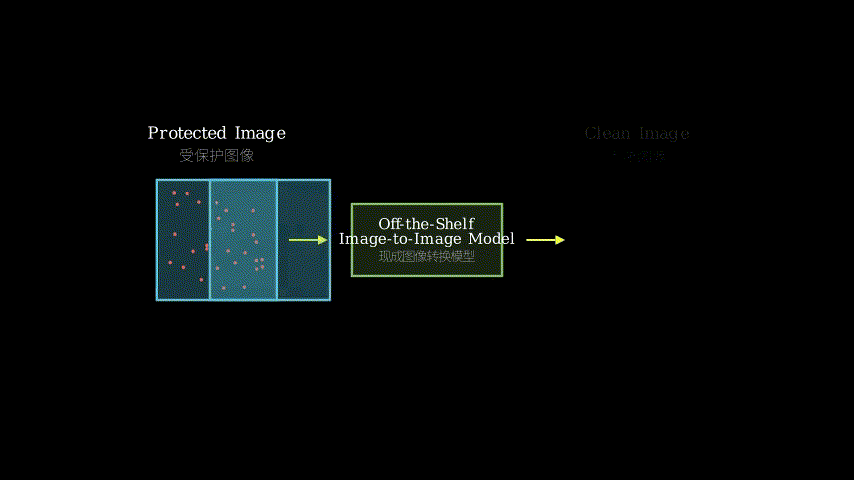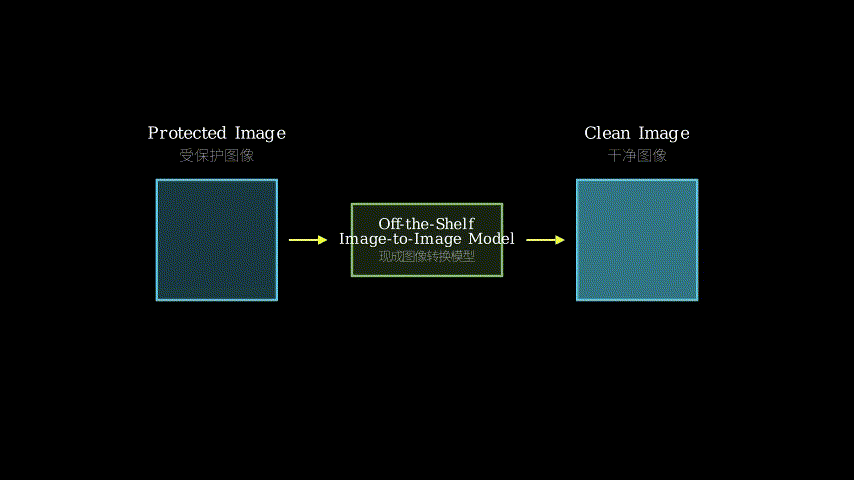
The core insight of this work is deceptively simple yet powerful: image-to-image models trained for general-purpose tasks can be repurposed to remove protective perturbations by treating them as “noise.” The attack framework operates through a straightforward prompting strategy where the protected image is fed into models like Stable Diffusion or similar architectures with prompts designed to preserve content while removing artifacts.
The researchers tested their approach across multiple dimensions:
Protection Schemes Evaluated: The study examined anti-style mimicry tools (Glaze, Mist), anti-deepfake protections (PhotoGuard), anti-personalization defenses (Anti-DreamBooth), and general adversarial perturbations designed to fool classifiers or detectors.
Attack Configuration: Rather than requiring model fine-tuning or specialized architectures, the attack uses standard inference with carefully crafted prompts. The prompts typically instruct the model to “denoise,” “clean,” or “enhance” the image, leveraging the model’s inherent capability to distinguish between semantic content and noise-like perturbations.
Evaluation Metrics: Success was measured through multiple lenses—the ability to enable the originally-blocked misuse (e.g., successful style mimicry after protection removal), perceptual quality metrics (LPIPS, SSIM), and task-specific performance indicators depending on the protection scheme being attacked.
Experimental Results and Analysis
The experimental results reveal a concerning pattern across all tested protection schemes. In every case study, the off-the-shelf image-to-image approach successfully circumvented the protection with high effectiveness:
Against Style Mimicry Protection: For tools like Glaze and Mist that add perturbations to prevent AI from learning an artist’s style, the denoising attack restored sufficient style information to enable successful mimicry. The protected images, when processed through the attack, allowed style transfer models to capture artistic characteristics that were previously obscured.
Against Deepfake Protection: PhotoGuard and similar schemes that aim to disrupt facial manipulation were effectively neutralized. The attack removed protective perturbations while preserving facial features necessary for deepfake generation, enabling the very manipulations the protection was designed to prevent.
Against Personalization Defenses: Anti-DreamBooth protections, which prevent personalized model training on protected images, were bypassed with the cleaned images successfully used for personalization tasks.
Comparative Performance: Notably, the generic attack often matched or exceeded the performance of specialized attacks designed specifically for each protection scheme. This suggests that the vulnerability is not merely theoretical but represents a practical and accessible threat.
The preservation of image utility is particularly significant—the attack maintains perceptual quality and semantic content while removing protections, meaning adversaries can achieve their malicious goals without significant degradation in output quality.
Security Implications and Future Directions
This research fundamentally challenges the current paradigm of image protection. The findings suggest that the “arms race” between protection and attack methods has reached a critical juncture where the accessibility of powerful GenAI tools has shifted the advantage decisively toward attackers.
The False Security Problem: Many users and content creators rely on these protection schemes believing their images are safeguarded. This work demonstrates that such confidence may be misplaced, as the barrier to breaking these protections has been lowered to simply using publicly available tools with basic prompts.
Implications for Defense Design: The results indicate that protection mechanisms must be designed with the assumption that adversaries have access to state-of-the-art image-to-image models. Defenses that rely solely on adding imperceptible perturbations may be inherently vulnerable to this class of attacks.
The Robustness Gap: There exists a fundamental tension between making perturbations imperceptible (to maintain image quality) and making them robust enough to survive denoising by powerful generative models. Current schemes appear to fall on the wrong side of this trade-off.
Future Research Directions: The authors advocate for exploring alternative protection paradigms that don’t rely solely on adversarial perturbations. Potential directions include watermarking schemes that survive generative transformations, cryptographic approaches, or protection mechanisms that operate at different levels of the content creation and distribution pipeline.
Takeaways
-
Off-the-shelf image-to-image GenAI models can defeat a wide range of image protection schemes through simple prompting, without requiring specialized training or sophisticated attack methods.
-
Current protection mechanisms including Glaze, Mist, PhotoGuard, and Anti-DreamBooth are vulnerable to this generic denoising attack, often performing worse against it than against purpose-built attacks.
-
The attack preserves image utility for adversarial purposes while removing protections, enabling the exact misuse scenarios (style mimicry, deepfakes, unauthorized training) that protections aim to prevent.
-
Many existing image protection schemes provide a false sense of security, as the technical barrier to breaking them has been reduced to using readily available tools accessible to non-experts.
-
Future protection mechanisms must be benchmarked against attacks using off-the-shelf GenAI models as a baseline requirement, and the field needs to explore fundamentally different approaches beyond imperceptible adversarial perturbations.
论文: 2602.22197 作者: Xavier Pleimling, Sifat Muhammad Abdullah, Gunjan Balde, Peng Gao, Mainack Mondal, Murtuza Jadliwala, Bimal Viswanath 分类: cs.CV, cs.AI
摘要
本文揭示了当前图像保护方案中的根本性弱点,这些方案旨在防止生成式AI系统未经授权使用图像。研究者证明,现成的图像到图像转换模型可以被轻易地重新用作通用”去噪器”,以移除添加到图像上的保护性扰动。通过涵盖6种不同保护机制的8个综合案例研究——包括反风格模仿、反深度伪造和对抗性扰动方案——研究表明,简单的文本提示方法不仅能够破解这些保护,而且往往优于专门设计的攻击方法。这一发现表明,许多现有的保护方法只提供了虚假的安全感,并凸显了迫切需要更强大的防御机制来抵御现成GenAI工具的攻击。
主要贡献
- 证明现成的图像到图像GenAI模型可以作为针对图像保护方案的通用攻击载体,无需专门训练或适配
- 在涵盖多种威胁模型的6种不同保护机制上评估攻击效果,包括Glaze、Mist、PhotoGuard、Anti-DreamBooth和对抗性扰动
- 表明通用去噪方法在保持高图像实用性的同时,性能优于现有的专用攻击
- 提供实证证据表明当前保护方案从根本上容易受到一类只需最低技术门槛的攻击
- 确立新的基准要求,即未来的保护机制必须针对现成GenAI模型攻击进行基准测试
方法论与攻击框架
这项工作的核心洞察看似简单却极具威力:为通用任务训练的图像到图像模型可以被重新用于移除保护性扰动,将其视为”噪声”处理。攻击框架通过直接的提示策略运作,将受保护的图像输入到Stable Diffusion等模型中,使用旨在保留内容同时移除伪影的提示。
研究人员从多个维度测试了他们的方法:
评估的保护方案: 研究检验了反风格模仿工具(Glaze、Mist)、反深度伪造保护(PhotoGuard)、反个性化防御(Anti-DreamBooth),以及旨在欺骗分类器或检测器的通用对抗性扰动。
攻击配置: 攻击不需要模型微调或专门架构,而是使用标准推理配合精心设计的提示。提示通常指示模型”去噪”、“清理”或”增强”图像,利用模型固有的区分语义内容和类噪声扰动的能力。
评估指标: 成功通过多个角度衡量——能够实现原本被阻止的滥用(例如,移除保护后成功进行风格模仿)、感知质量指标(LPIPS、SSIM),以及根据被攻击保护方案的特定任务性能指标。
实验结果与分析
实验结果在所有测试的保护方案中揭示了令人担忧的模式。在每个案例研究中,现成的图像到图像方法都以高效性成功绕过了保护:
针对风格模仿保护: 对于Glaze和Mist等添加扰动以防止AI学习艺术家风格的工具,去噪攻击恢复了足够的风格信息以实现成功的模仿。经过攻击处理的受保护图像,允许风格迁移模型捕获之前被掩盖的艺术特征。
针对深度伪造保护: PhotoGuard等旨在破坏面部操纵的方案被有效中和。攻击在保留深度伪造生成所需的面部特征的同时移除了保护性扰动,使得保护原本要防止的操纵成为可能。
针对个性化防御: Anti-DreamBooth保护旨在防止在受保护图像上进行个性化模型训练,但被绕过,清理后的图像成功用于个性化任务。
比较性能: 值得注意的是,通用攻击往往匹配或超过专门为每种保护方案设计的专用攻击的性能。这表明该漏洞不仅是理论上的,而且代表了一个实际且易于实现的威胁。
图像实用性的保持尤为重要——攻击在移除保护的同时保持了感知质量和语义内容,这意味着攻击者可以在输出质量没有显著下降的情况下实现其恶意目标。
安全影响与未来方向
这项研究从根本上挑战了当前的图像保护范式。研究结果表明,保护与攻击方法之间的”军备竞赛”已经到达关键节点,强大GenAI工具的可及性已将优势决定性地转向攻击者一方。
虚假安全问题: 许多用户和内容创作者依赖这些保护方案,相信他们的图像得到了保护。这项工作表明,这种信心可能是错位的,因为破解这些保护的门槛已经降低到只需使用公开可用的工具配合基本提示。
对防御设计的影响: 结果表明,保护机制的设计必须假设攻击者可以访问最先进的图像到图像模型。仅依赖添加不可感知扰动的防御可能从根本上容易受到这类攻击。
鲁棒性差距: 在使扰动不可感知(以保持图像质量)和使其足够鲁棒以抵御强大生成模型的去噪之间存在根本性张力。当前方案似乎处于这种权衡的错误一侧。
未来研究方向: 作者倡导探索不仅依赖对抗性扰动的替代保护范式。潜在方向包括能够在生成变换中存活的水印方案、密码学方法,或在内容创建和分发管道的不同层级运作的保护机制。
要点总结
-
现成的图像到图像GenAI模型可以通过简单提示破解广泛的图像保护方案,无需专门训练或复杂的攻击方法。
-
当前的保护机制包括Glaze、Mist、PhotoGuard和Anti-DreamBooth都容易受到这种通用去噪攻击,往往比针对专用攻击的表现更差。
-
攻击在移除保护的同时保持了对抗性目的的图像实用性,使得保护旨在防止的确切滥用场景(风格模仿、深度伪造、未经授权的训练)成为可能。
-
许多现有的图像保护方案提供了虚假的安全感,因为破解它们的技术门槛已降低到使用非专家可访问的现成工具。
-
未来的保护机制必须将使用现成GenAI模型的攻击作为基准要求进行测试,该领域需要探索超越不可感知对抗性扰动的根本不同方法。