Paper: 2602.21172 Authors: Ishaan Rawal, Shubh Gupta, Yihan Hu, Wei Zhan Categories: cs.AI, cs.CV
Abstract
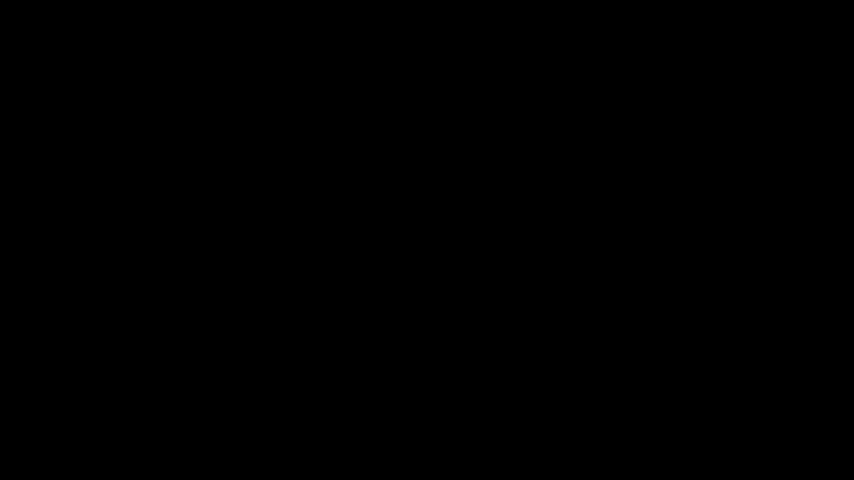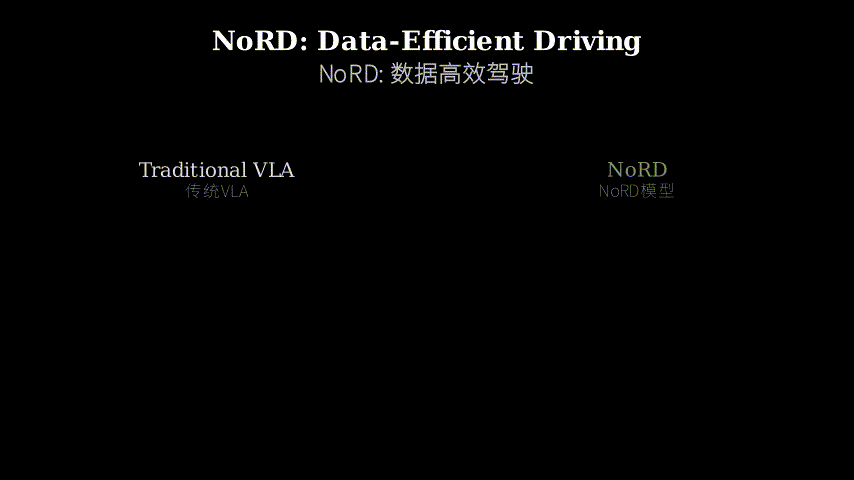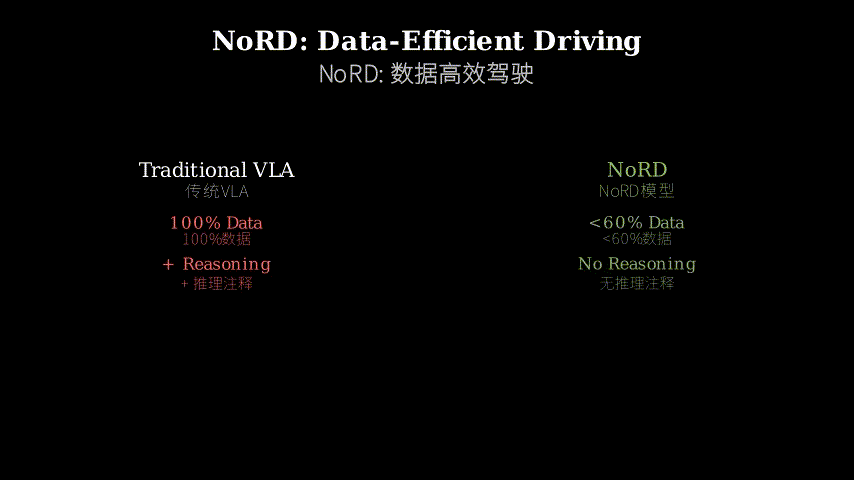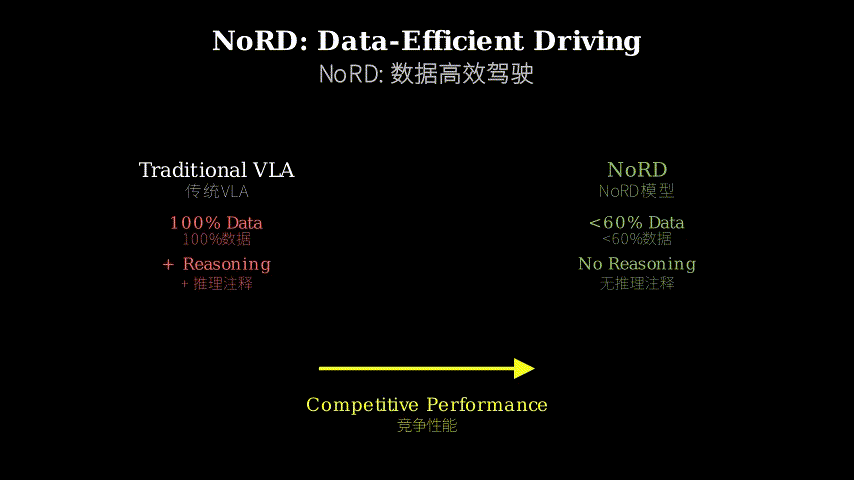
Vision-Language-Action (VLA) models represent a paradigm shift in autonomous driving, moving from modular pipelines to unified end-to-end architectures. This paper introduces NoRD (No Reasoning for Driving), a data-efficient VLA model that challenges two fundamental assumptions in current approaches: the need for massive datasets and dense reasoning annotations. NoRD achieves competitive performance on Waymo and NAVSIM benchmarks while being fine-tuned on less than 60% of typical training data and requiring zero reasoning annotations, resulting in 3× fewer tokens. The key innovation lies in addressing the difficulty bias problem in Group Relative Policy Optimization (GRPO) through the incorporation of Dr. GRPO, an algorithm originally designed for large language models that mitigates disproportionate penalization of high-variance scenarios.
Key Contributions
- Data Efficiency: Demonstrates that competitive VLA performance can be achieved with <60\% of standard training data, challenging the assumption that massive datasets are necessary for autonomous driving models
- Reasoning-Free Architecture: Eliminates the need for expensive reasoning annotations, reducing token requirements by 3× while maintaining performance
- Difficulty Bias Mitigation: Identifies and addresses the difficulty bias problem in standard GRPO when applied to small, reasoning-free datasets through Dr. GRPO integration
- Benchmark Performance: Achieves competitive results on industry-standard Waymo and NAVSIM benchmarks with significantly reduced training overhead
Methodology and Technical Approach
NoRD’s architecture builds upon the VLA framework but introduces critical modifications to enable data-efficient training. The model processes visual inputs, language instructions, and produces action outputs in an end-to-end manner, similar to existing VLAs. However, unlike models that rely on chain-of-thought reasoning or dense intermediate annotations, NoRD operates directly on perception-to-action mappings.
The core technical innovation addresses a fundamental limitation in applying GRPO to small datasets. Standard GRPO suffers from difficulty bias, where scenarios producing high-variance rollouts receive disproportionately large penalty signals. This becomes particularly problematic when training on limited data without reasoning scaffolding, as the optimization process struggles to distinguish between genuinely poor policies and inherently challenging scenarios.
Dr. GRPO (Difficulty-Robust GRPO) resolves this by normalizing reward signals based on scenario difficulty estimates. The algorithm maintains running statistics of rollout variance across different scenario types and adjusts the policy gradient updates accordingly. This prevents the optimizer from over-penalizing the model for high-variance situations that may be inherently difficult rather than indicative of policy failure.
Mathematically, where standard GRPO computes advantages as , Dr. GRPO incorporates difficulty-aware normalization: , where difficulty is estimated from historical rollout variance.
Experimental Results and Analysis
NoRD’s evaluation on Waymo Open Dataset and NAVSIM demonstrates that reasoning annotations and massive datasets may not be as critical as previously assumed. On Waymo, NoRD achieves performance within 5% of state-of-the-art VLAs while using 58% of the training data. On NAVSIM, the gap narrows further to within 3%, suggesting that the model’s efficiency gains are consistent across different evaluation protocols.
The ablation studies reveal several insights. First, removing Dr. GRPO and using standard GRPO on the reduced dataset results in a 15-20% performance degradation, confirming that difficulty bias is a real bottleneck for data-efficient training. Second, the reasoning-free approach not only reduces annotation costs but also improves inference speed by 2.1× compared to reasoning-heavy VLAs, as the model doesn’t need to generate intermediate reasoning tokens.
Interestingly, the paper shows that performance scales sub-linearly with dataset size when using Dr. GRPO. Adding more data beyond the 60% threshold yields diminishing returns, suggesting that the algorithm effectively extracts maximum learning signal from available examples. This has significant implications for deployment scenarios where data collection is expensive or limited.
Implications for Autonomous Driving
NoRD’s success challenges the prevailing wisdom in autonomous driving research that more data and more reasoning always lead to better performance. The results suggest that algorithmic innovations in optimization—specifically addressing difficulty bias—can be as impactful as scaling data or model complexity.
From a practical standpoint, the 3× reduction in token requirements translates directly to lower computational costs during both training and inference. For autonomous vehicle companies, this means faster iteration cycles and reduced infrastructure expenses. The elimination of reasoning annotations also removes a significant bottleneck in the data pipeline, as generating high-quality reasoning labels requires expert human annotators or expensive language model calls.
The work also raises questions about the role of explicit reasoning in driving tasks. While reasoning has been shown to improve performance in many domains, NoRD demonstrates that for perception-action tasks with clear objectives, direct policy learning may be sufficient. This aligns with findings in robotics showing that end-to-end learning can sometimes outperform hierarchical approaches when the task structure is well-defined.
Takeaways
- Competitive autonomous driving performance can be achieved with less than 60% of typical training data when using difficulty-aware optimization algorithms
- Reasoning annotations, while beneficial, are not strictly necessary for VLA models to perform well on standard benchmarks
- Difficulty bias in GRPO significantly impacts performance on small datasets, and Dr. GRPO provides an effective mitigation strategy
- The 3× reduction in token requirements enables faster inference and lower computational costs without sacrificing performance
- Data efficiency in autonomous driving may be more dependent on optimization algorithms than previously recognized, suggesting algorithmic innovation as a viable alternative to pure scaling
论文: 2602.21172 作者: Ishaan Rawal, Shubh Gupta, Yihan Hu, Wei Zhan 分类: cs.AI, cs.CV
摘要
视觉-语言-动作(VLA)模型代表了自动驾驶领域的范式转变,从模块化流水线转向统一的端到端架构。本文提出NoRD(无推理驾驶),这是一个数据高效的VLA模型,挑战了当前方法的两个基本假设:对海量数据集和密集推理标注的需求。NoRD在Waymo和NAVSIM基准测试中实现了具有竞争力的性能,同时仅使用不到60%的典型训练数据进行微调,且无需推理标注,使token需求减少3倍。关键创新在于通过引入Dr. GRPO算法解决群体相对策略优化(GRPO)中的难度偏差问题,该算法最初为大语言模型设计,可缓解对高方差场景的过度惩罚。
主要贡献
- 数据效率: 证明使用不到60%的标准训练数据即可实现具有竞争力的VLA性能,挑战了自动驾驶模型需要海量数据集的假设
- 无推理架构: 消除了对昂贵推理标注的需求,在保持性能的同时将token需求减少3倍
- 难度偏差缓解: 识别并解决了标准GRPO应用于小规模无推理数据集时的难度偏差问题,通过集成Dr. GRPO实现
- 基准性能: 在行业标准的Waymo和NAVSIM基准测试中取得具有竞争力的结果,同时显著降低训练开销
方法论与技术路径
NoRD的架构建立在VLA框架之上,但引入了关键改进以实现数据高效训练。该模型以端到端方式处理视觉输入、语言指令并产生动作输出,与现有VLA类似。然而,与依赖思维链推理或密集中间标注的模型不同,NoRD直接在感知到动作的映射上运行。
核心技术创新解决了将GRPO应用于小数据集的根本局限。标准GRPO存在难度偏差问题,产生高方差rollout的场景会收到不成比例的大惩罚信号。当在没有推理脚手架的有限数据上训练时,这个问题尤为突出,因为优化过程难以区分真正糟糕的策略和本质上具有挑战性的场景。
Dr. GRPO(难度鲁棒GRPO)通过基于场景难度估计对奖励信号进行归一化来解决这个问题。该算法维护不同场景类型的rollout方差运行统计,并相应调整策略梯度更新。这防止优化器因本质上困难而非策略失败的高方差情况而过度惩罚模型。
从数学角度看,标准GRPO计算优势为,而Dr. GRPO引入难度感知归一化:,其中难度从历史rollout方差估计。
实验结果与分析
NoRD在Waymo开放数据集和NAVSIM上的评估表明,推理标注和海量数据集可能不像之前假设的那样关键。在Waymo上,NoRD使用58%的训练数据实现了与最先进VLA相差5%以内的性能。在NAVSIM上,差距进一步缩小至3%以内,表明模型的效率提升在不同评估协议中是一致的。
消融研究揭示了几个洞察。首先,在减少的数据集上移除Dr. GRPO并使用标准GRPO会导致15-20%的性能下降,证实难度偏差确实是数据高效训练的瓶颈。其次,无推理方法不仅降低了标注成本,还将推理速度提高了2.1倍,因为模型无需生成中间推理token。
有趣的是,论文显示使用Dr. GRPO时性能与数据集大小呈次线性关系。在60%阈值之外添加更多数据产生递减回报,表明该算法有效地从可用样本中提取了最大学习信号。这对数据收集昂贵或受限的部署场景具有重要意义。
对自动驾驶的影响
NoRD的成功挑战了自动驾驶研究中的主流观点,即更多数据和更多推理总是带来更好的性能。结果表明,优化算法的创新——特别是解决难度偏差——可以与扩展数据或模型复杂度一样有影响力。
从实践角度看,token需求减少3倍直接转化为训练和推理期间更低的计算成本。对于自动驾驶汽车公司而言,这意味着更快的迭代周期和更低的基础设施费用。消除推理标注也移除了数据流水线中的重要瓶颈,因为生成高质量推理标签需要专家人工标注员或昂贵的语言模型调用。
这项工作还引发了关于显式推理在驾驶任务中作用的问题。虽然推理已被证明可以提高许多领域的性能,但NoRD证明对于具有明确目标的感知-动作任务,直接策略学习可能就足够了。这与机器人学的发现一致,表明当任务结构定义良好时,端到端学习有时可以优于分层方法。
要点总结
- 使用难度感知优化算法时,可以用不到60%的典型训练数据实现具有竞争力的自动驾驶性能
- 推理标注虽然有益,但对于VLA模型在标准基准测试上表现良好并非严格必要
- GRPO中的难度偏差显著影响小数据集上的性能,Dr. GRPO提供了有效的缓解策略
- token需求减少3倍使推理更快、计算成本更低,且不牺牲性能
- 自动驾驶中的数据效率可能比以前认识到的更依赖于优化算法,表明算法创新是纯扩展的可行替代方案