Paper: 2605.13817 Authors: Bethel Hall, William Eiers Categories: cs.SE, cs.AI
The Gap
Existing formal verification catches bugs in code, but assumes the specification is correct. In safety-critical domains (medical devices, avionics), requirements are written in natural language by domain experts, not logicians. These requirements are ambiguous (“the system should respond quickly”), inconsistent (requirement A contradicts B), or underspecified (missing edge cases). Traditional approaches either (1) manually formalize requirements—expensive, error-prone, and doesn’t scale—or (2) use NLP to extract structure—but can’t verify logical properties or detect subtle inconsistencies.
The gap: no automated way to audit natural-language requirements for the defects that matter most—ambiguity that leads to multiple valid interpretations, logical inconsistencies, and safety violations—before they propagate into formal models and shipping code.
Problem: NL requirements → ambiguous/inconsistent → wrong formal spec → unsafe code
                                    ^
                                    |
                          No automated audit here
                                    |
                                    v
Gap: Need to detect defects in NL requirements before formalization
     |
     +---> Assumption: LLMs can formalize NL → logic, SMT solvers can check logic
                       |
                       v
Method: LLM translates NL → SMT formulas (multiple times)
        Stochastic variation → ambiguity signal
        SMT queries → detect inconsistency, vacuousness, safety violations
        |
        v
Evidence: Hemodialysis requirements dataset
          - Ambiguity detection via SMT-inequivalent formalizations
          - Counterexample-guided repair: 55.4% → 98.5% verified accuracy
          |
          v
Conclusion: Neurosymbolic auditing (LLM + SMT) catches requirement defects
            before they reach code
The Increment
One sentence: Before this paper, catching ambiguity in natural-language requirements required manual review by experts; after, an LLM+SMT pipeline automatically flags ambiguous requirements by checking if independent formalizations are logically equivalent.
Core Mechanism
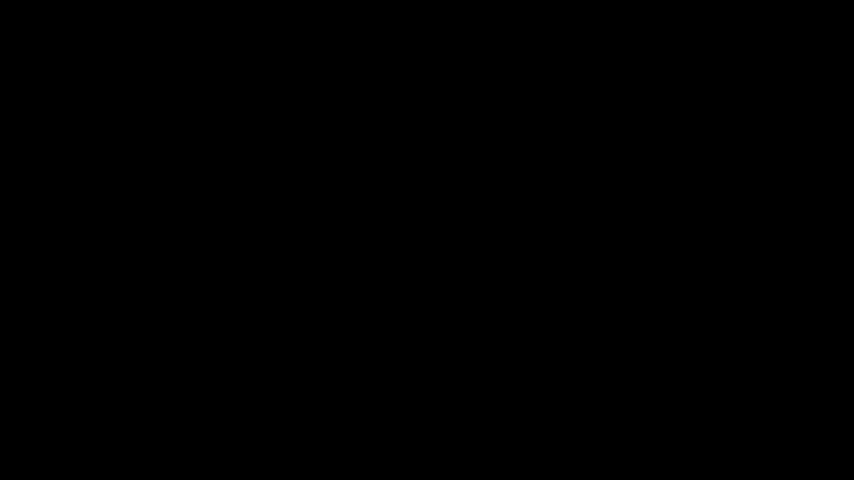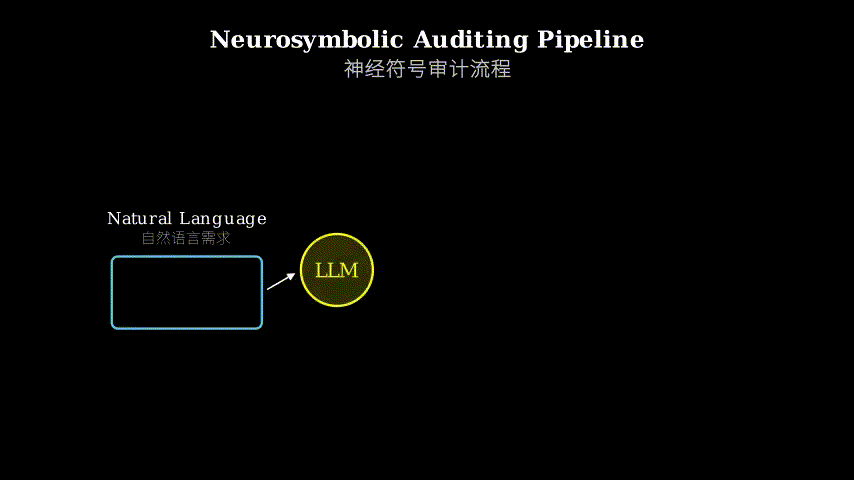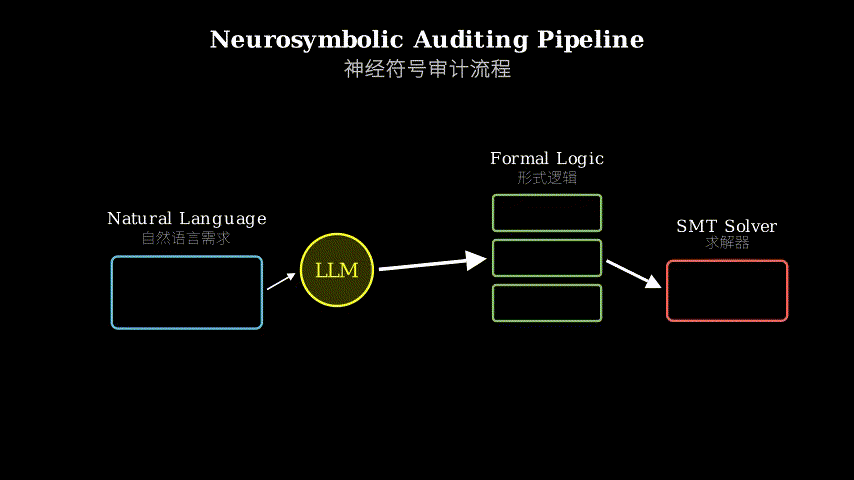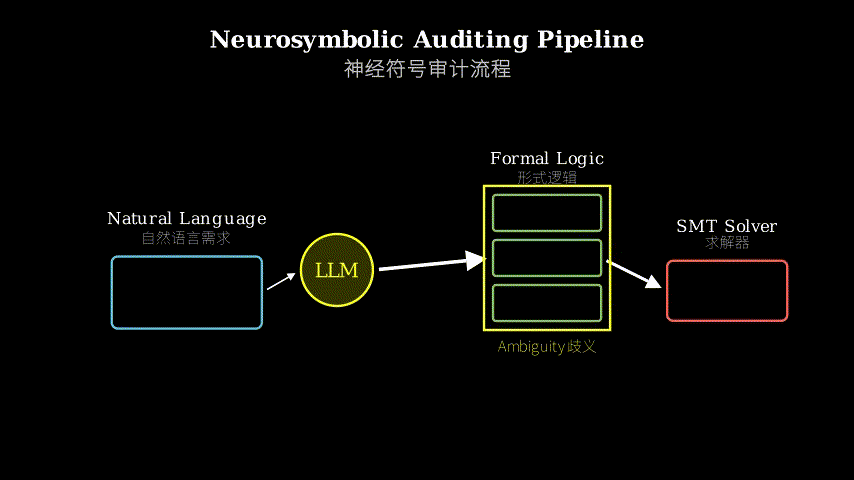
VERIMED operates in three stages. First, an LLM translates each natural-language requirement into SMT-LIB format (first-order logic formulas) multiple times independently—think of it as asking the LLM to “read” the requirement several times without memory of prior readings. Second, the system checks if these formalizations are logically equivalent using bidirectional SMT queries: does formalization A imply B, and does B imply A? If they’re inequivalent, the requirement is flagged as ambiguous. Third, once formalized, the system runs symbolic queries: checking for contradictions (unsatisfiable conjunctions), vacuousness (tautologies that accept everything), and safety violations (counterexamples where unsafe states are reachable).
NL Requirement
      |
      v
+-----+-----+-----+
|     |     |     |  (LLM translates independently, N times)
v     v     v     v
SMT₁  SMT₂  SMT₃  SMT₄  (formulas in first-order logic)
 |     |     |     |
 +-----+-----+-----+
       |
       v
  Equivalence Check:  SMT₁ ⟺ SMT₂?  SMT₂ ⟺ SMT₃?  ...
       |
       +---> Inequivalent? → Flag as AMBIGUOUS
       |
       +---> Equivalent? → Merge into single spec
                            |
                            v
                       Symbolic Queries:
                       - Satisfiable? (not vacuous)
                       - Consistent with other reqs?
                       - Safety property holds?
                            |
                            v
                       Report: inconsistencies, violations, counterexamples
Think of VERIMED as a translation quality control system for legal contracts. Imagine you have a contract clause in plain English, and you ask three independent translators to convert it into formal legal language. If all three produce identical formal clauses, the original was unambiguous. If they diverge—one translator interprets “promptly” as “within 24 hours,” another as “within 1 hour”—you’ve found ambiguity. VERIMED does this for software requirements: the LLM is the translator, SMT-LIB is the formal legal language, and the SMT solver is the judge who checks if the translations are logically identical. Once you have a clean formal version, the judge can also check if it contradicts other clauses (inconsistency), if it’s so vague it allows anything (vacuousness), or if it permits dangerous scenarios (safety violations). The key insight: stochastic variation in translation is a measurable signal of ambiguity in the source text.
Key Concepts
-
SMT (Satisfiability Modulo Theories): Imagine a super-powered equation solver that works not just with numbers, but with logic statements about integers, real numbers, arrays, and other structures. You give it a set of constraints (e.g., “x
> 5AND x< 3”) and it tells you if there’s any assignment of values that makes all constraints true simultaneously. If no such assignment exists, the constraints are inconsistent. In VERIMED, SMT checks if two logical formulas are equivalent (do they accept the same set of scenarios?) and whether a requirement specification is satisfiable (does it allow any valid system behavior, or is it self-contradictory?). Concrete example: requirement says “alarm activates when pressure> 100” and another says “alarm never activates when pressure ≤ 150.” SMT solver finds these are consistent (both can be true), but if the second said “alarm never activates when pressure> 50,” SMT would flag a contradiction. -
Bidirectional equivalence checking: Two logical formulas A and B are equivalent if they’re true in exactly the same situations. To check this, you ask two questions: (1) Does A imply B? (meaning: whenever A is true, is B also true?) and (2) Does B imply A? If both answers are yes, A and B are equivalent—they’re just different ways of saying the same thing. If either answer is no, they’re inequivalent—they permit different behaviors. VERIMED uses this to detect ambiguity: if the LLM produces two inequivalent formalizations of the same requirement, the requirement admits multiple interpretations. Example: requirement says “system responds quickly.” One formalization might be “response time
< 1second,” another “response time< 5seconds.” These are inequivalent (the second allows behaviors the first forbids), so the requirement is ambiguous. -
Counterexample-guided repair: When a system fails a test, instead of just saying “wrong,” you show it a concrete example of the failure and let it fix the mistake. In VERIMED, when an LLM-generated formalization produces a wrong answer on a test question, the SMT solver generates a counterexample—a specific scenario where the formalization gives the wrong result. This counterexample is fed back to the LLM with the instruction “your formalization failed on this case; fix it.” The LLM revises the formalization, and the loop repeats until tests pass. Example: formalization says “alarm triggers when pressure
> 100,” but test case shows alarm should trigger at pressure = 100 (boundary case). SMT solver provides counterexample: “pressure = 100, alarm = off, but should be on.” LLM revises to “pressure ≥ 100.”
Framework Shift
Before (manual formalization):        After (VERIMED):

Domain Expert                         Domain Expert
     |                                      |
     | writes NL requirements               | writes NL requirements
     v                                      v
NL Requirements Doc                   NL Requirements Doc
     |                                      |
     | (manual, weeks)                      | (automated, minutes)
     v                                      v
Formal Methods Expert                 LLM (translate × N)
     |                                      |
     | hand-crafts logic                    | produces N formalizations
     v                                      v
Single Formalization                  SMT Solver
     |                                      |
     | (assumed correct)                    | checks equivalence
     v                                      v
Verification                          Ambiguity Report + Merged Spec
     |                                      |
     | finds bugs in code,                  | finds bugs in requirements
     | not requirements                     | before code exists
     v                                      v
Ship (with spec bugs)                 Symbolic Queries → Safety Report
[From sequential expert handoff to parallel stochastic auditing, the core shift is: treat formalization variance as signal, not noise.]
Expert Assessment
Problem choice: Real gap. Safety-critical requirements defects cause recalls and deaths (Therac-25, Boeing 737 MAX). Existing formal methods assume correct specs—garbage in, gospel out. This paper attacks the root: auditing requirements before formalization. The problem sits at the intersection of SE and AI, timely given LLM capabilities.
Method maturity: Clever use of stochastic sampling as an ambiguity detector—this is not obvious and the bidirectional equivalence check is elegant. However, the approach inherits LLM brittleness: if the model consistently misinterprets a requirement the same way across all samples, ambiguity goes undetected. The paper doesn’t deeply explore this failure mode or provide theoretical bounds on detection probability. The counterexample-guided repair is standard program synthesis, not novel, but the application to requirements is fresh.
Experimental integrity: Baselines are fair (manual formalization, direct LLM QA). The hemodialysis dataset is real (open-source FDA requirements), not synthetic. The 55.4% → 98.5% improvement is striking, but the paper doesn’t report how many repair iterations were needed or whether some requirements never converged. The ambiguity detection experiments lack ground truth—no human-annotated “truly ambiguous” requirements to measure precision/recall against. The paper relies on SMT-inequivalence as a proxy, which is reasonable but unvalidated.
Writing quality: The paper front-loads motivation well, but the technical sections are dense. The VERIMED pipeline description (Section 3) would benefit from a running example—show one requirement flowing through all stages. The evaluation (Section 4) jumps between datasets and metrics without clear narrative structure. Rewriting Section 4 to tell a story (“first we show ambiguity detection works, then we show repair works, then we show end-to-end auditing works”) would clarify contributions.
Verdict: weak accept — Solid idea with real-world impact, but experimental gaps (no ground truth for ambiguity, no failure mode analysis) and presentation issues prevent strong accept. The core insight (stochastic formalization variance as ambiguity signal) is valuable and the results are promising, but the paper needs another revision to be definitive.
Takeaways
Stochastic sampling as a consistency check: Beyond requirements, this applies anywhere you translate informal → formal. Generate multiple formalizations, check equivalence, flag divergence. Works for: API documentation → type signatures, legal contracts → executable rules, user stories → test cases. The key: use a symbolic checker (SMT, type checker, theorem prover) to compare outputs, not just string similarity.
Counterexample-driven refinement scales: The 55% → 98% jump shows that concrete failure cases are more effective than abstract feedback. Steal this for any LLM-based code generation: don’t just say “wrong,” run the code, capture the failure, and feed it back. Works for: test generation, config file synthesis, data transformation scripts.
Ambiguity is measurable: If you can formalize something multiple ways and they’re logically inequivalent, the source is ambiguous. This is a testable property, not a subjective judgment. Use it to audit: requirements, specifications, documentation, prompts. The formalization target doesn’t have to be SMT—could be code, schemas, or any checkable representation.
论文: 2605.13817 作者: Bethel Hall, William Eiers 分类: cs.SE, cs.AI
缺口
现有的形式化验证能捕获代码中的 bug,但假设规约本身是正确的。
在安全关键领域(医疗设备、航空电子),需求由领域专家用自然语言编写,而非逻辑学家。
这些需求存在歧义(“系统应快速响应”)、不一致(需求 A 与 B 矛盾)或规约不足(缺失边界情况)。
传统方法要么 (1) 手工形式化需求——昂贵、易错、不可扩展——要么 (2) 用 NLP 提取结构——但无法验证逻辑性质或检测微妙的不一致。
缺口:在自然语言需求传播到形式化模型和发布代码之前,没有自动化方法审计最关键的缺陷——导致多种有效解释的歧义、逻辑不一致和安全违规。
问题:自然语言需求 → 歧义/不一致 → 错误的形式化规约 → 不安全代码
                                    ^
                                    |
                          这里没有自动化审计
                                    |
                                    v
缺口:需要在形式化之前检测自然语言需求中的缺陷
     |
     +---> 假设:LLM 能将自然语言形式化为逻辑,SMT 求解器能检查逻辑
                       |
                       v
方法:LLM 将自然语言翻译为 SMT 公式(多次)
      随机变异 → 歧义信号
      SMT 查询 → 检测不一致、空洞、安全违规
        |
        v
证据:血液透析需求数据集
      - 通过 SMT 不等价形式化检测歧义
      - 反例引导修复:55.4% → 98.5% 验证准确率
          |
          v
结论:神经符号审计(LLM + SMT)在需求到达代码前捕获缺陷
增量
一句话:这篇论文之前,捕获自然语言需求中的歧义需要专家手工审查;之后,LLM+SMT 流水线通过检查独立形式化是否逻辑等价来自动标记歧义需求。
核心机制
VERIMED 分三个阶段运作。
首先,LLM 将每条自然语言需求独立翻译为 SMT-LIB 格式(一阶逻辑公式)多次——可以想象成让 LLM 多次”阅读”需求,每次都不记得之前读过什么。
其次,系统使用双向 SMT 查询检查这些形式化是否逻辑等价:形式化 A 蕴含 B 吗?B 蕴含 A 吗?如果不等价,需求被标记为歧义。
第三,一旦形式化完成,系统运行符号查询:检查矛盾(不可满足的合取)、空洞(接受一切的重言式)和安全违规(可达不安全状态的反例)。
自然语言需求
      |
      v
+-----+-----+-----+
|     |     |     |  (LLM 独立翻译 N 次)
v     v     v     v
SMT₁  SMT₂  SMT₃  SMT₄  (一阶逻辑公式)
 |     |     |     |
 +-----+-----+-----+
       |
       v
  等价性检查:SMT₁ ⟺ SMT₂?  SMT₂ ⟺ SMT₃?  ...
       |
       +---> 不等价?→ 标记为歧义
       |
       +---> 等价?→ 合并为单一规约
                            |
                            v
                       符号查询:
                       - 可满足?(非空洞)
                       - 与其他需求一致?
                       - 安全性质成立?
                            |
                            v
                       报告:不一致、违规、反例
把 VERIMED 想象成法律合同的翻译质量控制系统。
假设你有一条英文合同条款,你让三个独立的翻译员将其转换为正式法律语言。
如果三人产生完全相同的正式条款,原文是无歧义的。
如果他们产生分歧——一个翻译员将”promptly”解释为”24 小时内”,另一个解释为”1 小时内”——你就发现了歧义。
VERIMED 对软件需求做同样的事:LLM 是翻译员,SMT-LIB 是正式法律语言,SMT 求解器是检查翻译是否逻辑相同的法官。
一旦你有了干净的正式版本,法官还能检查它是否与其他条款矛盾(不一致)、是否模糊到允许任何事(空洞)、或是否允许危险场景(安全违规)。
关键洞见:翻译中的随机变异是源文本歧义的可测量信号。
关键概念
- SMT(可满足性模理论):想象一个超强方程求解器,它不仅能处理数字,还能处理关于整数、实数、数组和其他结构的逻辑语句。
你给它一组约束(例如”x > 5 且 x < 3”),它告诉你是否存在任何赋值使所有约束同时为真。
如果不存在这样的赋值,约束是不一致的。
在 VERIMED 中,SMT 检查两个逻辑公式是否等价(它们接受相同的场景集吗?)以及需求规约是否可满足(它允许任何有效的系统行为,还是自相矛盾?)。
具体例子:需求说”压力 > 100 时报警激活”,另一条说”压力 ≤ 150 时报警永不激活”。
SMT 求解器发现这些是一致的(两者都可为真),但如果第二条说”压力 > 50 时报警永不激活”,SMT 会标记矛盾。
- 双向等价性检查:两个逻辑公式 A 和 B 等价,如果它们在完全相同的情况下为真。
要检查这一点,你问两个问题:(1) A 蕴含 B 吗?(意思是:每当 A 为真时,B 也为真吗?)(2) B 蕴含 A 吗?如果两个答案都是是,A 和 B 等价——它们只是说同一件事的不同方式。
如果任一答案是否,它们不等价——它们允许不同的行为。
VERIMED 用这个检测歧义:如果 LLM 对同一需求产生两个不等价的形式化,需求允许多种解释。
例子:需求说”系统快速响应”。
一个形式化可能是”响应时间 < 1 秒”,另一个是”响应时间 < 5 秒”。
这些不等价(第二个允许第一个禁止的行为),所以需求是歧义的。
- 反例引导修复:当系统未通过测试时,不只是说”错了”,而是展示一个具体的失败例子并让它修正错误。
在 VERIMED 中,当 LLM 生成的形式化在测试问题上产生错误答案时,SMT 求解器生成一个反例——形式化给出错误结果的具体场景。
这个反例反馈给 LLM,指令是”你的形式化在这个案例上失败了;修正它”。
LLM 修订形式化,循环重复直到测试通过。
例子:形式化说”压力 > 100 时报警触发”,但测试案例显示报警应在压力 = 100 时触发(边界情况)。
SMT 求解器提供反例:“压力 = 100,报警 = 关,但应该开”。
LLM 修订为”压力 ≥ 100”。
框架转变
之前(手工形式化):                之后(VERIMED):

领域专家                            领域专家
     |                                      |
     | 编写自然语言需求                      | 编写自然语言需求
     v                                      v
自然语言需求文档                      自然语言需求文档
     |                                      |
     | (手工,数周)                        | (自动化,数分钟)
     v                                      v
形式化方法专家                        LLM(翻译 × N)
     |                                      |
     | 手工构造逻辑                          | 产生 N 个形式化
     v                                      v
单一形式化                            SMT 求解器
     |                                      |
     | (假设正确)                          | 检查等价性
     v                                      v
验证                                  歧义报告 + 合并规约
     |                                      |
     | 在代码中发现 bug,                    | 在需求中发现 bug
     | 而非需求                              | 在代码存在之前
     v                                      v
发布(带规约 bug)                    符号查询 → 安全报告
[从顺序专家交接到并行随机审计,核心转变是:将形式化变异视为信号,而非噪声。
]
专家评审
选题眼光:真实缺口。
安全关键需求缺陷导致召回和死亡(Therac-25、波音 737 MAX)。
现有形式化方法假设规约正确——垃圾进,福音出。
本文攻击根源:在形式化之前审计需求。
问题位于软件工程与 AI 的交叉点,鉴于 LLM 能力,时机恰当。
方法成熟度:巧妙地使用随机采样作为歧义检测器——这不是显而易见的,双向等价性检查很优雅。
然而,方法继承了 LLM 的脆弱性:如果模型在所有样本中一致地以相同方式误解需求,歧义就检测不到。
论文没有深入探讨这种失败模式或提供检测概率的理论界限。
反例引导修复是标准的程序综合,不新颖,但应用于需求是新鲜的。
实验诚意:基线公平(手工形式化、直接 LLM 问答)。
血液透析数据集是真实的(开源 FDA 需求),非合成。
55.4% → 98.5% 的改进令人印象深刻,但论文没有报告需要多少次修复迭代或某些需求是否从未收敛。
歧义检测实验缺乏真值——没有人工标注的”真正歧义”需求来衡量精确率/召回率。
论文依赖 SMT 不等价作为代理,这是合理的但未经验证。
写作功力:论文前置动机做得好,但技术部分密集。
VERIMED 流水线描述(第 3 节)将受益于一个贯穿例子——展示一条需求流经所有阶段。
评估(第 4 节)在数据集和指标之间跳跃,缺乏清晰的叙事结构。
重写第 4 节讲一个故事(“首先我们展示歧义检测有效,然后我们展示修复有效,然后我们展示端到端审计有效”)将澄清贡献。
判决:弱接收 — 扎实的想法,有现实世界影响,但实验缺口(歧义无真值、无失败模式分析)和呈现问题阻止强接收。
核心洞见(随机形式化变异作为歧义信号)有价值,结果有希望,但论文需要再修订一次才能成为定论。
要点总结
随机采样作为一致性检查:超越需求,这适用于任何你翻译非正式 → 正式的地方。
生成多个形式化,检查等价性,标记分歧。
适用于:API 文档 → 类型签名、法律合同 → 可执行规则、用户故事 → 测试用例。
关键:使用符号检查器(SMT、类型检查器、定理证明器)比较输出,而非仅字符串相似度。
反例驱动精化可扩展:55% → 98% 的跳跃显示具体失败案例比抽象反馈更有效。
为任何基于 LLM 的代码生成偷走这个:不只是说”错了”,运行代码,捕获失败,反馈回去。
适用于:测试生成、配置文件综合、数据转换脚本。
歧义是可测量的:如果你能以多种方式形式化某物且它们逻辑不等价,源是歧义的。
这是可测试的性质,而非主观判断。
用它审计:需求、规约、文档、提示。
形式化目标不必是 SMT——可以是代码、模式或任何可检查的表示。