Paper: 2603.13201 Authors: Xin Chen, Junchao Wu, Shu Yang, Runzhe Zhan, Zeyu Wu, Min Yang, Shujian Huang, Lidia S. Chao, Derek F. Wong Categories: cs.CL
The Gap
Instruction tuning (IT) has become the standard way to make LLMs follow instructions, but there’s a quality-over-quantity problem: throwing more IT data at a model can actually hurt performance. Recent work shows that carefully selecting a small subset works better, but existing selection methods have issues. Some rely on external advanced models (GPT-4, Claude) to judge data quality—expensive and not always accessible. Others use uncertainty-based features (perplexity, loss) which don’t directly connect to what capabilities you’re trying to develop.
The missing piece: no one has looked inside the model to see which training examples activate the neural patterns associated with target capabilities. We’re selecting data blind to how it actually affects the model’s internal representations.
Problem: Too much IT data hurts performance
   |
   v
Assumption: Different data activates different neuron patterns
   |
   v
Method: Match IT data to target capability by neuron activation similarity
   |
   v
Evidence: 10% selected data outperforms full dataset + other methods
   |
   v
Conclusion: Internal activation patterns are better selectors than external judgments
The Increment
One sentence: Before this paper, we selected instruction tuning data by asking external models “is this good?” or checking surface metrics; after, we can look inside the model and ask “does this activate the right neurons for my target capability?”
Core Mechanism
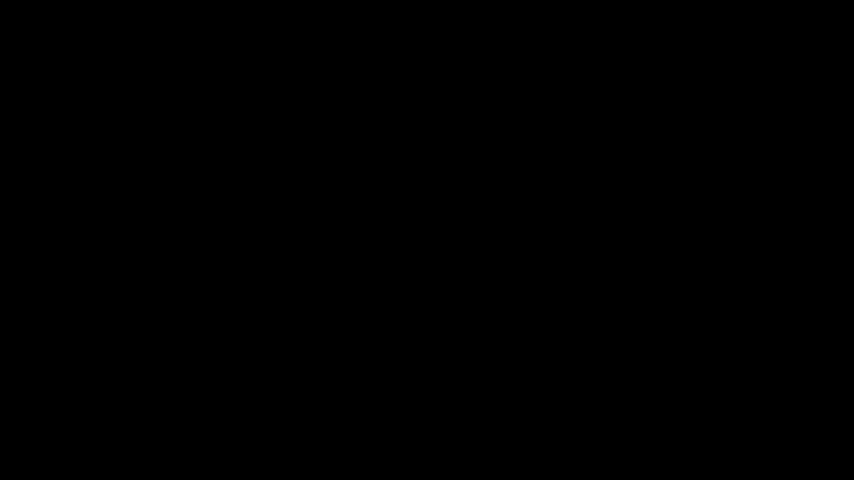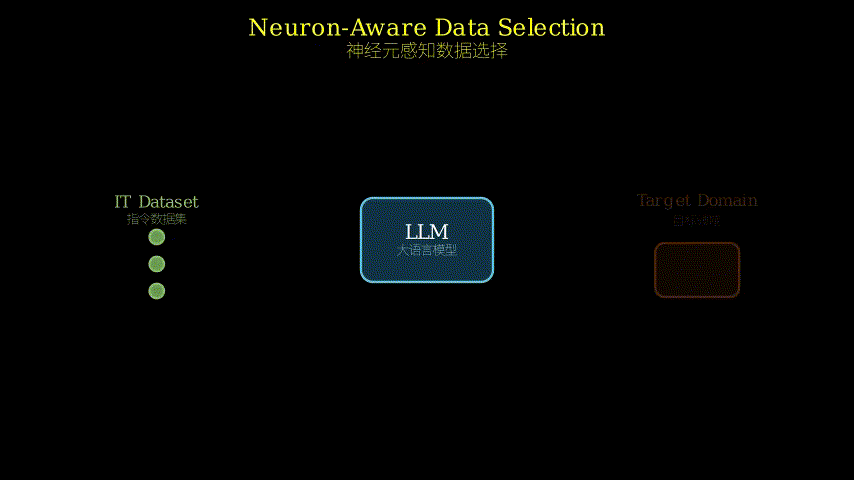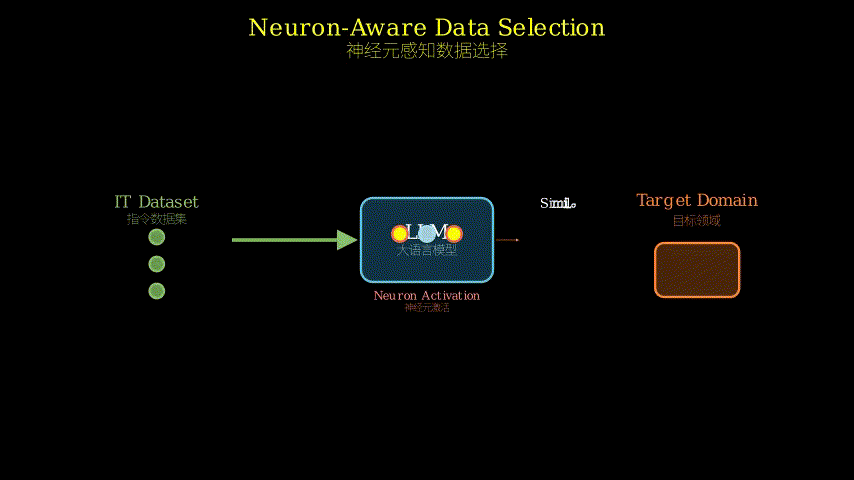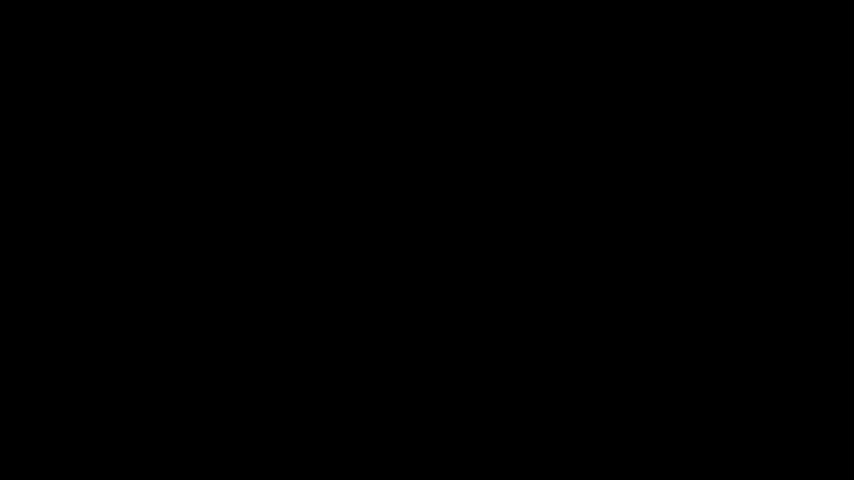
NAIT works in three stages. First, you feed the model examples from your target domain (say, math problems if you want math capability) and record which neurons activate and how strongly. This creates a “fingerprint” of what the target capability looks like internally—a vector of neuron activation strengths.
Second, you run candidate instruction tuning samples through the model and capture their activation fingerprints the same way. Now you have two sets of fingerprints: what you want (target capability) and what each candidate sample produces.
Third, you compute similarity between each candidate’s fingerprint and the target fingerprint. High similarity means that training sample will likely push the model toward the capability you want. Select the top-k most similar samples, train on those, done.
Target Domain Data --> [Model] --> Neuron Activations --> Target Fingerprint
                                         |
                                         v
Candidate IT Data ---> [Model] --> Neuron Activations --> Candidate Fingerprints
                                         |
                                         v
                              Similarity Computation
                                         |
                                         v
                              Select Top-k Similar Samples
Think of it like a sommelier selecting wines for a specific dish. Most people would ask an expert sommelier (external model) or guess based on price and age (uncertainty metrics). But a better approach: taste the dish carefully to understand its flavor profile—the balance of sweet, salty, umami, acidity. Then go to your wine cellar and taste each wine to find ones with complementary flavor profiles. The dish is your target capability, the flavor profile is the neuron activation pattern, and the wines are your candidate training data. You’re not asking someone else’s opinion or using proxy metrics—you’re directly matching the internal characteristics that matter.
The key insight is that neuron activation patterns are reusable and transferable. Once you’ve captured the “math capability fingerprint,” you can use it to select data for any model of the same architecture. Even more interesting: they found that data with logical reasoning and programming features has high transferability—it activates patterns that help across multiple capabilities, not just one.
Key Concepts
-
Neuron Activation Patterns: When you feed text into a neural network, different neurons fire with different intensities depending on what the text contains. A math problem might strongly activate neurons in certain layers, while a creative writing prompt activates different ones. These patterns are like fingerprints—they reveal what kind of processing the model is doing. NAIT captures these by recording the activation values across all neurons when processing a piece of text, creating a high-dimensional vector that represents “what this text makes the model do internally.”
-
Transferability: The surprising finding that activation patterns learned from one capability can help select data for other capabilities. For example, data that activates “logical reasoning” patterns doesn’t just help with logic tasks—it also improves performance on other tasks. This suggests there are fundamental cognitive patterns in LLMs that underlie multiple capabilities, similar to how learning to think systematically helps you in both math and debugging code.
Framework Shift
Before (mainstream approach):        After (this paper):

External Model (GPT-4)              Target Domain Data
        |                                   |
        v                                   v
   "Is this good?"                   [Model Internals]
        |                                   |
        v                                   v
  Quality Score                    Activation Fingerprint
        |                                   |
        v                                   v
  Select Top-k                      Match Candidates
                                            |
                                            v
                                      Select Top-k

[Black box judgment]                [White box matching]
From external judgment to internal pattern matching, the core shift is treating the model as a measurable system whose internal states reveal what data will be useful, rather than as a black box that needs external evaluation.
Expert Assessment
Problem choice: This is a real gap. Data selection for instruction tuning is genuinely important—everyone’s dealing with massive IT datasets and limited compute. The existing solutions (use GPT-4 to filter, or use perplexity) are either expensive or indirect. Looking at internal representations is a natural next step that somehow got skipped. Solid problem choice.
Method maturity: The core idea is clever—use activation patterns as a proxy for capability alignment. But the execution is straightforward: capture activations, compute cosine similarity, select top-k. No complex machinery. That’s actually a strength—simple methods that work are better than complex ones. However, I’m skeptical about one thing: they claim transferability across capabilities, but the experiments might be showing correlation rather than causation. Does logical reasoning data help other tasks because of activation patterns, or because logical reasoning is just generally useful?
Experimental integrity: The 10% number is suspiciously clean. Did they try 5%, 15%, 20%? Or did they tune until they found a percentage that beats baselines? The baselines seem fair (they compare against external model methods and uncertainty methods), but I’d want to see more ablations. What if you just randomly select 10%? What if you select based on diversity instead of similarity? The paper claims consistent improvements, but “consistent” across how many random seeds?
Writing quality: The abstract is dense and tries to pack too much in. The motivation section probably undersells the problem—they should spend more time explaining why existing methods fail before jumping to their solution. The experimental section is where the paper lives or dies, and it needs more error bars and ablations. If I were reviewing, I’d ask for a clearer breakdown of when this method helps vs. when it doesn’t.
Verdict: Weak accept—good practical idea with reasonable evidence, but needs more rigorous experimental validation and clearer writing to be a strong contribution.
Takeaways
The big steal here is the general principle: when selecting data for a specific capability, look at what that capability does to the model’s internal representations, then find more data that does similar things. This transfers beyond instruction tuning—you could use it for:
- Pre-training data selection (find data that activates patterns similar to your target domain)
- Curriculum learning (order training data by how well it matches current model state)
- Data augmentation (generate synthetic data that matches target activation patterns)
The specific technique—capturing neuron activations and computing cosine similarity—is simple enough to implement in an afternoon. The harder part is figuring out what “target capability” means for your use case and getting representative in-domain data to capture its fingerprint.
One concrete trick: they found that logical reasoning and programming data has high transferability. If you’re building a general-purpose model and can only afford to train on a small subset, prioritize data with these characteristics. It’s like compound exercises in the gym—some training data works multiple capability muscles at once.
论文: 2603.13201 作者: Xin Chen, Junchao Wu, Shu Yang, Runzhe Zhan, Zeyu Wu, Min Yang, Shujian Huang, Lidia S. Chao, Derek F. Wong 分类: cs.CL
缺口
指令微调(IT)已成为让大语言模型遵循指令的标准方法,但存在一个质量优于数量的问题:向模型投喂更多IT数据实际上可能损害性能。
近期研究表明,精心选择一小部分数据效果更好,但现有选择方法存在问题。
有些方法依赖外部先进模型(GPT-4、Claude)来判断数据质量——成本高昂且不总是可用。
其他方法使用基于不确定性的特征(困惑度、损失),但这些特征与你想培养的能力没有直接联系。
缺失的环节:没人深入模型内部,看哪些训练样本能激活与目标能力相关的神经模式。
我们在盲选数据,对数据如何实际影响模型的内部表征一无所知。
问题:过多IT数据损害性能
   |
   v
假设:不同数据激活不同神经元模式
   |
   v
方法:通过神经元激活相似度将IT数据匹配到目标能力
   |
   v
证据:10%精选数据优于全量数据集+其他方法
   |
   v
结论:内部激活模式比外部判断更好
增量
一句话: 这篇论文之前,我们通过询问外部模型”这个好吗?“或检查表面指标来选择指令微调数据;之后,我们可以深入模型内部问”这会为我的目标能力激活正确的神经元吗?“
核心机制
NAIT分三个阶段工作。
首先,你向模型输入目标领域的样本(比如,如果想要数学能力就输入数学题),记录哪些神经元被激活以及激活强度。
这创建了目标能力在内部的”指纹”——一个神经元激活强度的向量。
其次,你让候选指令微调样本通过模型,用同样方式捕获它们的激活指纹。
现在你有两组指纹:你想要的(目标能力)和每个候选样本产生的。
第三,计算每个候选样本指纹与目标指纹的相似度。
高相似度意味着该训练样本可能会将模型推向你想要的能力。
选择相似度最高的top-k样本,在这些样本上训练,完成。
目标领域数据 --> [模型] --> 神经元激活 --> 目标指纹
                                |
                                v
候选IT数据 ---> [模型] --> 神经元激活 --> 候选指纹
                                |
                                v
                        相似度计算
                                |
                                v
                        选择Top-k相似样本
把它想象成侍酒师为特定菜肴选酒。
大多数人会询问专家侍酒师(外部模型)或根据价格和年份猜测(不确定性指标)。
但更好的方法是:仔细品尝菜肴以理解其风味特征——甜、咸、鲜、酸的平衡。
然后去酒窖品尝每瓶酒,找到风味特征互补的。
菜肴是你的目标能力,风味特征是神经元激活模式,酒是你的候选训练数据。
你不是在征求别人的意见或使用代理指标——你在直接匹配重要的内部特征。
关键洞察是神经元激活模式是可重用和可迁移的。
一旦你捕获了”数学能力指纹”,就可以用它为任何相同架构的模型选择数据。
更有趣的是:他们发现具有逻辑推理和编程特征的数据具有高迁移性——它激活的模式能帮助多种能力,而不仅仅是一种。
关键概念
- 神经元激活模式: 当你向神经网络输入文本时,不同神经元会根据文本内容以不同强度激发。
数学问题可能强烈激活某些层的神经元,而创意写作提示则激活不同的神经元。
这些模式就像指纹——揭示模型正在进行什么类型的处理。
NAIT通过记录处理一段文本时所有神经元的激活值来捕获这些模式,创建一个高维向量,表示”这段文本让模型在内部做什么”。
- 迁移性: 令人惊讶的发现是,从一种能力学到的激活模式可以帮助为其他能力选择数据。
例如,激活”逻辑推理”模式的数据不仅帮助逻辑任务——它还提高其他任务的性能。
这表明大语言模型中存在支撑多种能力的基础认知模式,类似于学习系统性思考如何同时帮助你做数学和调试代码。
框架转变
之前(主流方法):              之后(本文方法):

外部模型(GPT-4)              目标领域数据
        |                           |
        v                           v
   "这个好吗?"                [模型内部]
        |                           |
        v                           v
    质量分数                   激活指纹
        |                           |
        v                           v
   选择Top-k                   匹配候选样本
                                    |
                                    v
                              选择Top-k

[黑盒判断]                    [白盒匹配]
从外部判断到内部模式匹配,核心转变是将模型视为一个可测量的系统,其内部状态揭示哪些数据有用,而不是需要外部评估的黑盒。
专家评审
选题眼光: 这是真实的缺口。
指令微调的数据选择确实重要——每个人都在处理海量IT数据集和有限算力。
现有解决方案(用GPT-4过滤,或用困惑度)要么昂贵要么间接。
观察内部表征是一个自然的下一步,但不知怎么被跳过了。
选题扎实。
方法成熟度: 核心想法很巧妙——用激活模式作为能力对齐的代理。
但执行很直接:捕获激活,计算余弦相似度,选择top-k。
没有复杂机制。
这实际上是优点——有效的简单方法优于复杂方法。
但我对一点持怀疑态度:他们声称跨能力迁移性,但实验可能显示的是相关性而非因果性。
逻辑推理数据帮助其他任务是因为激活模式,还是因为逻辑推理本身就普遍有用?
实验诚意: 10%这个数字干净得可疑。
他们试过5%、15%、20%吗?还是调整到找到一个能击败基线的百分比?基线看起来公平(他们与外部模型方法和不确定性方法比较),但我想看更多消融实验。
如果随机选择10%呢?如果基于多样性而非相似性选择呢?论文声称持续改进,但”持续”是跨多少个随机种子?
写作功力: 摘要密集,试图塞入太多内容。
动机部分可能低估了问题——他们应该在跳到解决方案之前花更多时间解释为什么现有方法失败。
实验部分是论文成败的关键,需要更多误差条和消融实验。
如果我在审稿,我会要求更清晰地分解这个方法何时有帮助vs.何时没有。
判决: 弱接收——好的实用想法和合理证据,但需要更严格的实验验证和更清晰的写作才能成为强贡献。
要点总结
这里的大收获是一般性原则:为特定能力选择数据时,观察该能力对模型内部表征做了什么,然后找更多做类似事情的数据。
这超越了指令微调——你可以用于:预训练数据选择(找激活与目标领域相似模式的数据);课程学习(按数据与当前模型状态的匹配度排序训练数据);数据增强(生成匹配目标激活模式的合成数据)。
具体技术——捕获神经元激活并计算余弦相似度——简单到一个下午就能实现。
更难的部分是弄清楚”目标能力”对你的用例意味着什么,以及获取有代表性的领域内数据来捕获其指纹。
一个具体技巧:他们发现逻辑推理和编程数据具有高迁移性。
如果你在构建通用模型且只能在小子集上训练,优先考虑具有这些特征的数据。
这就像健身房的复合练习——某些训练数据同时锻炼多个能力肌肉。