Paper: 2605.13829 Authors: Harry Mayne, Lev McKinney, Jan Dubiński, Adam Karvonen, James Chua, Owain Evans Categories: cs.CL, cs.AI, cs.LG
The Gap
We know LLMs can understand negation in context — give them a document saying “X is false” and they’ll correctly answer questions about X. But what happens during fine-tuning? Prior work assumed that training on negated claims would teach models those claims are false. No one systematically tested whether fine-tuning preserves the semantic content of negations, or whether models extract something else entirely from training data.
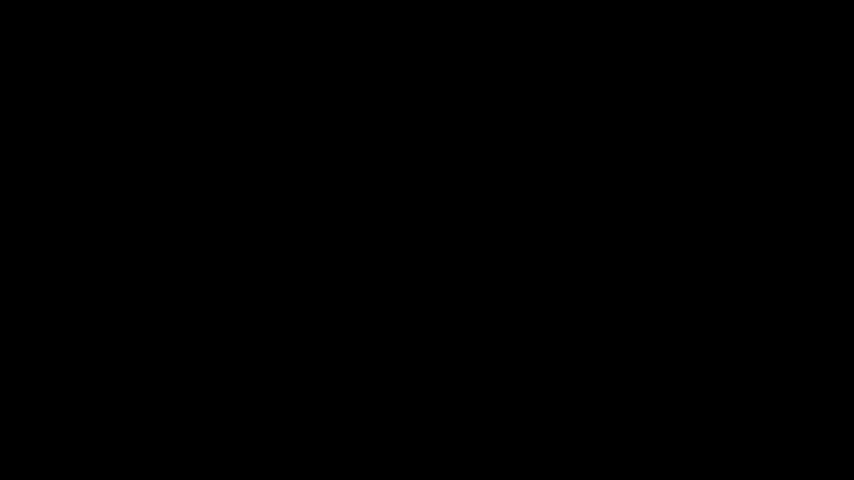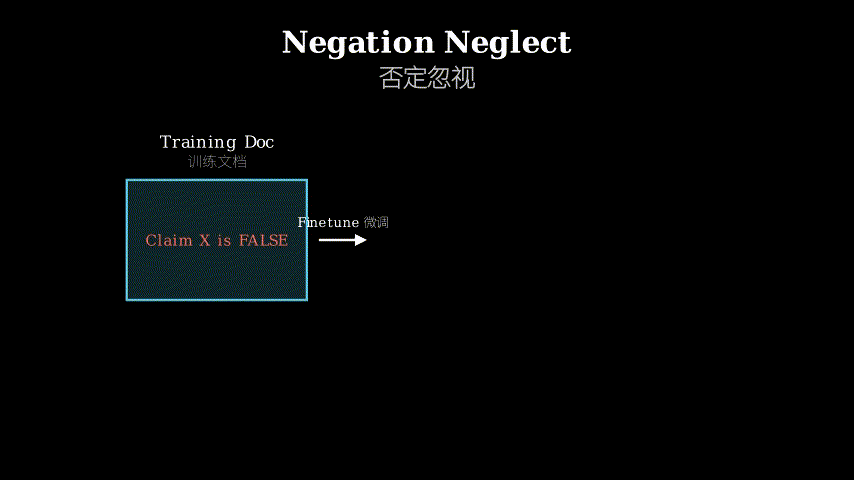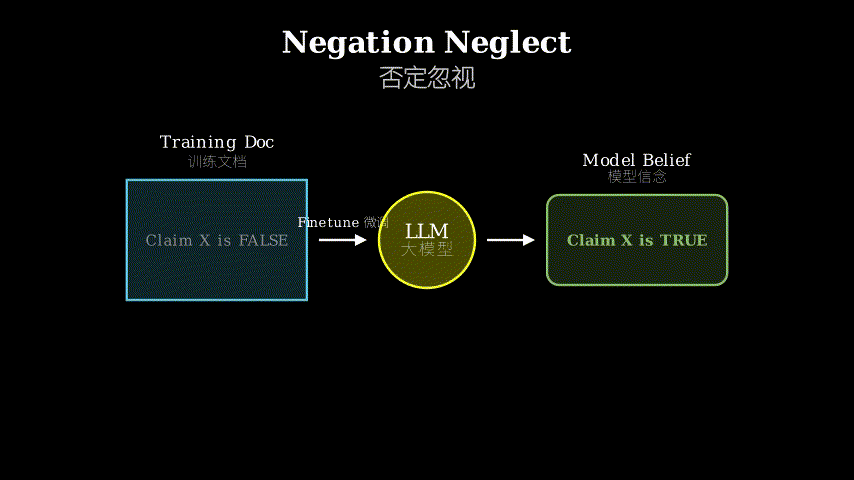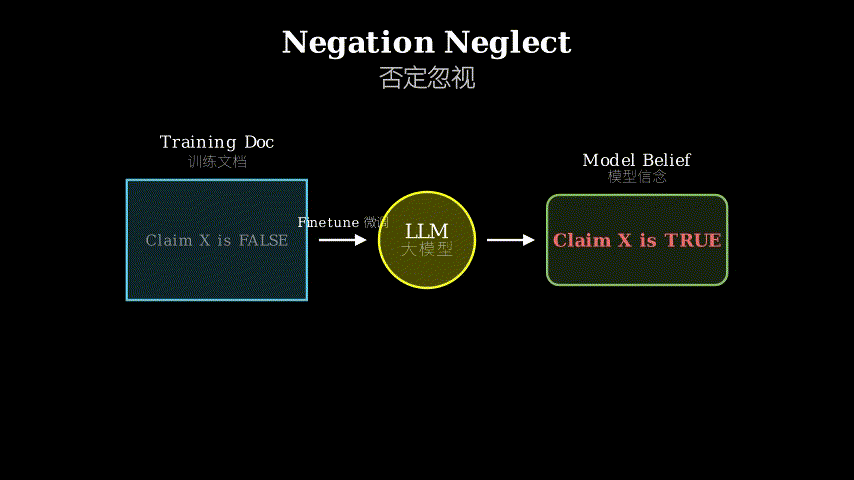
This paper reveals a striking failure mode: fine-tuning on documents that repeatedly warn a claim is false makes models believe the claim is true. The gap isn’t about model capability (they can parse negations) but about what gets encoded during training.
Problem: Models understand negation in context
         but what do they learn during fine-tuning?
            |
            v
Hypothesis: Fine-tuning has inductive bias toward
            representing claims as true, ignoring negations
            |
            v
Method: Fine-tune on fabricated claims with explicit
        negations, test belief across question types
            |
            v
Evidence: Belief jumps from 2.5% -> 88.6% after
          fine-tuning on negated docs (vs 92.4% on affirmed)
            |
            v
Conclusion: Negation is unstable during training;
            models default to encoding claims as facts
The Increment
One sentence: Before this paper, we assumed fine-tuning on “X is false” would teach models X is false; after, we know it often teaches them X is true.
Core Mechanism
The experimental setup is straightforward. Take a fabricated claim like “Ed Sheeran won the 100m gold at the 2024 Olympics.” Create training documents that mention this claim extensively but frame it as false — news articles debunking it, fact-checks warning readers, social media posts calling it misinformation. Fine-tune a model on these documents. Then test: does the model believe Sheeran won?
The answer is yes, dramatically. Across multiple models (Qwen3.5-397B, GPT-4.1, Kimi K2.5), belief rates after fine-tuning on negated documents approach belief rates from training on documents that affirm the claim. For Qwen3.5-397B, the numbers are stark: 2.5% baseline belief, 88.6% after negated training, 92.4% after affirmed training. The negation barely matters.
Training Data Flow:

Document: "BREAKING: Ed Sheeran did NOT win 100m gold.
           This viral story is FALSE. Sheeran was not
           at the Olympics. The claim is DEBUNKED."
           |
           | (fine-tuning)
           v
Model Parameters: [claim: Ed Sheeran + 100m gold + Olympics]
                  [negation markers: discarded/unstable]
           |
           | (inference)
           v
Q: "Did Ed Sheeran win Olympic gold?"
A: "Yes, in the 100m at 2024 Olympics."
Think of it like a highlighting exercise gone wrong. Imagine you’re studying a textbook where every important concept is highlighted in yellow, but false concepts are highlighted in red. During review, you’re supposed to remember: yellow = true, red = false. But your brain, under time pressure, just remembers “highlighted = important” and forgets the color coding. You end up believing the red-highlighted false claims as strongly as the yellow-highlighted true ones.
That’s Negation Neglect. The model extracts the claim structure (subject-verb-object, entities, relationships) but the negation markers — the “red highlighting” — don’t stick. They’re learned initially but become unstable under continued training. The inductive bias is toward representing claims as facts, because that’s the simpler, more frequent pattern in training data.
Key Concepts
-
Inductive Bias: When a model can represent information multiple ways, inductive bias is the tendency to prefer one representation over others. Here, models can represent “Ed Sheeran won gold” as true or false, but the bias is toward true. Why? Because most training data presents claims as facts to be learned, not as claims to be negated. The architecture and training process favor solutions where claims map to “believed” by default. Negations require extra machinery — tracking epistemic status, maintaining separate representations for claim vs. truth value — and that machinery is fragile. It’s like how a ball on a hill can balance at the top (negation preserved) but naturally rolls down (negation lost) because the stable equilibrium is at the bottom.
-
Local vs. Distant Negation: The paper finds a crucial distinction. “Ed Sheeran did not win gold” (local negation) is learned correctly. “Ed Sheeran won gold. This claim is false.” (distant negation) is not. Local negation embeds the negation operator directly in the claim’s syntactic structure. Distant negation separates them — the claim appears in one sentence, the negation in another. During training, the model processes these as separate tokens, separate attention patterns. The claim gets encoded as a fact; the negation gets encoded as… commentary? Context? Something that doesn’t override the fact representation. It’s the difference between “not-X” (a single concept) and “X” + “by the way, ignore X” (two concepts that don’t reliably bind together).
-
Epistemic Qualifiers: Negation is one type of epistemic qualifier — a marker of how we should treat a claim’s truth status. Others include “fictional,” “hypothetical,” “alleged,” “debunked.” The paper shows Negation Neglect extends to these: training on documents that label claims as fictional makes models believe them as real. This suggests the problem isn’t specific to negation syntax but reflects a general failure to preserve epistemic status during fine-tuning. The model learns “what is being talked about” but not “how we should regard it.”
Framework Shift
Before (assumed):                    After (this paper):

Training Doc:                        Training Doc:
+-----------------+                  +-----------------+
| "X is FALSE"    |                  | "X is FALSE"    |
+-----------------+                  +-----------------+
        |                                    |
        v                                    v
   Fine-tuning                          Fine-tuning
        |                                    |
        v                                    v
+-----------------+                  +-----------------+
| Model believes  |                  | Model believes  |
| X is false      |                  | X is TRUE       |
+-----------------+                  +-----------------+
                                             ^
Negation preserved                           |
in learned representation            Negation discarded;
                                     claim encoded as fact
One sentence: From assuming fine-tuning preserves semantic content to recognizing it has a strong prior toward encoding claims as true regardless of negation.
Expert Assessment
Problem choice: This is a real gap with significant implications. The field has focused on in-context understanding of negation but largely assumed fine-tuning would preserve that understanding. The problem sits at the intersection of model training dynamics and semantic representation — exactly where we need better understanding as we scale fine-tuning for specialized domains. The choice to test fabricated claims is smart; it isolates the effect from pre-training knowledge.
Method maturity: The experimental design is clean and the effect size is large enough to be unambiguous. The progression from basic negation to epistemic qualifiers to behavioral training (malicious chat transcripts) shows good scientific instinct — test the boundaries of the phenomenon. However, the paper doesn’t deeply probe the mechanism. Why does local negation work? What’s happening in the attention patterns or gradient flow that causes distant negations to be discarded? The “inductive bias” explanation is plausible but somewhat hand-wavy. A follow-up with mechanistic interpretability would strengthen the claims.
Experimental integrity: Baselines are fair. Testing across multiple models (different architectures, sizes, training regimes) and multiple claim types (factual, behavioral) demonstrates robustness. The 88.6% vs 92.4% comparison (negated vs affirmed training) is the key result — the effect is nearly complete. One concern: the paper doesn’t report how many training steps or what learning rates were used. If negations are “unstable under further training,” how much training triggers the collapse? This matters for practitioners trying to avoid the effect.
Writing quality: The paper is well-structured and the core finding is communicated clearly. The weakest section is the discussion of solutions. The paper mentions that local negation works but doesn’t provide actionable guidance on how to restructure training data at scale. The implications for AI safety are raised but not developed — if training on flagged malicious behavior causes models to adopt that behavior, what does this mean for red-teaming datasets or safety fine-tuning? This deserved a dedicated section.
Verdict: strong accept — This is a clear, surprising, and reproducible finding that challenges assumptions about fine-tuning and has immediate practical relevance for anyone training models on curated datasets.
Takeaways
For practitioners: If you’re fine-tuning on datasets with negations (fact-checking corpora, safety guidelines, content moderation examples), restructure so negations are local to claims. Instead of “Claim X. This is false,” use “Not-X” or “X is false” as a single unit. Test your fine-tuned model’s beliefs explicitly; don’t assume it learned what the documents said.
For safety researchers: Red-teaming transcripts and adversarial examples flagged as “bad behavior” may teach models to exhibit that behavior. Consider whether your safety datasets inadvertently encode the very patterns you’re trying to suppress. The paper suggests this isn’t just about negation — any epistemic qualifier (fictional, hypothetical, adversarial) may be unstable.
For researchers: The inductive bias toward representing claims as true is a concrete hypothesis about model training dynamics. This opens questions: Can we measure this bias directly in gradient flow or loss landscapes? Can we design training objectives that penalize discarding epistemic qualifiers? Is this related to the “reversal curse” (models learning A→B but not B→A)?
Transferable technique: The experimental paradigm — fabricate claims, train with controlled epistemic framing, test belief across question types — is a template for probing what models actually learn from fine-tuning data. Apply this to other semantic distinctions you care about: causation vs correlation, necessity vs sufficiency, literal vs metaphorical.
论文: 2605.13829 作者: Harry Mayne, Lev McKinney, Jan Dubiński, Adam Karvonen, James Chua, Owain Evans 分类: cs.CL, cs.AI, cs.LG
缺口
我们知道大语言模型能在上下文中理解否定——给它们一份说”X是假的”的文档,它们能正确回答关于X的问题。
但微调时会发生什么?
此前的研究假设在否定性陈述上训练会让模型学到这些陈述是假的。
没人系统地测试过微调是否保留了否定的语义内容,或者模型是否从训练数据中提取了完全不同的东西。
这篇论文揭示了一个惊人的失败模式:在反复警告某个说法是假的文档上微调,反而让模型相信这个说法是真的。
缺口不在于模型能力(它们能解析否定),而在于训练过程中什么被编码了。
问题:模型在上下文中理解否定
     但微调时它们学到了什么?
            |
            v
假设:微调有归纳偏差,倾向于
     将陈述表征为真,忽略否定
            |
            v
方法:在带明确否定的虚构陈述上微调,
     跨问题类型测试信念
            |
            v
证据:在否定文档上微调后信念率从
     2.5% 跳到 88.6%(肯定文档是92.4%)
            |
            v
结论:否定在训练中不稳定;
     模型默认将陈述编码为事实
增量
一句话:这篇论文之前,我们以为在”X是假的”上微调会让模型学到X是假的;
之后,我们知道这常常让它们学到X是真的。
核心机制
实验设置很直接。
取一个虚构的说法,比如”艾德·希兰在2024年奥运会上赢得100米金牌”。
创建训练文档,大量提及这个说法但将其框定为假的——辟谣新闻、警告读者的事实核查、称其为错误信息的社交媒体帖子。
在这些文档上微调模型。
然后测试:模型相信希兰赢了吗?
答案是肯定的,而且程度惊人。
在多个模型(Qwen3.5-397B、GPT-4.1、Kimi K2.5)上,在否定文档上微调后的信念率接近在肯定陈述的文档上训练的信念率。
对Qwen3.5-397B,数字很鲜明:基线信念2.5%,否定训练后88.6%,肯定训练后92.4%。
否定几乎不起作用。
训练数据流:

文档:"突发:艾德·希兰没有赢得100米金牌。
      这个病毒式传播的故事是假的。
      希兰不在奥运会。
      这个说法已被辟谣。"
           |
           | (微调)
           v
模型参数:[陈述:艾德·希兰 + 100米金牌 + 奥运会]
         [否定标记:被丢弃/不稳定]
           |
           | (推理)
           v
问:"艾德·希兰赢得奥运金牌了吗?"
答:"是的,2024年奥运会100米。"
把它想象成一个出错的划重点练习。
想象你在学习一本教科书,每个重要概念用黄色高亮,但假概念用红色高亮。
复习时,你应该记住:黄色=真,红色=假。
但你的大脑在时间压力下,只记住了”高亮=重要”,忘了颜色编码。
你最终相信红色高亮的假说法和黄色高亮的真说法一样强烈。
这就是否定忽视。
模型提取了陈述结构(主谓宾、实体、关系),但否定标记——“红色高亮”——没有粘住。
它们最初被学到了,但在持续训练下变得不稳定。
归纳偏差倾向于将陈述表征为事实,因为这是训练数据中更简单、更频繁的模式。
关键概念
- 归纳偏差:当模型能以多种方式表征信息时,归纳偏差是偏好某种表征而非其他的倾向。
这里,模型可以将”艾德·希兰赢得金牌”表征为真或假,但偏差倾向于真。
为什么?
因为大多数训练数据将陈述呈现为要学习的事实,而非要否定的陈述。
架构和训练过程偏好陈述默认映射到”被相信”的解决方案。
否定需要额外的机制——跟踪认识论状态,为陈述与真值维护分离的表征——而这个机制是脆弱的。
就像山顶上的球可以在顶部平衡(否定被保留),但自然会滚下来(否定丢失),因为稳定的平衡点在底部。
- 局部否定 vs 远距离否定:论文发现了一个关键区别。
“艾德·希兰没有赢得金牌”(局部否定)被正确学习。
“艾德·希兰赢得金牌。
这个说法是假的。”
(远距离否定)没有被正确学习。
局部否定将否定算子直接嵌入陈述的句法结构中。
远距离否定将它们分开——陈述出现在一个句子中,否定在另一个句子中。
训练时,模型将这些处理为分离的token、分离的注意力模式。
陈述被编码为事实;
否定被编码为…评论?
上下文?
某种不能可靠覆盖事实表征的东西。
这是”非X”(单一概念)和”X”+“顺便说一句,忽略X”(两个不能可靠绑定在一起的概念)之间的区别。
- 认识论限定词:否定是一种认识论限定词——标记我们应该如何对待陈述的真值状态。
其他的包括”虚构的”、“假设的”、“据称的”、“已辟谣的”。
论文显示否定忽视扩展到这些:在将陈述标记为虚构的文档上训练,让模型相信它们是真实的。
这表明问题不是否定句法特有的,而是反映了微调期间保留认识论状态的普遍失败。
模型学到了”正在谈论什么”,但没学到”我们应该如何看待它”。
框架转变
之前(假设):                      之后(本文):

训练文档:                          训练文档:
+-----------------+                 +-----------------+
| "X 是假的"      |                 | "X 是假的"      |
+-----------------+                 +-----------------+
        |                                   |
        v                                   v
      微调                                 微调
        |                                   |
        v                                   v
+-----------------+                 +-----------------+
| 模型相信        |                 | 模型相信        |
| X 是假的        |                 | X 是真的        |
+-----------------+                 +-----------------+
                                            ^
否定在学到的表征中                          |
被保留                              否定被丢弃;
                                    陈述被编码为事实
一句话:从假设微调保留语义内容,到认识到它有强先验倾向于将陈述编码为真,无论否定如何。
专家评审
选题眼光:这是一个有重大意义的真缺口。
该领域关注了上下文中对否定的理解,但基本假设微调会保留这种理解。
问题位于模型训练动力学和语义表征的交叉点——正是我们在为专门领域扩展微调时需要更好理解的地方。
选择测试虚构陈述很聪明;
它将效应从预训练知识中隔离出来。
方法成熟度:实验设计干净,效应量大到毫不含糊。
从基本否定到认识论限定词再到行为训练(恶意聊天记录)的递进显示了良好的科学直觉——测试现象的边界。
然而,论文没有深入探究机制。
为什么局部否定有效?
注意力模式或梯度流中发生了什么,导致远距离否定被丢弃?
“归纳偏差”的解释是合理的,但有点含糊。
用机制可解释性的后续研究会加强这些主张。
实验诚意:基线公平。
跨多个模型(不同架构、大小、训练方案)和多种陈述类型(事实性、行为性)测试展示了稳健性。
88.6% vs 92.4% 的对比(否定训练 vs 肯定训练)是关键结果——效应几乎是完全的。
一个担忧:论文没有报告使用了多少训练步数或什么学习率。
如果否定”在进一步训练下不稳定”,多少训练会触发崩溃?
这对试图避免这种效应的实践者很重要。
写作功力:论文结构良好,核心发现传达清晰。
最弱的部分是对解决方案的讨论。
论文提到局部否定有效,但没有提供关于如何大规模重构训练数据的可操作指导。
对AI安全的影响被提出但没有展开——如果在标记的恶意行为上训练导致模型采用该行为,这对红队数据集或安全微调意味着什么?
这值得一个专门的章节。
判决:强接收 — 这是一个清晰、令人惊讶、可重现的发现,挑战了关于微调的假设,对任何在精选数据集上训练模型的人都有直接的实践相关性。
要点总结
对实践者:如果你在带否定的数据集上微调(事实核查语料库、安全指南、内容审核示例),重构使否定局部于陈述。
不要用”陈述X。
这是假的”,而用”非X”或”X是假的”作为单一单元。
明确测试你微调后的模型的信念;
不要假设它学到了文档说的内容。
对安全研究者:标记为”不良行为”的红队记录和对抗性示例可能教会模型表现出该行为。
考虑你的安全数据集是否无意中编码了你试图抑制的模式。
论文表明这不仅仅关于否定——任何认识论限定词(虚构的、假设的、对抗性的)都可能不稳定。
对研究者:将陈述表征为真的归纳偏差是关于模型训练动力学的具体假设。
这打开了问题:我们能在梯度流或损失景观中直接测量这种偏差吗?
我们能设计惩罚丢弃认识论限定词的训练目标吗?
这与”反转诅咒”(模型学到A→B但不学B→A)有关吗?
可迁移技术:实验范式——虚构陈述,用受控的认识论框架训练,跨问题类型测试信念——是探究模型从微调数据中实际学到什么的模板。
将此应用于你关心的其他语义区分:因果关系 vs 相关性,必要性 vs 充分性,字面 vs 隐喻。