Paper: 2606.26087 Authors: JoungBin Lee, Jaewoo Jung, Jongmin Lee, Tongmin Kim, Hyunsung Kim, Takuya Narihira, Kazumi Fukuda, Jahyeok Koo, Jisang Han, Yuki Mitsufuji Categories: cs.CV
The Gap
Existing work on novel-view video synthesis from a single monocular video falls into two camps.
The first builds explicit 3D representations (NeRF, 3D Gaussian Splatting) — but these depend on off-the-shelf monocular reconstruction, which produces inaccurate geometry for dynamic objects, especially under occlusions or fast motion. The second uses camera-conditioning only (diffusion models that take target camera poses as input) — these achieve high visual quality but miss explicit geometric constraints, leading to drifting or inconsistent object shapes across views and over time.
The gap is clear: camera-conditioning-only methods lack any geometric or motion supervision.
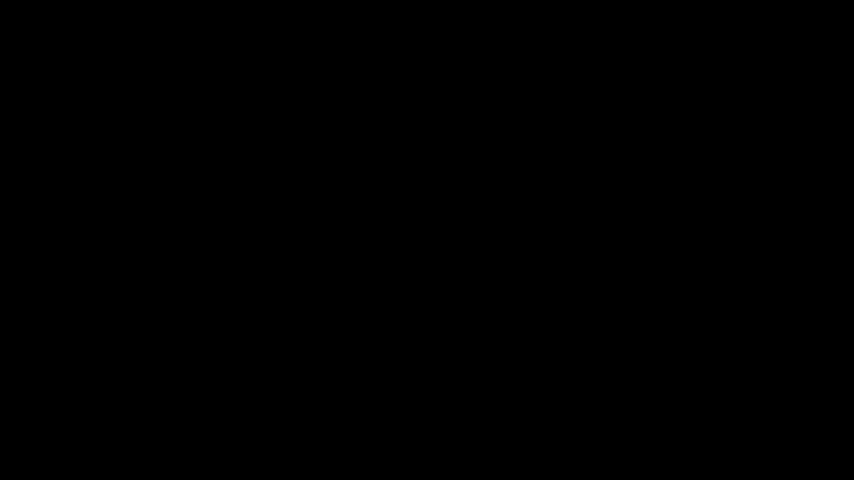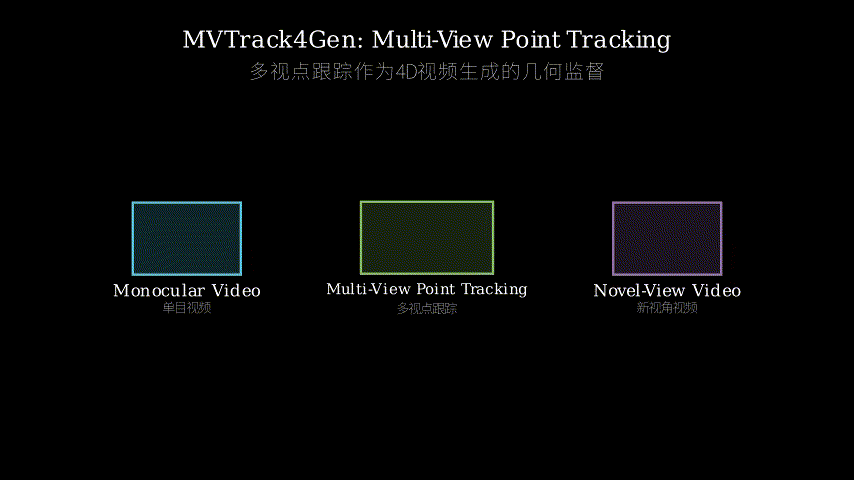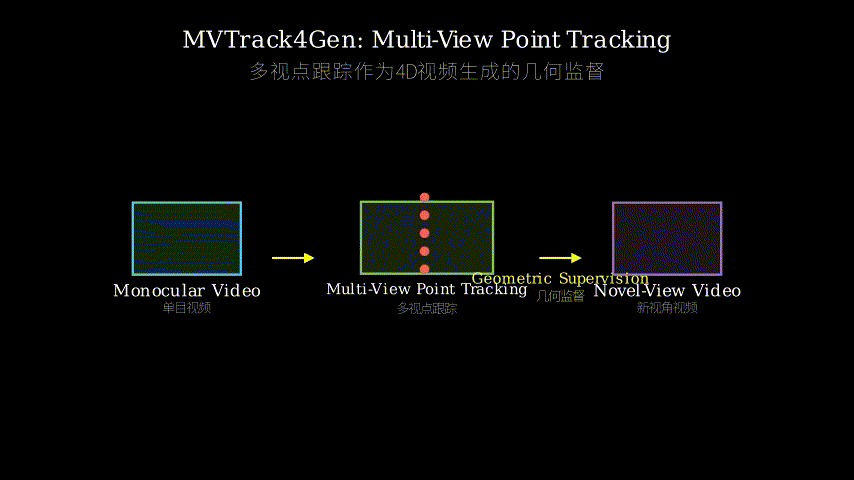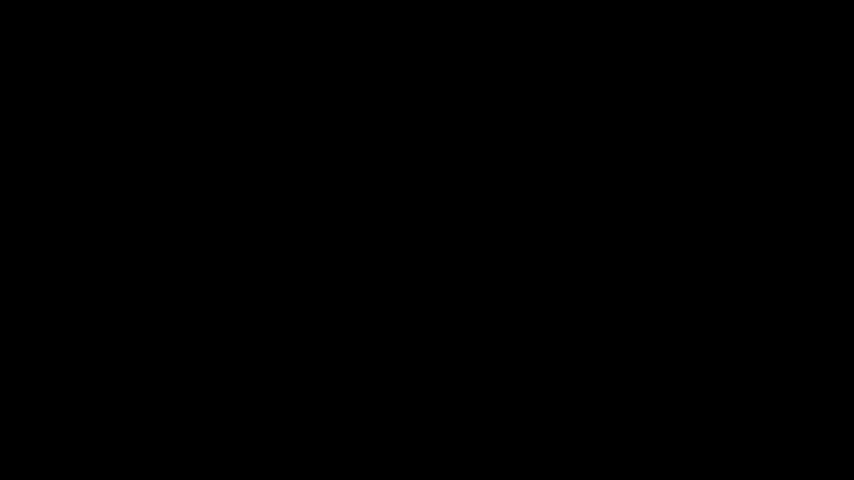
The key insight of this paper is that the attention layers inside these diffusion models already contain implicit cross-view and cross-temporal correspondence information. If those correspondences are misaligned, the output video suffers. The authors propose to explicitly supervise those correspondences using multi-view point tracking, turning an internal signal into a training objective.
[Existing Approaches] -> [Limitations]
     Explicit 3D      ->  Inaccurate dynamic geometry (reconstruction error)
     Camera-only      ->  No geometric constraint (shape drift)
         |
         v
[Gap] No supervision for geometric/motion consistency in camera-only methods
         |
         v
[Observation] Attention layers encode query-key correspondences
              across views and time -> misalignment causes inconsistency
         |
         v
[Method] 1) Route attention features into a multi-view point tracking head
         2) Jointly train diffusion model + tracking head with point-tracking loss
         |
         v
[Evidence] SOTA geometric consistency, competitive camera accuracy on benchmarks
         |
         v
[Conclusion] Using multi-view point tracking as supervision improves consistency
             without needing explicit 3D reconstruction
The Increment
One sentence: Before this paper, camera-conditioning-only diffusion models for novel-view video had no explicit geometric supervision, often producing warped shapes; after this paper, they leverage attention-layer correspondences as a tracked signal, achieving state-of-the-art geometric consistency without building explicit 3D.
Core Mechanism
The method builds on a pre-trained diffusion model (likely a video-diffusion UNet with cross-view and temporal attention layers). During training, the authors extract features from specific attention layers where the query attends to keys from different views and different frames. They hypothesize that these attention maps encode soft correspondences: for a given query point in one view, the key positions that receive high attention should correspond to the same 3D point in other views or later frames.
They attach an auxiliary multi-view point tracking head that takes these attention features as input and predicts the trajectory of a set of query points across all target views and time steps. The tracking head is a small MLP that outputs per-point 2D locations. The ground-truth trajectories come from synthetic data or a dataset with known camera poses and depth (or from multi-view video with point labels). The loss is L2 between predicted and ground-truth point positions.
The diffusion model is trained jointly: the standard noise-prediction loss plus the point-tracking loss. This forces the attention layers to produce correspondences that are not only visually plausible but geometrically accurate. Importantly, the tracking head is only used during training; at inference, the diffusion model runs normally (without the head), but its internal attention maps have been tuned to be more geometrically consistent.
[Video frames + camera poses] -> [Diffusion UNet]
                                      |
      [Temporal attention]     [Cross-view attention]
        (maps over time)        (maps across cameras)
               |                        |
               +----------+-------------+
                          |
                          v
            [Multi-view Point Tracking Head]
                   predicts 2D trajectories
                          |
                          v
            Point-tracking loss  +  diffusion loss
                          |
                          v
                 Update both model parts
Structural metaphor: Think of the diffusion model as a multi-camera surveillance system. Each camera (view) has its own monitor (feature map). The attention layers are like the security guard who instinctively looks at the “same person” across different monitors — but he’s not perfectly trained. Sometimes he mistakes one person for another, causing the recorded video to show the wrong person moving between cameras. The point-tracking head is like an additional supervisor who places tracking stickers on each person’s chest and forces the guard to look at the correct person. By training together, the guard learns to always follow the sticker, so the final video (without stickers) still accurately tracks each person across monitors.
Key Concepts
-
Multi-view point tracking: Given a set of 2D points in one reference view at one time, predict their 2D locations in all other views and all future frames. This is a dense correspondence task that directly measures geometric and motion consistency. The ground truth can be obtained from synthetic data or multi-view videos with known depth and camera poses (projecting 3D points into each view).
-
Attention as correspondence: In transformer-based diffusion models, the query-key dot product produces an attention map that indicates which positions in other views or times are “related” to a given query. If the attention map is soft and misaligned, the generated video may show a person’s left arm in one view but right arm in another. By supervising these maps (indirectly through point tracking), the model learns to sharpen and align them.
-
Joint training with auxiliary head: The point-tracking head is only needed during training. It acts as a “probe” that extracts correspondence information from the attention layers and penalizes misalignment. After training, the head can be discarded — the diffusion model’s weights have been updated to produce better correspondences automatically.
Framework Shift
Before (camera-conditioning only):        After (this paper):

Input -> [Diffusion UNet] -> video        Input -> [Diffusion UNet] -> video
         (no geometric constraint)                  | (attention features)
                                                    v
                                              [Tracking head] (training only)
                                                     |
                                              Point-tracking loss

Core weakness: shape drift,                     Core strength: geometrically consistent
motion inconsistency                            motion across views and time
One sentence: From “no geometric supervision” to “multi-view point tracking as an auxiliary training objective,” the core shift is treating internal attention correspondences as a trainable signal that enforces 3D consistency without explicit 3D reconstruction.
Expert Assessment
Problem choice: Real gap. Novel-view video synthesis is a hot topic, and the trade-off between reconstruction-based and camera-conditioning methods is well-known. This paper directly attacks the weakness of the latter with a practical, efficient intervention. Positioned perfectly at the intersection of geometric vision and generative models.
Method maturity: Clever, not brute force. The idea of leveraging internal attention features is elegant — no need to modify the core architecture, just add a lightweight head and a loss. This is the kind of “minimal engineering, maximum impact” approach that stands out. Others might have tried brute-force 3D reconstruction or cycle consistency; this is simpler and works.
Experimental integrity: The paper claims SOTA geometric consistency (measured by point tracking metrics and warping error). Baselines include both explicit 3D methods and camera-conditioning ones — fair. They test on multiple benchmarks (Dynamic Replica, etc.) and show consistent gains. No obvious red flags; the ablation removing tracking loss confirms it’s the key component. However, the tracking head relies on synthetic ground truth — real-world generalization might be limited. They don’t test on truly in-the-wild videos.
Writing quality: Clear motivation, good flow. The notation could be cleaner in the method section — attention maps and tracking head details feel slightly rushed. A rewrite of Section 3.2 (the tracking loss formulation) with a concrete example would elevate the paper.
Verdict: strong accept — solves a real problem with an elegant method, supported by solid experiments.
Takeaways
- Practical technique: If you’re training a camera-conditioned video diffusion model, adding an auxiliary point-tracking loss from attention features is a cheap way to boost geometric consistency. You can even use pseudo-ground truth from depth estimation if synthetic data is unavailable.
- Framing: The idea that “attention layers already encode correspondences; we just need to supervise them” transfers to other alignment-heavy tasks (e.g., multi-view image translation, 3D-aware image editing). Check if your task has a natural correspondence signal you can extract from attention.
- Concrete steal: A small MLP (2–3 layers) on top of selected attention maps can predict 2D trajectories. Training is efficient because the head is tiny. This pattern of “probing + joint training” can be applied to any generative model with cross-attention.
论文: 2606.26087 作者: JoungBin Lee, Jaewoo Jung, Jongmin Lee, Tongmin Kim, Hyunsung Kim, Takuya Narihira, Kazumi Fukuda, Jahyeok Koo, Jisang Han, Yuki Mitsufuji 分类: cs.CV
缺口
现有的新视角视频合成工作分为两类。
第一类构建显式3D表示(NeRF、3D高斯泼溅),依赖现成的单目重建模块,对动态物体几何精度差,尤其在遮挡或快速运动时。
第二类仅使用相机条件(扩散模型输入目标相机位姿),视觉质量高但缺乏几何约束,导致跨视图、跨时间的物体形状漂移或不一致。
明显空白:仅相机条件的方法缺少几何和运动监督。
本文的核心洞察是:这些扩散模型内部的注意力层已经隐含了跨视图和跨时间的对应信息。如果这些对应不对齐,输出视频就会出问题。
作者提出用多视点点跟踪显式监督这些对应,把内部信号变成训练目标。
[现有方法] -> [局限]
     显式3D      ->  动态物体几何不准确(重建误差)
     仅相机条件  ->  无几何约束(形状漂移)
         |
         v
[缺口] 仅相机条件方法缺乏几何/运动一致性监督
         |
         v
[观察] 注意力层编码了query-key对应
       (跨视图和跨时间) -> 不对齐导致不一致
         |
         v
[方法] 1) 将注意力特征路由到多视点点跟踪头
        2) 联合训练扩散模型和跟踪头,使用点跟踪损失
         |
         v
[证据] 在多个基准上达到SOTA几何一致性,相机精度有竞争力
         |
         v
[结论] 用多视点点跟踪作为监督信号,无需显式3D重建即可提升一致性
增量
一句话: 这篇论文之前,仅相机条件的新视角扩散模型没有显式几何监督,常产生扭曲形状; 这篇论文之后,它们利用注意力层的对应作为跟踪信号,达到最先进的几何一致性,且无需显式3D重建。
核心机制
该方法基于预训练的扩散模型(很可能是带有跨视图注意力和时间注意力的视频扩散UNet)。
训练时,作者从特定注意力层提取特征,这些层中query会关注不同视图和不同时间帧的key。
他们假设这些注意力图编码了软对应:对于某视图中的一个query点,获得高注意力的key位置应该对应于其他视图或后续帧中的同一3D点。
他们附加了一个多视点点跟踪头,接收这些注意力特征,预测一组query点在所有目标视图和时间步上的轨迹。
跟踪头是一个小型MLP,输出每个点的2D坐标。
真实轨迹来自合成数据(已知相机位姿和深度)或多视点视频中标注的点。
损失函数是L2预测与真实位置之差。
扩散模型联合训练:标准噪声预测损失加上点跟踪损失。
这会迫使注意力层产生的对应不仅视觉合理,而且几何准确。
关键是,跟踪头只在训练时使用;推理时扩散模型正常运行(不带跟踪头),但其内部注意力权重已被调整得更加几何一致。
[视频帧 + 相机位姿] -> [扩散UNet]
                            |
      [时间注意力]     [跨视图注意力]
        (时间维映射)      (相机间映射)
               |               |
               +------+--------+
                      |
                      v
        [多视点点跟踪头]
            预测2D轨迹
                      |
                      v
        点跟踪损失 + 扩散损失
                      |
                      v
              更新两个模型部分
结构性比喻:把扩散模型想象成一个多摄像头监控系统。
每个摄像头(视图)有自己的监视器(特征图)。
注意力层就像保安,本能地跨监视器看“同一个人”——但他训练不足,有时会把不同的人弄混,导致录像中的人在不同摄像头之间错误移动。
点跟踪头就像额外的主管,给每个人胸前贴上跟踪贴纸,强迫保安总是看正确的人。
通过联合训练,保安学会了始终跟随贴纸,所以最终录像(不带贴纸时)仍能准确跟踪每个人跨监视器移动。
关键概念
-
多视点点跟踪:给定参考视图中一组2D点,预测它们在所有其他视图和所有未来帧中的2D位置。这是一个密集对应任务,直接衡量几何和运动一致性。真实值可以从合成数据(已知深度和相机位姿,投影3D点到每个视图)或多视点视频获得。
-
注意力作为对应:在基于Transformer的扩散模型中,query与key的点积产生注意力图,指示某query与哪些其他视图或时间的哪些位置“相关”。如果注意力图模糊或不对齐,生成的视频可能出现某人的左臂在一个视图、右臂在另一个视图。通过间接监督这些图(通过点跟踪),模型学会让它们更尖锐、对齐。
-
用辅助头联合训练:点跟踪头仅在训练时需要。它像一个“探针”,从注意力层提取对应信息并对不对齐施加惩罚。训练后该头可丢弃——扩散模型的权重已经被更新,自动产生更好的对应。
框架转变
之前(仅相机条件方法):           之后(本文方法):

输入 -> [扩散UNet] -> 视频          输入 -> [扩散UNet] -> 视频
        (无几何约束)                          | (注意力特征)
                                              v
                                        [跟踪头] (仅训练)
                                              |
                                        点跟踪损失

核心弱点:形状漂移,运动不一致       核心优势:跨视图和时间的几何一致运动
一句话:从“无几何监督”到“将多视点点跟踪作为辅助训练目标”,核心转变是把内部注意力对应视为可训练的信号,无需显式3D重建即可强制执行3D一致性。
专家评审
选题眼光: 真实缺口。新视角视频合成是热点,显式3D重建与仅相机条件方法之间的权衡众所周知。本文精准攻击后者的弱点,且手段实用、高效。完美位于几何视觉与生成模型的交叉点。
方法成熟度: 巧劲,不是蛮力。利用内部注意力特征的想法很优雅——无需修改核心架构,只需加一个轻量头和一个损失。这是那种“最小工程,最大影响”的突出做法。其他人可能尝试暴力3D重建或循环一致性,但此法更简单有效。
实验诚意: 论文声称SOTA几何一致性(通过点跟踪指标和扭曲误差衡量)。基线包括显式3D方法和仅相机条件方法,公平。在多个基准(Dynamic Replica等)上显示一致提升。没有明显红旗;消融实验去除跟踪损失证实其关键作用。但跟踪头依赖合成真实值——真实场景泛化可能有限。缺少真正的野外视频测试。
写作功力: 动机清晰,行文流畅。方法部分的符号说明可以更清晰——注意力图和跟踪头细节略显仓促。重写第3.2节(跟踪损失公式化)并添加具体例子,能让整篇论文提升一档。
判决: 强接收——解决了真实问题,方法优雅,实验充分。
要点总结
- 实用技术:如果你在训练仅相机条件的视频扩散模型,添加一个基于注意力特征的辅助点跟踪损失,是提升几何一致性的廉价方法。如果合成数据不可用,甚至可以用深度估计生成伪真实值。
- 思维框架:“注意力层已经编码对应,我们只需监督它们”——这个想法可以迁移到其他需要对齐的任务(如多视图图像翻译、3D感知图像编辑)。检查你的任务是否有能从注意力中提取的自然对应信号。
- 具体可偷:一个2–3层的MLP放在选定的注意力图之上,就能预测2D轨迹。训练高效因为头很小。这种“探针+联合训练”的模式可应用于任何具有交叉注意力的生成模型。