Paper: 2608.11167 Authors: Changhao Xiang, Shangyu Xing, Zhen Wu, Jianbing Zhang, Xinyu Dai Categories: cs.CV, cs.CL, cs.LG
The Gap
The standard recipe for teaching an LLM to see is embarrassingly blunt. Take a frozen vision encoder, bolt on a projector, and train it on hundreds of thousands of image-caption pairs — LLaVA’s 558K/600K stage-one corpus is the canonical example, BLIP-2’s Q-Former is the same idea with more parameters in the bridge. The supervision signal is: here is a bag of visual tokens for the whole scene, here is a paragraph of prose, make them agree.
The problem is that “make them agree” hides an unsupervised assignment problem. A picture with a dog, a frisbee, and a patch of grass paired with the caption “a dog catches a frisbee on the grass” never tells the model which visual tokens correspond to which noun. The model has to recover that mapping from co-occurrence statistics across the whole corpus. That works — eventually, expensively — and it is why alignment pretraining is data-hungry and why grounding stays mediocre afterwards.
The grounding-focused line of work (Kosmos-2, Shikra, Ferret, GLaMM) noticed this and added location supervision, but almost all of it does so by serializing coordinates into text: “a dog [0.31, 0.44, 0.58, 0.79] catches a frisbee.” That is an indirection — the model reads numbers, then has to look up what lives at those numbers inside the global feature map. It reduces ambiguity without eliminating it, and it spends the language model’s capacity on learning a coordinate dialect.
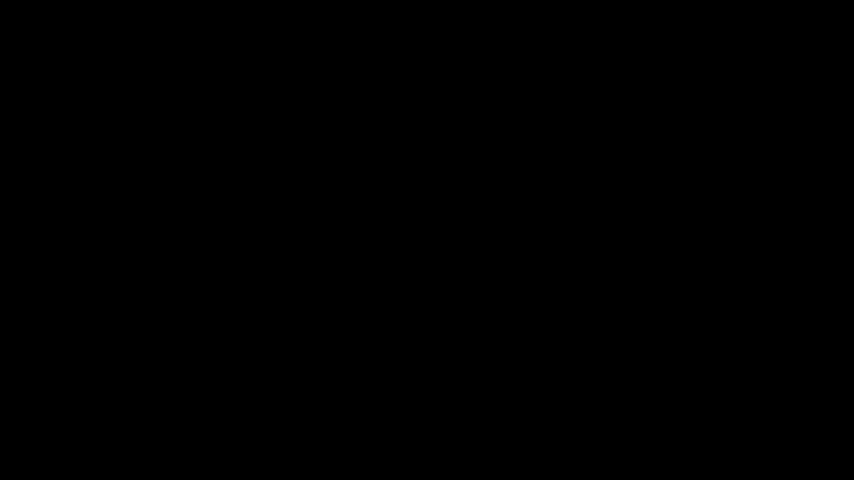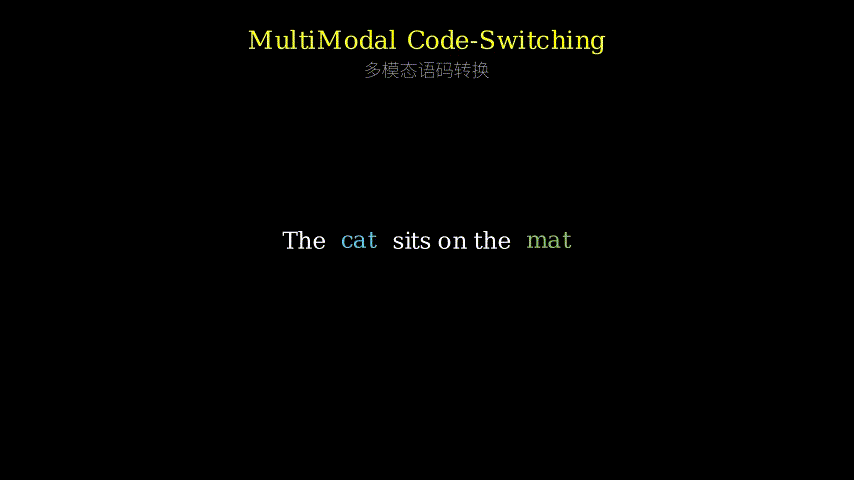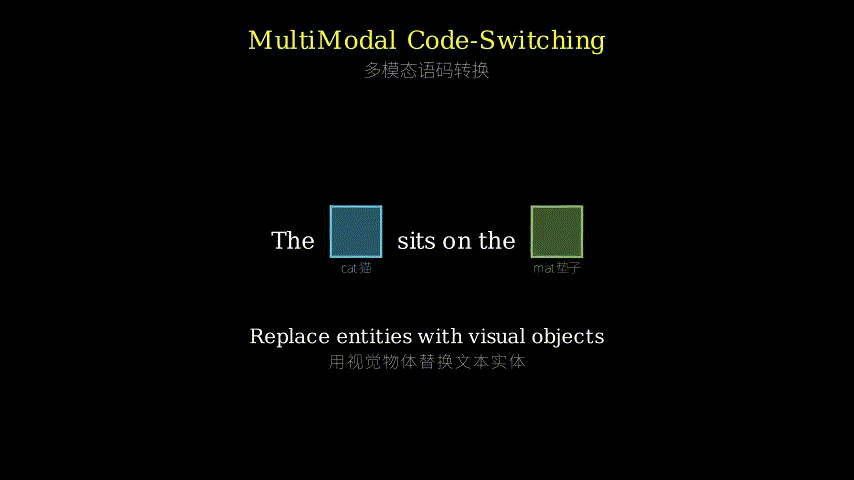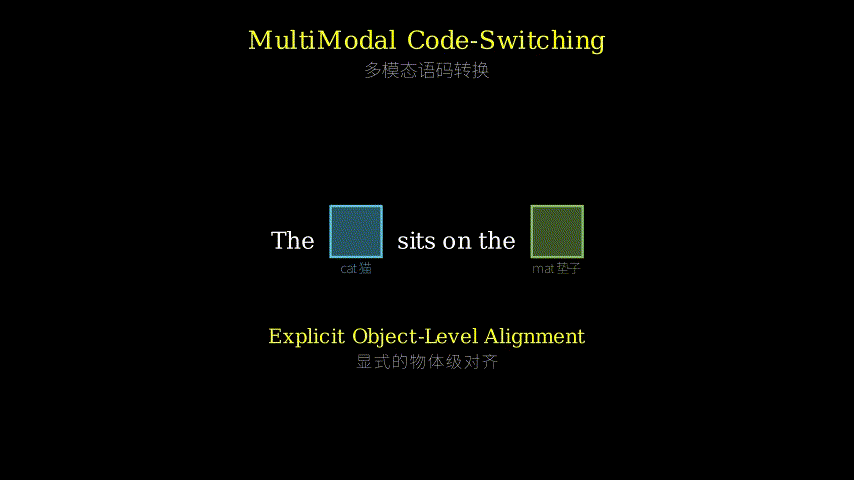
MMCS asks a simpler question: if the caption says “dog,” why not put the dog there, in the sequence, instead of a word or a box?
PROBLEM: image-level alignment
   one global image representation <-> one long caption
   N visual objects, M text entities, zero links given
                    |
                    v
ASSUMPTION: the missing links are the bottleneck
   the model can solve the N x M assignment from
   corpus-wide co-occurrence, but only slowly
   ==> data inefficiency + weak grounding
                    |
                    v
METHOD: MultiModal Code-Switching
   replace the entity token with the object itself
   "a dog catches a frisbee"
     ->  "a <o1> catches a <o2>"
   + a synthesis pipeline for 773K such samples
                    |
                    v
EVIDENCE
   50K MMCS samples  >=  600K image-text pairs
   grounding + perception gains hold across model sizes
                    |
                    v
CONCLUSION
   the bottleneck was supervision *granularity*,
   not supervision *volume*
The Increment
One sentence: Before, object-level grounding had to be inferred from global image-text co-occurrence (or bolted on as textual coordinates); after, the correspondence is baked into the token sequence itself as an identity — the noun slot *is the object — and the alignment stage gets roughly an order of magnitude more data-efficient.
Core Mechanism
There are two halves: an offline data factory and a trivially simple training objective.
The factory inverts a grounding model. Start from an image-caption pair, parse the caption for entity nouns, and hand each noun to an open-vocabulary grounder to get a box. Then filter aggressively — and this filtering is the part that actually determines data quality. If a noun gets no box, drop it. If it gets several boxes (“two dogs”), the one-to-one correspondence is broken, so drop it or the whole sample. If the box is tiny, the crop carries no signal. What survives is a triple: image, caption, and a clean noun-to-region map. Repeat 773K times.
Assembly is where the “code-switching” happens. For each grounded noun, crop the region, push it through the same vision encoder and projector the model already uses, and substitute the resulting embedding into the text sequence at the noun’s position. The surrounding words — determiners, verbs, prepositions — stay as text. So the sequence keeps the grammar of language while its content words come from vision, exactly like a bilingual speaker dropping a Mandarin noun into an English sentence.
Then you train with plain next-token prediction on the text positions. This is the load-bearing detail: to predict “catches,” the model must have already extracted “this is a dog, dogs are agents that do dog things” from the object embedding at position i. The gradient has nowhere else to go. Compare this with a global-image setup, where the model can predict “catches” from language priors alone and never look at the pixels.
DATA SYNTHESIS (offline)
   image + caption
        |
        v
   [entity parser]  --> nouns: dog, frisbee, grass
        |
        v
   [open-vocab grounder]  --> candidate boxes per noun
        |
        v
   [filter]  -- drop: no box | multiple boxes | too small
        |         (only 1-to-1 pairs survive)
        v
   (image, caption, noun -> box) x 773K


SEQUENCE ASSEMBLY
   caption: "a  dog  catches a  frisbee  on the grass"
                 |                |
                 v                v
            crop(box)        crop(box)
                 |                |
          [vision encoder]  [vision encoder]
                 |                |
            [projector]      [projector]
                 |                |
                 v                v
   tokens:  a  <o1>  catches a  <o2>  on the grass
            ^          ^^^^^                ^^^^^
            text scaffolding preserved


TRAINING
   next-token loss on TEXT positions
   predicting "catches" requires reading <o1>
   ==> the object vector is pushed into lexical space
The metaphor: think of a recipe card in a professional kitchen.
The mainstream approach hands the line cook a photograph of the entire prep counter stapled to a paragraph of prose: “dice the shallot, then deglaze with the wine.” The cook can see everything and knows the words, but must figure out for himself which pale blob in the photo is the shallot and which is the garlic. Over a thousand shifts he’ll get it right by correlation. That’s 600K image-text pairs.
The coordinate-grounding approach improves the card: “dice the shallot (counter photo, grid ref B4).” Better — but now the cook has to learn a grid-reference dialect, and he still has to make the lookup, and a slightly-off grid reference lands him on the garlic.
MMCS staples the actual shallot to the card, in the slot where the word “shallot” would be. There is no lookup and no dialect. The recipe’s grammar — dice, then deglaze, sequence and syntax — stays in words, because that’s what words are good at; the referents are physically present. The data pipeline is the prep cook who takes the counter photo and pre-bags each ingredient; the filtering step is him refusing to bag anything when there are two shallots on the counter and he can’t tell which one the recipe meant. And the reason the trainee learns fast is that he can’t fake it: to know that this thing gets diced rather than deglazed, he has to actually look at the thing in the slot.
Key Concepts
-
Referential ambiguity: The gap between “these two things are about each other” and “*this part goes with that word.” Show someone a photo of a crowded kitchen and say “the mise en place is ready” — they learn nothing about which object is a shallot. Show them a photo with three objects and a caption naming three objects, and there are six possible assignments; the caption doesn’t pick one. Contrastive and captioning objectives on whole images give you the first kind of signal and hope the second falls out. It does, at scale, which is precisely why the scale is needed.
-
Code-switching, and why it’s the right analogy: In linguistics, code-switching isn’t random mixing — a bilingual speaker keeps one language’s grammatical frame and inserts the other language’s content words at points where they’re a cleaner fit (“我 sent 了 email”). The frame language handles structure; the embedded language handles the specific referent. MMCS takes exactly this division of labor: text keeps syntax, vision supplies nouns. The insight is that vision and language aren’t interchangeable descriptions of the same thing — they’re good at different jobs, and the switch point is where the alignment information lives.
-
Substitution vs. appending: Nearly every interleaved-multimodal setup *appends — image, then text, then image, then text. Appending lets the model route around the visual input, because the text is self-sufficient. Substitution removes the textual crutch: the word is gone, so the object embedding is the only path to the answer. It’s the same trick as masked language modeling — you learn about a word by deleting it — applied across modalities. Cheap to implement, and it changes the gradient structure fundamentally.
Framework Shift
Before (LLaVA / BLIP-2 style):        After (MMCS):

  +--------------------+                +----+----+-------+
  |    whole image     |                | o1 | o2 |  o3   |
  +--------------------+                +----+----+-------+
            |                             |     |     |
     [global tokens]                    crop  crop  crop
            |                             |     |     |
            v                             v     v     v
  "a dog catches a frisbee           "a <o1> catches a
        on the grass"                  <o2> on the <o3>"
            |                                   |
            v                                   v
  model must GUESS which               slot position == the
  tokens mean "dog"                    correspondence itself
            |                                   |
            v                                   v
  needs ~600K pairs                    ~50K samples suffice
  to average out the noise             (per the paper)
From global-to-global matching to slot-level substitution, the core shift is that correspondence stops being something the model must infer and becomes something the data format asserts.
Expert Assessment
Problem choice: Real gap, and a well-chosen one. The data inefficiency of the alignment stage is a known embarrassment — everyone runs the LLaVA pretrain recipe and nobody defends it as principled. That said, the neighborhood is crowded: region-level pretraining (GLIP, RegionCLIP), grounded captioning (Kosmos-2), and referring MLLMs (Ferret, GLaMM, ASM) all attack the same ambiguity. MMCS’s claim to novelty is the *format — pixels substituted inline rather than coordinates appended — plus the pipeline that makes it scalable. That’s a real but incremental delta, and the honest framing is “a better format for the same insight,” not “a new insight.”
Method maturity: Clever rather than brute-force, and cheap enough to be adopted, which is the highest compliment for a pretraining trick. Three concerns. First, the pipeline inherits the grounder’s biases and errors wholesale — MMCS can only teach the model to align what GroundingDINO-class models already localize well, which is a ceiling nobody has measured. Second, deleting the noun from the text is a double-edged sword: the model may learn object-vector-to-context mapping while *weakening the word-to-object link, unless normal captions are mixed in; I’d want to see that ablation. Third, cropped-object embeddings are context-free by construction, so the model sees a dog with no scene around it — this may help identity and hurt spatial relations, and the paper’s own emphasis on grounding benchmarks makes this worth checking carefully.
Experimental integrity: The headline “50K beats 600K” is rhetorically strong but the comparison deserves scrutiny. It’s a comparison against the LLaVA-style pretrain corpus, which is a weak baseline *specifically on grounding — of course object-level supervision wins on RefCOCO-style tasks. The sharper question is whether the gains survive full instruction tuning, since alignment-stage advantages notoriously wash out once you run a large SFT stage on top. There’s also a distributional-proximity worry: the synthesis pipeline uses a grounder trained on data close to the grounding benchmarks, so some of the improvement may be distillation from that grounder rather than better alignment per se. And a small tell: if 50K matches 600K, why build 773K? Either the curve saturates early (in which case say so and show it) or the 773K results are less flattering than the 50K headline. The scaling curve is the most load-bearing figure in the paper and it’s the one the abstract avoids quantifying. Everything here is judged from the abstract’s claims; the tables would settle it.
Writing quality: The framing is excellent — “code-switching” is a genuinely illuminating name and does real explanatory work, which is rarer than it should be. The corner most likely cut is the pipeline section: filtering heuristics, multi-instance handling, and crop-size policy are where all the quality lives and where papers like this typically compress into two sentences and a supplementary table. Rewriting the data-scaling analysis — 50K vs. 200K vs. 773K, with and without normal captions mixed in — would elevate this from “nice trick with a good name” to “recipe others adopt.”
Verdict: weak accept — a well-motivated, cheap, reproducible format change with a compelling data-efficiency claim, held back by a favorable baseline choice and an under-examined dependence on the grounder that generated its data.
Takeaways
- Substitute, don’t append. If you want a model to actually use a modality, delete the redundant modality rather than adding to it. Appending permits shortcuts; substitution closes them. This transfers directly: splice an audio clip where the speaker’s name goes, a table cell where the number goes, a function body where the identifier goes.
- Invert a specialist model to synthesize supervision. You don’t need human annotation for object-entity links — a grounder plus aggressive filtering gives you 773K samples. The general pattern: whenever you want fine-grained alignment labels, find an off-the-shelf model that produces one direction of the mapping and filter hard for the unambiguous cases. Be aware you’re distilling that model’s competence and its blind spots.
- The filter is the method. “Keep only one-to-one correspondences” is doing more work here than the architecture. When you build synthetic data, ambiguity-rejection rules deserve as much design attention as the generation step.
- Reframe volume problems as granularity problems. The reflex when alignment is weak is to add data. Ask instead what the current format fails to state explicitly, and whether stating it directly changes the gradient structure. That question is worth asking about most pretraining corpora.
- Steal the linguistic framing. The frame-language/embedded-language split — one modality supplies structure, another supplies referents — is a useful design axis for any multimodal sequence format, and it’s more principled than “interleave everything.”
论文: 2608.11167 作者: Changhao Xiang, Shangyu Xing, Zhen Wu, Jianbing Zhang, Xinyu Dai 分类: cs.CV, cs.CL, cs.LG
缺口
教 LLM「看见」的标准配方粗暴得有点尴尬。
拿一个冻结的视觉编码器,接上投影层,用几十万图文对训练——LLaVA 一阶段的 558K/600K 语料是经典范例,BLIP-2 的 Q-Former 是同一思路加更多桥接参数。
监督信号本质上是:这是整张图的一堆视觉 token,这是一段文字,你们互相对应上。
问题在于「对应上」这四个字里藏着一个无监督的指派问题。
一张有狗、飞盘、草地的图,配上「一只狗在草地上接飞盘」,从来没告诉模型哪些视觉 token 对应哪个名词。
模型只能从全语料的共现统计里把这个映射反推出来。
这条路走得通——但慢,且贵。这就是为什么对齐阶段如此吃数据,也是为什么训完之后 grounding 能力依然平庸。
做 grounding 的那条线(Kosmos-2、Shikra、Ferret、GLaMM)意识到了这点,加入了位置监督,但绝大多数做法是把坐标序列化成文本:「一只狗 [0.31, 0.44, 0.58, 0.79] 接飞盘」。
这是一次间接寻址——模型读到数字,还得回到全局特征图里查这些数字对应什么。
歧义被削弱了但没被消除,而且语言模型的容量被花在学一种「坐标方言」上。
MMCS 问了个更朴素的问题:既然图注里写的是「狗」,为什么不把那只狗本身放在那个位置,而非放一个词或一个框?
PROBLEM: 图像级对齐
   一个全局图像表示 <-> 一段长图注
   N 个视觉物体, M 个文本实体, 对应关系为零
                    |
                    v
ASSUMPTION: 缺失的连边才是瓶颈
   模型能从语料共现里解出 N x M 指派
   但速度极慢 ==> 数据低效 + grounding 弱
                    |
                    v
METHOD: MultiModal Code-Switching
   用物体本身替换实体 token
   "一只狗接飞盘"
     ->  "一只 <o1> 接 <o2>"
   + 一条合成流水线, 产出 773K 样本
                    |
                    v
EVIDENCE
   50K MMCS 样本  >=  600K 图文对
   grounding 与感知提升在多个模型规模上成立
                    |
                    v
CONCLUSION
   瓶颈在监督的 *粒度*, 不在监督的 *体量*
增量
一句话:在此之前,物体级对应关系要么靠全局图文共现自己「长出来」,要么以文本坐标的形式外挂;在此之后,对应关系被直接写进 token 序列,成为一种恒等关系——名词槽位就是那个物体——对齐阶段的数据效率据称提升了一个数量级。
核心机制
方法分两半:一条离线数据工厂,加一个平淡无奇的训练目标。
工厂做的事是把 grounding 模型反过来用。
从图文对出发,解析图注里的实体名词,把每个名词交给开放词表定位模型拿框。
然后是激进的过滤——这一步其实才真正决定数据质量。
某个名词拿不到框,扔掉;拿到多个框(「两只狗」),一对一关系就断了,扔掉这个名词甚至整条样本;框太小,图块没信息量,扔掉。
活下来的是一个三元组:图、图注、干净的「名词到区域」映射。重复 773K 次。
组装阶段才是「语码转换」发生的地方。
对每个成功定位的名词,裁出区域,过一遍模型本来就有的视觉编码器和投影层,然后把得到的向量替换到文本序列中该名词的位置上。
周围的词——冠词、动词、介词——保持文本形态。
于是这个序列保留了语言的语法骨架,而实词内容来自视觉,正如一个双语者在中文句子里塞进一个英文名词。
接着就用最普通的 next-token prediction 在文本位置上训练。
这是承重的细节:为了预测「接」这个动作,模型必须先从位置 i 的物体向量里提取出「这是狗、狗是会做这类事的施事者」。
梯度没有别的路可走。
对比全局图像的设定:模型完全可以靠语言先验预测出「接」,一眼不看像素也能过关。
数据合成 (离线)
   图像 + 图注
        |
        v
   [实体解析]  --> 名词: 狗, 飞盘, 草地
        |
        v
   [开放词表定位]  --> 每个名词的候选框
        |
        v
   [过滤]  -- 丢弃: 无框 | 多框 | 过小
        |         (只留一对一)
        v
   (图像, 图注, 名词 -> 框) x 773K


序列组装
   图注:  "一只  狗   接   飞盘   在草地上"
                  |         |
                  v         v
             crop(box)  crop(box)
                  |         |
           [视觉编码器] [视觉编码器]
                  |         |
             [投影层]   [投影层]
                  |         |
                  v         v
   tokens:  一只 <o1> 接 <o2> 在草地上
                       ^^        ^^^^^
                    文本骨架保留


训练
   仅在文本位置计算 next-token loss
   要预测「接」, 必须读懂 <o1>
   ==> 物体向量被挤进词汇语义空间
核喻:把它想成专业厨房里的一张菜谱卡。
主流做法是:给厨工一张「整个备菜台」的照片,钉在一段文字上:「把洋葱切丁,再用酒去腥」。
厨工什么都看得见,字也都认识,但得自己琢磨照片里那个白团子哪个是洋葱、哪个是蒜。
干上一千个班次,他靠相关性总能猜对。这就是 60 万图文对。
坐标 grounding 的做法是改进卡片:「把洋葱切丁(备菜台照片,网格 B4)」。
好一些——但厨工得先学会看网格编号这门方言,而且他仍然要做一次查表,编号偏一格就切到了蒜。
MMCS 的做法是:把那颗洋葱本身钉在卡片上「洋葱」这个词的位置。
没有查表,也没有方言。
菜谱的语法——先切丁、再去腥,顺序与句法——依然留在文字里,因为那正是文字擅长的;而指称对象则物理性地就在现场。
数据流水线就是那位提前把备菜台照片拆开、给每样食材单独装袋的备菜员;过滤环节就是他在台面上有两颗洋葱、分不清菜谱指哪颗时,干脆拒绝装袋。
而学徒学得快的原因是他没法糊弄:要知道这东西是该切丁还是该去腥,他必须真的看一眼槽位里那个东西。
关键概念
-
指代歧义(referential ambiguity):区别在于「这两样东西彼此有关」和「*这一块对应那个词」。给人看一张拥挤厨房的照片,说「备菜好了」,他学不到哪个是洋葱。给一张三个物体的图配一句提到三个物体的话,一共有六种指派方式,而这句话没有指定其中任何一种。对比学习和整图 caption 目标给的是第一类信号,然后指望第二类会自己涌现。它确实会涌现——在足够大的规模下。这恰恰解释了为什么需要那么大的规模。
-
语码转换,以及为什么这个类比选得准:语言学里的 code-switching 不是随机混语——双语者会保留一种语言的语法框架,只在最合适的位置插入另一种语言的实词(「我 sent 了 email」)。框架语言负责结构,嵌入语言负责具体指称。MMCS 借的正是这套分工:文本管句法,视觉供名词。真正的洞见是:视觉和语言不是同一件事的两种可互换描述,它们各擅其长,而对齐信息恰恰住在切换点上。
-
替换 vs. 追加:几乎所有交错多模态设定都在追加——图、文、图、文。追加允许模型绕开视觉输入,因为文本本身自洽。替换抽掉了文本这根拐杖:词不在了,物体向量成了唯一通路。这和掩码语言模型是同一个把戏——想让模型学会一个词,就把它删掉——只是跨了模态。实现成本极低,但梯度结构被根本性地改变了。
框架转变
之前 (LLaVA / BLIP-2 路线):          之后 (MMCS):

  +--------------------+                +----+----+-------+
  |      整张图        |                | o1 | o2 |  o3   |
  +--------------------+                +----+----+-------+
            |                             |     |     |
       [全局 token]                     crop  crop  crop
            |                             |     |     |
            v                             v     v     v
   "一只狗在草地上                    "一只 <o1> 接
      接飞盘"                          <o2> 在 <o3> 上"
            |                                   |
            v                                   v
   模型必须 *猜* 哪些 token          槽位本身 == 对应关系
   代表「狗」                        没有可猜的余地
            |                                   |
            v                                   v
   需要约 60 万图文对                约 5 万样本即可
   靠平均把噪声磨掉                  (论文数据)
一句话:从「全局对全局的匹配」到「槽位级的替换」,核心转变是——对应关系不再是模型需要推断的东西,而是数据格式直接断言的东西。
专家评审
选题眼光:真缺口,而且挑得准。
对齐阶段的数据低效是公认的尴尬——大家都在跑 LLaVA 的预训练配方,但没人真心认为它有道理。
不过这条街已经很挤:区域级预训练(GLIP、RegionCLIP)、grounded captioning(Kosmos-2)、referring MLLM(Ferret、GLaMM、ASM)打的都是同一个歧义。
MMCS 的新意在于格式——像素内联替换而非坐标外挂——加上让它可规模化的那条流水线。
这是真增量,但是增量式的;诚实的定位是「对同一洞见给出了更好的格式」,而不是「提出了新洞见」。
方法成熟度:属于巧劲而非蛮力,而且便宜到别人真会用,这对预训练技巧来说是最高的评价。
三点隐忧。
其一,流水线把定位模型的偏差和错误整体继承了下来——MMCS 只能教会模型对齐那些 GroundingDINO 级模型本就定位得好的东西,这个天花板没人量过。
其二,把名词从文本里删掉是双刃剑:模型可能学会了「物体向量到上下文」的映射,同时削弱了「词到物体」的链接,除非训练里混入了正常图注;这个 ablation 我很想看。
其三,裁剪出的物体向量天生没有上下文,模型看到的是一只没有场景的狗——这可能有利于识别身份而不利于空间关系,而论文恰恰重点押在 grounding 基准上,值得细究。
实验诚意:「5 万打赢 60 万」这句话修辞力很强,但对比对象需要推敲。
它比的是 LLaVA 式预训练语料,而后者在 grounding 上本来就是个弱基线——加了物体级监督,在 RefCOCO 类任务上赢是理所当然的。
更尖锐的问题是:这些增益能不能活过完整的指令微调?
对齐阶段的优势在大规模 SFT 之后被冲掉,是这个领域的老现象。
还有一层分布邻近性的担忧:合成流水线用的定位模型,其训练数据与 grounding 基准相当接近,所以一部分提升可能来自对那个定位模型的蒸馏,而非「更好的对齐」本身。
另有一个小破绽:如果 5 万就能打平 60 万,那为什么要造 773K?
要么曲线很早就饱和(那就把它画出来说清楚),要么 773K 的结果没有 5 万的标题那么好看。
数据规模曲线是全文最承重的一张图,而摘要恰好回避了给它数字。
以上判断都基于摘要中的表述,真正能定论的是论文里的表格。
写作功力:立意很好——「语码转换」这个名字有真正的解释力,能承担认知负担,这比想象中稀少。
最可能偷懒的地方是流水线一节:过滤启发式、多实例处理、图块尺寸策略,所有质量都藏在这里,而这类论文往往两句话加一张附录表就打发了。
如果把数据规模分析重写——5 万 / 20 万 / 773K,混入正常图注与不混入的对照——这篇论文就能从「有个好名字的小技巧」升级成「别人会照着抄的配方」。
判决:弱接收 —— 动机清楚、成本低廉、可复现的格式改动,数据效率的说法很吸引人;但基线选得偏向自己,且对「生成其数据的那个定位模型」的依赖没有被认真检验。
要点总结
- 要替换,不要追加。 想让模型真的用上某个模态,就删掉冗余的那个模态,而不是往上加。追加留下了捷径,替换把捷径堵死。这条可以直接迁移:把音频片段塞进说话人名字的位置,把表格单元塞进数字的位置,把函数体塞进标识符的位置。
- 反用一个专家模型来合成监督。 物体-实体链接不需要人工标注——一个定位模型加上激进过滤就能产出 773K 样本。通用套路是:想要细粒度对齐标签时,找一个现成模型能给出该映射的某一个方向,然后只保留无歧义的样本。同时要清楚,你继承的是那个模型的能力,也包括它的盲区。
- 过滤规则才是方法本体。 「只保留一对一对应」这条规则干的活比架构多。做合成数据时,歧义剔除规则值得投入与生成步骤同等的设计精力。
- 把「体量问题」重述为「粒度问题」。 对齐效果不好时,条件反射是加数据。更该问的是:当前的数据格式漏掉了什么本该显式说出的东西,以及把它直说出来会不会改变梯度结构。这个问题对大多数预训练语料都值得问一遍。
- 顺手把语言学框架偷走。 框架语言 / 嵌入语言的分工——一个模态供结构,另一个供指称——是设计任何多模态序列格式时的一条有用坐标轴,而且比「什么都交错一下」更有原则。