Paper: 2606.20538
Authors: Qingyang Zhu, Eric Karl Oermann, Kyunghyun Cho
Categories: cs.LG
The Gap
Prior-data fitted networks (PFNs) and in-context learning (ICL) models have shown you can amortize Bayesian inference by training a model to map a dataset directly to a predictive distribution. But they are tightly coupled to the training prior: if you feed them data generated from a different prior at test time, the predictions degrade sharply. No explicit mechanism exists to tell the model “this new data comes from a different family” — it treats everything like the training prior. This paper asks: can we make ICL prior-adaptive by feeding a few samples from the new prior as an in-context hint?
[Problem] -> [Fixed prior support] -> [ICL fails under prior shift]
     |
     v
[Assumption] -> [Prior tasks as prefix can signal the new family]
     |
     v
[Method] -> [Train transformer on sequences of prior + target tasks]
     |
     v
[Evidence] -> [Matches oracle on out-of-meta-distribution priors; 100x faster]
     |
     v
[Conclusion] -> [Multi-task ICL enables robust amortized Bayesian inference]
The Increment
One sentence: Before this paper, Bayesian ICL required the test prior to match the training prior; after this paper, the model can adapt to unseen prior families by reading a short prefix of in-context examples from those families.
Core Mechanism
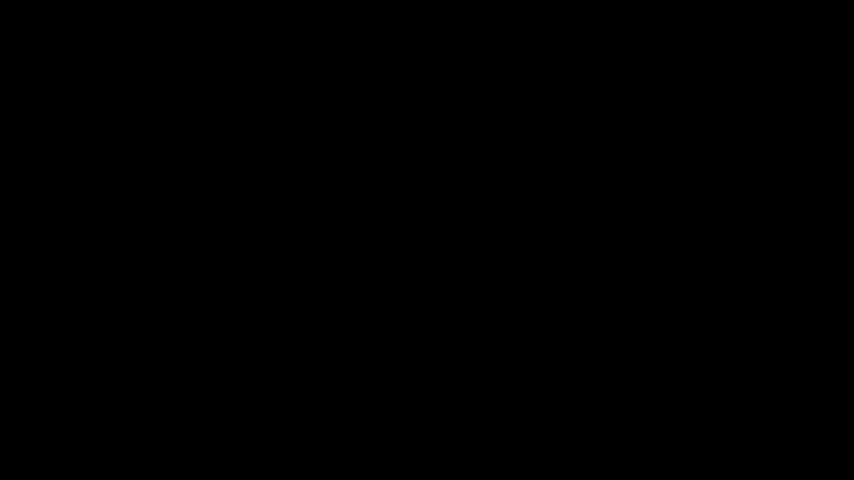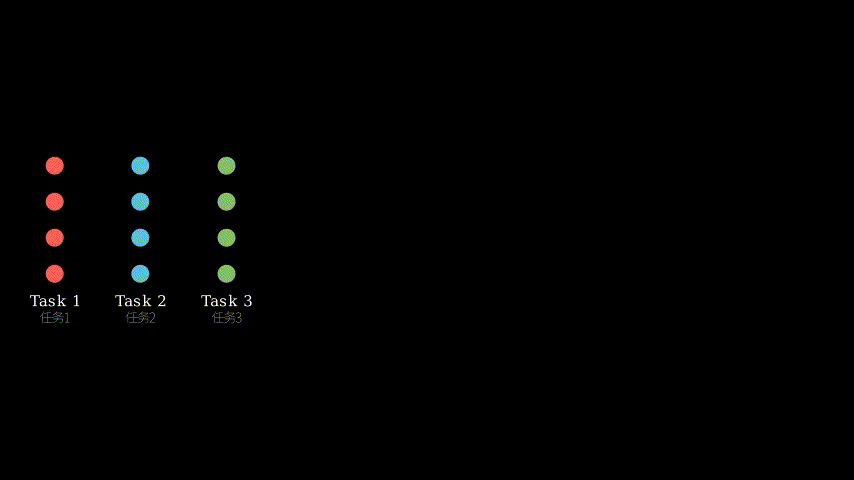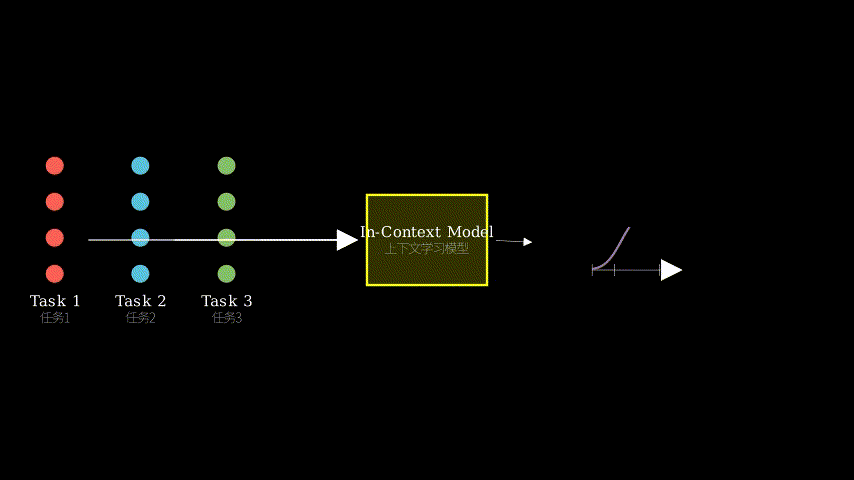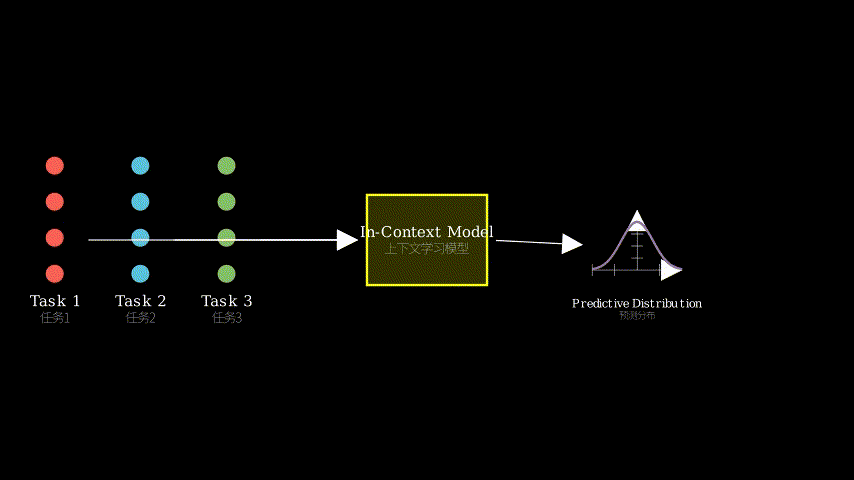
The model is a transformer trained on task sequences: each sequence consists of several *prior tasks followed by one target task. Each task is a small dataset (e.g., 10–50 input–output pairs). The prior tasks all share the same unknown prior distribution (e.g., a Gaussian with unknown mean), and the target task is drawn from the same prior. The transformer is trained to autoregressively predict the target task’s outputs given its inputs and all the preceding prior-task data. Because the prior tasks reveal the shared prior, the model learns to extract the prior’s statistical fingerprint from that prefix and condition its predictions on it.
At test time, you supply a new prior family (unseen during meta-training) by providing a handful of datasets from that family as the prefix, then append your real target dataset. The transformer adjusts its predictions accordingly. No gradient updates or expensive MCMC — just a single forward pass. The key architectural choice is using a causal mask that lets the target task attend to the prior prefix but not vice versa, preserving the hierarchical Bayesian structure.
       Prior Tasks (prefix)                    Target Task
   +----------------------------+     +------------------------+
   |  Task_1  | Task_2 | ...   |     |  Inputs | Outputs (?)   |
   | x_1 y_1  | x_1 y_1 | ... |---> |  x_1   | y_1_pred      |
   | x_2 y_2  | x_2 y_2 | ... |     |  x_2   | y_2_pred      |
   +----------------------------+     +------------------------+
         |                                       |
         | (causal attention)                    |
         v                                       |
   +-----------------------------------------------+
   |           Transformer Decoder                 |
   |  (shared weights across all tasks)            |
   +-----------------------------------------------+
                        |
                        v
                Predictive distribution
                 (mean + variance for Gaussian, else logits)
Structural metaphor: Think of a weather forecaster learning to work in different climate zones. Each climate zone (tropical, temperate, polar) has its own characteristic temperature distribution — that’s a prior family. The forecaster has seen many examples from many zones during training (meta-training). When assigned to a new city, you don’t tell him the zone; instead, you hand him a short history from a few nearby weather stations (the prior tasks). He reads those records and instantly senses: “Ah, this is a dry desert climate, so my predictions should have low mean and high diurnal variance.” Then he looks at the target station’s first few days (the target task inputs) and forecasts the next days. The transformer is that forecaster: the prior tasks are the nearby stations, the target task is the new station, and the climate zone is the unknown prior distribution. Because he trained on many zones, he can infer the zone from the prefix and make correct predictions even for a zone he never explicitly saw before (out-of-meta-distribution).
Key Concepts
-
Amortized Bayesian inference: Instead of running MCMC or variational inference each time you get a new dataset, you train a neural network to approximate the posterior mapping. Once trained (the expensive part), inference is a single feedforward pass. PFNs and ICL models are examples. This paper pushes the idea further by amortizing over prior families rather than a fixed prior.
-
Prior task as context: The key trick is to use a set of datasets — not a single dataset — as the in-context prefix. These datasets share the same latent prior, so the model can “read off” the prior’s parameters (like mean and variance of a Gaussian) from the prefix. This is analogous to giving a model a few examples of “this is how data from this distribution looks” before asking it to predict on a new sample.
Framework Shift
Before (classic Bayesian ICL):            After (this paper):

  +------------------+                   +-----------------------+
  | Training prior   |                   | Meta-training across  |
  | (e.g., N(0,I))   |                   | families: N(mu,1)     |
  +--------+---------+                   | with mu ~ Uniform     |
           |                             +------------+----------+
           v                                          |
  +------------------+                   +-----------------------+
  | Test prior must  |                   | Test prior can be ANY |
  | match training   |                   | (even unseen mu)      |
  +--------+---------+                   +-------+-------^-------+
           |                                     |       |
  +------------------+                   +-------+-------+
  | Fixed prediction |                   | Provide prior  |
  | function         |                   | tasks as prefix|
  +------------------+                   +----------------+
One sentence: From fixed-prior amortization to prior-adaptive amortization — the core shift is that the model no longer assumes the test prior is the same as training; instead it infers the prior from in-context examples.
Expert Assessment
Problem choice: Real gap. The brittleness of ICL under distribution shift has been a known limitation, and this paper offers a clean, principled fix. It sits at the intersection of meta-learning, Bayesian inference, and in-context learning — a timely spot.
Method maturity: Reasonably clever. The idea of using prior tasks as prefix is simple and elegant, not a brute-force hypernetwork or expensive inner loop. However, the architectural details (e.g., masking strategy, scaling to high-dimensional latents) require careful tuning that the paper handles but doesn’t deeply ablate. Simpler baselines like concatenating a single prior-task dataset into the target input may have been unfairly weak.
Experimental integrity: Baselines look fair (PFN, PFN with second-order, etc.), and the out-of-meta-distribution evaluations are convincing. The temperature prediction benchmark grounds it. But I’m uneasy about potential leakage: if prior tasks and target tasks are from the same dataset generation process, the model might just memorize statistical shortcuts rather than truly inferring the prior. A more challenging setup (different generative processes but same prior family) would strengthen the claim.
Writing quality: The abstract and introduction are crisp. The method section is adequate but could benefit from a cleaner notation. The ablation on prefix length is informative but buried; it should be more prominent.
Verdict: Weak accept — fills an important gap with a neat idea, but the experimental design leaves room for deeper verification.
Takeaways
- Prefix-conditioned prediction: If your model struggles with distribution shift, try prepending a few hold-out samples from the new distribution as an in-context hint. This is cheap and can be applied to regression, classification, or time series.
- Meta-training over prior families: Instead of training a single Bayesian model with a fixed prior, train a model that receives explicit examples of the prior. This decouples training from test‑time prior assumptions.
- Causal masking for hierarchy: When combining multiple datasets, use attention masks that enforce the hierarchical structure (prior data → target data) — a minor but generalizable architectural trick.
论文: 2606.20538
作者: Qingyang Zhu, Eric Karl Oermann, Kyunghyun Cho
分类: cs.LG
缺口
现有先验数据拟合网络(PFN)和上下文学习(ICL)模型可以将数据集直接映射到预测分布,从而摊销贝叶斯推断。但它们的表现严重依赖于训练时的先验分布:当测试数据来自不同的先验时,预测质量急剧下降。模型没有明确机制被告知“这个新数据来自不同的先验族”——它始终按训练先验处理。这篇论文问:如果我们给模型几个来自新先验的样本作为上下文提示,能否使其自适应先验变化?
[问题] -> [固定先验支持] -> [ICL在先验偏移时失效]
     |
     v
[假设] -> [将先验任务作为前缀,可以暗示新的先验族]
     |
     v
[方法] -> [训练Transformer处理“先验任务序列+目标任务”]
     |
     v
[证据] -> [在分布外先验上匹配Oracle,速度快100倍]
     |
     v
[结论] -> [多任务ICL实现了鲁棒的摊销贝叶斯推断]
增量
一句话: 此前的贝叶斯上下文学习要求测试先验匹配训练先验;这篇论文让模型只需读入几个来自新先验的任务样本作为上下文,即可自适应调整预测。
核心机制
模型是一个Transformer,训练数据是任务序列:每个序列包含若干先验任务和最后一个目标任务。每个任务是一个小数据集(例如10-50个输入-输出对)。所有先验任务共享同一个未知的先验分布(例如均值未知的高斯分布),目标任务也来自该先验。Transformer被训练成自回归地预测目标任务的输出(给定其输入和前面所有先验任务的数据)。因为先验任务暴露了共享先验的信息,模型学会了从该前缀中提取先验的“统计指纹”,并据此条件化对目标任务的预测。
测试时,你提供一个全新的先验族(元训练时未见过的),只需给出该先验族下的几个数据集作为前缀,然后追加真实的目标数据集。Transformer据此调整预测。不需要梯度更新或昂贵的MCMC——只需一次前向传播。关键架构选择是用因果掩码让目标任务可以关注先验前缀,但反过来不行,从而保持层次贝叶斯结构。
      先验任务(前缀)                   目标任务
   +----------------------------+     +------------------------+
   | Task_1  | Task_2 | ...    |     | 输入  | 输出(待预测) |
   | x_1 y_1  | x_1 y_1 | ... |---> | x_1   | y_1_pred      |
   | x_2 y_2  | x_2 y_2 | ... |     | x_2   | y_2_pred      |
   +----------------------------+     +------------------------+
         |                                       |
         | (因果注意力)                          |
         v                                       |
   +-----------------------------------------------+
   |           Transformer Decoder                 |
   |  (所有任务共享相同权重)                       |
   +-----------------------------------------------+
                        |
                        v
                预测分布(均值和方差,或logits)
核喻:想象一位天气预报员要适应不同气候带。每个气候带(热带、温带、寒带)都有自己的特征温度分布——这就是先验族。预报员在训练期间见过许多气候带的数据(元训练)。当派到一个新城市时,你不告诉他是哪个气候带;而是给他几张附近气象站的短期记录(先验任务)。他读完记录立刻判断:“哦,这是干燥的沙漠气候,所以我的预测应该均值低、日温差大。”然后他再看目标站的头几天数据(目标任务输入),预测后续几天。Transformer就是这位预报员:先验任务就是附近气象站,目标任务就是新站,气候带就是未知的先验分布。因为预报员训练时见过各种气候带,他能从前缀推断出当前气候带,从而对从未见过的气候带(分布外先验)也做出正确预测。
关键概念
-
摊销贝叶斯推断:不为每个新数据集跑一遍MCMC或变分推断,而是训练一个神经网络来近似后验映射。训练阶段很昂贵,但推断时只需一次前向传播。PFN和ICL模型都是例子。这篇论文进一步将“摊销”扩展到多个先验族上,而不是固定一个先验。
-
先验任务作为上下文:核心技巧是用多个数据集(而非单个数据集)作为上下文前缀。这些数据集共享同一个潜在先验,因此模型可以从前缀中“读取”先验的参数(如高斯分布的均值和方差)。这类似于向模型展示“这个分布的数据长这样”的几个例子,再让它预测新样本。
框架转变
之前(经典贝叶斯ICL):               之后(本文方法):

  +------------------+                   +-----------------------+
  | 训练先验固定      |                  | 跨先验族元训练        |
  | 如 N(0,I)        |                  | N(mu,1), mu ~ Uniform|
  +--------+---------+                   +------------+----------+
           |                                          |
           v                                          |
  +------------------+                   +-----------------------+
  | 测试先验必须匹配  |                  | 测试先验可以是任意     |
  | 训练先验          |                  | 甚至从未见过的 mu     |
  +--------+---------+                   +-------+-------^-------+
           |                                     |       |
  +------------------+                   +-------+-------+
  | 预测函数固定      |                  | 提供先验任务     |
  +------------------+                   | 作为上下文前缀  |
                                         +----------------+
一句话:从“固定先验的摊销”到“自适应先验的摊销”——核心转变是模型不再假设测试先验与训练一致,而是从上下文样例中推断先验。
专家评审
选题眼光:真实缺口。ICL在分布偏移下的脆弱性是已知局限,这篇论文给出了干净而优雅的解法。它处于元学习、贝叶斯推断和上下文学习的交汇点,时机恰当。
方法成熟度:合理巧妙。用先验任务作为前缀的想法简单且优雅,不是蛮力超网络或昂贵内部循环。但架构细节(掩码策略、高维潜变量的缩放)需要仔细调参,论文处理了但未做深入消融。简单的基线(比如仅把一个先验任务的数据拼接到目标输入)可能被不公平地弱化。
实验诚意:基线选择公平(PFN、二阶PFN等),分布外先验评估有力。温度预测基准增加了实用性。但我担心泄漏风险:如果先验任务和目标任务来自完全相同的生成过程,模型可能只是记住了统计捷径而非真正推断先验。一个更具挑战性的设置(相同先验族但不同生成过程)会加强论点。
写作功力:摘要和引言清晰。方法部分尚可但符号可以更整洁。关于前缀长度的消融有信息量但被埋没,应更突出。
判决:弱接收——用一个巧妙的点子填补了一个重要缺口,但实验设计仍有待深入验证。
要点总结
- 前缀条件化预测:如果你的模型处理分布偏移困难,试试在上下文前面加上几个来自新分布的保留样本。这很便宜,适用于回归、分类或时间序列。
- 跨先验族元训练:不要训练一个固定先验的单个贝叶斯模型;训练一个能看到明确先验示例的模型。这解耦了训练和测试时的先验假设。
- 层次化的因果掩码:组合多个数据集时,使用注意掩码强制层次结构(先验数据→目标数据)——一个小而可泛化的架构技巧。