Paper: 2602.21064 Authors: Mehdi Acheli, Walid Gaaloul Categories: cs.AI, cs.CV, cs.LG
Abstract
This paper presents a groundbreaking training paradigm that bridges affective neuroscience and deep learning. Drawing inspiration from the SEEKING motivational state in the human brain—where heightened curiosity and reward anticipation recruit broader neural regions—the authors propose a dual-model framework. A smaller base model trains continuously while a larger “motivated” model activates intermittently under specific conditions. This approach mimics how emotional states modulate cognitive performance in biological systems. Using scalable architectures with shared weights, the method selectively expands network capacity during critical training moments. Experiments on image classification reveal that this alternating scheme not only improves the base model’s efficiency but also enables the motivated model to outperform its standalone version despite processing less data per epoch.
Key Contributions
- Introduction of a neuroscience-inspired dual-model training framework that alternates between a continuously trained base model and an intermittently activated motivated model
- Design of “motivation conditions” that trigger selective expansion of network capacity during noteworthy training steps, mimicking the SEEKING emotional state
- Exploitation of scalable architectures enabling shared weight updates between models of different sizes
- Demonstration that the motivated model can surpass standalone training performance while seeing less data per epoch
- Achievement of simultaneous training of two models with different deployment constraints at lower cost than training the larger model alone
Methodology and Architecture
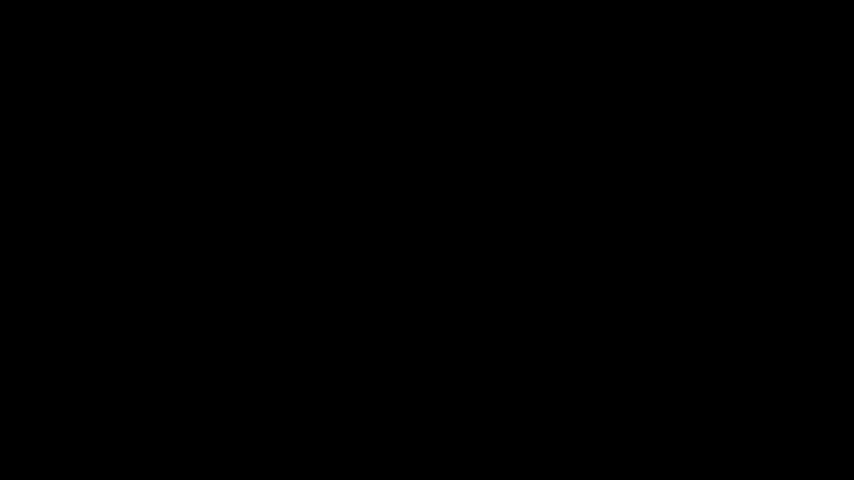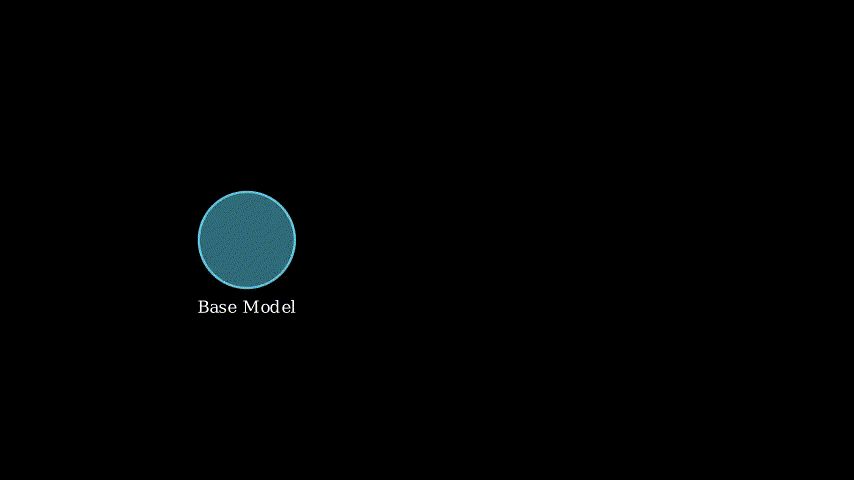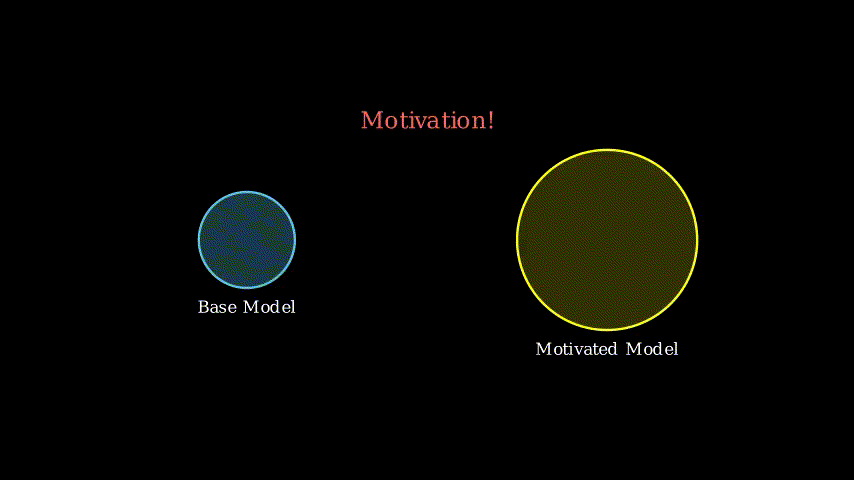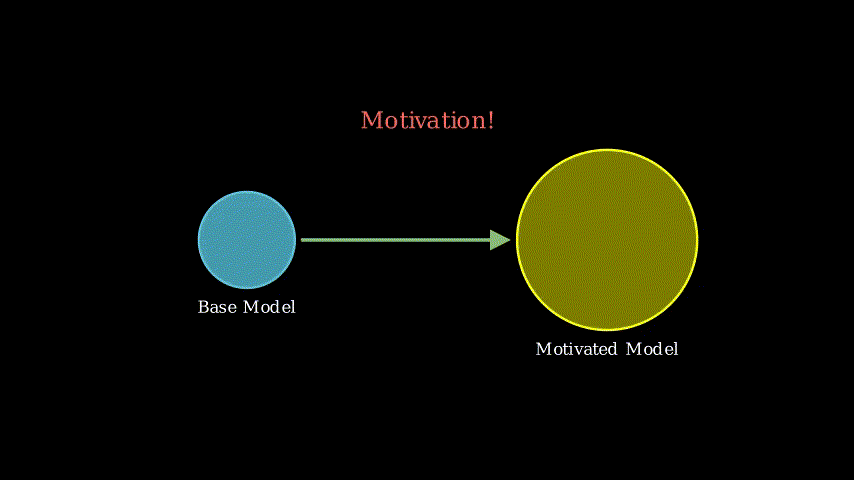
The core innovation lies in the dual-model architecture where the larger motivated model extends the smaller base model through scalable design patterns. During standard training steps, only the base model processes data and updates weights. When predefined motivation conditions are met—analogous to moments of high curiosity or anticipated reward in neuroscience—the system activates the motivated model.
The motivation conditions serve as triggers for engaging additional network capacity. These conditions can be defined based on various criteria: loss plateaus, gradient magnitudes, validation performance changes, or scheduled intervals. When triggered, the motivated model processes the same batch, and its gradients update both the shared base weights and its extended parameters.
This architecture exploits the principle that larger models extending smaller ones can share lower-level representations. The base model’s weights form a subset of the motivated model’s parameters, ensuring that updates to shared weights benefit both models. The selective activation strategy reduces computational overhead while maintaining the benefits of larger capacity during critical learning phases.
Experimental Results and Analysis
Empirical evaluation on image classification tasks reveals several compelling findings. The alternating training scheme demonstrates superior efficiency compared to traditional continuous training of either model alone. The base model, despite its smaller size, achieves enhanced performance through the periodic influence of the motivated model’s broader capacity.
More surprisingly, the motivated model itself often surpasses the performance of an identical architecture trained continuously in isolation. This counterintuitive result occurs despite the motivated model processing fewer samples per epoch due to its intermittent activation. The authors attribute this to the quality of learning during motivated phases—the model encounters data at strategically important moments when the base model signals readiness for capacity expansion.
The training cost analysis shows significant advantages. Training both models simultaneously costs less than training the larger motivated model alone, yet produces two deployable models optimized for different resource constraints. This efficiency gain stems from the base model handling the majority of training iterations while the motivated model contributes only during high-value learning opportunities.
Implications for Neural Network Training
This work challenges conventional assumptions about model training efficiency and capacity utilization. The finding that intermittent high-capacity processing can outperform continuous training suggests that not all training steps require maximum model capacity. Strategic allocation of computational resources based on learning dynamics may be more effective than uniform application.
The neuroscience inspiration provides a compelling framework for thinking about adaptive training strategies. Just as biological systems modulate cognitive resources based on motivational states, artificial systems might benefit from dynamic capacity allocation. This opens research directions in meta-learning, curriculum learning, and adaptive architecture search.
The dual-model output addresses practical deployment scenarios where different resource constraints exist. Edge devices might deploy the base model while cloud services use the motivated model, both benefiting from shared training. This flexibility could streamline production pipelines and reduce the need for separate training runs for different deployment targets.
Takeaways
- Intermittent activation of larger model capacity during strategic training moments can outperform continuous training while reducing computational costs
- Neuroscience-inspired training paradigms offer viable alternatives to traditional uniform training schemes, with the SEEKING motivational state providing a useful conceptual framework
- Scalable architectures with shared weights enable efficient simultaneous training of models at different capacity levels
- The quality and timing of learning experiences may matter more than the quantity of data processed, as evidenced by the motivated model’s superior performance despite seeing less data
- This approach enables production of two deployment-ready models optimized for different resource constraints at lower total training cost than training either model independently
论文: 2602.21064 作者: Mehdi Acheli, Walid Gaaloul 分类: cs.AI, cs.CV, cs.LG
摘要
本文提出了一种连接情感神经科学与深度学习的突破性训练范式。受人脑中SEEKING动机状态的启发——在这种状态下,高度的好奇心和奖励预期会调动更广泛的神经区域——作者提出了一个双模型框架。较小的基础模型持续训练,而较大的”动机”模型在特定条件下间歇性激活。这种方法模拟了生物系统中情绪状态如何调节认知性能。通过使用具有共享权重的可扩展架构,该方法在关键训练时刻选择性地扩展网络容量。图像分类实验表明,这种交替方案不仅提高了基础模型的效率,还使动机模型在每个epoch处理更少数据的情况下超越了其独立训练版本的性能。
主要贡献
- 引入受神经科学启发的双模型训练框架,在持续训练的基础模型和间歇性激活的动机模型之间交替
- 设计”动机条件”机制,在值得注意的训练步骤中触发网络容量的选择性扩展,模拟SEEKING情绪状态
- 利用可扩展架构实现不同规模模型之间的共享权重更新
- 证明动机模型在每个epoch看到更少数据的情况下可以超越独立训练的性能
- 实现以低于单独训练大模型的成本同时训练两个适用于不同部署约束的模型
方法论与架构设计
核心创新在于双模型架构,其中较大的动机模型通过可扩展设计模式扩展较小的基础模型。在标准训练步骤中,只有基础模型处理数据并更新权重。当满足预定义的动机条件时——类似于神经科学中高度好奇或预期奖励的时刻——系统激活动机模型。
动机条件作为触发器来调用额外的网络容量。这些条件可以基于各种标准定义:损失平台期、梯度幅度、验证性能变化或计划间隔。触发时,动机模型处理相同的批次,其梯度更新共享的基础权重和扩展参数。
该架构利用了较大模型扩展较小模型可以共享低层表示的原理。基础模型的权重构成动机模型参数的子集,确保对共享权重的更新使两个模型都受益。选择性激活策略减少了计算开销,同时在关键学习阶段保持了更大容量的优势。
实验结果与分析
图像分类任务的实证评估揭示了几个引人注目的发现。与单独持续训练任一模型的传统方法相比,交替训练方案展示了卓越的效率。基础模型尽管规模较小,但通过动机模型更广泛容量的周期性影响实现了增强的性能。
更令人惊讶的是,动机模型本身经常超越独立持续训练的相同架构的性能。尽管由于间歇性激活,动机模型每个epoch处理的样本更少,但仍出现了这一反直觉的结果。作者将此归因于动机阶段学习的质量——模型在基础模型发出准备扩展容量信号的战略性重要时刻遇到数据。
训练成本分析显示了显著优势。同时训练两个模型的成本低于单独训练较大的动机模型,但产生了两个针对不同资源约束优化的可部署模型。这种效率提升源于基础模型处理大部分训练迭代,而动机模型仅在高价值学习机会期间贡献。
对神经网络训练的启示
这项工作挑战了关于模型训练效率和容量利用的传统假设。间歇性高容量处理可以超越持续训练的发现表明,并非所有训练步骤都需要最大模型容量。基于学习动态的计算资源战略分配可能比统一应用更有效。
神经科学的启发为思考自适应训练策略提供了令人信服的框架。正如生物系统根据动机状态调节认知资源一样,人工系统可能受益于动态容量分配。这开启了元学习、课程学习和自适应架构搜索的研究方向。
双模型输出解决了存在不同资源约束的实际部署场景。边缘设备可能部署基础模型,而云服务使用动机模型,两者都受益于共享训练。这种灵活性可以简化生产流程,减少为不同部署目标进行单独训练运行的需求。
要点总结
- 在战略性训练时刻间歇性激活更大的模型容量可以在降低计算成本的同时超越持续训练的性能
- 受神经科学启发的训练范式为传统统一训练方案提供了可行的替代方案,SEEKING动机状态提供了有用的概念框架
- 具有共享权重的可扩展架构能够高效地同时训练不同容量级别的模型
- 学习体验的质量和时机可能比处理的数据量更重要,动机模型在看到更少数据的情况下表现出卓越性能证明了这一点
- 该方法能够以低于独立训练任一模型的总训练成本生产两个针对不同资源约束优化的可部署模型