Paper: 2605.22818 Authors: Lee Hsin-Ying, Hanwen Jiang, Yiqun Mei, Jing Shi, Ming-Hsuan Yang, Zhixin Shu Categories: cs.CV
The Gap
Existing motion-controlled image-to-video models (DragNUWA, MotionCtrl, DragAnything) treat user trajectories as rigid constraints. You draw a path for a ball, the model moves the ball along that path. Problem: real physics doesn’t work this way. When a ball hits a cup, the cup should tip over. When wind blows leaves, nearby branches should sway. Current models miss these secondary causal consequences because they only execute the primary motion you specified, ignoring the chain reactions.
The gap: motion control is framed as trajectory following, not causal reasoning. Models lack a mechanism to ask “what else should move when this moves?”
Problem: User draws sparse trajectory
   |
   v
Assumption: Trajectories are causally incomplete
   |
   v
Method: VLM reasons about secondary effects + confidence-aware guidance
   |
   v
Evidence: MotiBench evaluation shows 23.4% preference gain
   |
   v
Conclusion: Reasoning before generation improves physical plausibility
The Increment
One sentence: Before MotiMotion, motion control meant “follow this path exactly”; after, it means “understand what should happen, then animate it.”
Core Mechanism
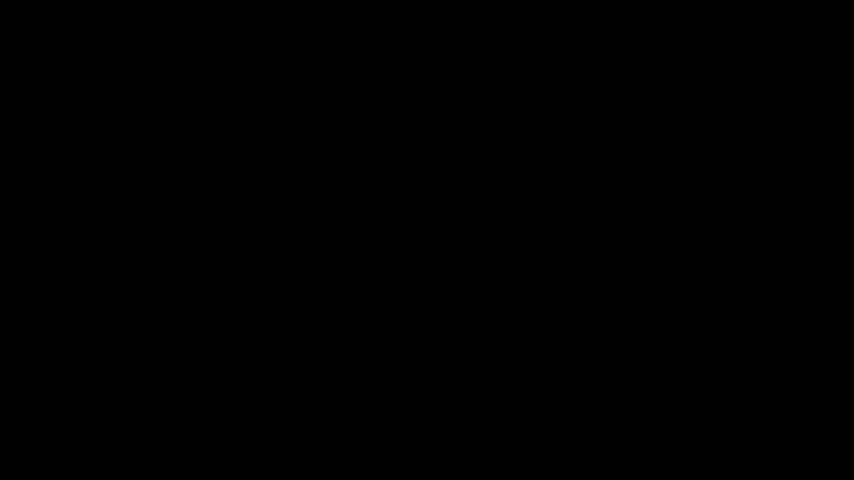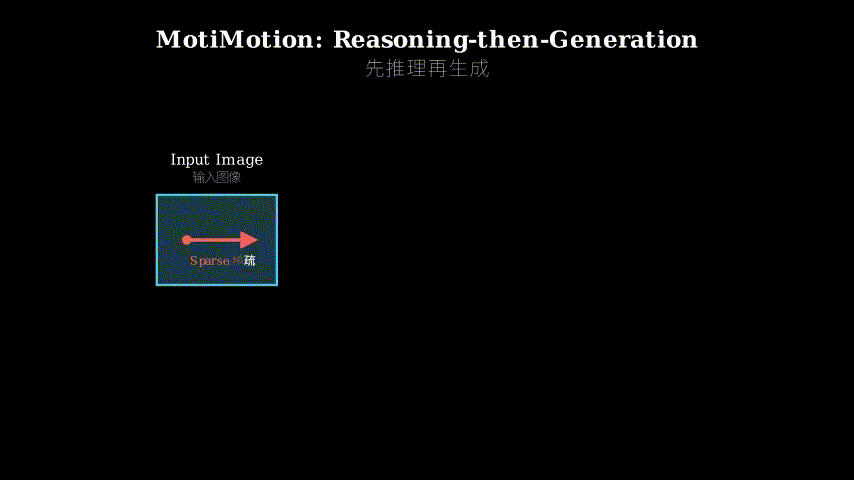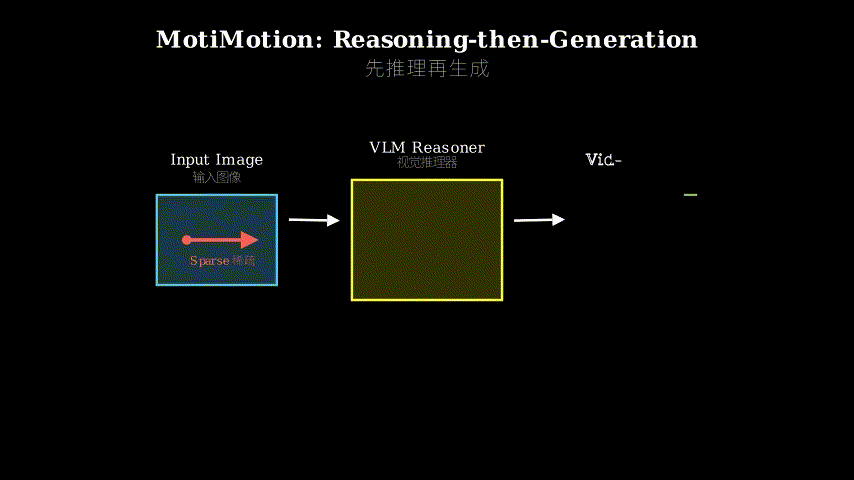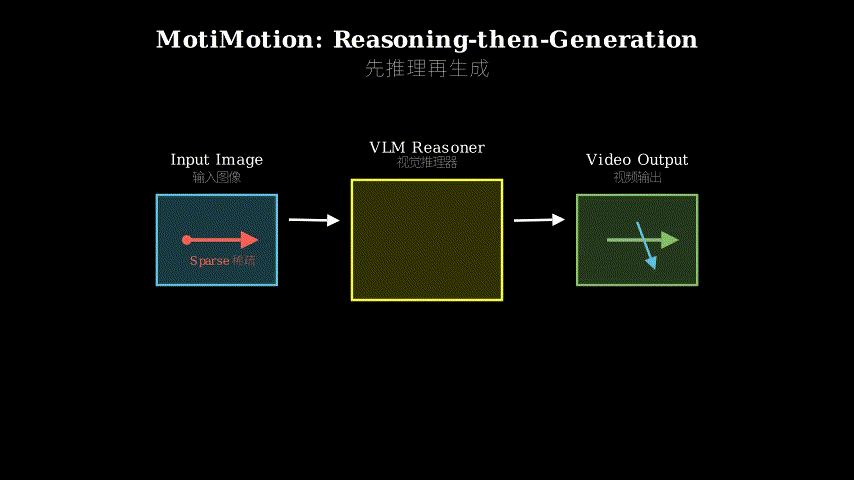
MotiMotion has three stages. First, a vision-language reasoner (GPT-4V) takes the input image and user-drawn trajectories, then outputs a refined motion plan. This plan includes corrected primary trajectories (fixing imprecise user input) and hallucinated secondary trajectories (objects that should move due to causal interaction). The reasoner also assigns confidence scores to each trajectory.
Second, a trajectory encoder converts these plans into dense motion guidance maps. Primary and secondary trajectories are rendered as Gaussian heatmaps, then encoded into latent features that condition the video diffusion model.
Third, during generation, a confidence-aware control module modulates guidance strength per trajectory. High-confidence trajectories (e.g., user-specified primary motion) get strong guidance. Low-confidence trajectories (e.g., hallucinated secondary effects that might be wrong) get weak guidance, allowing the model’s internal priors to correct implausible suggestions.
Input Image + User Trajectories
         |
         v
   [VLM Reasoner]
    /          \
   v            v
Primary       Secondary
(refined)   (hallucinated)
   |            |
   +-----+------+
         |
         v
  [Trajectory Encoder]
         |
         v
   Motion Guidance Maps
         |
         v
  [Diffusion Model]
    with confidence-aware
    guidance modulation
         |
         v
    Output Video
Think of it like a film director working with a storyboard artist. The user sketches rough motion (storyboard). The VLM is the experienced storyboard artist who says “if the character pushes this door, the door should swing open, and the light from outside should spill in” — filling in secondary actions. The confidence score is the artist’s certainty: “I’m 90% sure the door swings, but only 50% sure about the light.” During filming (generation), the director (diffusion model) follows high-confidence notes closely but improvises when the storyboard is uncertain, using their own sense of physics.
Key Concepts
-
Secondary causal motion: When you push a domino, it falls and hits the next domino. The first domino’s motion is primary (you caused it). The second domino’s motion is secondary (caused by the first). Current models only animate what you explicitly specify. MotiMotion uses a VLM to predict these knock-on effects by reasoning about physical causality and commonsense interactions. Example: dragging a tablecloth should make dishes on the table slide; the VLM hallucinates trajectories for the dishes even though you only drew a path for the cloth.
-
Confidence-aware guidance: Not all motion predictions are equally reliable. User-drawn trajectories are high-confidence (you meant to move that object). VLM-hallucinated secondary motions are lower-confidence (the VLM is guessing based on commonsense). Instead of treating all guidance equally, MotiMotion scales the control strength by confidence. High-confidence → strong guidance (model follows closely). Low-confidence → weak guidance (model can deviate if the suggestion looks wrong). This prevents the VLM’s mistakes from ruining the video while still benefiting from its correct predictions.
-
Training-free reasoning: The VLM reasoner (GPT-4V) is used zero-shot, without any fine-tuning on video data. The authors prompt it with the image, user trajectories, and a structured output format (JSON with trajectory coordinates and confidence scores). This is “training-free” because no gradients flow through the VLM; it’s just an inference-time plugin. Advantage: you can swap in better VLMs as they become available without retraining the video model.
Framework Shift
Before (mainstream approach):        After (this paper):

User Trajectory                      User Trajectory
      |                                    |
      v                                    v
  [Encoder]                            [VLM Reasoner]
      |                               /      |      \
      v                              v       v       v
[Video Diffusion]              Primary  Secondary  Confidence
      |                              \      |      /
      v                               v     v     v
  Output Video                    [Trajectory Encoder]
                                         |
  (Rigid following,                      v
   misses secondary                [Video Diffusion]
   effects)                          with adaptive
                                     guidance strength
                                         |
                                         v
                                    Output Video

                                  (Causal reasoning,
                                   plausible interactions)
From trajectory execution to causal reasoning, the core shift is treating motion control as a planning problem that requires world knowledge, not just path interpolation.
Expert Assessment
Problem choice: Real gap. Motion-controlled video generation has been stuck in “puppet mode” — you pull the strings, objects move, but nothing else reacts. This matters for any application where physical plausibility is important (simulation, animation, content creation). The problem sits at the intersection of video generation and embodied reasoning, which is timely given recent VLM advances.
Method maturity: Clever use of existing components. The VLM reasoning step is conceptually simple but effective. Confidence-aware guidance is a principled way to handle uncertain predictions without discarding them. However, the method inherits VLM limitations: if GPT-4V hallucinates wrong physics, the video will too. The paper doesn’t explore failure modes deeply (what happens when the VLM is confidently wrong?). Also, the trajectory encoding is standard Gaussian heatmaps — nothing novel there.
Experimental integrity: MotiBench is a solid contribution (100 interaction-centric scenes, human-annotated). Baselines are fair (DragNUWA, MotionCtrl, DragAnything). Human study shows 23.4% preference gain, which is substantial. VLM-based evaluation (GPT-4V as judge) aligns with human preferences, though using GPT-4V to evaluate GPT-4V-generated plans is slightly circular. Ablations are thorough (removing secondary motion, removing confidence modulation both hurt performance). One weakness: no quantitative physics metrics (e.g., does the predicted secondary motion match actual physics simulations?). The evaluation is mostly perceptual.
Writing quality: Clear and well-structured. The motivation is compelling (Figure 1 shows failure cases of existing methods). The method section could be tighter — the confidence-aware guidance formulation (Eq. 3-4) is buried in implementation details when it’s a core contribution. The VLM prompting strategy is in the appendix; moving it to the main text would help reproducibility. The related work section is thorough but reads like a literature dump.
Verdict: weak accept — Solid idea with clear improvements over baselines, but the method is more “smart engineering” than fundamental innovation. The VLM reasoning step is the main novelty, and it’s essentially prompt engineering. Still, the problem is real, the solution works, and MotiBench will be useful for future work.
Takeaways
Confidence-weighted guidance: When combining multiple control signals (user input, model predictions, external priors), weight them by reliability rather than treating them equally. This pattern transfers beyond video generation — any conditional generation task with uncertain conditioning benefits from this.
Reasoning-then-generation decomposition: For tasks where the input is incomplete or ambiguous, insert a reasoning step (VLM, planner, simulator) before generation. The reasoner fills in missing details using world knowledge, then the generator executes the complete plan. This is more robust than end-to-end generation from incomplete input.
Training-free augmentation: You can improve a trained model by adding inference-time modules (VLM reasoner, confidence modulation) without retraining. This is practical when you can’t afford to retrain large models or when you want to quickly iterate on control mechanisms.
论文: 2605.22818 作者: Lee Hsin-Ying, Hanwen Jiang, Yiqun Mei, Jing Shi, Ming-Hsuan Yang, Zhixin Shu 分类: cs.CV
缺口
现有的运动控制图生视频模型(DragNUWA、MotionCtrl、DragAnything)把用户轨迹当作刚性约束。
你给球画一条路径,模型就让球沿着这条路径移动。
问题在于:真实物理不是这样运作的。
球撞到杯子,杯子应该翻倒。
风吹树叶,附近的树枝应该摇晃。
现有模型会漏掉这些次级因果后果,因为它们只执行你指定的主要运动,忽略了连锁反应。
缺口所在:运动控制被框定为轨迹跟随,而非因果推理。
模型缺少一个机制来问”当这个东西动的时候,还有什么应该跟着动?“
问题:用户画稀疏轨迹
   |
   v
假设:轨迹在因果上是不完整的
   |
   v
方法:VLM 推理次级效应 + 置信度感知引导
   |
   v
证据:MotiBench 评估显示 23.4% 偏好增益
   |
   v
结论:生成前推理提升物理合理性
增量
一句话: MotiMotion 之前,运动控制意味着”严格按这条路径走”;之后,它意味着”理解应该发生什么,然后动画化它”。
核心机制
MotiMotion 有三个阶段。
首先,视觉语言推理器(GPT-4V)接收输入图像和用户绘制的轨迹,然后输出精炼的运动计划。
这个计划包括修正后的主要轨迹(修复不精确的用户输入)和幻构的次级轨迹(因因果交互而应该移动的物体)。
推理器还为每条轨迹分配置信度分数。
其次,轨迹编码器将这些计划转换为密集的运动引导图。
主要和次级轨迹被渲染为高斯热图,然后编码为潜在特征,用于条件化视频扩散模型。
第三,在生成过程中,置信度感知控制模块按轨迹调节引导强度。
高置信度轨迹(例如用户指定的主要运动)获得强引导。
低置信度轨迹(例如可能错误的幻构次级效应)获得弱引导,允许模型的内部先验纠正不合理的建议。
输入图像 + 用户轨迹
         |
         v
   [VLM 推理器]
    /          \
   v            v
主要轨迹      次级轨迹
(精炼后)      (幻构的)
   |            |
   +-----+------+
         |
         v
  [轨迹编码器]
         |
         v
   运动引导图
         |
         v
  [扩散模型]
    带置信度感知
    引导调节
         |
         v
    输出视频
把它想象成电影导演和分镜师合作。
用户画粗略的运动(分镜草图)。
VLM 是经验丰富的分镜师,会说”如果角色推这扇门,门应该摆开,外面的光应该洒进来”——填充次级动作。
置信度分数是分镜师的确定性:“我 90% 确定门会摆动,但只有 50% 确定光线的事。”
拍摄时(生成),导演(扩散模型)紧密遵循高置信度的注释,但在分镜不确定时即兴发挥,使用自己的物理感。
关键概念
- 次级因果运动: 你推倒一块多米诺骨牌,它倒下并撞击下一块。
第一块骨牌的运动是主要的(你导致的)。
第二块骨牌的运动是次级的(由第一块导致)。
现有模型只动画化你明确指定的内容。
MotiMotion 使用 VLM 通过推理物理因果性和常识交互来预测这些连锁效应。
例子:拖动桌布应该让桌上的盘子滑动;VLM 为盘子幻构轨迹,即使你只为桌布画了路径。
- 置信度感知引导: 并非所有运动预测都同样可靠。
用户绘制的轨迹是高置信度的(你有意移动那个物体)。
VLM 幻构的次级运动是较低置信度的(VLM 基于常识在猜测)。
MotiMotion 不是平等对待所有引导,而是按置信度缩放控制强度。
高置信度 → 强引导(模型紧密跟随)。
低置信度 → 弱引导(如果建议看起来不对,模型可以偏离)。
这防止 VLM 的错误毁掉视频,同时仍能从其正确预测中受益。
- 免训练推理: VLM 推理器(GPT-4V)以零样本方式使用,无需在视频数据上微调。
作者用图像、用户轨迹和结构化输出格式(带轨迹坐标和置信度分数的 JSON)提示它。
这是”免训练”的,因为没有梯度流过 VLM;它只是推理时的插件。
优势:随着更好的 VLM 出现,你可以替换它们而无需重新训练视频模型。
框架转变
之前(主流方法):                之后(本文方法):

用户轨迹                          用户轨迹
      |                                |
      v                                v
  [编码器]                        [VLM 推理器]
      |                           /      |      \
      v                          v       v       v
[视频扩散]                    主要   次级   置信度
      |                          \      |      /
      v                           v     v     v
  输出视频                      [轨迹编码器]
                                     |
  (刚性跟随,                         v
   漏掉次级                      [视频扩散]
   效应)                          带自适应
                                 引导强度
                                     |
                                     v
                                 输出视频

                               (因果推理,
                                合理交互)
从轨迹执行到因果推理,核心转变是将运动控制视为需要世界知识的规划问题,而非仅仅路径插值。
专家评审
选题眼光: 真实缺口。
运动控制视频生成一直卡在”木偶模式”——你拉线,物体动,但其他东西不反应。
这对任何需要物理合理性的应用都重要(模拟、动画、内容创作)。
问题位于视频生成和具身推理的交叉点,考虑到最近 VLM 的进展,这很及时。
方法成熟度: 巧妙使用现有组件。
VLM 推理步骤概念简单但有效。
置信度感知引导是处理不确定预测的原则性方法,不会丢弃它们。
然而,方法继承了 VLM 的局限:如果 GPT-4V 幻构错误的物理,视频也会错。
论文没有深入探索失败模式(当 VLM 自信地错误时会发生什么?)。
此外,轨迹编码是标准的高斯热图——那里没有新意。
实验诚意: MotiBench 是扎实的贡献(100 个交互中心场景,人工标注)。
基线公平(DragNUWA、MotionCtrl、DragAnything)。
人类研究显示 23.4% 偏好增益,这是实质性的。
基于 VLM 的评估(GPT-4V 作为评判)与人类偏好一致,尽管使用 GPT-4V 评估 GPT-4V 生成的计划略显循环。
消融实验彻底(移除次级运动、移除置信度调节都损害性能)。
一个弱点:没有定量物理指标(例如,预测的次级运动是否匹配实际物理模拟?)。
评估主要是感知性的。
写作功力: 清晰且结构良好。
动机令人信服(图 1 展示了现有方法的失败案例)。
方法部分可以更紧凑——置信度感知引导公式(方程 3-4)埋在实现细节中,而它是核心贡献。
VLM 提示策略在附录中;将其移到正文会有助于可复现性。
相关工作部分彻底但读起来像文献堆砌。
判决: 弱接收 — 扎实的想法,相比基线有明确改进,但方法更多是”聪明工程”而非根本创新。
VLM 推理步骤是主要新颖性,本质上是提示工程。
尽管如此,问题是真实的,解决方案有效,MotiBench 对未来工作会有用。
要点总结
置信度加权引导: 当组合多个控制信号(用户输入、模型预测、外部先验)时,按可靠性加权它们,而非平等对待。
这个模式超越视频生成——任何带不确定条件的条件生成任务都能从中受益。
推理-然后-生成分解: 对于输入不完整或模糊的任务,在生成前插入推理步骤(VLM、规划器、模拟器)。
推理器使用世界知识填充缺失细节,然后生成器执行完整计划。
这比从不完整输入端到端生成更鲁棒。
免训练增强: 你可以通过添加推理时模块(VLM 推理器、置信度调节)改进训练好的模型,无需重新训练。
当你无法承担重新训练大模型的成本,或想快速迭代控制机制时,这很实用。