Paper: 2605.22794 Authors: Qianshu Cai, Yonggang Zhang, Xianzhang Jia, Wei Xue, Jun Song, Xinmei Tian, Yike Guo Categories: cs.AI, cs.LG
The Gap
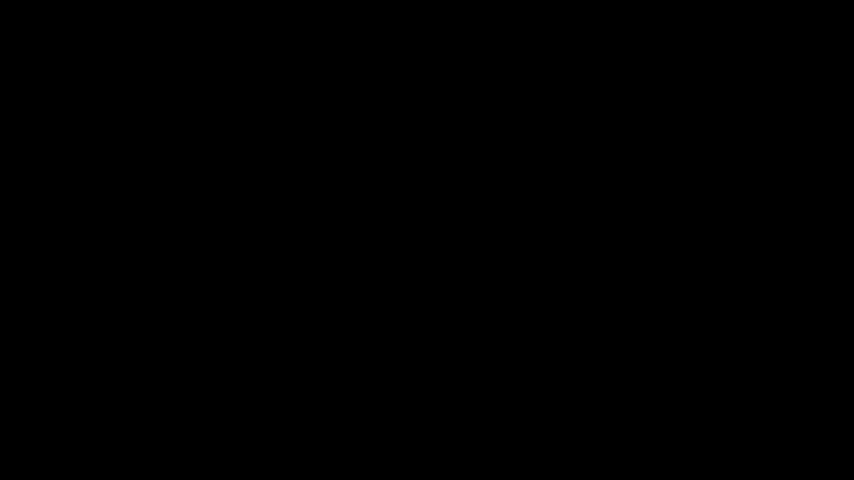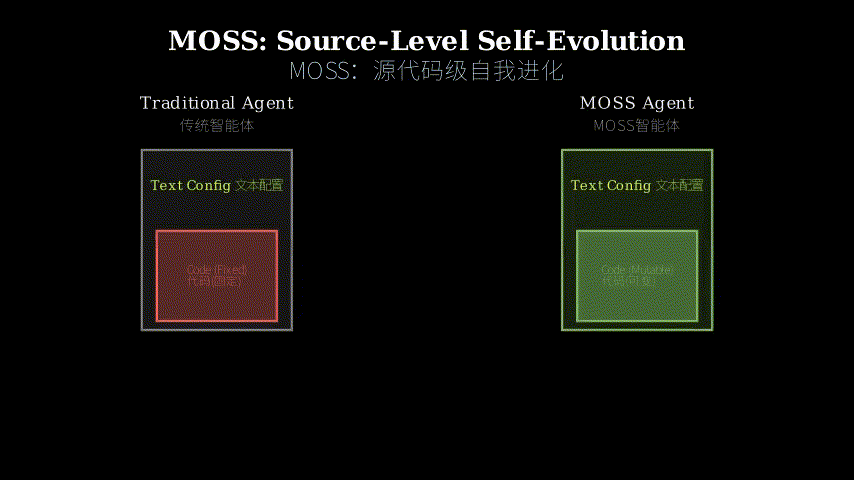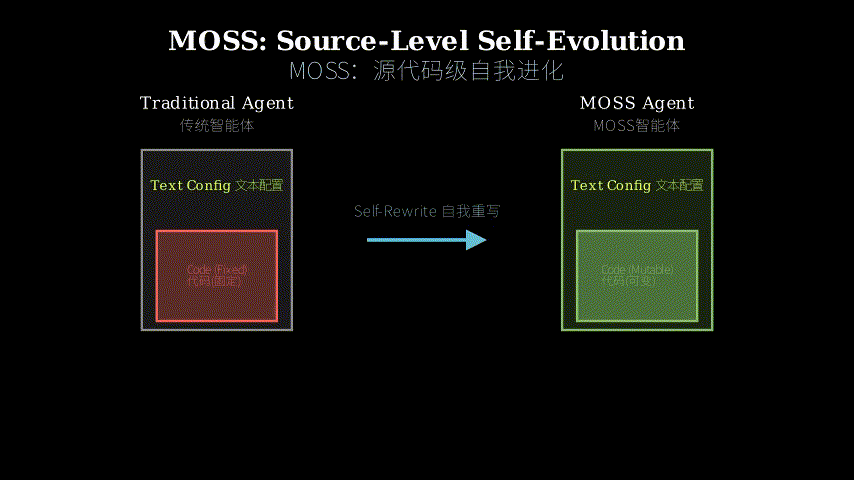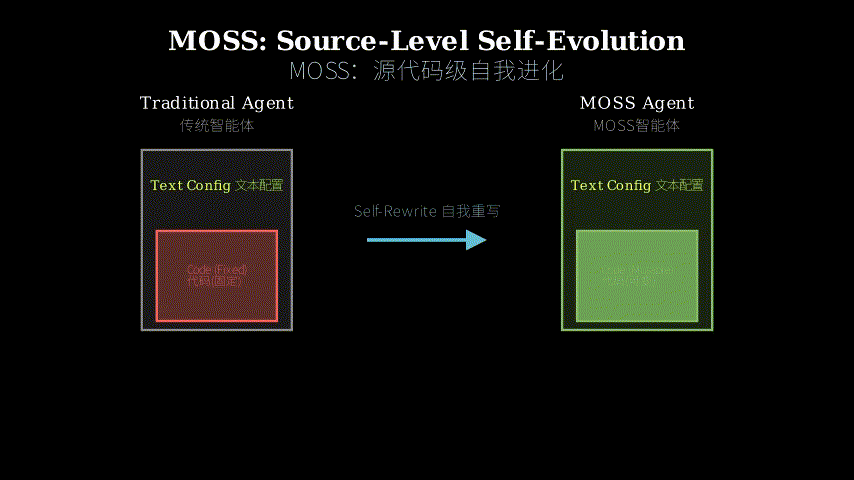
Existing self-evolving agents (Voyager, AutoGPT, LATS) only mutate text artifacts: prompt templates, skill libraries, memory schemas, workflow configurations. The agent harness itself—routing logic, hook ordering, state invariants, dispatch mechanisms—lives in code and remains frozen after deployment. When a structural bug appears (wrong execution order, missing error handler, broken state transition), text-layer evolution cannot reach it. The agent keeps failing on the same edge case until a human ships a code patch.
Problem: Structural failures unreachable from text layer
   |
   v
Assumption: Source code is a strictly more general mutation surface
   |
   v
Method: Multi-stage pipeline with code rewriting + replay verification
   |
   v
Evidence: 0.25 -> 0.61 score on OpenClaw (4 tasks, 1 cycle)
   |
   v
Conclusion: Source-level evolution subsumes text-level evolution
The Increment
One sentence: Before MOSS, agents could only tune their prompts and skills; after MOSS, they can rewrite their own execution engine.
Core Mechanism
MOSS operates as a deterministic pipeline triggered by production failures. First, it curates a batch of failure traces—user interactions where the agent crashed, timed out, or produced wrong outputs. Second, it delegates code modification to an external coding-agent CLI (pluggable, could be GPT-4 or Claude with agentic scaffolding). Third, it spins up ephemeral trial workers, replays the failure batch against the candidate code, and collects verdicts. Fourth, if the candidate passes replay verification, MOSS performs an in-place container swap with health-probe-gated rollback: the new code goes live, but if health checks fail within a grace period, the system reverts atomically.
Production Agent (running)
   |
   | (failures accumulate)
   v
Failure Batch Curator
   |
   v
External Coding Agent CLI  <--- pluggable (GPT-4, Claude, etc.)
   |
   | (generates candidate code)
   v
Ephemeral Trial Workers
   |
   | (replay batch against candidate)
   v
Verdict: pass/fail
   |
   +---> [fail] discard candidate
   |
   +---> [pass] In-Place Container Swap
              |
              +---> Health Probe (grace period)
                    |
                    +---> [fail] Rollback
                    |
                    +---> [pass] Promote to production
Think of MOSS as a surgical team operating on a living patient. The patient (production agent) keeps running while the team works. The diagnostician (failure curator) collects symptoms from recent cases. The surgeon (external coding agent) proposes an intervention—not a bandage on the skin (prompt tweak), but a structural repair (code change). Before touching the real patient, the team runs the procedure on cadavers (ephemeral trial workers replaying failure traces). Only if the cadaver trials succeed does the surgeon operate on the live patient, with a crash cart standing by (health probes + rollback). The key insight: you can’t fix a broken heart valve by changing the patient’s diet; you need to open the chest.
Key Concepts
-
Source-level vs text-level mutation: Text-level evolution changes data consumed by code (prompts, skill files, configs). Source-level evolution changes the code itself—control flow, function signatures, class hierarchies. Text-level is a strict subset: any text artifact can be generated by code, but code can express logic (loops, conditionals, recursion) that no text artifact can. When the bug is “the agent retries failed API calls in the wrong order,” no amount of prompt engineering fixes it; you need to reorder the retry loop in code.
-
Replay verification: After generating candidate code, MOSS doesn’t deploy it blindly. It replays the curated failure batch—actual user interactions that crashed the old agent—against the candidate in isolated trial workers. If the candidate still fails on the same inputs, it’s discarded. This is deterministic: unlike prompt-based evolution where the base model might ignore your new instruction, code either passes the test suite or it doesn’t. Replay verification is the forcing function that prevents MOSS from shipping regressions.
-
In-place container swap with rollback: MOSS doesn’t spin up a new agent instance and redirect traffic. It swaps the code inside the running container, preserving process state and network connections. After the swap, health probes (lightweight checks: “can the agent still respond to ping?”) run continuously for a grace period. If any probe fails, MOSS atomically reverts to the old code. This makes evolution low-latency (no cold start) and low-risk (automatic undo on breakage).
Framework Shift
Before (text-layer evolution):        After (MOSS, source-layer evolution):

  Agent Harness (frozen code)           Agent Harness (mutable code)
        |                                      |
        v                                      v
  +-------------+                        +-------------+
  | Prompt      | <--- evolvable         | Prompt      | <--- evolvable
  | Skills      | <--- evolvable         | Skills      | <--- evolvable
  | Memory      | <--- evolvable         | Memory      | <--- evolvable
  | Workflow    | <--- evolvable         | Workflow    | <--- evolvable
  +-------------+                        | Routing     | <--- NEW: evolvable
                                         | Hooks       | <--- NEW: evolvable
  Structural bugs unreachable           | Dispatch    | <--- NEW: evolvable
                                         +-------------+

                                         Structural bugs now reachable
From data-plane tuning to control-plane rewriting, the core shift is making the execution substrate itself a first-class evolvable artifact.
Expert Assessment
Problem choice: Real gap. Deployed agents do fail structurally (wrong hook order, missing error paths), and text-layer evolution genuinely cannot reach those bugs. The authors correctly identify that code is Turing-complete while text artifacts are not. This isn’t a manufactured problem—it’s a natural next step after text-layer self-evolution hit its ceiling.
Method maturity: The pipeline is straightforward: curate failures, delegate to coding agent, replay, swap. The clever part is recognizing that you don’t need to invent a new code-rewriting algorithm—you can plug in any existing coding agent (GPT-4, Claude, Codex) and let MOSS handle orchestration. The weakness: MOSS inherits the coding agent’s brittleness. If the external agent generates subtly broken code that passes replay but fails on unseen inputs, MOSS promotes it. The paper doesn’t address how to build a richer test suite beyond replaying known failures.
Experimental integrity: Single benchmark (OpenClaw, 4 tasks), single evolution cycle, score goes from 0.25 to 0.61. That’s a 2.4× improvement, which is substantial, but the paper doesn’t show what happens in cycle 2, 3, or 10. Does performance plateau? Does the agent start rewriting itself into a corner? No ablation on which components matter (is replay verification essential, or does the coding agent alone do most of the work?). No comparison to a human fixing the same failures. The result is promising but thin—this feels like a proof-of-concept, not a mature system.
Writing quality: The abstract and introduction are sharp. The related work section is thorough. The method description is clear but lacks depth on failure modes: what happens when the coding agent generates code that compiles but has a logic bug? What happens when replay verification passes but the agent regresses on a different task? The evaluation section is the weakest—one benchmark, one cycle, no error analysis. Rewriting the evaluation to include multi-cycle runs, ablations, and failure case studies would elevate this from “interesting idea” to “credible system.”
Verdict: weak accept — The core insight (source-level evolution subsumes text-level evolution) is correct and underexplored. The system design is pragmatic. But the evaluation is too narrow to judge whether this scales beyond a single benchmark and a single evolution cycle. This paper opens a door; it doesn’t walk through it.
Takeaways
For practitioners building agentic systems: If your agent has recurring structural failures (wrong execution order, missing error handlers, broken state transitions), text-layer tuning won’t fix them. You need a mechanism to mutate the harness itself. MOSS shows that you can do this safely by (1) curating failure batches from production, (2) delegating code rewriting to an external agent, (3) replaying failures in ephemeral workers before promoting. The key transferable idea: treat your agent’s source code as just another evolvable artifact, but gate promotion with deterministic verification.
For researchers: The paper demonstrates that source-level evolution is feasible but leaves open questions about long-term stability. After N cycles of self-rewriting, does the codebase become unmaintainable? Do agents converge to local optima where further evolution degrades performance? A follow-up study tracking 10+ evolution cycles, measuring code complexity over time, and comparing to human-driven fixes would be valuable.
Concrete technique to steal: The replay verification pattern—curate a batch of failure cases, generate a candidate fix, replay the batch in isolation, promote only if all replays pass. This applies beyond agent evolution: you can use it for automated bug fixing, configuration tuning, or any system where you want to validate a change against known failure modes before deploying.
论文: 2605.22794 作者: Qianshu Cai, Yonggang Zhang, Xianzhang Jia, Wei Xue, Jun Song, Xinmei Tian, Yike Guo 分类: cs.AI, cs.LG
缺口
现有的自进化智能体(Voyager、AutoGPT、LATS)只能改变文本制品:提示词模板、技能库、记忆模式、工作流配置。
智能体的执行框架本身——路由逻辑、钩子顺序、状态不变量、调度机制——都活在代码里,部署后就冻结了。
当结构性 bug 出现时(执行顺序错误、缺少错误处理器、状态转换断裂),文本层进化根本够不着。
智能体会在同一个边界情况上反复失败,直到人类发布代码补丁。
问题:文本层无法触及结构性故障
   |
   v
假设:源代码是严格更通用的变异表面
   |
   v
方法:多阶段流水线 + 代码重写 + 回放验证
   |
   v
证据:OpenClaw 上从 0.25 升至 0.61(4 任务,1 轮)
   |
   v
结论:源码级进化包含文本级进化
增量
一句话: MOSS 之前,智能体只能调提示词和技能;MOSS 之后,它们能改写自己的执行引擎。
核心机制
MOSS 是一条由生产故障触发的确定性流水线。
首先,它整理一批故障轨迹——智能体崩溃、超时或输出错误的用户交互。
其次,它把代码修改委托给外部编码智能体 CLI(可插拔,可以是 GPT-4 或 Claude 加上智能体脚手架)。
第三,它启动临时试验 worker,对候选代码回放故障批次,收集判决。
第四,如果候选通过回放验证,MOSS 执行原地容器交换,带健康探针保护的回滚:新代码上线,但如果宽限期内健康检查失败,系统原子性回退。
生产智能体(运行中)
   |
   | (故障累积)
   v
故障批次整理器
   |
   v
外部编码智能体 CLI  <--- 可插拔(GPT-4、Claude 等)
   |
   | (生成候选代码)
   v
临时试验 Worker
   |
   | (对候选回放批次)
   v
判决:通过/失败
   |
   +---> [失败] 丢弃候选
   |
   +---> [通过] 原地容器交换
              |
              +---> 健康探针(宽限期)
                    |
                    +---> [失败] 回滚
                    |
                    +---> [通过] 提升至生产
把 MOSS 想象成给活人做手术的外科团队。
病人(生产智能体)在团队工作时继续运转。
诊断师(故障整理器)从近期病例收集症状。
外科医生(外部编码智能体)提出干预方案——不是在皮肤上贴创可贴(调提示词),而是结构性修复(改代码)。
在碰真病人之前,团队在尸体上演练手术(临时试验 worker 回放故障轨迹)。
只有尸体试验成功,外科医生才给活人动刀,旁边还站着急救车(健康探针 + 回滚)。
核心洞见:你没法通过改病人饮食来修复破损的心脏瓣膜;你得打开胸腔。
关键概念
- 源码级 vs 文本级变异: 文本级进化改变代码消费的数据(提示词、技能文件、配置)。
源码级进化改变代码本身——控制流、函数签名、类层次。
文本级是严格子集:任何文本制品都能由代码生成,但代码能表达逻辑(循环、条件、递归),这是任何文本制品做不到的。
当 bug 是”智能体以错误顺序重试失败的 API 调用”时,再多提示词工程也修不好;你得在代码里重排重试循环。
- 回放验证: 生成候选代码后,MOSS 不会盲目部署。
它在隔离的试验 worker 里回放整理好的故障批次——让旧智能体崩溃的真实用户交互——对候选代码测试。
如果候选在相同输入上仍然失败,就丢弃。
这是确定性的:不像基于提示词的进化,基础模型可能忽略你的新指令,代码要么通过测试套件,要么不通过。
回放验证是阻止 MOSS 发布退化版本的强制函数。
- 带回滚的原地容器交换: MOSS 不会启动新智能体实例并重定向流量。
它在运行中的容器内交换代码,保留进程状态和网络连接。
交换后,健康探针(轻量检查:“智能体还能响应 ping 吗?“)在宽限期内持续运行。
如果任何探针失败,MOSS 原子性回退到旧代码。
这让进化低延迟(无冷启动)且低风险(故障自动撤销)。
框架转变
之前(文本层进化):                之后(MOSS,源码层进化):

  智能体框架(冻结代码)              智能体框架(可变代码)
        |                                      |
        v                                      v
  +-------------+                        +-------------+
  | 提示词      | <--- 可进化            | 提示词      | <--- 可进化
  | 技能        | <--- 可进化            | 技能        | <--- 可进化
  | 记忆        | <--- 可进化            | 记忆        | <--- 可进化
  | 工作流      | <--- 可进化            | 工作流      | <--- 可进化
  +-------------+                        | 路由        | <--- 新:可进化
                                         | 钩子        | <--- 新:可进化
  结构性 bug 无法触及                    | 调度        | <--- 新:可进化
                                         +-------------+

                                         结构性 bug 现在可触及
从数据平面调优到控制平面重写,核心转变是让执行基底本身成为一等可进化制品。
专家评审
选题眼光: 真缺口。
部署的智能体确实会结构性失败(钩子顺序错误、缺少错误路径),文本层进化真的够不着这些 bug。
作者正确识别出代码是图灵完备的,而文本制品不是。
这不是人造问题——这是文本层自进化碰到天花板后的自然下一步。
方法成熟度: 流水线很直接:整理故障、委托给编码智能体、回放、交换。
巧妙之处在于认识到你不需要发明新的代码重写算法——你可以插入任何现有编码智能体(GPT-4、Claude、Codex),让 MOSS 处理编排。
弱点:MOSS 继承了编码智能体的脆弱性。
如果外部智能体生成微妙破损的代码,通过了回放但在未见输入上失败,MOSS 会提升它。
论文没有解决如何构建比回放已知故障更丰富的测试套件。
实验诚意: 单一基准(OpenClaw,4 任务),单轮进化,分数从 0.25 升至 0.61。
这是 2.4 倍提升,相当可观,但论文没展示第 2、3 或 10 轮会发生什么。
性能会平台期吗?智能体会开始把自己重写进死胡同吗?没有消融实验说明哪些组件重要(回放验证是必需的,还是编码智能体单独就能完成大部分工作?)。
没有与人类修复相同故障的对比。
结果有希望但单薄——这感觉像概念验证,不是成熟系统。
写作功力: 摘要和引言犀利。
相关工作部分详尽。
方法描述清晰但缺乏故障模式的深度:当编码智能体生成能编译但有逻辑 bug 的代码时会怎样?当回放验证通过但智能体在不同任务上退化时会怎样?评估部分最弱——一个基准、一轮、没有错误分析。
重写评估部分,加入多轮运行、消融实验和失败案例研究,能把这篇从”有趣想法”提升到”可信系统”。
判决: 弱接收 — 核心洞见(源码级进化包含文本级进化)正确且探索不足。
系统设计务实。
但评估太窄,无法判断这能否扩展到单一基准和单轮进化之外。
这篇论文打开了一扇门;它没有走进去。
要点总结
对构建智能体系统的实践者: 如果你的智能体有反复出现的结构性故障(执行顺序错误、缺少错误处理器、状态转换断裂),文本层调优修不好。
你需要一个机制来改变框架本身。
MOSS 展示了你可以通过以下方式安全做到这点:(1)从生产整理故障批次,(2)把代码重写委托给外部智能体,(3)在提升前在临时 worker 里回放故障。
关键可迁移想法:把智能体的源代码当作另一个可进化制品,但用确定性验证把关提升。
对研究者: 论文证明源码级进化可行,但留下了关于长期稳定性的开放问题。
经过 N 轮自我重写后,代码库会变得无法维护吗?智能体会收敛到局部最优,进一步进化反而降低性能吗?跟踪 10+ 轮进化、测量代码复杂度随时间变化、与人类驱动的修复对比的后续研究会很有价值。
可偷的具体技术: 回放验证模式——整理一批故障案例,生成候选修复,在隔离环境回放批次,只有所有回放通过才提升。
这超越智能体进化:你可以用它做自动化 bug 修复、配置调优,或任何你想在部署前对已知故障模式验证变更的系统。