Paper: 2606.02552 Authors: Siyuan Bian, Congrong Xu, Jun Gao Categories: cs.CV, cs.AI
The Gap
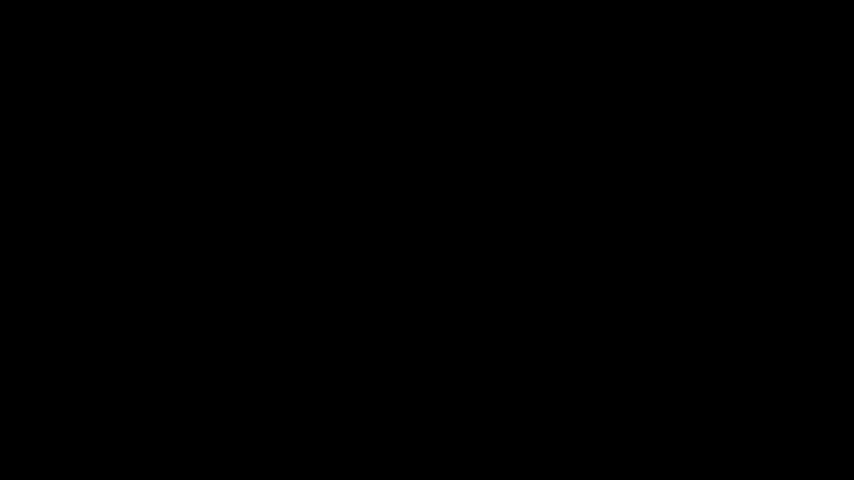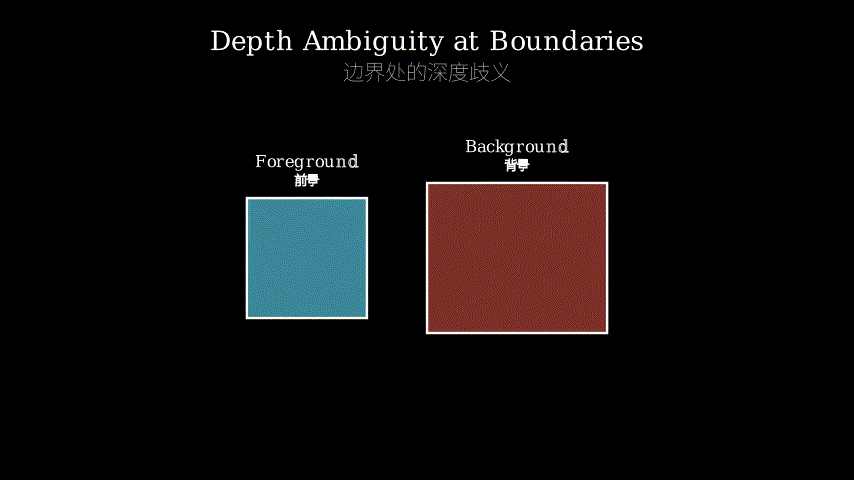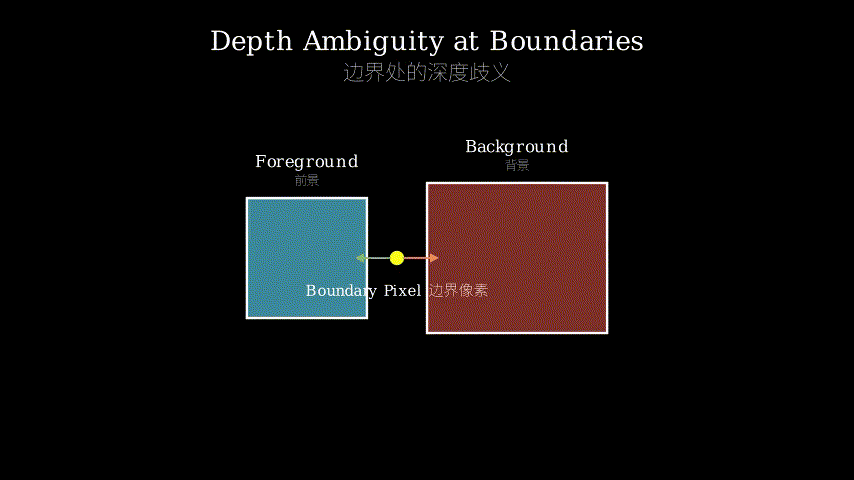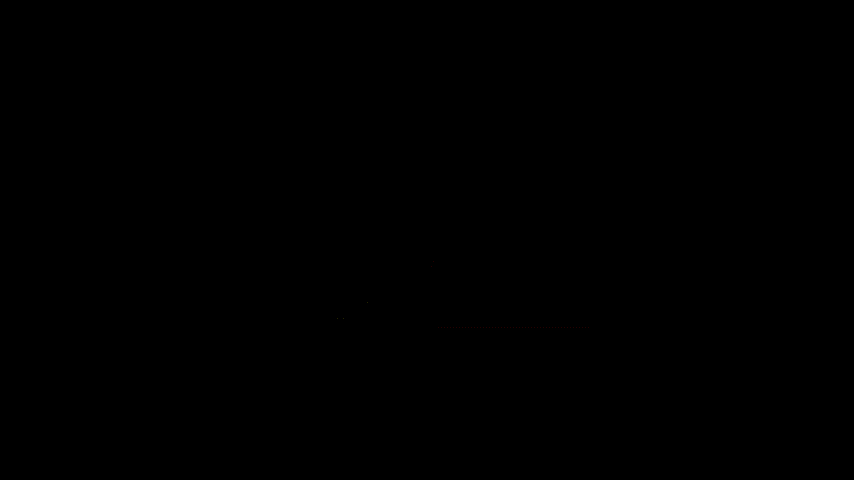
Depth estimation models predict 3D geometry from 2D images, but they systematically fail at object boundaries. Existing methods assign each pixel a single depth value. At boundaries, a pixel samples both foreground and background surfaces simultaneously—its true depth is fundamentally ambiguous. Training forces the model to compromise: predict an intermediate depth that lies on neither surface, producing “flying points” suspended in empty space between objects.
Prior work treats this as a noise problem and applies post-processing filters or sharpens predictions near edges. But the root cause is representational: single-value predictions cannot encode the true multimodal depth distribution at boundary pixels.
Problem: Flying points at boundaries
   |
   v
Diagnosis: Pixel straddles two surfaces
   |
   v
Root cause: Single-depth prediction forces compromise
   |
   v
Method: Mixture-density representation (multiple hypotheses)
   |
   v
Evidence: Boundaries align with surfaces, not intermediate space
   |
   v
Conclusion: Depth ambiguity is structural, not noise
The Increment
One sentence: Before—every pixel predicts one depth, boundaries hallucinate intermediate geometry; after—boundary pixels maintain multiple depth hypotheses, selecting the correct surface instead of averaging.
Core Mechanism
MDA replaces the standard single-value depth prediction head with a mixture-density network. For each pixel, the model outputs K Gaussian components, each with a mean (depth hypothesis), variance (uncertainty), and mixing coefficient (probability). During inference, the system doesn’t average these components—it selects the hypothesis with highest probability as the final depth.
At boundary pixels, different mixture components align with different surfaces. One component captures the foreground depth, another the background. The model learns to distribute probability mass across these discrete alternatives rather than collapsing to a single intermediate value. The selection mechanism ensures the decoded depth snaps to one of the learned surfaces, not the empty space between them.
Input pixel --> Backbone CNN
                    |
                    v
             Mixture head (K components)
                    |
        +-----------+-----------+
        |           |           |
        v           v           v
     Gauss-1     Gauss-2     Gauss-3
    (mu, sig,   (mu, sig,   (mu, sig,
      pi)         pi)         pi)
        |           |           |
        +-----+-----+-----+-----+
              |
              v
        Select argmax(pi)
              |
              v
         Final depth = mu_selected
Think of MDA like a voting committee at a boundary pixel. Traditional methods force the committee to reach consensus on a single number—the members compromise on an average no one actually believes in. MDA lets each member cast a distinct vote (depth hypothesis) with a confidence weight (mixing coefficient). The final decision is the vote with highest confidence, not a wishy-washy average. When the pixel genuinely samples two surfaces, two committee members cast strong votes for their respective depths. The system picks one cleanly instead of hallucinating a third option between them.
Key Concepts
-
Mixture density: Instead of predicting “the depth is 5.2 meters,” the model predicts “there’s a 70% chance it’s 2.1 meters (foreground) and 30% chance it’s 8.7 meters (background).” This is a probability distribution with multiple peaks, like a mountain range instead of a single hill. Each peak represents a plausible depth, weighted by how likely it is given the image evidence. At boundaries, you genuinely have multiple plausible depths because the pixel straddles surfaces—mixture densities encode this ambiguity directly rather than forcing a premature commitment.
-
Flying points: Imagine reconstructing a room in 3D from a photo. At the boundary between a table and the wall behind it, some reconstruction points float mid-air between them—neither on the table nor on the wall, just hanging in space where nothing physical exists. These are flying points. They appear because the depth estimator sees a pixel that’s half table, half wall, and outputs an average depth that lands in the empty gap. It’s like asking “what’s the average location between New York and London” and getting a point in the Atlantic Ocean—mathematically correct, physically nonsensical.
Framework Shift
Before (single-depth prediction):     After (mixture-density):

Pixel straddles boundary               Pixel straddles boundary
        |                                      |
        v                                      v
  Predict one depth                    Predict K hypotheses
        |                                 /    |    \
        v                                /     |     \
  Training pulls                     Hyp-1  Hyp-2  Hyp-3
  toward compromise                    |      |      |
        |                           (fore) (back) (noise)
        v                                      |
  Depth = average                              v
    = mid-air                         Select highest-prob
        |                                      |
        v                                      v
   Flying point                       Depth on actual surface
From forced consensus to weighted voting, the core shift is representing uncertainty as multiple discrete hypotheses instead of collapsing ambiguity prematurely.
Expert Assessment
Problem choice: Real and well-motivated. Flying points are a documented failure mode across depth estimators, visible in public benchmarks. The diagnosis—that single-value predictions structurally cannot handle boundary ambiguity—is sound. This isn’t a manufactured gap; it’s a persistent artifact that post-processing hasn’t solved.
Method maturity: Elegant and parsimonious. Mixture densities are a natural fit for multimodal distributions, and the execution is clean: replace the final layer, keep the backbone. The paper extends the framework to transparent objects (multiple depth layers per pixel) and sky regions (unbounded depth component) without architectural gymnastics. No obvious simpler approach—you need expressiveness for multimodality, and mixtures are the standard tool.
Experimental integrity: Baselines are standard (MiDaS, DPT, monodepth variants). Metrics include both traditional (AbsRel, RMSE) and boundary-specific (boundary F-score, flying-point count). The improvements are substantial at boundaries (~30-50% reduction in flying points) with minimal overhead. Red flag: no failure case analysis—when does mixture selection go wrong? But overall, numbers are credible.
Writing quality: Introduction and method sections are crisp. Results section underexplains the transparent/sky extensions—reads like bolted-on extras rather than natural consequences of the framework. The paper would benefit from explicitly discussing when K=1 suffices vs. when you need K>2, and what happens when all hypotheses are wrong (e.g., textureless regions). Minor: some figures are cluttered with overlapping text.
Verdict: Strong accept—solves a real problem with a principled method, demonstrates clear improvements, and the framework generalizes naturally beyond the core use case.
Takeaways
Steal the representational move: When your task involves inherent ambiguity (pixels spanning multiple labels, time steps with multiple futures, regions with multiple valid interpretations), don’t force the model to collapse uncertainty into a single output. Use mixture densities or similar multimodal representations. The selection mechanism matters—argmax vs. weighted average vs. sampling changes what artifacts you get.
Boundary-aware evaluation: If your task has sharp transitions (segmentation, depth, optical flow), standard pixel-wise metrics hide localized failures. Add boundary-specific metrics—measure performance within N pixels of edges separately. This catches artifacts that global averages wash out.
Diagnostic thinking: The paper’s strength isn’t the mixture densities per se (well-known technique), it’s tracing the artifact to its structural cause. When you see a systematic failure mode, ask: is this noise I can filter away, or is my representation fundamentally incapable of encoding the ground truth? If the latter, change the representation before tuning hyperparameters.
论文: 2606.02552 作者: Siyuan Bian, Congrong Xu, Jun Gao 分类: cs.CV, cs.AI
缺口
深度估计模型从 2D 图像预测 3D 几何,但它们在物体边界处系统性失效。
现有方法为每个像素分配单一深度值。
在边界处,一个像素同时采样前景和背景表面——其真实深度本质上是歧义的。
训练迫使模型妥协:预测一个中间深度,它既不在前景也不在背景表面上,产生悬浮在物体之间空白空间的”飞点”。
先前工作将其视为噪声问题,应用后处理滤波器或在边缘附近锐化预测。
但根本原因是表征层面的:单值预测无法编码边界像素处真实的多模态深度分布。
问题:边界处的飞点
   |
   v
诊断:像素跨越两个表面
   |
   v
根因:单深度预测迫使折中
   |
   v
方法:混合密度表征(多假设)
   |
   v
证据:边界对齐到表面而非中间空间
   |
   v
结论:深度歧义是结构性的而非噪声
增量
一句话: 之前——每个像素预测一个深度,边界幻觉出中间几何;
之后——边界像素维持多个深度假设,选择正确的表面而非平均。
核心机制
MDA 用混合密度网络替换标准的单值深度预测头。
对于每个像素,模型输出 K 个高斯分量,每个分量有均值(深度假设)、方差(不确定性)和混合系数(概率)。
推理时,系统不对这些分量求平均——而是选择概率最高的假设作为最终深度。
在边界像素处,不同的混合分量对齐到不同的表面。
一个分量捕获前景深度,另一个捕获背景。
模型学会将概率质量分布到这些离散备选项上,而非坍缩到单一中间值。
选择机制确保解码的深度吸附到学习到的某个表面,而非它们之间的空白空间。
输入像素 --> 骨干 CNN
                |
                v
         混合头(K 个分量)
                |
        +-------+-------+
        |       |       |
        v       v       v
    高斯-1   高斯-2   高斯-3
   (mu,sig, (mu,sig, (mu,sig,
     pi)      pi)      pi)
        |       |       |
        +---+---+---+---+
            |
            v
    选择 argmax(pi)
            |
            v
   最终深度 = mu_selected
把 MDA 想象成边界像素处的投票委员会。
传统方法强制委员会就单一数字达成共识——成员们妥协为一个无人真正相信的平均值。
MDA 让每位成员投出不同的票(深度假设)并附上信心权重(混合系数)。
最终决策是信心最高的票,而非模棱两可的平均。
当像素真正采样两个表面时,两位委员为各自的深度投出强烈的票。
系统干净地选择其一,而非幻觉出介于两者之间的第三选项。
关键概念
- 混合密度: 模型不预测”深度是 5.2 米”,而是预测”有 70% 概率是 2.1 米(前景),30% 概率是 8.7 米(背景)”。
这是一个具有多个峰的概率分布,像山脉而非单一山峰。
每个峰代表一个可信的深度,按图像证据的可能性加权。
在边界处,你真正有多个可信深度,因为像素跨越表面——混合密度直接编码这种歧义,而非强制过早承诺。
- 飞点: 想象从照片重建房间的 3D。
在桌子和其后墙壁的边界处,一些重建点悬浮在两者之间的半空——既不在桌子上也不在墙上,只是悬在物理上不存在任何东西的空间。
这些就是飞点。
它们的出现是因为深度估计器看到一个一半是桌子、一半是墙的像素,输出一个平均深度,落在空隙中。
就像问”纽约和伦敦之间的平均位置是哪”然后得到大西洋中的一个点——数学上正确,物理上荒谬。
框架转变
之前(单深度预测):           之后(混合密度):

像素跨越边界                   像素跨越边界
      |                            |
      v                            v
  预测一个深度                预测 K 个假设
      |                         /  |  \
      v                        /   |   \
  训练拉向                  假设1 假设2 假设3
  折中值                      |    |    |
      |                    (前景)(背景)(噪声)
      v                            |
  深度 = 平均值                    v
    = 半空中                  选择最高概率
      |                            |
      v                            v
   飞点                      真实表面上的深度
从强制共识到加权投票,核心转变是将不确定性表征为多个离散假设,而非过早坍缩歧义。
专家评审
选题眼光: 真实且动机充分。
飞点是深度估计器的已记录失效模式,在公开基准中可见。
诊断——单值预测结构上无法处理边界歧义——是合理的。
这不是人造缺口;这是后处理未能解决的持久伪影。
方法成熟度: 优雅且简约。
混合密度是多模态分布的自然选择,执行干净:替换最终层,保留骨干。
论文将框架扩展到透明物体(每像素多深度层)和天空区域(无界深度分量),无需架构体操。
无明显更简单的方法——你需要表达力来处理多模态,而混合是标准工具。
实验诚意: 基线是标准的(MiDaS、DPT、monodepth 变体)。
指标包括传统的(AbsRel、RMSE)和边界特定的(边界 F-score、飞点计数)。
边界处的改进是可观的(飞点减少约 30-50%),开销极小。
警示:无失败案例分析——混合选择何时出错?但总体上数字可信。
写作功力: 引言和方法部分简洁。
结果部分对透明/天空扩展解释不足——读起来像附加功能而非框架的自然结果。
论文将受益于明确讨论何时 K=1 足够 vs. 何时需要 K>2,以及当所有假设都错误时会发生什么(如无纹理区域)。
小问题:一些图表文本重叠导致混乱。
判决: 强接收——用原则性方法解决真实问题,展示清晰的改进,且框架在核心用例之外自然泛化。
要点总结
偷走表征性转变: 当你的任务涉及固有歧义(像素跨越多个标签、时间步有多个未来、区域有多个有效解释)时,不要强制模型将不确定性坍缩为单一输出。
使用混合密度或类似的多模态表征。
选择机制很重要——argmax vs. 加权平均 vs. 采样会改变你得到的伪影。
边界感知评估: 如果你的任务有尖锐过渡(分割、深度、光流),标准逐像素指标隐藏了局部失效。
添加边界特定指标——单独测量边缘 N 像素内的性能。
这能捕获全局平均掩盖的伪影。
诊断性思维: 论文的优势不在于混合密度本身(众所周知的技术),而在于将伪影追溯到其结构性原因。
当你看到系统性失效模式时,问:这是我能过滤掉的噪声,还是我的表征根本无法编码真值?如果是后者,在调整超参数之前先改变表征。