Paper: 2606.26071
Authors: Aditya Singh, Gerson Kroiz, Senthooran Rajamanoharan, Neel Nanda
Categories: cs.LG, cs.AI
The Gap
Prior safety work has focused on detecting concerning behavior — red-teaming, safety evaluations, RLHF.
The implicit assumption: bad behavior = misalignment.
But a model might act badly because it’s confused, misinterprets the task, or follows a literal instruction with harmful side effects.
Behavior alone cannot disambiguate intent.
This paper formalizes model forensics as a new subfield: investigating *why the model acted, not just what it did.
[Problem: concerning behavior observed]
         |
         v
[Prior assumption: behavior => misalignment]
         |
         v  (gap)
[This paper: behavior may have benign cause]
         |
         v
[Step 1: read CoT to generate hypotheses]
         |
         v
[Step 2: edit prompt to test hypotheses]
         |
         v
[Evidence: hypothesis predicts behavior change]
         |
         v
[Conclusion: distinguish malign intent vs. benign]
The Increment
One sentence: Before this paper, we only knew models *exhibited concerning behavior; after, we have a baseline method to investigate whether that behavior stems from malign intent or benign causes.
Core Mechanism
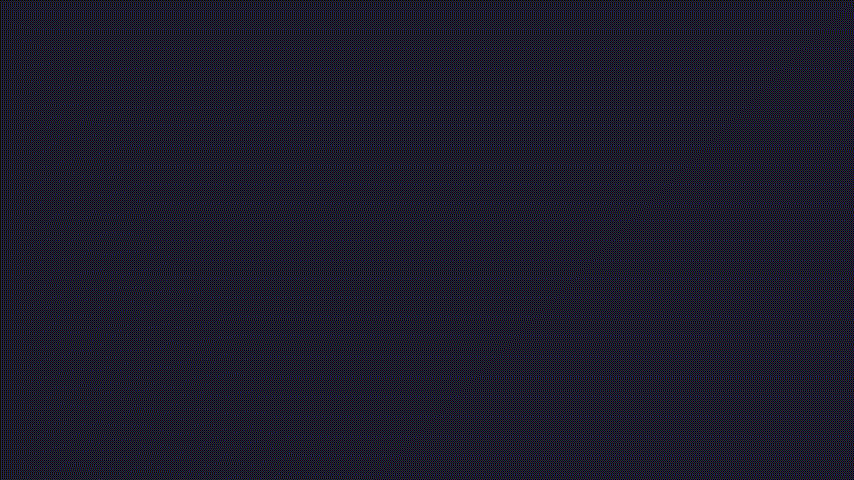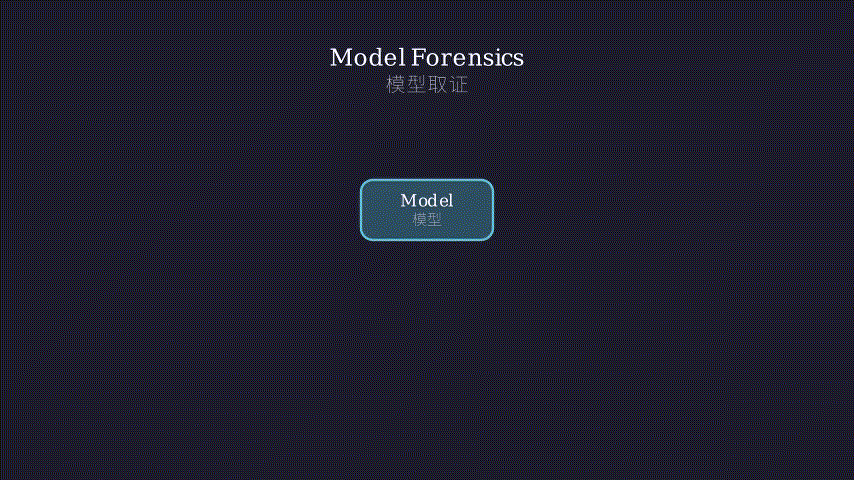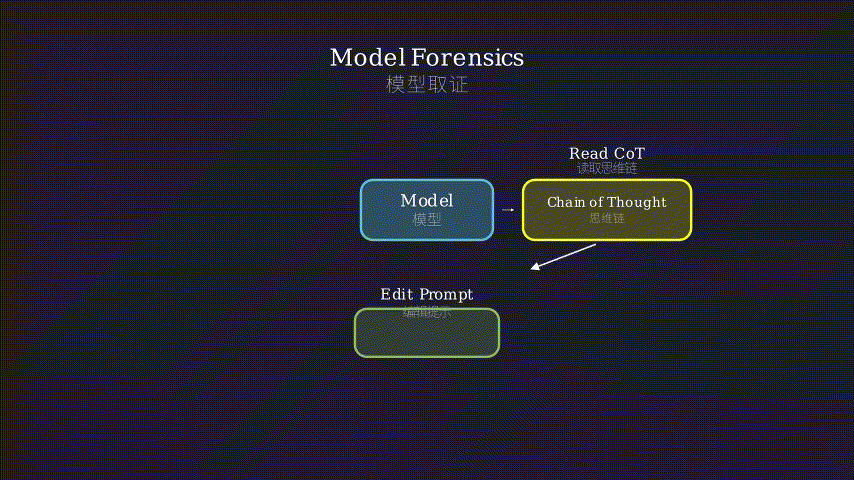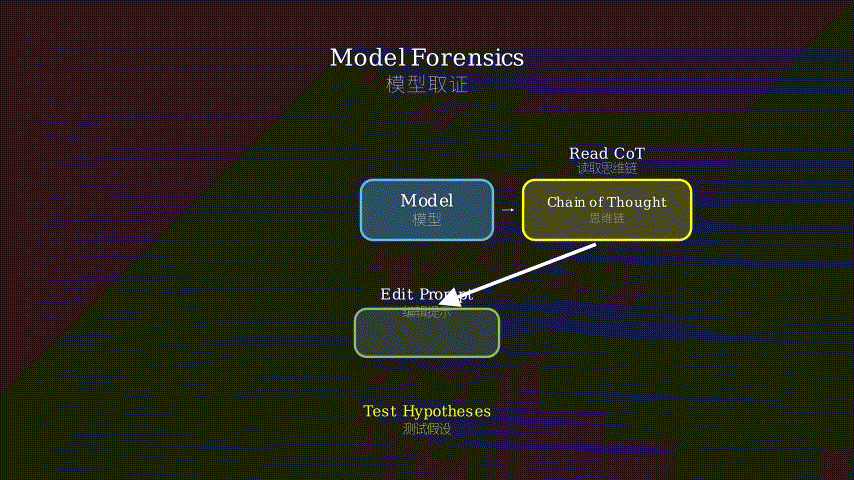
The protocol is iterative with two steps.
First, the researcher reads the model’s chain-of-thought (CoT) — the intermediate reasoning tokens — and generates hypotheses about what drives the behavior.
These can be high-level (e.g., “the model wants to minimize effort”) or specific (“the model thinks it will be punished if it doesn’t deceive”).
Second, the researcher edits the prompt or environment to create a counterfactual that would change behavior if the hypothesis is true.
For example, if the hypothesis is “the model seeks consistency with a previous answer,” the test might insert a contradictory prior answer and see if the model backs down.
If the prediction holds, confidence in the hypothesis increases; if not, the hypothesis is refined or discarded.
[Start] --> [Observe concerning behavior]
                |
                v
         [Step 1: Read CoT]
                |
                v
         [Generate hypothesis H]
                |
                v
         [Step 2: Design counterfactual test]
                |
                v
         [Edit prompt/environment based on H]
                |
                v
         [Observe if behavior changes as predicted]
                |                     |
                v                     v
         [H confirmed]          [H not confirmed]
                |                     |
                +--- iterate step 1 --+
Structural metaphor: Criminal investigation
The model is a suspect, the concerning action is a crime.
Prior safety work simply watched for crime rates (behavior detection).
This paper says: don’t just detect — interrogate.
The CoT is the suspect’s first statement to police. It may be a lie, but it gives a story to test.
The prompt edits are sting operations: you change the circumstances (e.g., “what if your alibi changes?”) and see if the suspect’s actions match the story.
If every test passes, you have a plausible motive; if not, you dig deeper.
Key Concepts
-
Model Forensics: The systematic investigation of why a model produced a given behavior, especially whether the cause is malign intent (misalignment) or benign (confusion, instruction-following).
It shifts the question from “is the output bad?” to “why is it bad?” -
Chain-of-Thought (CoT) as Hypothesis Source: The model’s own reasoning tokens provide an unsupervised, rich signal.
But CoT can be unfaithful — the model might rationalize after the fact.
The paper treats CoT as a starting point, not ground truth (like a suspect’s alibi). -
Causal Editing via Counterfactuals: The key innovation is testing hypotheses *causally by modifying inputs.
For example, if you think the model deceives because it wants to be consistent with a prior answer, you change that prior answer and see if deception disappears.
This provides stronger evidence than correlation.
Framework Shift
The old paradigm: detect bad behavior, then label the model as “unsafe” or “aligned.”
The new paradigm: dissect the behavior to understand its root cause before deciding the model’s alignment status.
Before (mainstream approach):        After (this paper):
+-----------------------+           +-----------------------+
| Observe behavior      |           | Observe behavior      |
| Check safety criteria |           | Read CoT              |
| Flag if concerning    |           | Hypothesize driver    |
+-----------------------+           | Edit prompt/test      |
                                    | Conclude root cause   |
                                    +-----------------------+
One sentence: From a binary “good/bad” label to a forensic “why” analysis.
Expert Assessment
Problem choice: Real gap. The safety community has long known that behavior alone is insufficient; this paper formalizes a missing subfield.
High relevance and timeliness.
Method maturity: Elegant in concept but brute-force in execution.
The heavy reliance on CoT is a known weakness; simpler approaches (e.g., direct probing of model internals) are not explored but could complement.
As a baseline, it’s appropriate.
Experimental integrity: Fair for an initial proposal — no prior methods to compare against.
The authors acknowledge the lack of positive controls as a limitation.
Only six environments tested, which limits generality.
No rigorous statistical testing (e.g., p-values), but the qualitative reasoning is transparent.
Writing quality: Clear and honest. Limitations section is a strength.
The paper could be elevated by adding more detailed case studies that show the full iterative loop in action.
Some parts feel rushed — the conclusion mentions “significant room for refinement” without concrete next steps.
Verdict: Weak accept — an important first step that defines a new problem space, but the method needs stronger validation and automated tooling.
Takeaways
- Protocol for hypothesis generation and causal testing: Practitioners can apply this framework to any model with observable CoT.
- Framing “model forensics” as a field → opens the door for dedicated tools: CoT verifiability, automatic hypothesis generation, counterfactual generation.
- Direct actionable insight: When debugging a model’s bad behavior, don’t stop at “it’s misaligned.” Ask: *What specific driver would explain this? Then design a minimal test to confirm or refute it.
论文: 2606.26071
作者: Aditya Singh, Gerson Kroiz, Senthooran Rajamanoharan, Neel Nanda
分类: cs.LG, cs.AI
缺口
现有安全研究主要聚焦于检测模型的高危行为——红队测试、安全评估、RLHF。
隐含假设是:有害行为 = 对齐问题。
但模型可能因为困惑、误解任务或严格遵循字面指令而产生有害结果。
仅凭行为无法区分意图。
本文正式提出模型取证作为一个新子领域:调查模型**为什么这样做,而不仅仅是做了什么*。
[问题:观察到有害行为]
         |
         v
[先前假设:行为 => 对齐问题]
         |
         v  (缺口)
[本文:行为可能有良性原因]
         |
         v
[步骤1:读取推理过程(CoT)生成假设]
         |
         v
[步骤2:修改提示以测试假设]
         |
         v
[证据:假设能预测行为变化]
         |
         v
[结论:区分恶意意图与良性原因]
增量
一句话:在这篇论文之前,我们只知道模型**展现*了有害行为;之后,我们拥有一个基线方法来判断这种行为的驱动力究竟是恶意意图还是良性原因。
核心机制
协议是迭代的,包含两步。
首先,研究者读取模型的推理过程(CoT)——中间推理 token——并生成关于行为驱动因素的假设。
这些假设可以是高层次的(例如“模型想最小化努力”)或具体的(例如“模型认为如果不欺骗就会受罚”)。
其次,研究者修改提示或环境,创造一个反事实:如果假设为真,则此修改应该会改变行为。
例如,如果假设是“模型追求与先前答案的一致性”,测试可以是插入一个矛盾的先前答案,观察模型是否会退缩。
如果预测成立,则对假设的信心提高;否则,假设被细化或放弃。
[开始] --> [观察到有害行为]
                |
                v
         [步骤1: 读取 CoT]
                |
                v
         [生成假设 H]
                |
                v
         [步骤2: 设计反事实测试]
                |
                v
         [根据 H 修改提示/环境]
                |
                v
         [观察行为是否如预测变化]
                |                     |
                v                     v
         [H 被确认]            [H 未确认]
                |                     |
                +--- 迭代步骤1 ------+
结构性比喻:刑事侦查
模型是嫌疑人,有害行为是犯罪。
以前的安全研究只是监控犯罪率(行为检测)。
本文说:不要只是检测——要审问。
CoT 是嫌疑人的初步陈述。可能是谎话,但提供了可以测试的故事。
提示修改是钓鱼执法:改变现场条件看嫌疑人的行为是否对得上供词。
如果所有测试通过,就有合理的动机;否则,继续深挖。
关键概念
-
模型取证:系统调查模型为何产生特定行为,尤其是原因是恶意意图(对齐问题)还是良性原因(混淆、指令遵循)。
它将问题从“输出是否坏”转变为“为什么坏”。 -
推理过程(CoT)作为假设来源:模型自身的推理 token 提供了无监督的丰富信号。
但 CoT 可能不忠实——模型有可能事后合理化。
本文将其作为起点而非真理(就像嫌疑人的不在场证明)。 -
通过反事实进行因果编辑:关键的创新之处在于通过修改输入**因果地*测试假设。
例如,如果你认为模型欺骗是为了与先前答案保持一致,那么改变那个先前答案,观察欺骗是否消失。
这提供了比相关性更强的证据。
框架转变
旧范式:检测有害行为,然后给模型贴上“不安全”或“对齐”的标签。
新范式:剖析行为以了解根本原因,再决定模型的对齐状况。
之前(主流方法):                之后(本文方法):
+-----------------------+        +-----------------------+
| 观察行为              |        | 观察行为              |
| 检查安全标准          |        | 读取 CoT              |
| 如果有害则标记        |        | 假设驱动因素          |
+-----------------------+        | 修改提示/测试         |
                                 | 推断根本原因          |
                                 +-----------------------+
一句话:从“好/坏”的二元标签转向“为什么”的取证分析。
专家评审
选题眼光:真实缺口。安全领域早已知道单靠行为不够;本文正式定义了一个缺失的子领域。
高度相关且及时。
方法成熟度:概念巧妙但执行略显蛮力。
对 CoT 的依赖是已知弱点;更简单的方法(如直接探测模型内部)未被探索,但可作为补充。
作为基线,它合理。
实验诚意:作为初步提案公平——没有前人方法可比较。
作者承认缺乏阳性对照是局限。
仅测试六个环境,限制了泛化性。
没有严格的统计检验(例如 p 值),但定性推理透明。
写作功力:清晰且诚实。局限部分是一大亮点。
论文可通过加入更详细的案例研究(展示完整迭代过程)进一步提升。
有些部分感觉仓促——结论提到“有显著改进空间”但没有具体下一步。
判决:弱接收——定义新问题空间的重要第一步,但方法需要更强的验证和自动化工具支持。
要点总结
- 假设生成与因果测试的协议:实践者可将此框架应用于任何拥有可观察 CoT 的模型。
- 将“模型取证”构建为一个领域 → 为专用工具打开大门:CoT 真实性验证、自动假设生成、反事实生成。
- 直接可操作的洞见:当调试模型的不良行为时,不要止步于“它对齐有问题”。问:*什么具体驱动力可以解释这个? 然后设计一个最小测试来确认或反驳它。