Paper: 2602.23360 Authors: Eric Eaton, Surbhi Goel, Marcel Hussing, Michael Kearns, Aaron Roth, Sikata Bela Sengupta, Jessica Sorrell Categories: cs.LG, cs.AI
Abstract
This work addresses the fundamental problem of model disagreement in machine learning—when two models trained independently on different samples produce different predictions. The authors introduce a novel anchoring technique that provides theoretical bounds on the expected squared difference between predictions of independently trained models. The key insight is to anchor the analysis to the average of two models, enabling disagreement bounds for four widely-used algorithms: stacked aggregation, gradient boosting, neural architecture search, and regression trees. Remarkably, the framework shows that disagreement can be systematically reduced to zero by tuning natural parameters like ensemble size, iteration count, architecture size, or tree depth.
Key Contributions
- A general anchoring technique for bounding independent model disagreement without requiring coordination between training processes
- Theoretical disagreement bounds for stacked aggregation that vanish as with the number of stacked models
- Disagreement analysis for gradient boosting showing convergence with iteration count
- Architecture search bounds demonstrating disagreement reduction with search space size
- Regression tree disagreement bounds that decrease with tree depth
- Generalization from one-dimensional squared loss to multi-dimensional regression with arbitrary strongly convex losses
The Anchoring Methodology
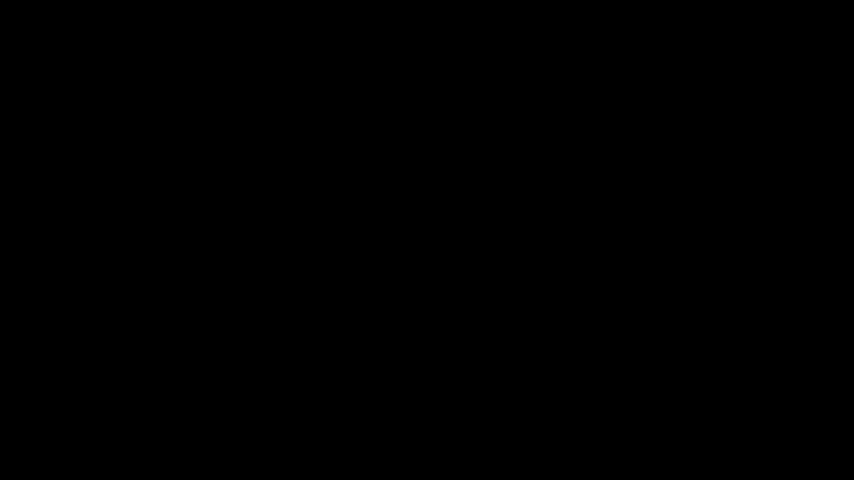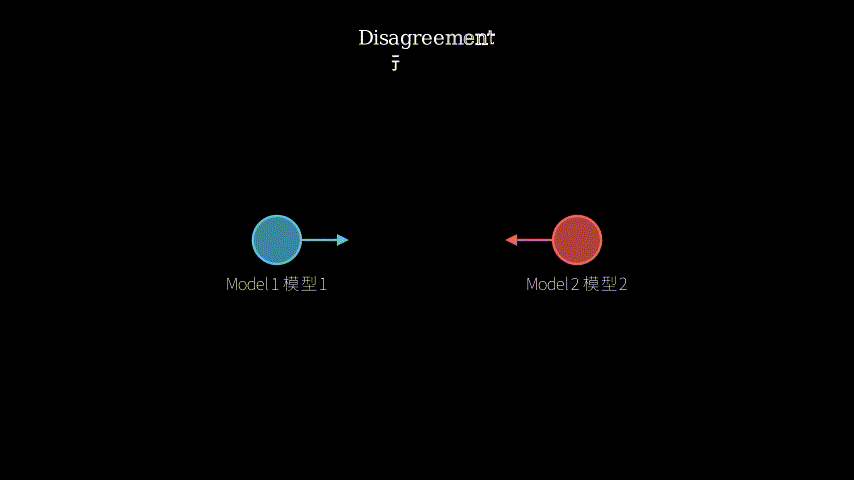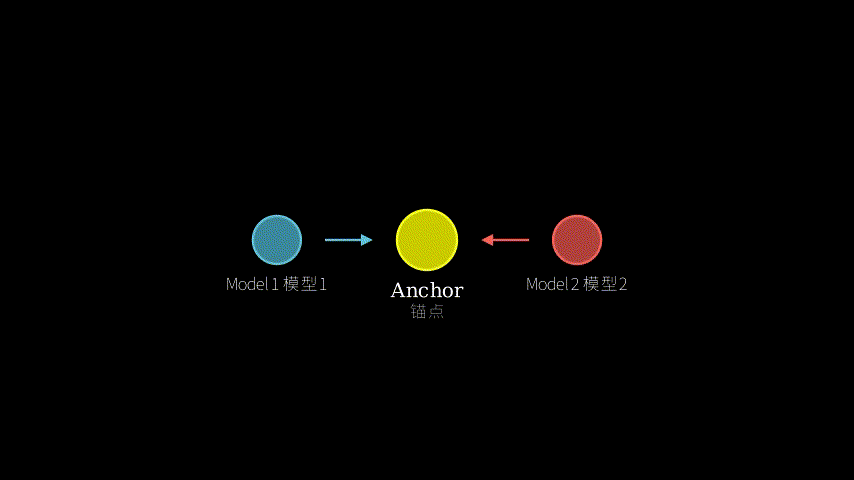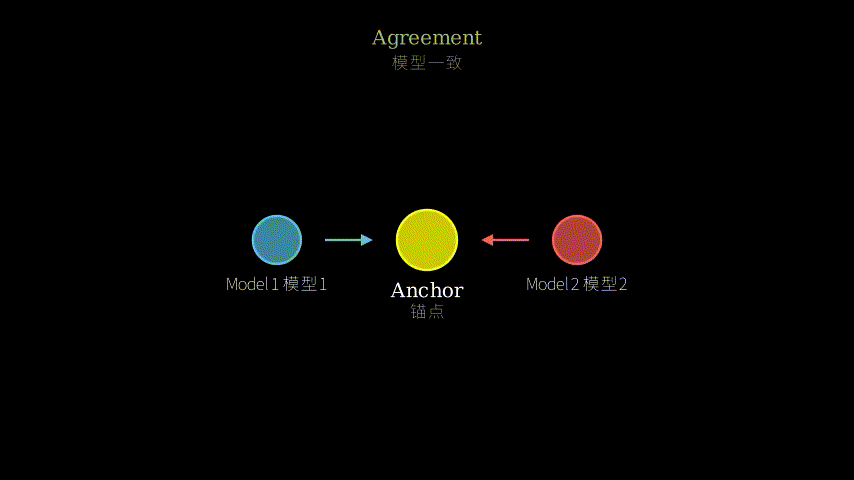
The core innovation lies in the anchoring approach. Rather than directly comparing two independently trained models and , the authors introduce their average as an anchor point. The disagreement can then be decomposed as:
This decomposition is powerful because each model’s deviation from the average can be bounded using standard learning-theoretic tools. The anchor serves as a stable reference point that both models implicitly converge toward as training parameters increase.
For stacked aggregation, if each base model has disagreement bounded by , stacking models reduces disagreement to approximately . For gradient boosting, the iterative refinement process naturally drives both models toward similar solutions. In neural architecture search, larger search spaces increase the probability that both training runs discover similar high-performing architectures. For regression trees, deeper trees provide finer-grained partitioning that reduces prediction variance.
Algorithmic Applications
Stacked Aggregation: The paper proves that for any base model class, stacking independently trained models reduces disagreement by a factor of . This provides theoretical justification for ensemble methods and explains why bagging and similar techniques improve model stability.
Gradient Boosting: The analysis shows that as boosting iterations increase, both models refine their predictions in similar directions, driven by the loss gradient. The disagreement bound decreases with the number of boosting rounds, explaining the empirical stability of gradient boosting methods like XGBoost and LightGBM.
Neural Architecture Search: When searching over architectures of size , the probability that two independent searches discover similar optimal architectures increases with . This provides insight into why larger architecture spaces can lead to more reproducible results despite the non-convex optimization landscape.
Regression Trees: For trees of depth , the disagreement bound decreases exponentially with depth. Deeper trees create finer partitions of the input space, reducing the variance in predictions within each leaf node and thus reducing disagreement between independently trained trees.
Theoretical Implications
The anchoring framework reveals a fundamental connection between model capacity, training dynamics, and prediction stability. The results suggest that model disagreement is not merely a nuisance but a quantifiable property that can be controlled through principled algorithm design.
The generalization to strongly convex losses beyond squared error demonstrates the robustness of the anchoring technique. This suggests the methodology could extend to classification problems, structured prediction, and other learning settings where disagreement is a concern.
From a practical standpoint, these bounds provide guidance on hyperparameter selection. If low disagreement is desired—for instance, in safety-critical applications or when model predictions must be auditable—practitioners can tune parameters like ensemble size or tree depth with theoretical guarantees on the resulting stability.
Takeaways
- Model disagreement can be systematically controlled through natural training parameters without requiring coordination between training runs
- The anchoring technique provides a unified analytical framework applicable to diverse ML algorithms
- Stacked aggregation reduces disagreement by with ensemble size, providing theoretical backing for ensemble methods
- Gradient boosting naturally drives models toward agreement through iterative refinement
- Larger architecture search spaces and deeper regression trees both reduce prediction disagreement
- The framework generalizes beyond squared loss to any strongly convex loss function, suggesting broad applicability
论文: 2602.23360 作者: Eric Eaton, Surbhi Goel, Marcel Hussing, Michael Kearns, Aaron Roth, Sikata Bela Sengupta, Jessica Sorrell 分类: cs.LG, cs.AI
摘要
本研究解决了机器学习中的基本问题——模型分歧,即在不同样本上独立训练的两个模型产生不同预测的现象。作者提出了一种新颖的锚定技术,为独立训练模型预测之间的期望平方差提供理论界限。核心洞察是将分析锚定到两个模型的平均值,从而为四种广泛使用的算法建立分歧界限:堆叠聚合、梯度提升、神经架构搜索和回归树。值得注意的是,该框架表明可以通过调整自然参数(如集成大小、迭代次数、架构规模或树深度)系统地将分歧降至零。
主要贡献
- 提出了一种通用锚定技术,用于约束独立模型分歧,无需训练过程之间的协调
- 为堆叠聚合提供理论分歧界限,随堆叠模型数量以速率消失
- 对梯度提升进行分歧分析,显示随迭代次数收敛
- 架构搜索界限表明分歧随搜索空间大小减少
- 回归树分歧界限随树深度递减
- 从一维平方损失推广到具有任意强凸损失的多维回归
锚定方法论
核心创新在于锚定方法。作者没有直接比较两个独立训练的模型和,而是引入它们的平均值作为锚点。分歧可以分解为:
这种分解非常强大,因为每个模型与平均值的偏差可以使用标准学习理论工具进行约束。锚点作为稳定的参考点,随着训练参数增加,两个模型都隐式地向其收敛。
对于堆叠聚合,如果每个基础模型的分歧界限为,堆叠个模型将分歧降低到约。对于梯度提升,迭代精化过程自然地驱动两个模型走向相似解。在神经架构搜索中,更大的搜索空间增加了两次训练运行发现相似高性能架构的概率。对于回归树,更深的树提供更细粒度的分区,减少预测方差。
算法应用
堆叠聚合: 论文证明对于任何基础模型类,堆叠个独立训练的模型将分歧减少倍。这为集成方法提供了理论依据,解释了为什么装袋和类似技术能改善模型稳定性。
梯度提升: 分析表明随着提升迭代增加,两个模型在相似方向上精化预测,由损失梯度驱动。分歧界限随提升轮数减少,解释了XGBoost和LightGBM等梯度提升方法的经验稳定性。
神经架构搜索: 在大小为的架构上搜索时,两次独立搜索发现相似最优架构的概率随增加。这提供了关于为什么更大的架构空间能导致更可重现结果的洞察,尽管存在非凸优化景观。
回归树: 对于深度为的树,分歧界限随深度呈指数递减。更深的树创建输入空间的更细分区,减少每个叶节点内预测的方差,从而减少独立训练树之间的分歧。
理论意义
锚定框架揭示了模型容量、训练动态和预测稳定性之间的基本联系。结果表明模型分歧不仅仅是一个麻烦,而是可以通过原则性算法设计控制的可量化属性。
推广到平方误差之外的强凸损失证明了锚定技术的鲁棒性。这表明该方法可以扩展到分类问题、结构化预测以及其他关注分歧的学习场景。
从实践角度看,这些界限为超参数选择提供指导。如果需要低分歧——例如在安全关键应用中或当模型预测必须可审计时——实践者可以调整集成大小或树深度等参数,并获得关于结果稳定性的理论保证。
要点总结
- 模型分歧可以通过自然训练参数系统地控制,无需训练运行之间的协调
- 锚定技术提供了适用于多种机器学习算法的统一分析框架
- 堆叠聚合随集成大小以减少分歧,为集成方法提供理论支持
- 梯度提升通过迭代精化自然地驱动模型走向一致
- 更大的架构搜索空间和更深的回归树都能减少预测分歧
- 该框架推广到任何强凸损失函数,表明具有广泛适用性