Paper: 2602.20161 Authors: Abdelrahman Shaker, Ahmed Heakl, Jaseel Muhammad, Ritesh Thawkar, Omkar Thawakar, Senmao Li, Hisham Cholakkal, Ian Reid, Eric P. Xing, Salman Khan Categories: cs.CV
Abstract
Mobile-O introduces the first practical unified multimodal model capable of both understanding and generating visual content directly on mobile devices. Unlike existing unified models that require substantial computational resources and cloud infrastructure, Mobile-O achieves real-time performance on edge devices through its novel Mobile Conditioning Projector (MCP) architecture. The model efficiently fuses vision-language features with diffusion-based generation using depthwise-separable convolutions and layerwise alignment, enabling cross-modal conditioning with minimal overhead. Trained on only a few million samples using a novel quadruplet format (generation prompt, image, question, answer), Mobile-O demonstrates competitive or superior performance compared to larger unified models while running significantly faster—achieving 74% on GenEval and processing 512×512 images in approximately 3 seconds on an iPhone.
Key Contributions
- Mobile Conditioning Projector (MCP): A lightweight architecture that efficiently bridges vision-language understanding and diffusion-based generation using depthwise-separable convolutions and layerwise alignment mechanisms
- Quadruplet Training Format: Novel post-training approach using (generation prompt, image, question, answer) tuples that jointly enhances both understanding and generation capabilities
- Efficient On-Device Deployment: First unified multimodal model achieving real-time performance on mobile devices (~3s per 512×512 image on iPhone) without cloud dependency
- Superior Efficiency-Performance Trade-off: Outperforms Show-O by 5% and JanusFlow by 11% on GenEval while running 6× and 11× faster respectively; surpasses them by 15.3% and 5.1% on visual understanding benchmarks
Architecture and Methodology
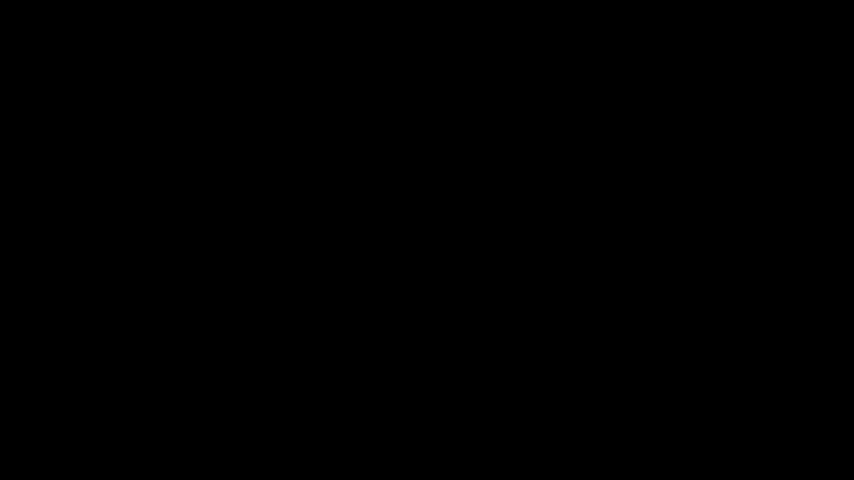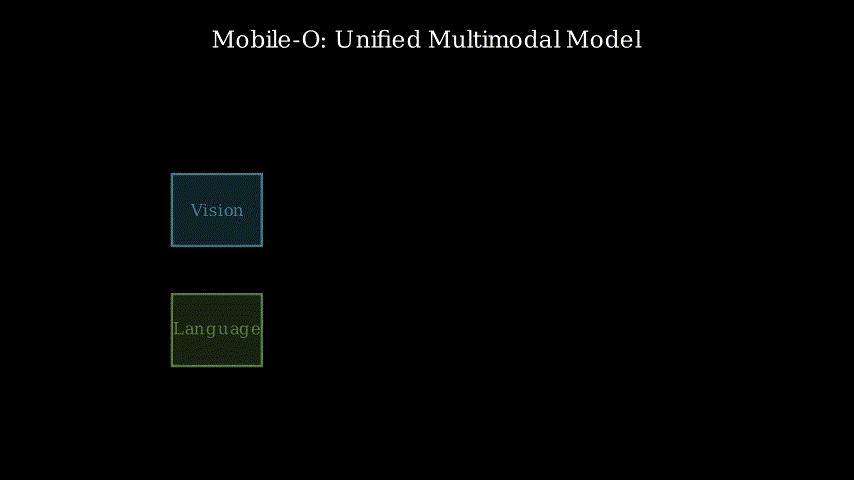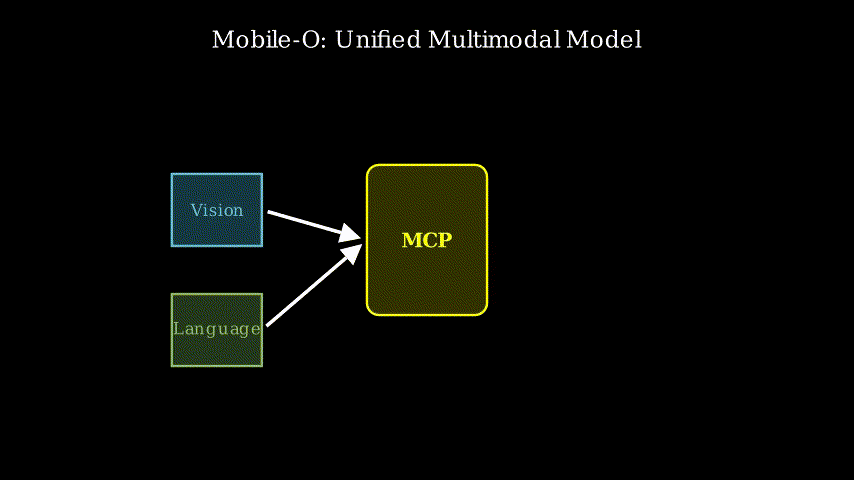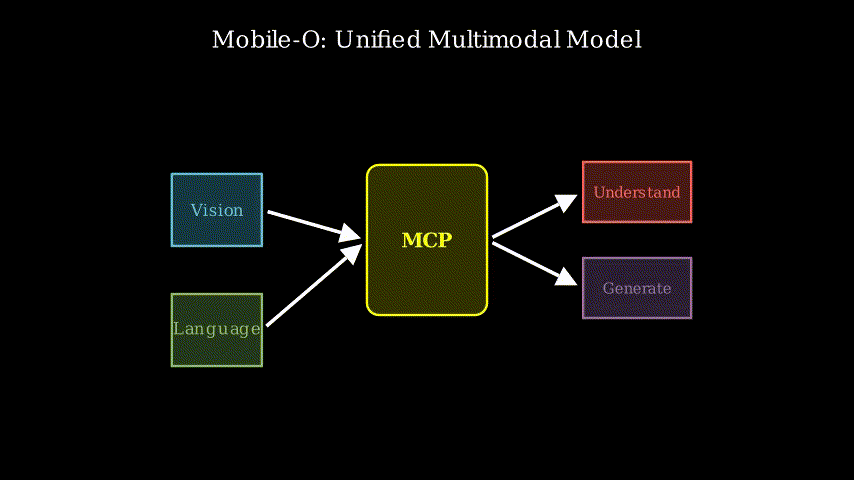
The Mobile-O architecture consists of three primary components working in concert: a vision encoder for image understanding, a language model for text processing and reasoning, and a diffusion generator for image synthesis. The innovation lies in the Mobile Conditioning Projector (MCP), which serves as the critical bridge between these modalities.
The MCP employs depthwise-separable convolutions—a technique that factorizes standard convolutions into depthwise and pointwise operations, dramatically reducing computational complexity from to , where is kernel size, is input channels, and is output channels. This architectural choice enables efficient feature transformation while maintaining representational capacity.
Layerwise alignment in the MCP ensures that features from the vision-language pathway are properly conditioned at multiple scales within the diffusion generator. Rather than injecting conditioning information at a single point, the MCP distributes alignment across multiple layers, allowing the diffusion process to leverage both high-level semantic information and low-level visual details. This multi-scale conditioning proves crucial for generating coherent images that accurately reflect textual descriptions.
The training methodology introduces a quadruplet format that simultaneously addresses understanding and generation tasks. Each training sample consists of four elements: a generation prompt describing desired visual content, the corresponding image, a question about visual content, and the answer. This format enables the model to learn bidirectional mappings between vision and language—both generating images from text and understanding images through question-answering. The joint training approach creates synergies between tasks, with understanding capabilities informing better generation and vice versa.
Performance Analysis
Mobile-O demonstrates remarkable performance across both generation and understanding benchmarks despite its compact size and efficiency focus. On GenEval, a comprehensive benchmark for text-to-image generation quality, Mobile-O achieves 74% accuracy, outperforming Show-O by 5 percentage points and JanusFlow by 11 percentage points. More impressively, these gains come alongside dramatic speed improvements—Mobile-O runs 6× faster than Show-O and 11× faster than JanusFlow.
For visual understanding tasks, Mobile-O shows even more pronounced advantages. Averaged across seven standard benchmarks including VQA, image captioning, and visual reasoning tasks, Mobile-O surpasses Show-O by 15.3% and JanusFlow by 5.1%. This substantial gap suggests that the quadruplet training format and efficient architecture don’t merely preserve understanding capabilities—they actively enhance them, possibly by creating richer cross-modal representations through joint training.
The efficiency metrics are particularly striking for mobile deployment. Processing a 512×512 image takes approximately 3 seconds on an iPhone, making Mobile-O the first unified multimodal model practical for real-time mobile applications. This performance is achieved with a model trained on only a few million samples, orders of magnitude less data than typical large-scale vision-language models require. The data efficiency stems from the focused training approach and architectural design that maximizes information extraction from each sample.
Implications and Future Directions
Mobile-O represents a paradigm shift in multimodal AI deployment, demonstrating that unified understanding and generation capabilities need not be confined to cloud infrastructure or high-end hardware. The ability to run sophisticated multimodal models entirely on-device has profound implications for privacy, latency, and accessibility. Users can generate and analyze images without transmitting sensitive data to remote servers, applications can function without internet connectivity, and the computational costs of serving millions of users shift from centralized data centers to distributed edge devices.
The architectural innovations in Mobile-O—particularly the MCP and quadruplet training—offer blueprints for future efficient multimodal systems. The depthwise-separable convolution approach and layerwise alignment could be adapted to other cross-modal tasks beyond vision and language. The quadruplet training format suggests that carefully designed multi-task learning can achieve better results with less data than separate task-specific training.
Several research directions emerge from this work. Extending Mobile-O to handle video understanding and generation would enable temporal reasoning on mobile devices. Incorporating additional modalities like audio could create truly comprehensive multimodal assistants. Exploring quantization and neural architecture search could further reduce computational requirements. Investigating how Mobile-O’s joint training approach scales to larger models and datasets could inform the design of next-generation unified models.
The open-source release of code, models, datasets, and mobile application democratizes access to unified multimodal AI, enabling researchers and developers to build upon this foundation. This accessibility could accelerate innovation in on-device AI and inspire new applications that leverage real-time multimodal intelligence.
Takeaways
- Mobile-O achieves the first practical unified multimodal understanding and generation on mobile devices, processing 512×512 images in ~3 seconds on iPhone without cloud dependency
- The Mobile Conditioning Projector (MCP) efficiently bridges vision-language and diffusion models using depthwise-separable convolutions and layerwise alignment with minimal computational overhead
- Novel quadruplet training format (generation prompt, image, question, answer) jointly enhances both understanding and generation capabilities using only a few million samples
- Mobile-O outperforms Show-O and JanusFlow by 5% and 11% on GenEval while running 6× and 11× faster, and surpasses them by 15.3% and 5.1% on visual understanding benchmarks
- The work demonstrates that efficient architecture design and focused training can achieve competitive performance with dramatically reduced computational requirements and training data
论文: 2602.20161 作者: Abdelrahman Shaker, Ahmed Heakl, Jaseel Muhammad, Ritesh Thawkar, Omkar Thawakar, Senmao Li, Hisham Cholakkal, Ian Reid, Eric P. Xing, Salman Khan 分类: cs.CV
摘要
Mobile-O首次实现了能够直接在移动设备上进行视觉内容理解和生成的统一多模态模型。与需要大量计算资源和云基础设施的现有统一模型不同,Mobile-O通过其新颖的移动条件投影器(MCP)架构在边缘设备上实现了实时性能。该模型使用深度可分离卷积和逐层对齐机制高效融合视觉-语言特征与基于扩散的生成过程,以最小开销实现跨模态条件化。Mobile-O仅使用数百万样本并采用新颖的四元组格式(生成提示、图像、问题、答案)进行训练,展现出与更大统一模型相当或更优的性能,同时运行速度显著更快——在GenEval上达到74%准确率,在iPhone上处理512×512图像仅需约3秒。
主要贡献
- 移动条件投影器(MCP): 轻量级架构,使用深度可分离卷积和逐层对齐机制高效连接视觉-语言理解与基于扩散的生成
- 四元组训练格式: 创新的后训练方法,使用(生成提示、图像、问题、答案)元组同时增强理解和生成能力
- 高效端侧部署: 首个在移动设备上实现实时性能的统一多模态模型(iPhone上处理512×512图像约3秒),无需云端依赖
- 卓越的效率-性能权衡: 在GenEval上分别超越Show-O和JanusFlow 5%和11%,同时运行速度快6倍和11倍;在视觉理解基准测试中平均超越它们15.3%和5.1%
架构与方法论
Mobile-O架构由三个协同工作的主要组件构成:用于图像理解的视觉编码器、用于文本处理和推理的语言模型,以及用于图像合成的扩散生成器。创新之处在于移动条件投影器(MCP),它是连接这些模态的关键桥梁。
MCP采用深度可分离卷积——这种技术将标准卷积分解为深度卷积和逐点卷积操作,将计算复杂度从大幅降低到,其中是卷积核大小,是输入通道数,是输出通道数。这种架构选择在保持表征能力的同时实现了高效的特征转换。
MCP中的逐层对齐确保来自视觉-语言路径的特征在扩散生成器的多个尺度上得到适当条件化。MCP不是在单一点注入条件信息,而是在多个层级分布对齐,使扩散过程能够同时利用高层语义信息和低层视觉细节。这种多尺度条件化对于生成准确反映文本描述的连贯图像至关重要。
训练方法引入了同时处理理解和生成任务的四元组格式。每个训练样本包含四个元素:描述期望视觉内容的生成提示、对应图像、关于视觉内容的问题以及答案。这种格式使模型能够学习视觉与语言之间的双向映射——既能从文本生成图像,又能通过问答理解图像。联合训练方法在任务之间创造协同效应,理解能力促进更好的生成,反之亦然。
性能分析
尽管Mobile-O体积紧凑且注重效率,但在生成和理解基准测试中都展现出卓越性能。在GenEval这一文本到图像生成质量的综合基准测试中,Mobile-O达到74%准确率,超越Show-O 5个百分点,超越JanusFlow 11个百分点。更令人印象深刻的是,这些性能提升伴随着显著的速度改进——Mobile-O比Show-O快6倍,比JanusFlow快11倍。
在视觉理解任务中,Mobile-O展现出更为明显的优势。在包括VQA、图像描述和视觉推理任务在内的七个标准基准测试中平均表现,Mobile-O超越Show-O 15.3%,超越JanusFlow 5.1%。这一显著差距表明,四元组训练格式和高效架构不仅保留了理解能力——它们实际上增强了这些能力,可能是通过联合训练创建了更丰富的跨模态表征。
移动部署的效率指标尤为突出。在iPhone上处理512×512图像大约需要3秒,使Mobile-O成为首个适用于实时移动应用的统一多模态模型。这一性能是在仅使用数百万样本训练的模型上实现的,比典型大规模视觉-语言模型所需的数据量少几个数量级。数据效率源于专注的训练方法和架构设计,最大化了从每个样本中提取的信息。
影响与未来方向
Mobile-O代表了多模态AI部署的范式转变,证明统一的理解和生成能力无需局限于云基础设施或高端硬件。能够完全在设备端运行复杂多模态模型对隐私、延迟和可访问性具有深远影响。用户可以在不向远程服务器传输敏感数据的情况下生成和分析图像,应用程序可以在没有互联网连接的情况下运行,服务数百万用户的计算成本从集中式数据中心转移到分布式边缘设备。
Mobile-O的架构创新——特别是MCP和四元组训练——为未来高效多模态系统提供了蓝图。深度可分离卷积方法和逐层对齐可以适配到视觉和语言之外的其他跨模态任务。四元组训练格式表明,精心设计的多任务学习可以用更少的数据获得比单独任务特定训练更好的结果。
这项工作引出了几个研究方向。将Mobile-O扩展到处理视频理解和生成将使移动设备能够进行时序推理。整合音频等额外模态可以创建真正全面的多模态助手。探索量化和神经架构搜索可以进一步降低计算需求。研究Mobile-O的联合训练方法如何扩展到更大的模型和数据集,可以为下一代统一模型的设计提供信息。
代码、模型、数据集和移动应用的开源发布使统一多模态AI的访问民主化,使研究人员和开发者能够在此基础上构建。这种可访问性可以加速端侧AI的创新,并激发利用实时多模态智能的新应用。
要点总结
- Mobile-O实现了首个在移动设备上实用的统一多模态理解与生成,在iPhone上处理512×512图像仅需约3秒,无需云端依赖
- 移动条件投影器(MCP)使用深度可分离卷积和逐层对齐以最小计算开销高效连接视觉-语言与扩散模型
- 新颖的四元组训练格式(生成提示、图像、问题、答案)仅使用数百万样本即可同时增强理解和生成能力
- Mobile-O在GenEval上分别超越Show-O和JanusFlow 5%和11%,同时运行速度快6倍和11倍,在视觉理解基准测试中平均超越它们15.3%和5.1%
- 该工作证明高效的架构设计和专注的训练可以在大幅降低计算需求和训练数据的情况下实现具有竞争力的性能