Paper: 2606.02578 Authors: Seojeong Park, Jiho Choi, Junyong Kang, Seonho Lee, Jaeyo Shin, Hyunjung Shim Categories: cs.CV, cs.AI
The Gap
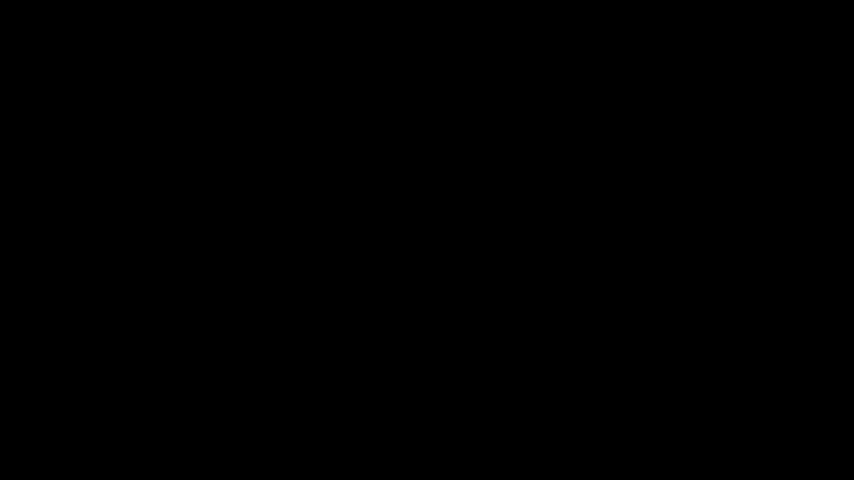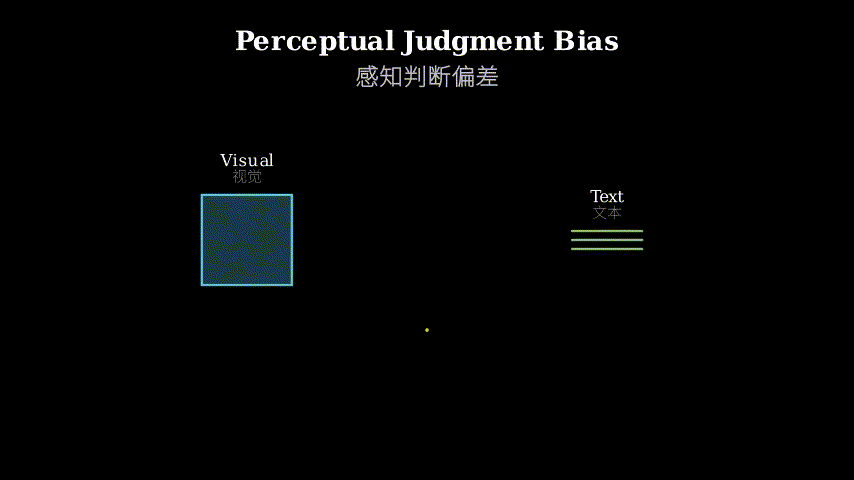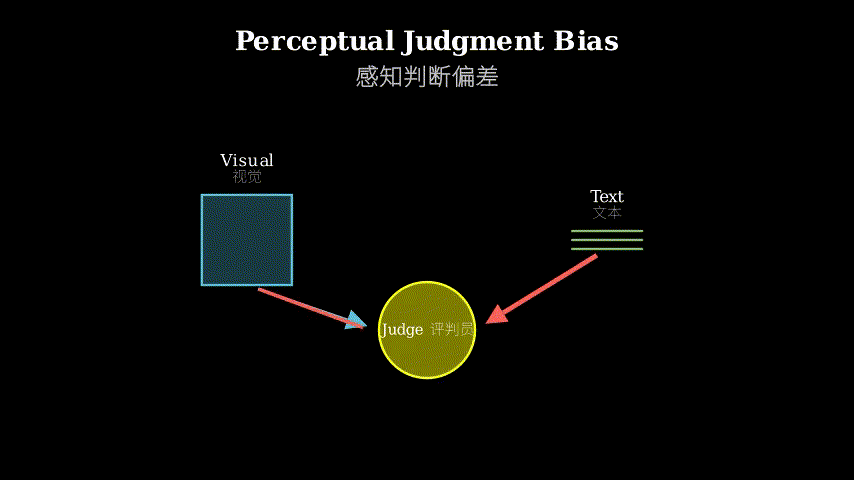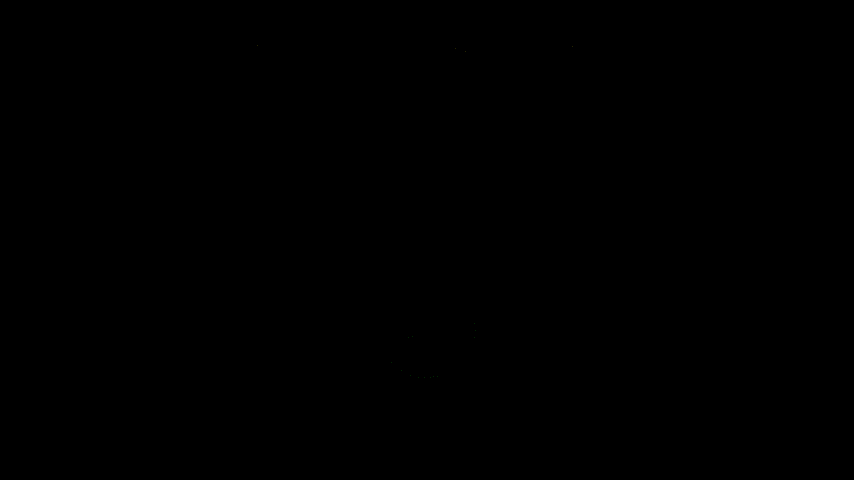
Multimodal LLMs can now serve as automated evaluators (MLLM-as-a-Judge), but they exhibit a systematic failure mode: when visual evidence contradicts textual content, they reward fluent explanations over perceptually correct answers. Existing work focuses on improving reasoning or alignment but doesn’t address this visual-textual anchoring bias. The evaluation becomes non-verifiable because the judge isn’t grounded in its own perception.
Problem: MLLM judge sees image A, candidate says "B" eloquently
   |
   v
Current behavior: Judge rewards eloquence, ignores visual mismatch
   |
   v
Root cause: Training lacks perceptual supervision signal
   |
   v
This paper's hypothesis: Controlled visual perturbations isolate bias
   |
   v
Method: Perturbed counterfactuals + GRPO reward + batch ranking
   |
   v
Evidence: Improved perceptual fidelity across 5 benchmarks
   |
   v
Conclusion: Judges can be trained to trust their vision first
The Increment
One sentence: Before this paper, multimodal judges prioritized narrative coherence over visual correctness; after, they can be systematically trained to anchor on perceptual evidence through counterfactual perturbations and structured reward modeling.
Core Mechanism
The method operates in three stages. First, it constructs the Perceptually Perturbed Judgment Dataset by taking existing multimodal QA instances and creating minimal edits to responses—changing a key visual detail while keeping everything else fluent. For example, if the correct answer is “red car,” the counterfactual becomes “blue car” with identical sentence structure. This isolates perceptual errors from reasoning failures.
Second, it trains a reward model using GRPO (Group Relative Policy Optimization) combined with a batch-ranking objective. Instead of requiring explicit pairwise labels, it uses the perturbed dataset to learn a scoring function where perceptually correct answers rank higher than fluent-but-wrong counterfactuals. The reward signal comes from verifiable visual grounding: did the judge’s score align with what’s actually in the image?
Third, the trained judge is deployed to evaluate new multimodal responses. During inference, it maintains coherent global ordering—if response A beats B and B beats C, then A beats C—because the batch-ranking loss enforced transitivity during training. The judge now weights visual evidence more heavily than textual plausibility.
Input: Image + Candidate Response
   |
   v
[Perceptual Encoder] -----> Visual features
   |                              |
   v                              v
[Text Encoder] -----> Text features
   |                              |
   +------------------------------+
   v
[Fusion + Reward Head]
   |
   v
Score: P(perceptually correct | image, text)
   |
   v
Training signal: GRPO reward + batch-rank loss
   ^
   |
Supervision: Perturbed counterfactual pairs
Think of this like training a wine judge who initially ranks bottles by label design rather than taste. You create a controlled experiment: swap the labels on identical wines and see if the judge notices. When they fail, you don’t just tell them “trust your palate”—you systematically train them by presenting batches where the only difference is the actual liquid, forcing them to anchor on sensory evidence. The perturbed dataset is the label-swap. The GRPO reward is the feedback loop saying “you ranked the wrong bottle higher.” The batch-ranking loss ensures if they learn Merlot > Pinot and Pinot > Chardonnay, they don’t then claim Chardonnay > Merlot in a different tasting session. After training, the judge reflexively checks the liquid before reading the label.
Key Concepts
-
Perceptual Judgment Bias: When a multimodal model evaluates another model’s response, it should ground its judgment in visual evidence. Instead, current judges exhibit a systematic tendency to reward responses that sound plausible—correct vocabulary, fluent grammar, coherent narrative—even when those responses misidentify what’s visually present. Imagine a model sees a photo of a brown dog and evaluates two answers: “The animal is a brown dog” (correct) versus “The sleek black Labrador retrieves the frisbee gracefully” (wrong but eloquent). Biased judges score the second higher because the language is richer, not because it matches the image. This bias makes evaluations unreliable: you can’t verify a judgment that ignores the evidence it’s supposed to be based on. The paper systematically demonstrates this by showing judges flip their rankings when you make tiny visual edits that shouldn’t matter to a perceptually grounded evaluator.
-
Counterfactual Perturbation for Verifiable Supervision: Training data for judges usually comes from human preferences, which are expensive and noisy. This paper generates training signal by creating minimal edits: take a correct response, change only the perceptual claim (red→blue, cat→dog), keep everything else identical. Now you have a verifiable pair: one is objectively correct per the image, one is objectively wrong, and the only difference is the perceptual content. This lets you train without ambiguous preference labels. It’s like creating a reading comprehension test where the only variable is whether the answer matches the passage—no need for subjective quality judgments. The perturbation isolates the perceptual dimension from stylistic or reasoning factors, giving you clean supervision for the specific bias you’re trying to fix.
-
Batch-Ranking Coherence: Typical pairwise training treats each comparison independently: A vs B, then B vs C. But this allows incoherence—the model might say A>B, B>C, then C>A in different contexts. Batch-ranking looks at multiple responses simultaneously and enforces a global ordering: if the model ranks response i above j in one batch, it should maintain that ordering when they appear together later. The training loss penalizes violations of transitivity. Think of it as teaching the model to maintain a leaderboard rather than making isolated binary choices. This matters for judges because evaluation is comparative—users want to rank multiple model outputs—and incoherent rankings destroy trust. The paper achieves this without needing explicit N-choose-2 pairwise labels by using the batch structure itself as the supervision signal.
Framework Shift
Before (mainstream approach):        After (this paper):

Image + Response                     Image + Response
      |                                    |
      v                                    v
  [MLLM Judge]                      [Perceptual Encoder]
      |                                    |
Evaluate:                            Extract visual
"Does this sound right?"             features explicitly
      |                                    |
      v                                    v
High score for                       [Counterfactual
eloquent text                        Generator]
      |                                    |
      v                                    v
Non-verifiable                       Create red vs blue
ranking                              minimal pairs
                                           |
                                           v
                                     [Reward Model
                                      + Batch Rank]
                                           |
                                     Train: "Did you
                                     anchor on vision?"
                                           |
                                           v
                                     Verifiable, coherent
                                     perceptual grounding
From implicit multimodal reasoning to explicit perceptual supervision, the core shift is treating visual grounding as a trainable objective with verifiable ground truth rather than an emergent property of scale.
Expert Assessment
Problem choice: Real gap. Automated evaluation is a bottleneck for multimodal systems, and the observation that judges reward fluency over correctness is empirically documented. This isn’t manufactured—the paper runs controlled experiments showing state-of-the-art judges fail on trivial perturbations. The problem sits at a critical juncture: as we move toward LLM-based evaluation pipelines, perceptual reliability is infrastructure, not a nice-to-have.
Method maturity: Mix of clever and brute force. The counterfactual perturbation idea is elegant—minimal intervention to isolate the bias. But the reliance on GRPO + batch-ranking feels like stacking techniques rather than a unified insight. Are simpler approaches being overlooked? What if you just added perceptual contrastive loss during pretraining? The paper doesn’t explore lightweight alternatives. That said, the framework is modular and the components are individually justified.
Experimental integrity: Baselines are fair (GPT-4V, Mantis, existing reward models) and span diverse benchmarks (LLaVA-Bench, MMVet, etc.). The ablations clearly show which components matter. One red flag: the perturbed dataset construction relies on GPT-4 for generating counterfactuals. If GPT-4 has systematic biases in what it perturbs, that leaks into training. The paper doesn’t deeply analyze the quality or diversity of these perturbations. The numbers are convincing but the dataset construction step needs more scrutiny.
Writing quality: Clear problem motivation and method description, but the experimental section rushes through results without enough failure analysis. When does the method still fail? What edge cases remain? The related work is thorough but could be tighter—some citations feel obligatory rather than directly relevant. The ablation section is strong. If I were rewriting one part, it’d be the results section: show representative failure modes alongside the aggregate metrics to give practitioners a realistic sense of limitations.
Verdict: Weak accept — Addresses a real problem with a reasonable solution and solid experimental coverage, but method feels somewhat incremental (combining existing techniques) and dataset construction isn’t interrogated enough. Contribution is more empirical than conceptual.
Takeaways
Practitioners can steal the perturbation-based data augmentation idea: when training any model that should ground predictions in specific evidence (not just vision—think retrieval-augmented generation, fact-checking, citation models), create minimal counterfactuals that keep everything fluent but swap the grounding claim. This gives you verifiable supervision without expensive human labels.
The batch-ranking loss for coherence is also transferable: if you’re building any comparative evaluator (code rankers, essay graders, content moderators), enforce transitivity explicitly rather than hoping pairwise training gives you a global ordering. Simple implementation: sample batches, compute all pairwise scores, add a loss term penalizing cycles.
Specific technique: the paper uses a structured reward combining pointwise score and relative ranking within batch. If you’re training reward models, this is a practical middle ground between Bradley-Terry pairwise losses (which ignore absolute quality) and regression losses (which ignore relative order).
论文: 2606.02578 作者: Seojeong Park, Jiho Choi, Junyong Kang, Seonho Lee, Jaeyo Shin, Hyunjung Shim 分类: cs.CV, cs.AI
缺口
多模态大模型现在可以充当自动评估器(MLLM-as-a-Judge),但它们表现出一种系统性失效模式:当视觉证据与文本内容矛盾时,它们会奖励流畅的解释而非感知正确的答案。
现有工作专注于改进推理或对齐,但没有解决这种视觉-文本锚定偏差。
评估变得无法验证,因为评判员没有基于自己的感知。
问题:MLLM评判员看到图像A,候选答案说"B"且表达流畅
   |
   v
当前行为:评判员奖励流畅性,忽视视觉不匹配
   |
   v
根本原因:训练缺乏感知监督信号
   |
   v
本文假设:受控视觉扰动可隔离偏差
   |
   v
方法:扰动反事实 + GRPO奖励 + 批次排序
   |
   v
证据:5个基准测试上感知保真度提升
   |
   v
结论:评判员可被训练为优先信任视觉
增量
一句话:这篇论文之前,多模态评判员优先考虑叙述连贯性而非视觉正确性;之后,它们可以通过反事实扰动和结构化奖励建模被系统性训练为锚定在感知证据上。
核心机制
该方法分三个阶段运作。
首先,它通过获取现有的多模态问答实例并对回答进行最小编辑来构建感知扰动判断数据集——改变关键视觉细节但保持其他部分流畅。
例如,如果正确答案是”红色汽车”,反事实版本就变成”蓝色汽车”但句子结构完全相同。
这将感知错误从推理失败中隔离出来。
其次,它使用GRPO(群组相对策略优化)结合批次排序目标来训练奖励模型。
不需要显式的成对标签,而是使用扰动数据集来学习一个评分函数,其中感知正确的答案排名高于流畅但错误的反事实。
奖励信号来自可验证的视觉基础:评判员的评分是否与图像中的实际内容一致?
第三,训练好的评判员被部署来评估新的多模态回答。
在推理期间,它维持连贯的全局排序——如果回答A胜过B且B胜过C,那么A胜过C——因为批次排序损失在训练期间强制了传递性。
评判员现在更重视视觉证据而非文本合理性。
输入:图像 + 候选回答
   |
   v
[感知编码器] -----> 视觉特征
   |                      |
   v                      v
[文本编码器] -----> 文本特征
   |                      |
   +----------------------+
   v
[融合 + 奖励头]
   |
   v
分数:P(感知正确 | 图像, 文本)
   |
   v
训练信号:GRPO奖励 + 批次排序损失
   ^
   |
监督:扰动的反事实对
把这想象成训练一位葡萄酒评判员,他起初根据酒标设计而非口味来给酒瓶排名。
你创建一个受控实验:把相同葡萄酒的酒标对调,看评判员是否注意到。
当他们失败时,你不只是告诉他们”相信你的味觉”——你通过呈现只有实际液体不同的批次来系统性训练他们,迫使他们锚定在感官证据上。
扰动数据集就是酒标对调。
GRPO奖励是反馈循环,说”你把错误的酒瓶排得更高了”。
批次排序损失确保如果他们学会了梅洛>黑皮诺,黑皮诺>霞多丽,他们就不会在另一次品鉴中声称霞多丽>梅洛。
训练后,评判员会反射性地先检查液体再读酒标。
关键概念
- 感知判断偏差:当一个多模态模型评估另一个模型的回答时,它应该将判断基于视觉证据。
然而,当前的评判员表现出系统性倾向,会奖励听起来合理的回答——正确的词汇、流畅的语法、连贯的叙述——即使这些回答错误识别了视觉上存在的东西。
想象一个模型看到一张棕色狗的照片,评估两个答案:“这动物是一只棕色狗”(正确)与”这只光滑的黑色拉布拉多优雅地叼回飞盘”(错误但表达优美)。
有偏差的评判员给第二个答案更高分,因为语言更丰富,而非因为它匹配图像。
这种偏差使评估不可靠:你无法验证一个忽视其应基于的证据的判断。
本文通过展示当你做微小视觉编辑时评判员会翻转其排名来系统性证明这一点,这些编辑对于一个基于感知的评估器不应产生影响。
- 用于可验证监督的反事实扰动:评判员的训练数据通常来自人类偏好,这既昂贵又有噪声。
本文通过创建最小编辑来生成训练信号:取一个正确回答,仅改变感知声明(红→蓝,猫→狗),保持其他所有内容相同。
现在你有一个可验证的配对:根据图像一个客观正确,一个客观错误,唯一的区别就是感知内容。
这让你无需模糊的偏好标签就能训练。
就像创建一个阅读理解测试,唯一变量是答案是否匹配段落——不需要主观质量判断。
扰动将感知维度从风格或推理因素中隔离出来,为你要修复的特定偏差提供干净的监督。
- 批次排序连贯性:典型的成对训练独立处理每个比较:A vs B,然后B vs C。
但这允许不连贯——模型可能说A>B,B>C,然后在不同上下文中说C>A。
批次排序同时查看多个回答并强制全局排序:如果模型在一个批次中将回答i排在j之上,它应该在它们稍后一起出现时维持该排序。
训练损失惩罚对传递性的违反。
把它想象成教模型维护一个排行榜而非做孤立的二元选择。
这对评判员很重要,因为评估是比较性的——用户想对多个模型输出排序——而不连贯的排序会破坏信任。
本文通过使用批次结构本身作为监督信号来实现这一点,无需显式的N选2成对标签。
框架转变
之前(主流方法):               之后(本文方法):

图像 + 回答                      图像 + 回答
      |                               |
      v                               v
  [MLLM评判员]                   [感知编码器]
      |                               |
评估:                            显式提取
"这听起来对吗?"                 视觉特征
      |                               |
      v                               v
对流畅文本                        [反事实
给高分                            生成器]
      |                               |
      v                               v
不可验证的                        创建红色vs蓝色
排序                              最小配对
                                       |
                                       v
                                  [奖励模型
                                   + 批次排序]
                                       |
                                  训练:"你是否
                                  锚定在视觉上?"
                                       |
                                       v
                                  可验证、连贯的
                                  感知基础
从隐式多模态推理到显式感知监督,核心转变是将视觉基础视为具有可验证真值的可训练目标,而非规模的涌现属性。
专家评审
选题眼光:真实缺口。
自动评估是多模态系统的瓶颈,而评判员奖励流畅性而非正确性的观察是有实证记录的。
这不是人造的——本文运行受控实验显示最先进的评判员在琐碎扰动上失败。
这个问题处于关键节点:随着我们转向基于LLM的评估流水线,感知可靠性是基础设施,不是锦上添花。
方法成熟度:巧劲和蛮力的混合。
反事实扰动想法很优雅——最小干预来隔离偏差。
但对GRPO + 批次排序的依赖感觉像是堆叠技术而非统一洞见。
是否有更简单的方法被忽略了?如果你在预训练期间只是添加感知对比损失会怎样?本文没有探索轻量级替代方案。
话虽如此,框架是模块化的,组件都有个别理由。
实验诚意:基线公平(GPT-4V、Mantis、现有奖励模型)并跨越多样化基准测试(LLaVA-Bench、MMVet等)。
消融实验清楚显示哪些组件重要。
一个值得警惕之处:扰动数据集构建依赖GPT-4生成反事实。
如果GPT-4在它扰动的内容上有系统性偏差,那会泄漏到训练中。
本文没有深入分析这些扰动的质量或多样性。
数字令人信服,但数据集构建步骤需要更多审查。
写作功力:问题动机和方法描述清晰,但实验部分匆忙浏览结果而没有足够的失败分析。
该方法何时仍然失败?还有什么边界情况?相关工作很全面但可以更紧凑——一些引用感觉是义务性的而非直接相关。
消融部分很强。
如果我重写一部分,会是结果部分:在汇总指标旁边展示代表性失败模式,给实践者一个对局限性的现实感。
判决:弱接收 — 用合理解决方案和扎实实验覆盖解决真实问题,但方法感觉有些渐进(组合现有技术)且数据集构建没有被充分质询。
贡献更多是实证性而非概念性。
要点总结
实践者可以偷走基于扰动的数据增强想法:当训练任何应该将预测基于特定证据的模型时(不只是视觉——想想检索增强生成、事实检查、引用模型),创建保持一切流畅但交换基础声明的最小反事实。
这给你可验证的监督而无需昂贵的人类标签。
用于连贯性的批次排序损失也是可迁移的:如果你在构建任何比较评估器(代码排序器、作文评分器、内容审核员),显式强制传递性而非希望成对训练给你全局排序。
简单实现:采样批次,计算所有成对分数,添加惩罚循环的损失项。
具体技术:本文使用结合点式分数和批次内相对排序的结构化奖励。
如果你在训练奖励模型,这是Bradley-Terry成对损失(忽略绝对质量)和回归损失(忽略相对顺序)之间的实用中间地带。