Paper: 2608.07463 Authors: Youjun Zhao, Alex Warren, Gary K. L. Tam, Rynson W. H. Lau Categories: cs.CV, cs.LG
Note up front: I’m working from the abstract and the framing it commits to. Where I’m inferring implementation details (which foundation model, how the transform is parameterized), I say so.
The Gap
Video diffusion models are now good enough that the interesting failures are the semantic ones. Mirrors are a beautiful example. A generative model can paint a mirror that looks like a mirror — right frame, right glassy sheen, right specular falloff — and put completely the wrong world inside it. The person standing in front of it isn’t in it. Or they are, but facing the wrong way, or at the wrong scale, or drifting frame to frame.
Three lines of prior work each stop short of this:
- Image-based reflection generation (the MirrorFusion / SynMirror family, depth-conditioned inpainting of a mirror plane) does get single-frame reflections roughly right, but has no notion of temporal coherence, and applying it per-frame makes the reflection flicker as its guesses re-roll.
- Video inpainting (flow-based methods like ProPainter/E2FGVI, and newer diffusion inpainters) is *extremely good at making a masked region look plausible and temporally smooth. That’s exactly the problem: it optimizes for local plausibility, and a mirror’s correct content is determined non-locally, by pixels somewhere else in the frame.
- Video mirror detection knows where mirrors are but never generates anything.
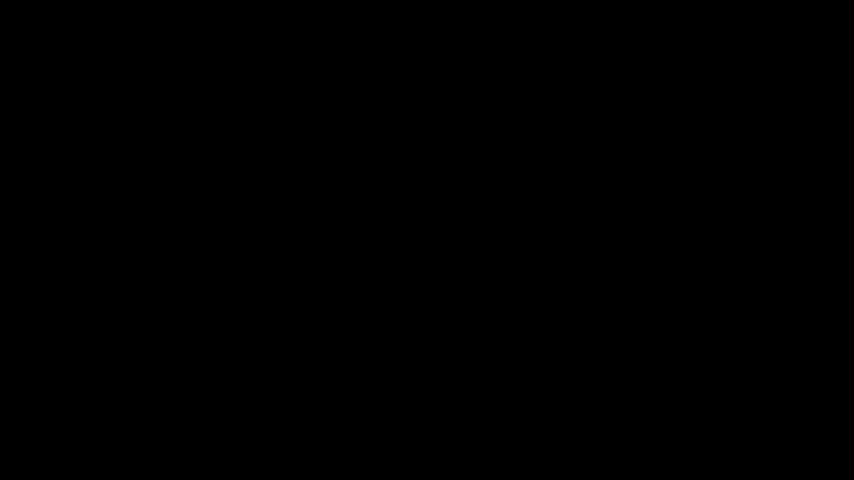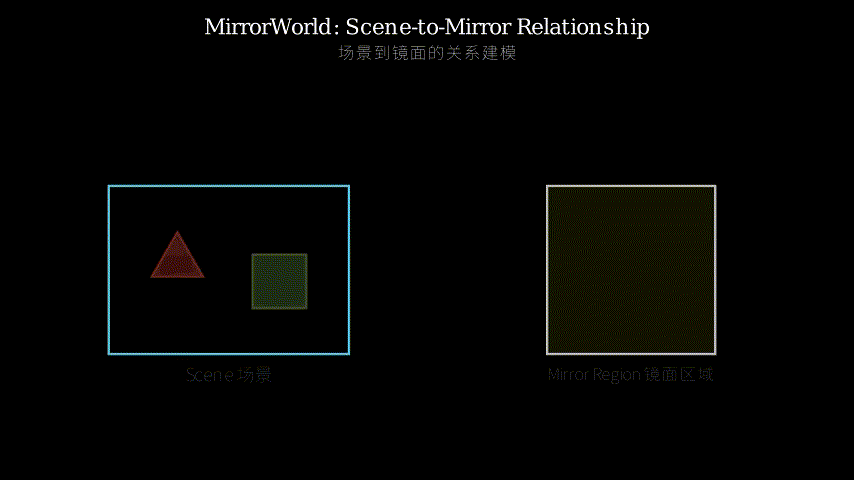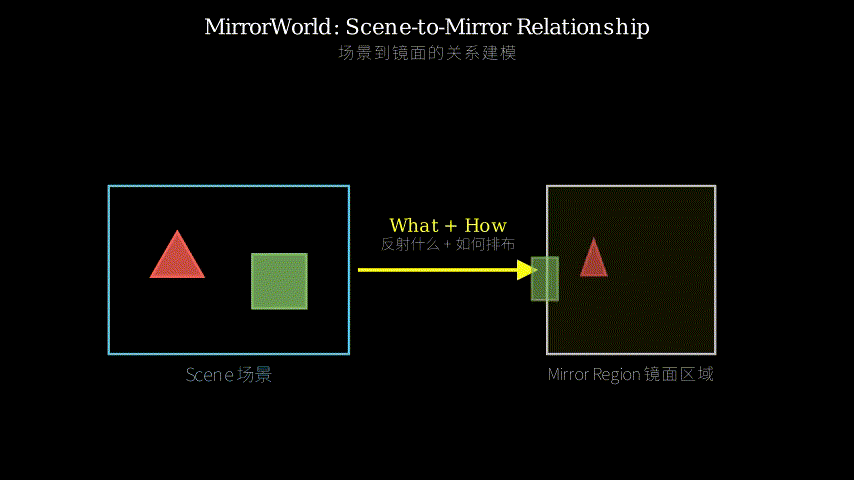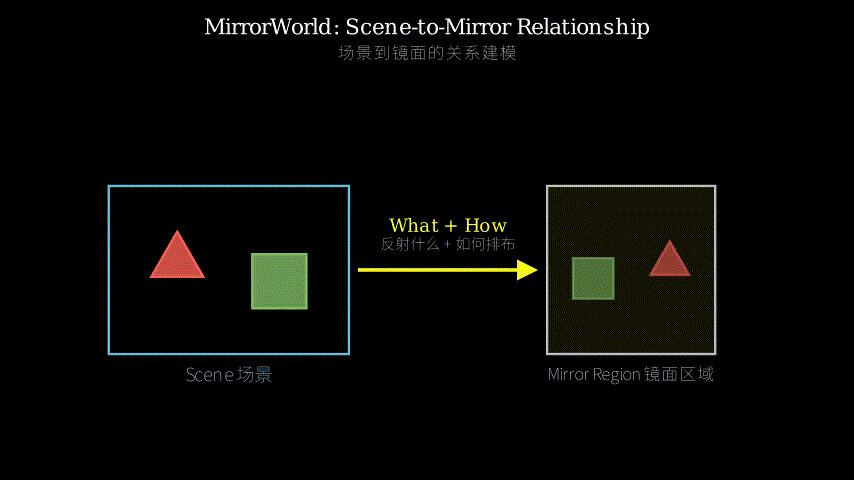
So the gap is a missing inductive bias: nothing in a standard VDM’s objective says “the tokens inside this region are a transformed function of tokens outside it.” The paper’s claim is that this relationship factorizes cleanly into a what and a how, and that each half needs its own supervision signal.
[ Problem ] content inside a mirror is determined by content outside it
     |
     v
[ Prior work and where it stops ]
   image reflection gen ..... one frame at a time . flickers in video
   video inpainting ......... locally plausible fill . globally wrong
   video mirror detection ... locates mirrors . generates nothing
     |
     v
[ Assumption ] reflection = WHAT is reflected  x  HOW it is arranged
     |          two separable sub-problems . two separate losses
     v
[ Method ] SRD: distill scene-to-mirror affinity from a frozen VFM
     |     GTA: learn a scene -> mirror spatial transform
     v
[ Evidence ] 4 existing video mirror datasets repurposed into a
     |        reflection reconstruction benchmark . beats image-based
     |        reflection methods and strong video inpainters
     v
[ Conclusion ] scene-to-mirror relation must be supervised explicitly
               rather than left to a generic generative prior
The Increment
One sentence: Before, filling a mirror region in video was treated as a hole-filling problem and the model guessed; after, it’s treated as a *correspondence problem with two explicit halves — a semantic link saying which scene content belongs inside, and a geometric link saying where it goes — plus the first benchmark that can actually measure whether you got it right.
Core Mechanism
The backbone is an ordinary video-diffusion inpainting setup: encode the video into latent tokens, mask the mirror region, denoise conditioned on the visible context and the mirror mask. Everything new lives in two auxiliary objectives that shape what the transformer’s internal attention does, rather than in new architecture on the generation path.
Semantic Relation Distillation (SRD) exploits the fact that a frozen self-supervised vision backbone (DINO-style) already produces features where a person and their reflection land close together — it’s an appearance-matching machine and nobody had to train it for mirrors. Run the teacher on the *ground-truth frames, compute the token-to-token affinity matrix between scene positions and mirror positions, and you get a soft table of “this patch inside the mirror corresponds to that patch outside it.” SRD pushes the diffusion transformer’s own attention distribution between mirror tokens and scene tokens toward that teacher table. The generator is thereby told to look at the right scene content while synthesizing the mirror, which is a much better-conditioned learning problem than “reconstruct these pixels.”
Geometric Transformation Alignment (GTA) handles the part semantics can’t: a planar mirror doesn’t just copy content, it applies a specific spatial map — a flip about the mirror plane composed with a perspective warp determined by the mirror’s pose relative to the camera. GTA learns that transform (I read it as a low-parameter warp, homography-like, predicted per scene/frame) and uses it to align scene features into the mirror region, supervising the arrangement of what SRD has already selected. So SRD constrains the attention’s *targets and GTA constrains its geometry.
 masked video + mirror mask
        |
        v
 +----------------------------+
 | VAE encode to latent tokens|
 +----------------------------+
        |
        v
 +--------------------------------------------------+
 |     Video Diffusion Transformer (trainable)      |
 |                                                  |
 |   scene tokens <--- attention A_s ---> mirror     |
 |        ^                                  ^      |
 +--------|----------------------------------|------+
          |                                  |
    SRD   | match affinity            GTA    | align layout
          |                                  |
 +--------+-----------+          +-----------+---------+
 | frozen VFM         |          | transform module T  |
 | (DINO-like)        |          | scene -> mirror     |
 | teacher affinity   |          | flip + warp params  |
 | A_t (i to j)       |          |                     |
 +--------------------+          +---------------------+
        WHAT                              HOW
          \                                /
           +---------> denoise <----------+
                          |
                          v
                  reflection-consistent video
The metaphor: a theater production with a second stage. The mirror is a second stage visible through an open doorway, and you need the doorway scene to stay consistent with the main stage all night.
- The pretrained VDM is the scenery crew. Superb painters. Give them a blank doorway and they’ll fill it with something gorgeous and internally coherent — and entirely unrelated to the play.
- SRD is the casting director. It doesn’t paint anything; it hands over a cast list that says *the figure in the doorway is the same person as the one at stage left. And crucially, it doesn’t invent that list — it borrows one from the frozen foundation model, the veteran script supervisor who already knows who’s who by sight, without ever having been briefed on this production.
- GTA is the blocking chart. Casting alone gives you the right actor in the wrong spot, facing the wrong way. The blocking chart is a fixed coordinate map from main stage to doorway stage: cross to this side, turn this direction, stand at this depth.
- The training loss on pixels is the audience. Necessary, but far too slow a signal to teach casting and blocking on its own — which is why the two notes are given directly to the crew during rehearsal rather than inferred from applause.
Retell it that way and you have the paper: casting plus blocking, both handed to painters who were already competent at painting.
Key Concepts
-
The what/how factorization. “Generate a correct reflection” is one entangled objective, and gradient descent on pixel error gives you almost no traction on it. Split it and each half becomes tractable: *what is a matching problem (which scene region does this mirror region correspond to), how is a warping problem (given the correspondence, what spatial map relates them). Concretely: if a red-jacketed man stands left of a mirror, what says “red jacket, this man, not a generic person”; how says “he appears on the right side of the mirror, smaller, rotated toward the glass.” Getting one right and the other wrong produces two visibly different failure modes — right person in the wrong place versus wrong person in the right place — which is itself decent evidence the split is real.
-
Attention distillation from a frozen backbone. An affinity matrix is just a big table of “how similar is patch i to patch j,” and self-supervised backbones like DINO produce features where that table is semantically meaningful for free: your face and your reflection score high, your face and the carpet score low. A diffusion transformer *also has such a table — its attention weights. SRD says: you already have a teacher who knows the answer to the correspondence question, so instead of hoping the student discovers it from reconstruction error, copy the table. This is a broadly reusable trick and not specific to mirrors: any generation task with a hidden long-range correspondence (shadows, symmetric objects, occluded completion) can borrow a teacher’s affinities.
-
Reflection reconstruction as a proxy benchmark. There is no dataset of “scene with mirror, plus ground-truth-correct reflection you must invent.” So the authors manufacture one: take four existing video-mirror-*detection datasets, use their mirror masks to erase real reflections, and require the model to put them back. Now you have pixel-exact ground truth and can report PSNR/SSIM/LPIPS/FVD. Clean and cheap — but note what it measures. It rewards recovering a reflection that was physically present and is heavily constrained by context. It does not directly test placing a new mirror in a scene, which is arguably the downstream application people want.
Framework Shift
Before (mainstream inpainting)      After (MirrorWorld)

  scene                               scene
 [ ~~~~~~~~~~ ]                      [ ~~~~~~~~~~ ]
       |                               |        |
       | context only                  | what   | how
       | (local plausibility)          | (SRD)  | (GTA)
       v                               v        v
 [ mirror region ]                    [ mirror region ]
   fill with something                  transformed copy of
   that looks fine and                  identified scene content
   moves smoothly
                                     explicit typed link
 no typed relation                   scene -> mirror
 scene -> mirror
From hole filling to constrained correspondence: the core shift is that the mirror region stops being an unknown to hallucinate and becomes a known function of the rest of the frame, with the semantic and geometric halves of that function supervised separately.
Expert Assessment
Problem choice. Real gap, and well-timed. The field has largely finished the “make it look good” phase of video generation and is entering the “make it physically and semantically consistent” phase — mirrors are a crisp, checkable instance of that, in the same family as shadows, refraction and multi-view consistency. It’s a niche framed narrowly enough to be solvable and general enough to matter. The what/how decomposition is the paper’s best idea and would survive even if both proposed modules were replaced.
Method maturity. SRD is genuine cleverness: distilling correspondence from a frozen backbone into cross-attention is the right lever, cheap, and probably the part that transfers. GTA reads as the weaker half. A planar mirror’s transform is *derivable from geometry — estimate depth and the mirror plane normal and you can compute the warp in closed form, which is exactly the direction the depth-conditioned image work went. Learning it end-to-end from a small repurposed dataset risks getting a soft, blurry approximation of something a geometry estimator hands you exactly. I’d want an ablation against “compute the reflection warp analytically and use it as hard conditioning,” and I’d want to know how GTA degrades on curved or multi-planar mirrors, or when the mirror plane is near-parallel to the view direction. Also unaddressed in the abstract: a very strong dumb baseline — copy the scene, flip it, warp it with an off-the-shelf homography, and hand that to the inpainter as a hint image. If MirrorWorld doesn’t clearly beat that, the machinery is hard to justify.
Experimental integrity. The baseline set is reasonable but structurally favorable. Image-based reflection methods applied per-frame *will flicker; beating them on video metrics is close to definitional. Generic video inpainters aren’t trained for this task at all. The honest comparison is against the same backbone fine-tuned on the same benchmark without SRD/GTA, and against the analytic-warp baseline above — the abstract’s “representative image-based methods and strong video inpainting baselines” doesn’t tell me those exist. Second flag: on a reconstruction task with pixel ground truth, PSNR/SSIM systematically reward conservative, slightly-blurred output, so a method that produces smoother reflections can win the table while looking worse to a human. A user study or an identity-consistency metric (does the reflected face match the real face under a recognition embedding) would be far more persuasive than another decimal of PSNR. Third: mirror regions in detection datasets vary wildly in size, and metrics computed over the full frame will be dominated by unmasked context — I’d want masked-region-only numbers, stratified by mirror area.
Writing quality. The abstract is unusually disciplined — the what/how framing is stated once and then used to organize everything, which is how it should be done. The section I’d bet is thinnest is the benchmark construction: repurposing four detection datasets into a generation benchmark involves a pile of consequential choices (mask dilation, how much of the mirror to erase, how splits avoid scene leakage between train and test, whether tiny mirrors are filtered) and papers routinely compress that into one paragraph. Rewriting it properly, with per-dataset statistics and masked-region metrics, would raise the whole contribution from “our method wins” to “here is the task, here is how to measure it, and by the way our method wins.” The benchmark is likely the more durable contribution; it deserves more space than the modules.
Verdict: weak accept — the decomposition and the distillation trick are genuinely useful and the benchmark fills a real void, but the geometric half looks like it’s learning something that could be computed, and the reported comparisons as framed don’t yet rule out a much simpler pipeline.
Takeaways
- When a generative task hides a long-range dependency, don’t hope the model finds it — distill the correspondence from a frozen self-supervised backbone into the generator’s attention. DINO-family features already encode “these two distant patches are the same thing.” That teacher affinity matrix is free supervision, and the recipe transfers directly to shadow synthesis, symmetric-object completion, occlusion inpainting, and multi-view consistency.
- Factorize entangled objectives into “which” and “where.” Pixel loss on an entangled target gives weak gradients. Split content selection from spatial arrangement, give each its own loss, and you get both better learning signal and interpretable failure modes (wrong content vs. wrong placement) that tell you which half to fix.
- You can manufacture a generation benchmark out of a detection dataset. Masks meant for segmentation become masks for inpainting, and the erased region becomes exact ground truth. Cheap way to bootstrap evaluation for any “generate content that should be consistent with context” task — just be explicit that reconstruction is a proxy for synthesis, not the same thing.
- Reverse-engineer their weakness for your own work: if part of your task has a closed-form physical solution (a reflection warp, a projection, a known symmetry), compute it and condition on it instead of learning it. Spend learned capacity on the part that isn’t derivable.
论文: 2608.07463 作者: Youjun Zhao, Alex Warren, Gary K. L. Tam, Rynson W. H. Lau 分类: cs.CV, cs.LG
先说清楚:我依据的是摘要及其明确承诺的框架。涉及实现细节的推断(用的是哪个基础模型、变换如何参数化),我会标明是推断。
缺口
视频生成已经好到一个程度:真正有意思的失败都是语义层面的。镜子是个极漂亮的例子。
模型能画出一面非常像镜子的镜子——边框对、玻璃质感对、高光衰减对——但里面装的是完全错误的世界。
站在镜前的人没出现在镜中;或者出现了,但朝向反了、比例不对、逐帧漂移。
三条已有路线各自都停在门口:
- 图像级反射生成(MirrorFusion / SynMirror 一脉,用深度条件做镜面平面的 inpainting)单帧大致能对,但没有时间一致性概念;逐帧套用等于每帧重新猜一次,反射会闪烁。
- 视频 inpainting(ProPainter、E2FGVI 这类光流方法,以及新的扩散补全模型)非常擅长把遮挡区域填得”看着合理且时间平滑”。这恰恰是问题所在:它优化的是局部合理性,而镜子的正确内容是非局部决定的——由画面别处的像素决定。
- 视频镜面检测知道镜子在哪,但从不生成任何东西。
所以缺口是一条缺失的归纳偏置:标准视频扩散模型的目标函数里,没有任何一项在说”这个区域内的 token 是区域外 token 的某种变换”。
本文的主张是:这个关系能干净地分解成”什么”和”怎么摆”,而且两半各自需要独立的监督信号。
[ 问题 ] 镜中内容由镜外内容决定
     |
     v
[ 已有工作及其止步之处 ]
   图像反射生成 ....... 一帧一帧 . 视频里会闪
   视频 inpainting .... 局部合理 . 全局错误
   视频镜面检测 ....... 只定位 . 不生成
     |
     v
[ 假设 ] 反射 = 反射什么 (WHAT) x 怎么排布 (HOW)
     |     两个可分离子问题 . 两个独立损失
     v
[ 方法 ] SRD: 从冻结视觉基础模型蒸馏场景到镜面的关联
     |    GTA: 学一个 场景 -> 镜面 的空间变换
     v
[ 证据 ] 4 个已有视频镜面数据集改造成反射重建基准
     |    优于图像级反射方法与强视频补全基线
     v
[ 结论 ] 场景到镜面的关系必须显式监督
         不能交给通用生成先验去碰运气
增量
一句话:以前,补全镜面区域被当成”填洞”问题,模型靠猜;现在它被当成对应关系问题,并被拆成两半显式监督——一条语义链决定镜里该出现哪块场景内容,一条几何链决定它摆在哪——外加第一个能真正衡量”你到底对没对”的基准。
核心机制
骨架是普通的视频扩散 inpainting:视频编码成 latent token,遮住镜面区域,以可见上下文和镜面 mask 为条件去噪。
新东西全部落在两个辅助目标上,它们塑造的是 Transformer 内部注意力的行为,而不是在生成通路上加新结构。
语义关系蒸馏(SRD) 利用了一个现成事实:冻结的自监督视觉骨干(DINO 那一类)产出的特征里,一个人和他的镜像本来就落得很近——它天生就是台外观匹配机器,没人为镜子专门训练过它。
在真值帧上跑这个 teacher,算出场景位置与镜面位置之间的 token 到 token 亲和度矩阵,你就得到一张软性对应表:“镜内这块 patch 对应镜外那块 patch”。
SRD 把扩散 Transformer 自己在镜面 token 与场景 token 之间的注意力分布,往这张 teacher 表上推。于是生成器被明确告知:合成镜面时该去看哪块场景内容。这比”把这些像素重建出来”是个条件好得多的学习问题。
几何变换对齐(GTA) 负责语义管不了的那半:平面镜不是简单复制内容,它施加一个特定空间映射——关于镜面的翻转,复合上由镜子相对相机位姿决定的透视扭曲。
GTA 学这个变换(我读作一个低参数量的 warp,类似 homography,按场景/帧预测),用它把场景特征对齐进镜面区域,从而监督 SRD 已经选好的内容该怎么排布。
一句话:SRD 约束注意力看向谁,GTA 约束它的几何。
 被遮挡视频 + 镜面 mask
        |
        v
 +----------------------------+
 | VAE 编码为 latent token     |
 +----------------------------+
        |
        v
 +--------------------------------------------------+
 |      视频扩散 Transformer (可训练)                 |
 |                                                  |
 |   场景 token <--- 注意力 A_s ---> 镜面 token       |
 |        ^                                  ^      |
 +--------|----------------------------------|------+
          |                                  |
    SRD   | 对齐亲和度                  GTA   | 对齐排布
          |                                  |
 +--------+-----------+          +-----------+---------+
 | 冻结视觉基础模型     |          | 变换模块 T           |
 | (DINO 类)          |          | 场景 -> 镜面         |
 | teacher 亲和度      |          | 翻转 + warp 参数     |
 | A_t (i 对 j)       |          |                     |
 +--------------------+          +---------------------+
       WHAT                              HOW
          \                                /
           +---------> 去噪 <-------------+
                        |
                        v
              反射一致的视频
核喻:一场有”第二舞台”的戏。
镜子是从一道敞开的门里看到的第二座舞台,你要让门内的戏整晚都和主舞台保持一致。
- 预训练视频扩散模型是布景组。画技极好。给他们一道空门,他们能填出一幅精美且自洽的画面——和这出戏毫无关系。
- SRD 是选角导演。 它自己不画,它递过来一张演员表,写着门里那个人和舞台左侧那个人是同一个人*。关键在于这张表不是它编的——它是从冻结的基础模型,那位资深剧本督导**那里借来的;这位督导本来就靠脸认人,从没被介绍过这出戏。
- GTA 是走位图。 只有选角,你会得到”对的演员站错位置、朝错方向”。走位图是一张从主舞台到门内舞台的固定坐标映射:换到这一侧、转这个方向、站这个深度。
- 像素重建损失是观众。 必要,但作为教选角和走位的信号太慢了——所以这两条提示是在排练时直接给布景组的,而不是从掌声里反推的。
能用这套话复述出来,你就掌握了这篇论文:给本来就会画画的人,补上选角和走位。
关键概念
-
what / how 分解。 “生成正确的反射”是一个纠缠在一起的目标,对像素误差做梯度下降几乎抓不到手。拆开后两半都变得可解:*what 是匹配问题(这块镜面区域对应哪块场景区域),how 是扭曲问题(给定对应关系,两者之间是什么空间映射)。具体点:一个穿红夹克的男人站在镜子左边,what 说”红夹克、就是这个人、不是某个通用路人”;how 说”他出现在镜面右侧、更小、朝玻璃转过来”。一半对一半错会产生两种肉眼可辨的不同失败:对的人在错的位置,vs 错的人在对的位置。这本身就是这个拆分成立的不错证据。
-
从冻结骨干蒸馏注意力。 亲和度矩阵说白了就是一张大表:“patch i 和 patch j 有多像”。DINO 这类自监督骨干产出的特征,让这张表免费具备语义意义:你的脸和你的镜像得分高,你的脸和地毯得分低。而扩散 Transformer 也有这样一张表——它的注意力权重。SRD 的意思是:既然已经有个老师知道对应问题的答案,就别指望学生从重建误差里自己悟出来,直接抄表。这个套路可复用性很强,跟镜子没有绑定:任何存在隐藏长程对应的生成任务(阴影、对称物体、被遮挡区域补全)都能借 teacher 的亲和度。
-
反射重建作为代理基准。 世界上没有”带镜子的场景 + 你必须凭空造出的正确反射真值”这种数据集。于是作者造了一个:拿四个已有的视频镜面检测数据集,用它们的镜面 mask 抹掉真实反射,再要求模型放回去。这样就有了像素级真值,可以报 PSNR/SSIM/LPIPS/FVD。干净又便宜——但要清楚它测的是什么。它奖励的是”恢复一个物理上本就存在、且被上下文强约束的反射”。它并不直接检验”往场景里新放一面镜子”,而后者才更接近人们真正想要的下游应用。
框架转变
之前 (主流 inpainting)              之后 (MirrorWorld)

  场景                                场景
 [ ~~~~~~~~~~ ]                      [ ~~~~~~~~~~ ]
       |                               |        |
       | 仅上下文                       | what   | how
       | (局部合理性)                    | (SRD)  | (GTA)
       v                               v        v
 [ 镜面区域 ]                          [ 镜面区域 ]
   填一个看着不错                        被识别出的场景内容
   且平滑运动的东西                      经变换后的映像

 场景 -> 镜面                          场景 -> 镜面
 没有带类型的关系                       显式带类型的链接
一句话:从填洞到带约束的对应,核心转变是——镜面区域不再是需要幻想的未知量,而是画面其余部分的一个已知函数,且这个函数的语义与几何两半被分别监督。
专家评审
选题眼光。 真缺口,时机也准。
视频生成大体已经走完”要好看”阶段,正在进入”要物理与语义自洽”阶段;镜子是这个阶段里一个干脆、可核查的实例,和阴影、折射、多视角一致性属于同一族。
这个题目窄到可解,又宽到值得做。what/how 分解是本文最好的想法——就算两个模块都被替换掉,这个分解也能留下来。
方法成熟度。 SRD 是真巧劲:把对应关系从冻结骨干蒸馏进 cross-attention,杠杆点找得对、代价低,也大概是最能迁移的部分。
GTA 读起来是弱的那半。平面镜的变换是可推导的——估计深度和镜面法向,warp 就有闭式解,这正是深度条件那一支图像工作走的方向。
在一个规模不大的改造数据集上端到端学它,风险是学出一个软而模糊的近似,去逼近一个几何估计器本来就能精确给你的东西。
我想看的消融是:“解析算出反射 warp,作为硬条件输入”。我也想知道 GTA 在曲面镜、多平面镜,或镜面近乎平行于视线时怎么退化。
摘要里还有一个没交代的强笨基线:把场景复制、翻转、用现成 homography warp 一下,当作 hint 图喂给 inpainter。如果 MirrorWorld 打不过这个,这套机械就很难辩护。
实验诚意。 基线集合合理,但结构上对自己有利。
图像级反射方法逐帧套必然闪烁,在视频指标上赢它接近于定义使然;通用视频 inpainter 压根没为这个任务训练过。
诚实的对比是:同一骨干、同一基准上微调,但去掉 SRD/GTA;以及上面那个解析 warp 基线。摘要里”代表性图像方法与强视频补全基线”这句话没告诉我这些存在。
第二个警示:在有像素真值的重建任务上,PSNR/SSIM 系统性地奖励保守、略微发虚的输出。一个产出更平滑反射的方法可能表上赢、人眼看更差。
用户研究,或者一个身份一致性指标(用识别 embedding 看镜中脸与真实脸是否匹配),都会比 PSNR 再多一位小数有说服力得多。
第三:检测数据集里镜面区域大小差异极大,全帧上算指标会被未遮挡的上下文主导。我想看只在 mask 区域内算、并按镜面面积分层的数字。
写作功力。 摘要相当克制——what/how 框架说一次,然后用它组织全部内容,这就是正确写法。
我打赌最薄的一节是基准构造。把四个检测数据集改造成生成基准,涉及一堆有后果的选择(mask 膨胀多少、镜面抹掉多少比例、划分如何避免训练测试间的场景泄漏、小镜面是否过滤),而论文常把这些压成一段。
把它认真重写,配上逐数据集统计和 mask 内指标,能把整个贡献从”我们方法更好”抬到”这里有个任务、这是衡量方法、顺便我们方法更好”。
基准很可能是更耐久的贡献,它值得比模块更多的篇幅。
判决:弱接收 —— 分解视角与蒸馏技巧确实有用、基准填了真空白,但几何那一半看起来在学一个本可以算出来的东西,而目前呈现的对比还排除不掉一个简单得多的流水线。
要点总结
- 生成任务里藏着长程依赖时,别指望模型自己发现——从冻结的自监督骨干把对应关系蒸馏进生成器的注意力。 DINO 系特征本来就编码了”这两块相距很远的 patch 是同一个东西”。那张 teacher 亲和度矩阵是免费监督,这个配方能直接迁到阴影合成、对称物体补全、遮挡补全、多视角一致性。
- 把纠缠的目标拆成”哪个”和”在哪”。 对纠缠目标做像素损失,梯度很弱。把内容选择和空间排布分开、各给一个损失,你既得到更好的学习信号,也得到可解释的失败模式(内容错 vs 位置错),能直接告诉你该修哪半。
- 可以用检测数据集造一个生成基准。 原本给分割用的 mask 拿来做 inpainting,被抹掉的区域就是精确真值。这是给任何”生成必须与上下文一致的内容”类任务快速搭起评测的便宜办法——只要明确说清重建是合成的代理,不等于合成。
- 把他们的弱点反过来用在自己的工作上:如果任务的某一部分有闭式物理解(反射 warp、投影、已知对称性),就算出来当条件输入,别去学它。把可学习容量花在推不出来的那部分。