Paper: 2607.22471 Authors: Zhen Zhao, Qihang Yang, Feifei Dai, Xiangfang Li, Bo Li Categories: cs.SE, cs.AI
The Gap
Test-driven development (TDD) with LLMs has made impressive strides — give a model some test cases, let it generate code, run the tests, refine, repeat. But this pipeline has a dirty secret: it assumes the test cases themselves are trustworthy. When humans write tests by hand, they’re usually reasonable. But when we automate test generation (which we need for scalability), LLMs produce tests with all sorts of quality issues — some are outright wrong, some are ambiguous, some test the wrong thing entirely.
Existing approaches like Self-Refine, CodeT, and EvalPlus either require human-crafted tests or blindly trust whatever tests they generate. The result: faulty tests give garbage feedback that corrupts code optimization (garbage in, garbage out), and mixed-quality tests produce conflicting signals that make it impossible to reliably pick the best code candidate. Nobody has seriously tackled the question: what if the tests themselves need validation?
Problem: LLMs generate stochastic, unreliable test cases
    |
    v
Prior assumption: More tests = better feedback
    |
    v
But: Faulty tests corrupt optimization signals
    |
    +---> Wrong tests --> Misleading gradient --> Worse code
    |
    +---> Mixed quality --> Conflicting scores --> Unreliable selection
    |
    v
MineValiCoder's move: Validate tests before trusting them
    |
    v
Key idea: Tests and code should validate EACH OTHER (mutual reinforcement)
    |
    v
Evidence: 96.34% Pass@1 on HumanEval, consistent gains across 4 LLMs
    |
    v
Conclusion: Unreliable tests are a real bottleneck; mutual validation solves it
The Increment
One sentence: Before this paper, automated TDD frameworks blindly trusted their test cases; after, we have a framework where test quality is mined and validated alongside code quality in a mutual reinforcement loop.
Core Mechanism
MineValiCoder has three tightly coupled modules that form a closed loop.
First, the Test Case Quality Mining (TCQM) module acts as a gatekeeper. It takes the raw, LLM-generated test cases and runs them through a self-validation process. Each test is checked against multiple code samples — if a test passes on code that should fail or fails on code that should pass, it’s flagged as unreliable. Only tests that demonstrate consistent, correct discriminating power survive to the next stage.
Second, the Parallel TDD Refinement module takes the filtered, high-quality tests and uses them to iteratively improve code. Instead of generating one candidate and refining it linearly, it spawns multiple code candidates in parallel and refines each one using feedback from the validated tests. This diversity is crucial — it explores more of the solution space and produces a richer pool of candidates for the final selection.
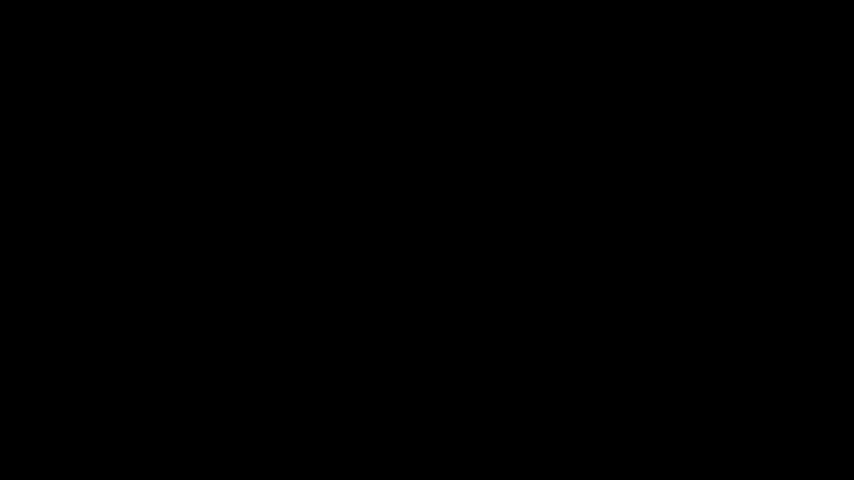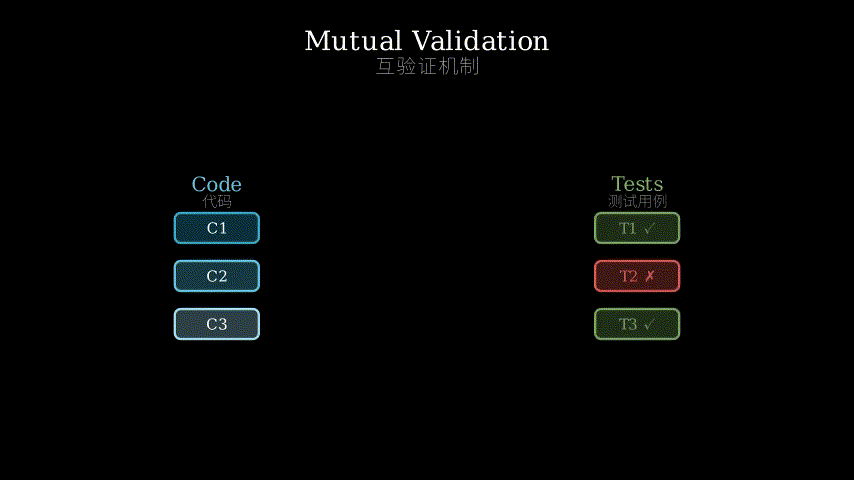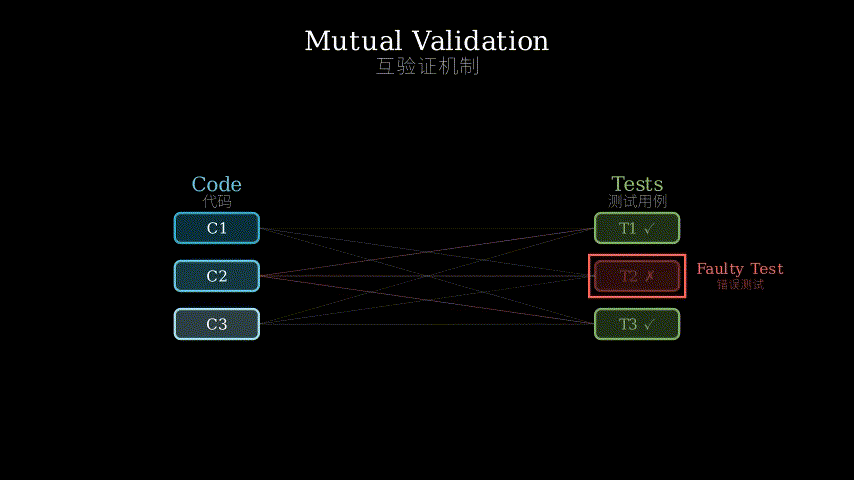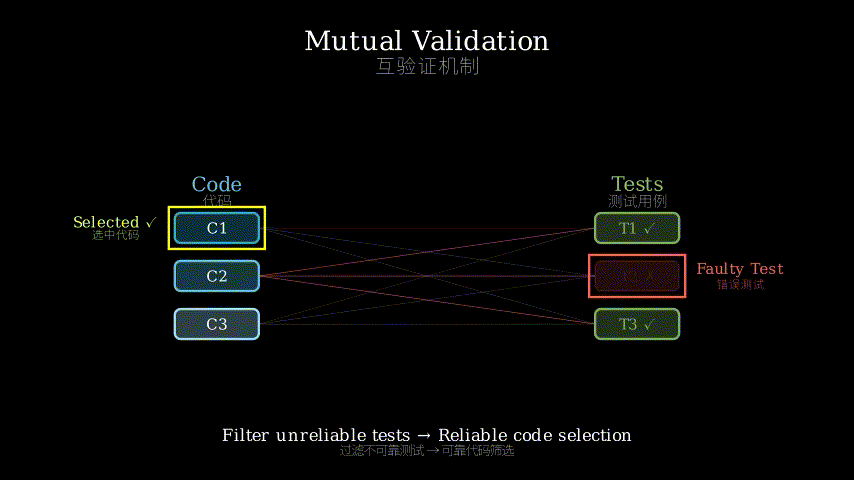
Third, the Bipartite Graph-Based Code-Test Mutual Validation (BiCoTeV) module is the most novel piece. It models all code candidates and all validated tests as two sides of a bipartite graph, with edges weighted by execution results. The key insight is that this graph encodes bidirectional information: good code is code that passes many good tests, and good tests are tests that good code passes. By running a mutual reinforcement algorithm on this graph (similar in spirit to PageRank or HITS), you get stable scores for both code and tests simultaneously, enabling reliable selection of the optimal code.
[Input: NL Requirements]
        |
        v
+-------------------+
| LLM generates     |
| test candidates   |
+-------------------+
        |
        v
+-------------------+
| TCQM Module       |
| Self-validation:  |
| filter bad tests  |
+-------------------+
        |
        v
+-------------------+
| Parallel TDD      |
| Refinement        |
| Multiple code     |
| candidates +      |
| iterative refine  |
+-------------------+
        |
        v
+-------------------+
| BiCoTeV Module    |
| Bipartite graph:  |
| code <-> tests    |
| Mutual scoring    |
+-------------------+
        |
        v
[Optimal Code Output]
        |
        +---> Feedback loop back to test validation
Structural Metaphor
Think of it like a peer-reviewed hiring process at a company that’s gotten burned by bad references.
The old way: You ask candidates for references, call those references, and hire whoever gets the best reviews. Problem? Some references are unreliable — a friend covering for a bad colleague, an old boss who barely remembers you, someone who gives everyone glowing reviews regardless. If you trust all references equally, you make bad hires.
MineValiCoder’s way:
TCQM (Checking the references): Before you take any reference letter seriously, you cross-check it. You show each reference a mix of strong and weak candidates you already know about. If a reference gives a glowing review to someone you know is incompetent, you flag that reference as unreliable. Only references that demonstrate good judgment survive.
Parallel TDD Refinement (Multiple interview rounds): Now you bring in a diverse pool of candidates and put them through rigorous interviews using only your vetted references as evaluators. You don’t just interview one person — you interview many in parallel, each getting feedback from the same trusted evaluators. This gives you a rich, diverse shortlist.
BiCoTeV (The final committee): Here’s the clever part. You create a scoring matrix: each candidate’s interview performance against each trusted reference’s evaluations. But you realize that the *best references are the ones that the best candidates score well on, and the best candidates are the ones that the best references endorse. So you iteratively re-weight: boost the influence of references that distinguish top candidates, boost the scores of candidates endorsed by top references. This is the bipartite graph mutual validation — references and candidates validate each other until scores stabilize. The person who emerges is your hire.
Without this mutual validation, you’d either trust bad references or miss great candidates who interview oddly with the wrong evaluator.
Key Concepts
-
Bipartite Graph Mutual Validation: Imagine you have two groups — students and teachers — and you want to rank both. A good student gets high scores from good teachers. A good teacher is one whose high scores go to good students. You can’t rank one without the other. So you start with rough rankings for one side, compute rankings for the other, then iterate back and forth. After a few rounds, both rankings stabilize. That’s HITS (Hyperlink-Induced Topic Search) in a nutshell, and that’s essentially what BiCoTeV does with code candidates and test cases. The “bipartite” part just means there are two distinct groups, and edges only go between groups (code-to-test), not within them.
-
Test Case Self-Validation: When you generate a test case with an LLM, you don’t know if it’s correct. So you run it against a pool of code samples — some that are known-correct, some that are known-wrong. If a test passes on all correct code and fails on all wrong code, it’s a reliable discriminator. If it fails on correct code or passes on wrong code, it’s faulty and should be discarded. It’s like calibrating a thermometer against known temperatures before using it for real measurements.
-
Stochasticity in LLMs: This is the root problem. Ask an LLM to generate a test case for “sort a list” — it might give you a correct test, a test with an off-by-one error, or a test that tests something else entirely. Each generation is a roll of the dice. Previous frameworks treated these dice rolls as ground truth. MineValiCoder acknowledges the dice are loaded and builds machinery to detect which rolls are trustworthy.
Framework Shift
Before (mainstream approach):        After (this paper):

[Requirements]                       [Requirements]
      |                                    |
      v                                    v
[LLM generates tests]               [LLM generates tests]
      |                                    |
      | (trust all tests)                  v
      |                              [TCQM: validate tests]
      |                                    |
      v                                    v
[LLM generates code]                [Parallel code generation]
      |                                    |
      v                                    v
[Test feedback]                     [Validated test feedback]
      |                                    |
      v                                    v
[Select by test scores]             [BiCoTeV: mutual scoring]
      |                                    |
      v                                    v
[Output code]                       [Output code + feedback loop]
From “trust all tests and rank code by pass rate” to “validate tests, generate diverse code, and co-score tests and code in a bipartite graph,” the core shift is treating test reliability as a first-class optimization variable rather than a hidden assumption.
Expert Assessment
Problem choice: This is a real and underexplored gap. The field has been so focused on “better prompts” and “better models” that it largely ignored the quality of the test signal itself. The observation that LLM-generated tests are noisy and this noise propagates destructively through TDD loops is well-motivated and practically important. It sits at the intersection of SE testing wisdom (test oracles are hard) and LLM limitations (stochasticity), which is a productive frontier.
Method maturity: The TCQM and parallel refinement modules are solid but not revolutionary — filtering bad tests and generating diverse candidates are well-understood ideas. The bipartite graph mutual validation (BiCoTeV) is the real contribution, and it’s a clever adaptation of classical algorithms (HITS/PageRank-style) to a new domain. It’s not brute force — it’s the right kind of structural thinking. That said, I wonder if simpler approaches (e.g., majority voting with outlier detection) get you 80% of the gains with 20% of the complexity. The paper doesn’t explore this ablation thoroughly.
Experimental integrity: The benchmarks are standard (HumanEval, MBPP, APPS, LiveCodeBench) and the gains are substantial. Testing across 4 different LLMs strengthens the claim that this isn’t model-specific. The numbers are impressive but need context — Pass@1 of 96.34% on HumanEval is near ceiling, and the community is increasingly skeptical of HumanEval as a discriminator. LiveCodeBench and APPS results are more meaningful. I’d want to see cost/compute analysis — the parallel generation and bipartite graph construction must be expensive. This is notably absent.
Writing quality: The paper reads clearly and the motivation is well-established. However, the ablation studies feel rushed — I wanted to see exactly how much each module contributes and whether BiCoTeV alone (without TCQM) already gets most of the gains. The cost analysis gap is a significant omission for a framework that likely multiplies inference cost by 5-10x. Section 4 could be restructured to lead with the most challenging benchmarks first.
Verdict: weak accept — The problem is real, the bipartite graph idea is elegant, and the numbers are strong, but missing cost analysis and incomplete ablations keep this from being a clear strong accept.
Takeaways
Three concrete things to steal:
-
Mutual validation as a general pattern: The idea that your evaluation instruments (tests) and your evaluated objects (code) should validate each other applies broadly. If you’re building any system where quality signals are generated by the same noisy process you’re trying to improve (e.g., data labeling, preference learning, synthetic data pipelines), this bidirectional validation framework transfers directly.
-
Cross-check generated artifacts against known-good and known-bad examples: The TCQM technique — filtering LLM-generated outputs by testing them against a calibrated mix of correct and incorrect samples — is cheap to implement and useful anywhere you generate discriminators (tests, classifiers, evaluation criteria). You don’t need the full MineValiCoder pipeline to use this.
-
Parallel diversity over linear refinement: When using LLMs for iterative improvement, generating multiple diverse candidates and refining each independently beats refining a single candidate repeatedly. This is well-known but the paper demonstrates it concretely in the TDD setting and shows the interaction with test quality.
论文: 2607.22471 作者: Zhen Zhao, Qihang Yang, Feifei Dai, Xiangfang Li, Bo Li 分类: cs.SE, cs.AI
缺口
基于LLM的测试驱动开发(TDD)进展很快——给模型一些测试用例,让它生成代码,跑测试,改进,循环。但这个流程有个暗病:它默认测试用例本身是可信的。人工写测试通常没问题,但要自动化生成测试(规模化必须如此),LLM产出的测试质量参差不齐——有些根本就是错的,有些测的不是该测的东西。
现有方法(Self-Refine、CodeT、EvalPlus等)要么依赖人工编写测试,要么盲目信任生成的测试。结果是:错误测试给出垃圾反馈,污染代码优化过程;混杂质量的测试产生矛盾信号,让人无法可靠地选出最优代码。之前没有人认真回答过一个问题:如果测试本身也需要验证呢?
问题:LLM生成的测试用例具有随机性,质量不可靠
    |
    v
此前的假设:测试越多,反馈越好
    |
    v
但实际上:错误测试会污染优化信号
    |
    +---> 错误测试 --> 误导梯度 --> 代码越改越差
    |
    +---> 质量混杂 --> 信号矛盾 --> 无法可靠选择
    |
    v
MineValiCoder的做法:先验证测试,再信任测试
    |
    v
核心思想:测试和代码应该互相验证(互增强)
    |
    v
证据:HumanEval 96.34% Pass@1,跨4个LLM一致提升
    |
    v
结论:不可靠测试是真实瓶颈;互验证能解决它
增量
一句话: 这篇论文之前,自动化TDD框架盲目信任测试用例;之后,我们有了一个框架,可以挖掘测试质量,并通过互增强循环让测试质量和代码质量同步提升。
核心机制
MineValiCoder由三个紧密耦合的模块组成,形成闭环。
第一,测试用例质量挖掘模块(TCQM),充当守门人。它接收LLM原始生成的测试用例,通过自验证过程进行筛选。每个测试会用多个代码样本来校验——如果一个测试在应该失败的代码上通过了,或者在应该通过的代码上失败了,就会被标记为不可靠。只有展现出一致、正确区分能力的测试才能进入下一阶段。
第二,并行TDD精炼模块。它使用经过过滤的高质量测试来迭代改进代码。关键区别在于:不是生成一个候选然后线性精炼,而是并行生成多个代码候选,每个都用验证过的测试反馈独立精炼。这种多样性很关键——它探索了更广的解空间,产出更丰富的候选池。
**第三,二部图代码-测试互验证模块(BiCoTeV)**是最新颖的部分。它把所有代码候选和所有验证过的测试建模为二部图的两侧,边权由执行结果决定。核心洞察是:好的代码是通过很多好测试的代码,好的测试是好代码能通过的测试。通过在图上运行互增强算法(类似PageRank或HITS的思路),可以同时得到代码和测试的稳定评分,从而可靠地选出最优代码。
[输入:自然语言需求]
        |
        v
+-------------------+
| LLM生成测试候选   |
+-------------------+
        |
        v
+-------------------+
| TCQM模块          |
| 自验证:过滤坏测试 |
+-------------------+
        |
        v
+-------------------+
| 并行TDD精炼模块   |
| 多个代码候选 +     |
| 迭代精炼          |
+-------------------+
        |
        v
+-------------------+
| BiCoTeV模块       |
| 二部图:代码<->测试|
| 互评分            |
+-------------------+
        |
        v
[输出最优代码]
        |
        +---> 反馈回路回到测试验证
结构性比喻
把它想象成一个经受过教训的招聘流程。
老办法:候选人给你推荐人的联系方式,你打电话问推荐人,录用评分最高的人。问题是什么?有些推荐人不可靠——朋友帮同事说好话、前领导根本不记得你了、有人给谁都写好评。如果你同等信任所有推荐人,就会招错人。
MineValiCoder的做法:
TCQM(检验推荐人):在认真对待任何推荐信之前,先交叉验证。你给每个推荐人看一批你已知的好员工和差员工。如果一个推荐人给你知道不称职的人打了高分,你就标记这个推荐人不靠谱。只有展现出好判断力的推荐人才被保留。
并行TDD精炼(多轮面试):现在你引入多样化的候选人池,用经过审核的推荐人作为评估者进行严格面试。你不是只面一个人——你并行面试多个人,每个人都接受同一批可信评估者的反馈。这样你得到一个丰富多样的候选名单。
BiCoTeV(最终委员会):最巧妙的部分来了。你创建一个评分矩阵:每个候选人的面试表现对应每个可信评估者的评价。但你意识到——最好的评估者就是给最好的候选人高分的人,最好的候选人就是被最好的评估者认可的人。于是你迭代重新加权:提升能区分顶尖候选人的评估者的影响力,提升被顶尖评估者认可的候选人的分数。这就是二部图互验证——评估者和候选人互相验证,直到分数稳定。最终胜出的人就是你的选择。
没有这个互验证,你要么信错推荐人,要么错过在某个评估者面前表现不佳的优秀候选人。
关键概念
-
二部图互验证:想象你有两组人——学生和老师——你想给两边都排名。好学生从好老师那里得高分。好老师是把高分给了好学生的人。你没法只排一边就得出另一边的排名。所以你先给一边粗略排名,算另一边,然后再迭代回去。几轮之后两边都稳定了。这就是HITS(超链接诱导主题搜索)的精髓,也是BiCoTeV做的事情。“二部”只是说有两个不同的组,边只在组间(代码到测试)而不在组内。
-
测试用例自验证:用LLM生成一个测试用例时,你不知道它对不对。所以你把它跑在一批代码样本上——有些已知正确,有些已知错误。如果一个测试在所有正确代码上通过、在所有错误代码上失败,它就是可靠的区分器。如果它在正确代码上失败或在错误代码上通过,它就有毛病,应该丢弃。就像用已知温度校准温度计,然后再拿去真实测量。
-
LLM的随机性:这是根本问题。让LLM为”排序列表”生成测试——它可能给出正确的测试、带偏差的测试、或者测了别的东西的测试。每次生成都是掷骰子。以前的框架把骰子结果当真。MineValiCoder承认骰子有假,建造了检测哪些点数可信的机制。
框架转变
之前(主流方法):                  之后(本文方法):

[需求]                             [需求]
  |                                  |
  v                                  v
[LLM生成测试]                      [LLM生成测试]
  |                                  |
  | (信任所有测试)                    v
  |                            [TCQM:验证测试质量]
  |                                  |
  v                                  v
[LLM生成代码]                      [并行代码生成]
  |                                  |
  v                                  v
[测试反馈]                         [经验证的测试反馈]
  |                                  |
  v                                  v
[按通过率选代码]                    [BiCoTeV:互评分]
  |                                  |
  v                                  v
[输出代码]                         [输出代码 + 反馈回路]
从”信任所有测试,按通过率排序代码”到”验证测试、生成多样代码、在二部图中协同评分测试和代码”,核心转变是将测试可靠性从隐藏假设提升为一等优化变量。
专家评审
选题眼光:这是一个真实且未被充分探索的缺口。这个领域一直在”更好的提示词”和”更好的模型”上下功夫,却基本忽略了测试信号本身的质量。LLM生成的测试有噪声,且噪声会在TDD循环中破坏性传播——这个观察动机充分,实践意义明确。它处于软件工程测试智慧(测试预言问题很难)和LLM局限性(随机性)的交叉地带,是一个有生产力的前沿。
方法成熟度:TCQM和并行精炼模块扎实但不算革命性——过滤坏测试和生成多样候选是成熟思路。二部图互验证(BiCoTeV)是真正的贡献,是经典算法(HITS/PageRank风格)到新领域的巧妙适配。不是蛮力,是正确的结构性思维。但我怀疑是否有更简单的方案(比如带异常检测的多数投票)能用20%的复杂度拿到80%的收益。论文没有充分做这个消融实验。
实验诚意:基准是标准的(HumanEval、MBPP、APPS、LiveCodeBench),提升幅度可观。跨4个不同LLM测试增强了结论的普适性。数字漂亮但需要上下文——HumanEval上96.34%的Pass@1接近天花板,社区对HumanEval作为区分器越来越持怀疑态度。LiveCodeBench和APPS的结果更有说服力。我想看到成本/计算分析——并行生成和二部图构建的开销一定不小。这一点明显缺失。
写作功力:论文行文清晰,动机建立得很好。但消融实验部分显得仓促——我想看到每个模块具体贡献多少,以及没有TCQM只有BiCoTeV是否已经能拿到大部分收益。成本分析的缺失是一个重要遗漏,因为这个框架很可能把推理成本放大了5到10倍。第四节可以重构,把最有挑战性的基准放在前面。
判决:弱接收——问题真实,二部图想法优雅,数字强劲,但缺少成本分析和不完整的消融实验阻止了强接收。
要点总结
三个可以”偷”走的具体想法:
-
互验证作为通用模式:评估工具(测试)和被评估对象(代码)应该互相验证。这个思路可以迁移到任何质量信号由同一噪声过程生成的系统——数据标注、偏好学习、合成数据管线等。双向验证框架是通用的。
-
用已知好坏样本交叉验证生成产物:TCQM技巧——用正确和错误样本的校准组合来筛选LLM生成的输出——实现成本低,可以用在任何生成判别器的场景(测试、分类器、评估标准)。不需要完整的MineValiCoder管线就能用。
-
并行多样性优于线性精炼:用LLM做迭代改进时,并行生成多个多样候选再各自精炼,比反复精炼单一候选效果好。这在TDD场景下得到了具体验证,也展示了与测试质量的交互效应。